VoiceNet-RAI는 음성 데이터로부터 성별 및 연령을 분류하기 위해 MFCC 특징, 다국어 wav2vec 2.0 임베딩 및 EfficientNet-Lite를 통합합니다. 이 프레임워크는 영어 데이터셋에서 최대 97.87%의 정확도를 달성하며, 음성 인식, 인증 및 디지털 포렌식 분야의 책임감 있는 응용을 지원합니다.
연구 논문
VoiceNet: 성별 및 연령 분류를 위한 책임감 있는 인공지능 다국어 음성 프레임워크
48 조회수
⸱
2026년 9월 11일
이 논문에서
요약
초록
음성 데이터로부터 정확한 성별 및 연령 분류를 수행하는 것은 개인화되고 안전하며 윤리적인 인간-컴퓨터 상호작용(HCI)을 위해 중요합니다. wav2vec 2.0과 같은 대규모 사전 학습된 음성 모델의 사용이 증가함에 따라, 다국어 및 개인정보 보호를 고려한 인구통계학적 추론을 위해 이러한 표현형을 책임감 있게 활용할 필요성이 제기되고 있습니다. 본 연구에서는 다양한 언어적 맥락에서 정확하고 공정하며 투명한 분류를 지원하기 위해, EfficientNet-Lite 아키텍처 내에서 멜-주파수 셉스트럼 계수(MFCCs)와 트랜스포머 기반의 다국어 wav2vec 2.0 임베딩을 통합한 딥러닝(DL) 프레임워크인 VoiceNet-RAI를 제안합니다. 이 프레임워크는 문맥 정보와 스펙트럼 정보를 결합하여 가변적인 녹음 조건 하에서도 강건성을 향상시킵니다. 28개 언어를 포함하는 다국어 음성 데이터에 대한 실험 결과, 영어 서브셋에서 정확도 97.87%, 정밀도 98.61%, 재현율 98.70%, F1-score 98.65%의 강력한 분류 성능을 보였습니다. Mozilla Common Voice 데이터셋을 이용한 외부 검증에서는 성별 분류에 대해 98.27%의 정확도를 기록하여, 독립적인 데이터셋에 대한 일반화 가능성을 입증했습니다. 절제 분석(Ablation analysis)을 통해 MFCC와 wav2vec 2.0 특징을 결합하는 것이 원시 데이터 또는 MFCC 단독 표현형을 사용하는 것보다 성능이 향상됨을 추가로 확인했습니다. 이러한 결과는 강건하고 책임감 있는 성별 및 연령 분류를 위해 하이브리드 스펙트럼-문맥 음성 표현형이 가진 잠재력을 보여줍니다.
서론
음성 인식은 개인이 자신의 감정, 생각 및 목표를 표현하는 인간 의사소통의 핵심 구성 요소입니다. 인간의 목소리는 폐에서 공기가 배출되고 입술, 혀, 치아와 같은 조음 기관에 의해 소리로 형성되는 생물학적 과정을 통해 생성됩니다1. 귀는 음성 식별에 필수적인 역할을 하며, 음량 및 피치와 같은 특성을 기반으로 남성과 여성의 목소리를 구별할 수 있습니다. 남성과 여성 간의 음성 피치에 상당한 차이를 만드는 한 가지 특성은 성적 이형성입니다2. 음성을 통한 연령 및 성별 분류는 인간-기계 상호작용, 자동 성별 인식, 개인 맞춤형 인사, 음성 감정 사전 분류 및 성별 기반 전화 분류를 포함한 수많은 응용 분야와 관련이 있습니다3.
언어는 인간 상호작용의 본질적인 부분입니다. 인간의 목소리는 개인마다 다른 여러 특성을 포함하고 있으며, 이는 연령과 성별뿐만 아니라 정서적 및 정신적 상태에 대한 정보를 제공할 수 있습니다. 이러한 다차원적 특성은 음성 기반 보안 시스템 및 음성 지향 인공지능(AI) 비서와 같은 응용 분야에 활용될 수 있습니다. 음성 분석이 중요한 다른 분야로는 자동 화자 확인(ASV) 시스템과 감정 기반 AI 시스템이 있습니다. 음성 기반 입력 시스템은 데이터베이스 내의 검색 범위를 줄일 수도 있습니다4,5. 또한, AI 기반 보안 시스템은 범죄 수사 및 피해자 보호와 같은 응용 분야에 음성 데이터를 사용할 수 있습니다. 남성과 여성의 목소리는 성도의 공명 특성 차이로 인해 서로 다른 특성을 나타냅니다. 이러한 특성은 계산 처리에 적합한 형태로 음성 신호에서 추출될 수 있으며, 이를 통해 음성 데이터로부터 성별 분류가 가능해집니다6,7. 따라서 음성 기반 성별 분류를 위해서는 효율적인 학습 알고리즘이 필요합니다. 딥러닝(DL) 알고리즘은 오디오 데이터에서 복잡한 패턴을 학습하는 능력이 뛰어나 음성 관련 분류에 특히 적합합니다. 이러한 모델은 아키텍처에 따라 합성곱, 순환, 시간적 합성곱 또는 완전 연결 층을 포함할 수 있습니다. 이 층들은 톤과 피치를 포함한 관련 음향 특성을 학습할 수 있습니다. 일단 학습된 모델은 이전에 본 적 없는 오디오 녹음 파일에서 성별을 분류할 수 있습니다8. 머신러닝(ML) 연구의 또 다른 중요한 분야는 음성 녹음으로부터 연령을 분류하는 것입니다. ML 알고리즘은 피치, 음색, 진폭과 같은 음향 특성을 사용하여 연령 관련 패턴을 식별할 수 있습니다. 주성분 분석(PCA)과 같은 기법 또한 음성 데이터에서 유용한 패턴을 추출하고 잠재적으로 분류 성능을 향상시키는 데 적용될 수 있습니다9.
DL은 이미지, 감정 및 음성 인식과 같은 응용 분야에서 강력한 성능을 입증해 왔습니다. 특히 심층 신경망(DNNs)은 음성 관련 작업에 널리 사용됩니다. 본 연구에서는 확립된 특징 추출 기술과 결합하여 음성 분류에 DL 기반 접근법을 적용합니다. 멜 주파수 셉스트럴 계수(MFCCs)는 음성 신호의 관련 스펙트럼 특성을 포착하여 후속 처리를 위한 효율적인 표현을 제공합니다. 추출된 특징은 이후 음성 기반의 성별 및 연령 분류를 위한 전이 학습 프레임워크에 통합됩니다10,1.
최근 연구에서는 화자 속성 분류를 위해 자기지도 학습 및 Transformer 기반의 음성 표현 방식을 점점 더 많이 채택하고 있습니다. 연구자들은 HuBERT 및 wav2vec 2.0과 같은 자기지도 학습 음성 모델에서 성별 및 연령 편향을 포함한 인구통계학적 편향을 조사하여, 공정성을 고려한 평가의 중요성을 강조했습니다12. 보다 최근에는 Transformer 기반의 언어 독립적 접근 방식이 다국어 및 소음 환경에서의 성별 인식을 위해 학습된 문맥적 음성 표현의 효과를 입증했습니다13. Sinha 등은 연령 및 성별 분류를 위해 wav2vec 2.0의 레이어별 표현을 추가로 조사하였으며, 서로 다른 Transformer 레이어가 각기 다른 수준의 화자 관련 정보를 캡처한다는 것을 보여주었습니다14. 이러한 발전은 기존의 MFCC 기반 스펙트럼 정보와 문맥적 wav2vec 2.0 표현을 결합하는 동시에, 다국어 및 책임감 있는 AI(Responsible AI) 고려 사항을 통합한 VoiceNet-RAI 프레임워크를 제안하는 동기가 되었습니다.
최근 연구들에 따르면 화자의 연령과 성별은 전통적인 음향 특징과 딥러닝 기반 표현 방식을 모두 사용하여 특성화할 수 있음이 입증되었습니다. 음향 및 시간적 정보를 결합한 접근 방식은 상호 보완적인 음성 특성이 연령 및 성별 분류 성능을 향상시킬 수 있음을 보여주었습니다15,16. 관련 연구에서는 딥 보틀넥 표현(deep bottleneck representations)을 사용하여 생성된 변환 음성 특징이 화자의 연령 및 성별 분류 성능을 개선할 수 있다는 점 또한 입증되었습니다17. 이러한 결과는 음성 및 음성 유도 신호와 관련된 분류 작업에서 스펙트럼, 시간 및 학습된 표현 방식을 더 폭넓게 활용하는 것을 뒷받침합니다.
머신러닝 및 딥러닝 접근 방식을 사용하여 음성으로부터 연령과 성별을 인식하는 연구가 다수 수행되었습니다18,19,20,21,2,23,24,25,26,27,28,29,30. 보다 최근의 접근 방식에서는 화자의 연령 및 성별 분류를 위해 변환된 MFCC 표현과 심층 신경망을 탐구하였으며31, 강건한 음성 기반 인구통계학적 분류 시스템을 개발할 때 다국어 및 언어 의존적 변동성은 여전히 중요한 고려 사항으로 남아 있습니다. 발음, 음성 구조, 화자 특성 및 녹음 조건의 차이는 여러 언어와 인구 집단에 걸친 모델의 일반화 가능성을 저하시킬 수 있습니다. 따라서 보완적인 스펙트럼 및 문맥적 음성 표현을 사용하면 다국어 환경에서 강건성을 향상시킬 수 있습니다.
음성 기반 인구통계학적 인식을 위해 다수의 음향 특징이나 앙상블 분류기를 결합한 하이브리드 접근 방식이 이전에 시도된 바 있으나, VoiceNet-RAI는 단일 프레임워크 내에서 두 가지 상보적인 수준의 음성 표현을 통합한다는 점에서 차이가 있다. 구체적으로, 전통적인 MFCC 특징은 국소적인 스펙트럼 및 성도 특성을 보존하는 반면, wav2vec 2.0은 Transformer 인코더를 사용하여 가공되지 않은 음성으로부터 학습된 문맥화된 표현을 제공한다. VoiceNet-RAI는 수작업으로 설계된 음향 기술자나 단일 딥 표현에만 의존하는 대신, 시간적으로 집계된 MFCC와 wav2vec 2.0 표현의 특징 수준 융합을 수행한 후, EfficientNet-Lite를 사용하여 결과로 나온 하이브리드 표현을 정제한다. 따라서 본 연구의 과학적 독창성은 성별 및 연령 분류를 위해 스펙트럼, 자기지도 학습 기반 문맥, 그리고 경량 딥 표현을 조화롭게 통합한 점과 더불어, 다국어 평가, 독립 데이터셋 검증 및 하위 그룹 공정성 분석을 수행했다는 점에 있다. 이러한 결합은 기존의 하이브리드 음성 분류 파이프라인을 단순한 정확도 중심의 특징 융합을 넘어, 표현의 상보성, 경량 모델 설계, 일반화 가능성 및 책임감 있는 AI(Responsible AI)를 동시에 고려하는 프레임워크로 확장시킨다.
본 연구의 주요 기여는 MFCC 및 wav2vec 2.0 특징을 EfficientNet-Lite와 통합하여 음성 데이터로부터 성별과 연령을 식별하는 접근 방식을 개발한 것입니다. 28개 언어의 음성 녹음 데이터셋을 대상으로 광범위한 실험을 수행하였으며, 원본 특징, MFCC 특징, wav2vec 2.0 특징 및 이들의 조합을 ML 및 DL 모델로 평가하였습니다. 모델 성능은 전체 다국어 데이터셋과 영어 전용 서브셋을 모두 사용하여 평가되었습니다. 또한, 성별 및 언어별 하위 그룹 분석, 화자 독립 평가 및 Mozilla Common Voice 데이터셋을 이용한 검증을 통해 다국어 및 책임감 있는 AI(Responsible AI) 관점에서 프레임워크를 추가로 평가하였습니다. 아울러, 제안된 프레임워크의 성능을 기존 문헌에 보고된 최신 접근 방식들과 비교하고 교차 검증 결과를 제공하였습니다. 이와 관련하여 상당수의 연구가 수행되었으며, Table 1에 모델, 데이터셋 및 보고된 결과를 포함한 이러한 연구들을 요약하였습니다19,20,21,2,23,24,25,26,27,28,29,30,31.
프로토콜
본 연구는 직접적인 참여자 관여 없이 공개적으로 이용 가능한 BVC Challenging Voice Set 및 Mozilla Common Voice 데이터셋을 사용하였습니다. 따라서 기관의 윤리 승인 및 추가적인 고지된 동의는 필요하지 않았습니다. 성별 및 연령 분류에 필요한 데이터만 처리되었으며, 개별 화자를 식별하려는 시도는 하지 않았습니다. 제안된 프레임워크의 전체 워크플로우 방법론은 그림 1에 공유되어 있습니다.
데이터 획득
제안된 접근법에 사용된 데이터셋은 Biometrics Vision and Computing (BVC) 그룹에서 개발하고 GitHub에 게시한 공개 음성 데이터셋인 BVC Challenging Voice Set에서 얻은 .wav 오디오 파일로 구성되었습니다32. 이 데이터셋에는 남성 화자 36명과 여성 화자 190명을 포함하여 총 526명의 음성 녹음이 포함되어 있습니다. 또한 각 화자별로 단일 문장 및 다중 문장 녹음을 모두 포함하여 약 3,964개의 녹음 파일로 구성되었습니다. 표 2는 제안된 VoiceNet-RAI 프레임워크의 음성 데이터셋에 사용된 인구통계학적 특성, 언어 범위, 녹음 특성, 데이터 분할 전략 및 전처리 설정을 요약하여 보여줍니다.
특징 추출
오디오 파일들을 처리하여 필수 특성들을 추출하였으며, 이를 CSV 파일에 저장하였습니다. 연령, 성별, 화자의 발음 등의 메타데이터는 해당 README 파일에서 추출하였습니다. WAV 파일 처리 및 관련 특징 추출에는 Python과 SciPy 패키지를 사용하였습니다. 오디오 신호를 시간 영역에서 주파수 영역으로 변환하기 위해 NumPy의 고속 푸리에 변환(FFT) 및 주파수 함수를 이용하였습니다. WAV 파일은 시간의 함수로서 진폭을 나타내지만, 분류 작업에서는 남성과 여성의 목소리를 구별할 수 있는 주파수 관련 특성이 더 중요하였습니다3.
오디오 신호를 주파수 영역 표현으로 변환하기 위해, FFT 알고리즘을 사용하여 이산 푸리에 변환(DFT)을 구현하였습니다. 푸리에 변환은 시간 영역 신호를 주파수 스펙트럼으로 변환합니다. 이 스펙트럼은 시간 정보를 보존하지 않으므로, 오디오 신호를 중첩되는 세그먼트로 나누고 단시간 푸리에 변환(STFT) 방식을 사용하여 각 세그먼트에 푸리에 변환을 적용하였습니다. np.fft.fft 함수는 복소 주파수 스펙트럼을 생성하였고, np.fft.fftfreq는 그에 해당하는 샘플 주파수를 제공하였습니다. 샘플 디렉토리에는 한 명의 화자에 대해 10개의 오디오 파일이 준비되어 있었습니다. 각 WAV 파일은 지배 주파수를 추출하기 위해 20 ms 슬라이딩 윈도우를 사용하여 처리되었습니다. 예를 들어, 4초 길이의 오디오 녹음물은 20개의 주파수 값 리스트를 생성하였습니다. 녹음물 10개가 포함된 디렉토리의 경우, 각각 20개의 주파수 값을 포함하는 10개의 해당 리스트가 하나의 리스트들의 리스트로 결합되었습니다. 주파수는 20 Hz에서 280 Hz 사이의 값만 유지하도록 필터링하였으며, 50 Hz 주변의 잠재적 노이즈는 제외하였습니다.
하이브리드 MFCC 및 wav2vec 2.0 특징 표현
고수준의 문맥적 음성 표현과 저수준의 음향적 특성을 모두 포착하기 위해, 본 연구에서는 MFCC 특성과 Transformer 기반의 wav2vec 2.0 임베딩을 통합한 하이브리드 특성 추출 전략을 사용하였습니다.
MFCC 특징 추출
멜 주파수 케프스트럼 계수(Mel-Frequency Cepstral Coefficients, MFCCs)는 음성 및 오디오 신호 처리, 특히 음성 인식 및 화자 식별과 같은 응용 분야에서 널리 사용되는 특징량입니다34,35. 본 연구에서 MFCC 추출은 오디오 신호를 음성의 지각적으로 유의미한 특성을 나타내는 특징 벡터로 변환하였습니다. 이 과정은 고주파 성분을 강화하는 프리엠퍼시스(pre-emphasis)로 시작하여, 신호를 짧고 겹치는 프레임으로 나누는 프레이밍(framing) 및 윈도잉(windowing) 단계로 이어졌습니다. 각 오디오 샘플은 먼저 16 kHz로 리샘플링되었으며, 10-ms의 오버랩을 가진 25-ms 프레임으로 세그먼트되었습니다. 그 후, 각 프레임에 고속 푸리에 변환(Fast Fourier Transform)을 적용하여 신호를 시간 영역에서 주파수 영역으로 변환하였습니다.
결과로 얻은 주파수 스펙트럼은 인간 청각 지각의 비선형 주파수 응답을 근사화하는 일련의 Mel 필터 뱅크를 통과시켰습니다. 이러한 필터 뱅크는 지각적으로 덜 중요한 주파수의 기여도는 줄이는 동시에, 더 관련성이 높은 주파수를 강조했습니다. 이후 각 필터 뱅크 출력값의 로그를 계산하여 소리 크기에 대한 인간 청각의 로그 감도를 근사화했습니다. 그런 다음 로그 필터 뱅크 에너지에 이산 코사인 변환(DCT)을 적용하여 계수 간의 상관관계를 제거하고 오디오 신호의 압축된 표현을 생성했습니다. MFCC로 알려진 결과 계수들은 음성의 중요한 스펙트럼 특성을 포착했습니다. MFCC는 이러한 속성에 따라 목소리를 구분 짓는 음향적 특성을 포착하므로 성별 및 연령 분류에 사용되었습니다.
wav2vec 2.0 임베딩 추출
wav2vec 2.0 Base 모델은 대규모의 레이블이 없는 음성 코퍼스로 사전 학습되었습니다. 이 모델은 원시 파형 입력을 처리하여 문맥화된 음성 임베딩을 생성하는 다층 Transformer 인코더로 구성되었습니다36.
입력 파형 x ∈ RT가 주어지면, wav2vec 2.0 모델은 잠재 표현의 시퀀스를 생성합니다:
Z = {z1,z1,....,zn},zi ∈ R768 (1)
각 임베딩 벡터의 차원은 768이었으며, 분류에 적합한 고정 길이 표현을 얻기 위해 모든 타임 스텝에 대해 시간적 평균 풀링(temporal mean pooling) 연산을 적용하였습니다.
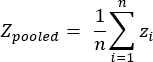 (2)
특징 융합 메커니즘
MFCC 및 wav2vec 2.0 특징은 특징 수준 결합(feature-level concatenation)을 통해 융합되었습니다. 구체적으로, MFCC 특징은 먼저 시간적 평균화를 사용하여 고정 길이 벡터로 집계되었습니다.
m ∈ R40 (3)
최종 하이브리드 특징 벡터는 다음과 같이 얻었습니다:
h = [m || zpooled] ∈ R808 (4)
여기서 ||는 연결(concatenation)을 나타냅니다. 이러한 융합은 심층 문맥 임베딩과 수작업으로 추출한 스펙트럼 특징을 결합하여, 모델이 고차원의 의미론적 정보와 세밀한 음향 패턴을 모두 포착할 수 있도록 하였습니다.
모든 오디오 샘플은 먼저 16 kHz로 리샘플링되었습니다. MFCC 특성은 프레임 단위로 계산된 후 시간적으로 평균화하여 고정된 40차원 벡터를 생성하였으며, wav2vec 2.0 임베딩은 시간축을 따라 평균 풀링(mean-pooling)하여 768차원 표현을 생성하였습니다. 두 특성 세트 모두 결합 전 고정 길이 벡터로 변환되었으므로, 프레임 수준의 시간적 정렬은 필요하지 않았습니다. 이렇게 생성된 MFCC 및 wav2vec 표현은 분류 모델에 전달되기 전 808차원의 하이브리드 특성 벡터로 연결되었습니다.
EfficientNet-Lite와의 통합
융합된 특징 벡터 h는 특징 학습에 적합한 형식으로 재구성되어 EfficientNet-Lite 모델의 학습 입력값으로 제공되었습니다. 먼저 완전 연결 투영 층(fully connected projection layer)을 통해 808차원 벡터를 더 높은 차원의 잠재 공간으로 매핑한 후, EfficientNet-Lite 블록이 계층적 특징을 정교화했습니다. 과적합을 줄이고 모델의 일반화 성능을 향상시키기 위해 배치 정규화(batch normalization) 및 드롭아웃(dropout) 층이 사용되었습니다. 성별 및 연령 클래스에 대한 최종 예측 확률을 생성하기 위해 SoftMax 활성화 함수가 사용되었습니다. 융합된 표현 h ∈ R808은 처음에 1차원 특징 벡터로 처리되어 이를 4,096차원으로 매핑하는 완전 연결 투영 층을 통과했습니다. 이후 투영된 표현은 EfficientNet-Lite 아키텍처에 공급되기 전 1 × 64 × 64 텐서로 재구성되었습니다.
기존의 3채널 이미지 입력 대신 단일 채널 음성 특징 표현을 수용하기 위해, 기존 EfficientNet-Lite의 입력 컨볼루션 레이어를 3개에서 1개의 입력 채널로 수정하였습니다. 나머지 EfficientNet-Lite 특징 추출 블록은 주요 아키텍처 변경 없이 그대로 유지하였습니다. 고정 길이 표현을 생성하기 위해 최종 특징 맵에 적응형 글로벌 평균 풀링 레이어를 적용하였습니다. 기존의 분류 헤드는 성별 분류를 위한 2개의 출력 유닛과 미리 정의된 연령대별 출력 유닛 수를 갖는 작업 특화 완전 연결 레이어로 교체되었습니다. 마지막으로, 클래스 확률을 생성하기 위해 SoftMax 활성화 함수를 적용하였습니다. 제안된 하이브리드 표현은 현대적인 자기 지도 학습 기반 음성 임베딩과 전통적인 신호 처리 특징을 결합하였습니다. wav2vec 2.0 임베딩은 문맥 정보와 장거리 의존성을 포착하는 반면, MFCC 특징은 상호 보완적인 저수준 음향 정보를 제공하였습니다. 이러한 표현들의 통합은 특히 소음이 많거나 다국어 음성 조건에서 분류 성능을 향상시켰습니다.
ML 분류기
본 연구에서는 음성 기반의 성별 및 연령대 분류를 위해 여러 머신러닝(ML) 알고리즘의 성능을 분석하였습니다.
랜덤 포레스트
예측 정확도를 높이고 과적합(overfitting)을 줄이기 위해 여러 개의 결정 트리(Decision Trees, DTs)를 결합한 강력한 머신러닝(Machine Learning, ML) 분류기로서 랜덤 포레스트(Random Forest, RF)를 사용하였습니다. RF는 여러 트리의 예측 결과를 집계하여 최종 예측을 생성하는 앙상블 학습 절차를 통해 작동합니다37,38. 이러한 접근 방식 덕분에 RF는 개별 DT에서 흔히 발생하는 과적합을 줄이면서 데이터 내의 다양한 패턴을 포착할 수 있었습니다. 트리 구축 과정에서 도입된 무작위성은 모델의 일반화 능력을 향상시켜, 음성 데이터로부터 성별 및 연령을 분류하는 것과 같은 분류 작업에 RF가 적합하도록 하였습니다.
로지스틱 회귀
분류를 위한 통계적 ML 모델로 로지스틱 회귀(Logistic Regression, LR)가 사용되었습니다39. 이진 분류의 경우, LR은 로지스틱(시그모이드) 함수를 사용하여 입력 특성에 기반한 결과 확률을 추정하며, 도출된 확률을 통해 클래스 예측을 생성합니다. LR은 두 개 이상의 클래스가 포함된 다중 클래스 분류 문제에도 적용 가능했습니다. 다중 클래스 분류를 위해 LR은 분류 설정에 따라 one-vs-rest 또는 SoftMax 회귀와 같은 접근 방식을 사용하였습니다.
엑스트라 트리 분류기(Extra Tree Classifier)
여러 개의 DT를 결합하여 예측을 생성하는 앙상블 학습 알고리즘으로 Extra Trees Classifier (ETC)가 사용되었습니다40,41. RF와 달리, ETC는 트리 구축 과정에서 후보 특성과 분할 임계값을 무작위로 선택함으로써 추가적인 무작위성을 도입합니다. 이 절차를 통해 상관관계가 더 낮은 트리들이 생성되었으며, 개별 특성에 대한 모델의 민감도가 낮아져 노이즈에 대한 강건성이 향상되었습니다. 특성 중요도를 평가하고 데이터를 분할하기 위한 분할 기준으로 Gini index가 사용되었습니다.
서포트 벡터 머신
고차원 특징 공간에서 최적의 결정 경계를 식별하기 위해 ML 분류기로 서포트 벡터 머신(Support Vector Machine, SVM)을 사용하였다42. 목표는 클래스 간의 마진을 최대화하는 초평면을 결정하는 것이었다. 결정 경계와 가장 가까운 데이터 포인트 사이의 마진이 클수록 일반적으로 더 나은 클래스 분리와 일반화가 가능했다. SVM은 분류, 회귀 및 특징 기반 데이터 분석을 포함한 여러 ML 작업에 적용 가능했다.
합성곱 신경망
합성곱 신경망(Convolutional Neural Networks, CNNs)은 이미지 및 오디오 데이터의 구조화된 표현을 포함하는 분류 작업의 딥러닝(Deep Learning, DL) 모델로 사용되었습니다. 1차원 CNN(1D-CNNs) 또한 순차 및 텍스트 데이터에 널리 적용되어 왔습니다. CNN 아키텍처는 합성곱 필터와 풀링 연산을 사용하여 입력 데이터로부터 판별 특징을 추출합니다43,4. 음성 데이터로부터 성별 및 연령을 분류하기 위해, CNN은 음성 유래 표현에 적용되어 피치, 주파수, 톤 및 성별과 연령 그룹을 구분하는 데 관련된 기타 음성 특성과 연관된 패턴을 학습하였습니다.
VGG19
깊고 상대적으로 균일한 계층적 특징 추출 구조를 특징으로 하는 DL 아키텍처로 VGG19를 사용하였다45. 이 아키텍처는 19개의 층에 걸쳐 작은 3 × 3 합성곱 필터를 사용하여 판별 특징을 점진적으로 추출할 수 있게 한다. 음성 유래 표현에 적용했을 때, VGG19는 피치 및 주파수 변동과 같은 저수준 음향 패턴과 고수준 판별 특징을 모두 포착하였다. 이러한 깊은 아키텍처는 성별 및 연령과 관련된 음성 특성을 모델링하기 위한 점진적인 특징 추상화를 가능하게 하였다.
EfficientNet-Lite
계산 효율적인 DL 아키텍처로 EfficientNet-Lite가 사용되었다46,47. 이 모델은 더 무거운 DL 아키텍처보다 적은 계산 리소스를 필요로 하면서도 강력한 분류 성능을 달성하기 위해 균형 잡힌 스케일링 전략을 채택하였다. 이 모델의 복합 스케일링 방식은 효율적인 특징 추출을 달성하기 위해 모델의 깊이, 너비 및 입력 해상도를 함께 고려하였다.
EfficientNet-Lite는 가벼운 아키텍처와 분류 성능 및 모델 복잡도 사이의 유리한 균형 덕분에 제안된 VoiceNet-RAI 프레임워크를 위해 선택되었습니다. 더 무거운 아키텍처와 비교하여, EfficientNet-Lite는 효율적인 컨볼루션 블록과 복합 스케일링을 사용하여 더 적은 파라미터와 낮은 계산 요구 사항으로 효과적인 특징 학습을 달성했습니다. 이러한 특성 덕분에 EfficientNet-Lite는 제안된 음성 분류 프레임워크에 적합하며, 리소스 제한 환경에서의 배포 가능성을 제공합니다.
MobileNet
MobileNet은 모바일 및 엣지 컴퓨팅 환경을 포함하여 계산 리소스가 제한된 애플리케이션을 위한 경량 DL 아키텍처로 사용되었습니다48. MobileNet의 계산 효율성은 주로 depthwise separable convolutions를 통해 달성되었으며, 이는 기존의 합성곱 아키텍처와 비교하여 파라미터 수와 계산 연산을 줄여주었습니다. 이러한 특성 덕분에 MobileNet은 상대적으로 낮은 계산 요구 사항을 유지하면서 음성 데이터로부터 성별 및 연령 분류를 평가하는 데 적합했습니다.
InceptionV3
음성 유래 표현으로부터 계층적 특징을 추출하기 위해 딥 아키텍처로 InceptionV3가 사용되었습니다49. 이 아키텍처는 서로 다른 추상화 수준에서 특징을 추출하기 위해 합성곱, 풀링 및 혼합 연산을 통합하였습니다. 음성 데이터로부터의 성별 및 연령 분류를 위해, InceptionV3는 음성 특성의 변화와 관련된 복잡한 음향 패턴과 계층적 표현을 학습하는 데 사용되었습니다.
평가 파라미터
정확도는 분류 작업에서 가장 빈번하게 사용되는 평가 지표 중 하나였습니다50. 정확도는 전반적인 분류 성능에 대한 유용한 척도를 제공하지만, 특히 불균형 데이터셋의 경우 항상 포괄적인 평가를 제공하는 것은 아니었습니다. 따라서 모델 성능을 평가하기 위해 정밀도, 재현율 및 F1-score를 포함한 추가 지표들이 사용되었습니다. 이러한 지표들은 각 클래스에 대한 정답 및 오답 예측을 고려함으로써 더욱 포괄적인 평가를 가능하게 했습니다.
정확도는 전체 관찰 수 대비 올바르게 분류된 관찰 수의 비율로 정의되었습니다. 정확도는 균형 잡힌 데이터셋에서 특히 유용한 정보가 되지만, 본 연구에 사용된 데이터셋은 불균형했습니다. 따라서 분류 메트릭을 계산하고 해석할 때 진양성(TP), 위양성(FP), 진음성(TN) 및 위음성(FN)을 고려하였습니다. 아래 식은 정확도의 표준 정의를 나타냅니다:
정확도 = (TP+TN)/(TP+TN+FP+FN)×10 (5)
정밀도는 분류기가 관련 인스턴스만을 반환하는 능력을 평가합니다:
정밀도= TP/(TP+FP) ×10 (6)
민감도로도 알려진 재현율(Recall)은 분류기가 모든 관련 사례를 식별하는 능력을 측정합니다:
재현율(Recall)= TP/(FN+TP) × 10 (7)
F1-score는 정밀도(precision)와 재현율(recall)을 하나의 척도로 결합한 것이며, 특히 불균형 데이터셋의 분류 성능을 평가하는 데 유용합니다:
F1-Score =2 ×(PPV ×TPR)/(TPR+PPV) × 10 (8)
결과
Experimental results for age and gender classification were evaluated using MFCC-based and hybrid feature representations with ML and DL models. The dataset was partitioned into training and testing sets at an 80:20 ratio, with 80% used for training and 20% for testing. Speaker-level partitioning was applied to prevent recordings from the same speaker from appearing in both sets.
The hyperparameters and implementation details of the proposed framework are summarized in Table 3. The experiments were conducted on a system equipped with an Intel i7-8265U CPU, 16 GB of RAM, and an NVIDIA Tesla K80 GPU running Windows 11. Python and the Scikit-learn library were used to develop the ML models, whereas the proposed DL framework was implemented using PyTorch. These models were evaluated for gender and age classification from voice data.
The Adam optimizer was used with an initial learning rate of 1 × 10⁻4, β₂ = 0.999, and ε = 1 × 10⁻8. A batch size of 64 and a maximum of 50 epochs were used, with early stopping set to a patience of four epochs to reduce overfitting. A dropout rate of 0.3 was applied to the fully connected layers for regularization. Categorical cross-entropy was used as the loss function for the classification tasks. The ReduceLROnPlateau learning-rate scheduler was used to monitor the validation loss.
To prevent data leakage and ensure a fair evaluation, speaker-level splitting was enforced so that no speaker appeared in both the training and testing sets. In addition, five-fold cross-validation was performed to assess the generalizability and robustness of the proposed model.
Results of models using the original dataset
Table 4 presents the performance of several ML and DL models for gender classification on a dataset comprising 28 languages, without MFCC features. Precision, recall, F1-score, and accuracy were used as the evaluation metrics.
Among the evaluated models, EfficientNet-Lite achieved the highest accuracy of 83.48%, with a precision 82.87%, a recall 84.28%, and an F1-score 83.54%. MobileNet and InceptionV3 also performed well, with MobileNet achieving 81.33% accuracy and 83.11% F1-score, and InceptionV3 achieving 80.77% accuracy and 82.52% F1-score. The CNN model achieved an accuracy of 75.71% and an F1-score of 77.43%, while ResNet achieved an accuracy of 74.37% and an F1-score of 75.54%. SVM, RF, LR, and ETC achieved accuracies ranging from 71.42% to 73.59% and F1-scores ranging from 72.48% to 74.34%. VGG19 achieved a comparatively lower accuracy of 70.56%, with a recall of 75.07% and an F1-score of 74.17%. Overall, EfficientNet-Lite and MobileNet achieved the strongest performance among the evaluated models when using the original features.
Results of models using MFCC features
MFCC features were subsequently evaluated for gender classification. Table 5 compares the performance of the ML and DL models using MFCC features on the dataset comprising 28 languages.
EfficientNet-Lite achieved the highest performance, with an accuracy of 92.64%, precision of 93.79%, recall of 94.92%, and F1-score of 94.84%. MobileNet achieved an accuracy of 91.39% and an F1-score of 91.07%, whereas InceptionV3 achieved an accuracy of 90.24% and an F1-score of 89.83%. ResNet achieved an accuracy of 89.43% and an F1-score of 83.67%, while CNN achieved an accuracy of 88.60% and an F1-score of 87.35%. VGG19 achieved an accuracy of 87.48% and an F1-score of 85.58%.
Among the traditional ML models, SVM achieved an accuracy of 85.47% and an F1-score of 84.29%; RF achieved an accuracy of 84.57% and an F1-score of 87.42%; LR achieved an accuracy of 83.25% and an F1-score of 84.98%; and ETC achieved an accuracy of 83.59% and an F1-score of 85.43%. Overall, the inclusion of MFCC features improved the performance of most models compared with the results obtained using the original features. EfficientNet-Lite achieved the highest overall performance in this experiment.
Results of models using hybrid MFCC–wav2vec 2.0 features with the English-language dataset
The next set of experiments evaluated gender classification using the hybrid MFCC–wav2vec 2.0 feature representation on the English-language subset. The performance of the evaluated models is presented in Table 6. EfficientNet-Lite achieved the highest performance, with an accuracy of 97.87%, precision of 98.61%, recall of 98.70%, and F1-score of 98.65%.
Among the traditional ML models, SVM achieved an accuracy of 92.58% and an F1-score of 91.52%; ETC achieved an accuracy of 91.49% and an F1-score of 92.79%; LR achieved an accuracy of 90.64% and an F1-score of 91.34%; and RF achieved an accuracy of 88.36% and an F1-score of 90.86%. Overall, the models demonstrated strong performance on the English-language subset, with EfficientNet-Lite achieving the highest values across the reported evaluation metrics.
Results of five-fold cross-validation
Five-fold cross-validation was performed to evaluate the stability and generalizability of the proposed framework. The cross-validation results obtained using the English-language voice dataset are presented in Table 7. EfficientNet-Lite achieved a standard deviation of ±0.0033 across the five folds. The low variability across folds indicated stable performance under the evaluated cross-validation setting.
Age classification using voice data
In addition to gender classification, age classification was evaluated using multiple models and MFCC features. Table 8 presents the performance of the evaluated models for age classification.
The results showed that the transfer-learning models achieved accuracies above 85%, with MobileNet achieving 85.23% and InceptionV3 achieving 86.67%. EfficientNet-Lite achieved the highest reported performance, with an accuracy of 88.42%, precision of 86.56%, and recall of 87.21%.
Validation of the proposed framework
To evaluate the proposed framework on an external dataset, additional experiments were conducted using the Mozilla Common Voice dataset51. The dataset contained approximately 500 hours of crowdsourced speech recordings with associated demographic metadata, including age, gender, and accent information. The corpus was organized into predefined training, development, and test subsets. Audio recordings were processed using the same preprocessing pipeline as that used in the primary experiments, including resampling to 16 kHz, extraction of 40-dimensional MFCC features, and generation of 768-dimensional wav2vec 2.0 embeddings. The two representations were concatenated to produce the 808-dimensional hybrid feature vector used by VoiceNet-RAI. The validation results are presented in Table 9.
EfficientNet-Lite with the hybrid low- and high-level feature representation achieved a gender classification accuracy of 98.27%, higher than that of the other evaluated models. Among the ML models, RF achieved 90.47% accuracy, SVM 90.69%, and LR 89.75%. Among the other DL models, ResNet achieved 92.19% accuracy, whereas VGG19 achieved 92.12%. The corresponding precision, recall, and F1-score values are reported in Table 9.
Ablation study on feature representation and fusion
An ablation study was conducted to evaluate the contribution of the feature representations used in the proposed framework. Four configurations were considered: raw/original features, MFCC-only features, wav2vec 2.0-only embeddings, and the proposed hybrid MFCC–wav2vec 2.0 representation. EfficientNet-Lite was used as the representative model because it achieved the highest performance across the evaluated experimental settings. The ablation results are presented in Table 10.
The baseline model using raw features achieved 83.48% accuracy, whereas the MFCC-based representation achieved 92.64% accuracy and 94.84% F1-score. The hybrid MFCC–wav2vec 2.0 representation achieved an accuracy of 97.87% and an F1-score of 98.65%. Under identical English-language data partitions and training conditions, the hybrid MFCC–wav2vec 2.0 representation achieved 97.87% accuracy, compared with 92.64% for the MFCC-only representation.
Controlled experiments were conducted using identical data partitions, training settings, and the EfficientNet-Lite architecture to evaluate the contribution of each feature representation. Raw/original features, MFCC-only features, wav2vec 2.0-only embeddings, and the hybrid MFCC–wav2vec 2.0 representation were compared under these conditions. This experimental design was used to assess the individual and combined contributions of the feature representations.
Statistical significance analysis
All feature configurations in this comparison were evaluated using the same English-language subset, identical speaker-level data partitions, and the same five cross-validation folds. The proposed model achieved significantly higher accuracy than the raw-feature (97.86 ± 0.23% vs. 83.48 ± 0.24%; t (4) = 384.32, p < 0.001), MFCC-only (97.86 ± 0.23% vs. 92.60 ± 0.32%; t (4) = 131.50, p < 0.001), and wav2vec 2.0-only configurations (97.86 ± 0.23% vs. 95.34 ± 0.24%; t (4) = 126.00, p < 0.001), confirming that the improvements from MFCC–wav2vec 2.0 fusion were statistically significant.
Responsible AI considerations and deployment guidelines
Responsible AI in voice-based demographic classification required consideration of fairness, transparency, privacy, potential misuse, and deployment-related risks in addition to predictive performance. Although subgroup analysis provided an empirical assessment of performance differences across the evaluated gender and language groups, fairness could not be established solely from similar classification accuracy. Therefore, the VoiceNet-RAI framework was evaluated from multiple Responsible AI perspectives.
Fairness and bias analysis
A fairness analysis was conducted across gender and language subgroups to evaluate the Responsible AI characteristics of the proposed VoiceNet-RAI framework. The results are presented in Table 11. For gender-wise evaluation, model performance was analyzed separately for male and female speakers. The results showed less than 1.5% variation in accuracy and F1-score between the evaluated gender groups.
For language-wise evaluation, performance was assessed across the evaluated language groups within the dataset of 28 languages. The results showed an average variation of less than 2% in accuracy across the evaluated groups, with greater variation observed for some lower-resource languages with fewer available samples.
Fairness was further assessed using the demographic parity difference, the equal opportunity difference, the False Positive Rate (FPR), and the False Negative Rate (FNR). Demographic parity difference quantified differences in positive prediction rates between groups, whereas equal opportunity difference quantified differences in True Positive Rates (TPRs). FPR and FNR were used to characterize subgroup-specific error patterns. These metrics complemented subgroup-level accuracy and F1-score, providing additional information on differences in model performance across the evaluated demographic and linguistic groups. Under the evaluated dataset and subgroup definitions, the results indicated relatively small performance differences across the assessed gender and language groups. However, these findings were limited to the demographic and linguistic groups represented in the evaluated datasets and did not establish fairness across unrepresented populations or deployment settings.
Explainability and transparency
VoiceNet-RAI combined interpretable MFCC-based acoustic features with contextual wav2vec 2.0 embeddings. The ablation study evaluated the contributions of the individual and combined feature representations. However, wav2vec 2.0 embeddings remained comparatively difficult to interpret. Post-hoc explanation methods could therefore be investigated in future studies to identify the features that contributed most strongly to individual predictions.
Privacy preservation
Because voice recordings contained sensitive biometric information, privacy-preserving deployment required data-minimization practices, including processing only the information required for the classification task and avoiding unnecessary storage of raw audio. Secure storage, controlled access, and local inference could further reduce privacy risks. Formal privacy-preserving approaches, including differential privacy, were not evaluated in the present study and remained an area for future investigation.
Responsible deployment
Deployment of VoiceNet-RAI would require human oversight, confidence-aware decision-making, and continuous performance monitoring. Low-confidence predictions should not be used independently for critical decisions, and model performance should be re-evaluated when deployment conditions differ substantially from those represented in the training and validation datasets.
Comparison with state-of-the-art techniques
A comparative evaluation of the proposed framework and previously published approaches is presented in Table 12. Studies published between 2019 and 2024 were considered, including approaches based on ML, DL, and transfer learning. The comparison included previously reported studies in the same application domain. As shown in Table 12, the proposed framework achieved higher reported accuracy for gender and age classification than the compared approaches. However, because the studies may have differed in datasets, preprocessing procedures, data partitions, and evaluation protocols, the comparison reflected reported performance rather than a controlled head-to-head experimental comparison.
DATA AVAILABILITY:
The raw speech data used in this study are publicly available from the BVC Challenging Voice Set hosted on GitHub and the Mozilla Common Voice dataset. The BVC dataset can be accessed at https://github.com/OgeNI/BVC_Challenging_Voice_Set, while the Common Voice dataset is available at https://www.kaggle.com/datasets/mozillaorg/common-voice/data.
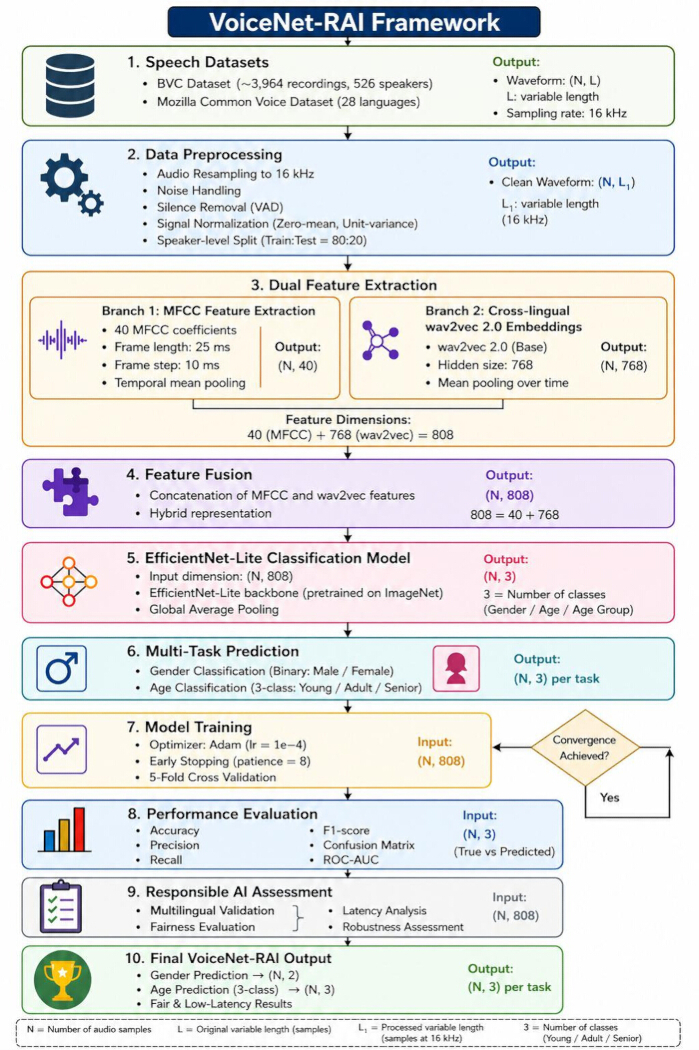
Figure 1: Architecture Diagram. The complete workflow methodology of the proposed framework. Please click here to view a larger version of this figure.
| References | Models | Datasets | Results |
| 19 | GBC, DT, RF, SVM, NN | VoxForge dataset | GBC 90% |
| 20 | Robustscalar, PCA, and Logistic regression, Sequential model | voice.mozilla.org | Sequential Model 91%. |
| 21 | CNN, CRNN, TCN | Mozilla Voice dataset | 80% CNN |
| 22, 23 | Backpropagation, DT, Bagging, RF, KNN, DNN, DL | Kaggle, Mozilla Voice dataset, Speech Accent Archive | Kaggle: Bagging, KNN and RF 98.10%. Voice common: Bagging 55.39%. Speech accent: Bagging 78.94%. |
| 24 | DNN, MLP, KNN, SVC, DT, RF, SVC RBF kernel, ADA, QDA, GNB, ResNET34 and ResNET50. | Mozilla Common Voice | ResNET50 98.57%. |
| 25 | ANN, SVM, RF, DT, NB, KNN | OGI Kids Speech corpus, Private corpus, Specific Dataset, | For Gender detection SVM 98%, For age detection RF 95% |
| 26 | SVM, DA, NB, DT, KNN, Ensem- ble, LightGBM | Mozilla Common Voice, VoxCeleb | LGBM 91% |
| 27 | KNN, SVM, LR, SGD, Stacked model | Various gender sources | Stacked model 99.64% |
| 28 | DNN, SVM | Various gender sources | SVM 97% |
| 29 | SVM, RF, CART, KNN | Dataset contain 3169 instances | RF 93% |
| 30 | CNN | Nigerian subjects dataset | CNN 85.48%. |
| 31 | DT, RF, KNN, LR, SVM, ANN, CNN2D | 3 dataset from kaggle | Gender Prediction: ANN 85.51%, Age Prediction: ANN 89.20%. |
Table 1: Summary of existing studies on voice-based gender and age classification, including models, datasets, and reported performance.
| Dataset Characteristic | Description / Value | ||
| Total number of speakers | 526 | ||
| Male speakers | 336 | ||
| Female speakers | 190 | ||
| Total recordings | Approximately 3,964 | ||
| Number of languages | 28 | ||
| Language-wise distribution | English and 28 native languages (Afemai, Akoko-Edo, Annang, Efik, Ekoi, Fulani, Hausa, Ibibio, Idoma, Igala, Igbo, Igede, Ijaw, Ika, Ikom, Ikwerre, Ishan, Kaire-Kaire, Kanuri, Lokaa, Urhobo, Yoruba, Obudu, Ogoni, Okobo, Okirika, Tiv and Ukwani. The dominant tribe amongst these native languages in the dataset is Igbo.) | ||
| Age groups | three age groups: young people (teens and twenties), adults (thirties, forties and fifties), and seniors (sexagenarians, heptagenarians and octogenarians) | ||
| Age-group distribution | Teens13–19 yearsLow (< 10%)Twenties20–29 yearsVery High (~35–45%)Thirties30–39 yearsHigh (~20–30%)Forties40–49 yearsModerate (~10–15%)Fifties50–59 yearsLow (~5–10%)Sixties+60–80+ yearsSparse (< 5%) | ||
| Recording duration | 3-10 seconds | ||
| Recording conditions | 16 bit PCM | ||
| Original sampling rate | 44.1 kHz | ||
| Processing sampling rate | 16 kHz | ||
| MFCC frame length | 25 ms | ||
| MFCC frame overlap / step | 10 ms | ||
| MFCC representation | 39-dimensional temporally averaged vector | ||
| wav2vec 2.0 representation | 768-dimensional temporally mean-pooled vector | ||
| Final fused representation | 807 dimensions | ||
| Train–test split | 80:20 | ||
| Data partitioning | Speaker-independent splitting | ||
| Cross-validation | 5-fold cross-validation | ||
| External validation dataset | Mozilla Common Voice | ||
Table 2: Demographic characteristics, language coverage, data partitioning, and preprocessing settings of the speech dataset used in VoiceNet-RAI.
| Parameter | Value / Description | ||
| Framework | PyTorch | ||
| Hardware | NVIDIA GPU (CUDA-enabled) | ||
| Random seed | 42 | ||
| Optimizer | Adam | ||
| Initial Learning Rate | 1 × 10⁻⁴ | ||
| β₁ / β₂ | 0.9 / 0.999 | ||
| Adam epsilon | 1 × 10⁻⁸ | ||
| Batch Size | 64 | ||
| Epochs | 50 (Early stopping patience = 8) | ||
| Loss Function | Categorical Cross-Entropy | ||
| Normalization | Z-score normalization | ||
| Learning Rate Scheduler | ReduceLROnPlateau | ||
| Dropout Rate | 0.3 | ||
| Training time | 20min | ||
| Inference time/sample | 13 seconds | ||
| Feature Extraction | Feature Extraction | ||
| MFCC Coefficients | 40 | ||
| Window Size | 25 ms | ||
| Stride | 10 ms | ||
| wav2vec Variant | Base (pretrained) Embedding Dimension | ||
| Pooling Strategy | Mean pooling | ||
| Feature Fusion | Concatenation (MFCC + wav2vec) | ||
| MFCC Coefficients | 40 | ||
| Evaluation Protocol | Evaluation Protocol | ||
| Train-Test Split | Speaker-level separation | ||
| Cross-Validation | 5-Fold | ||
| Datasets | Mozilla Common Voice (28 languages + English subset) and BVC Gender & Age from Voice Challenging Dataset | ||
| Tasks | Gender and Age Classification | ||
Table 3: Training configuration, feature-extraction settings, hyperparameters, and evaluation protocol used for VoiceNet-RAI.
| Models | Accuracy | Precision | Recall | F1-score |
| RF | 71.42 | 72.79 | 74.43 | 73.52 |
| LR | 73.59 | 74.22 | 75.40 | 74.34 |
| ETC | 72.44 | 72.33 | 74.52 | 73.41 |
| SVM | 73.52 | 72.60 | 72.39 | 72.48 |
| CNN | 75.71 | 76.59 | 77.34 | 77.43 |
| VGG19 | 70.56 | 73.28 | 75.07 | 74.17 |
| ResNet | 74.37 | 73.49 | 76.68 | 75.54 |
| EfficientNet-Lite | 83.48 | 82.87 | 84.28 | 83.54 |
| MobileNet | 81.33 | 83.19 | 82.14 | 83.11 |
| InceptionV3 | 80.77 | 81.34 | 82.67 | 82.52 |
Table 4: Gender-classification performance of ML and DL models using the 28-language dataset without MFCC features.
| Models | Accuracy | Precision | Recall | F1-score |
| RF | 84.57 | 86.53 | 87.39 | 87.42 |
| LR | 83.25 | 84.42 | 85.64 | 84.98 |
| ETC | 83.59 | 84.25 | 86.36 | 85.43 |
| SVM | 85.47 | 83.37 | 85.26 | 84.29 |
| CNN | 88.60 | 86.75 | 88.46 | 87.35 |
| VGG19 | 87.48 | 85.49 | 85.80 | 85.58 |
| ResNet | 89.43 | 84.39 | 82.34 | 83.67 |
| EfficientNet-Lite | 92.64 | 93.79 | 94.92 | 94.84 |
| MobileNet | 91.39 | 90.64 | 91.15 | 91.07 |
| InceptionV3 | 90.24 | 88.81 | 90.70 | 89.83 |
Table 5: Gender-classification performance of ML and DL models using MFCC features on the 28-language dataset.
| Models | Accuracy | Precision | Recall | F1-score |
| RF | 88.36 | 90.91 | 89.94 | 90.86 |
| LR | 90.64 | 92.24 | 91.30 | 91.34 |
| ETC | 91.49 | 92.80 | 92.79 | 92.79 |
| SVM | 92.58 | 92.75 | 90.64 | 91.52 |
| CNN | 93.69 | 94.69 | 94.53 | 94.34 |
| VGG19 | 91.37 | 92.64 | 93.48 | 93.21 |
| ResNet | 95.28 | 96.39 | 95.52 | 95.43 |
| EfficientNet-Lite | 97.87 | 98.61 | 98.70 | 98.65 |
| MobileNet | 96.41 | 95.51 | 96.39 | 96.24 |
| InceptionV3 | 96.35 | 95.29 | 96.84 | 96.08 |
Table 6: Gender-classification performance of ML and DL models using the hybrid MFCC–wav2vec 2.0 feature representation on the English-language subset.
| Models | Accuracy | Precision | Recall | F1-score |
| First-fold | 97 | 93 | 96 | 94 |
| Second-fold | 96 | 94 | 96 | 95 |
| Third-fold | 97 | 94 | 95 | 95 |
| Fourth-fold | 96 | 93 | 95 | 94 |
| Fifth-fold | 97 | 94 | 96 | 95 |
| Average | 96.6 | 93.6 | 95.6 | 94.6 |
Table 7: Five-fold cross-validation performance of VoiceNet-RAI on the English-language subset.
| Models | Accuracy | Precision | Recall | F1-score |
| RF | 80.15 | 78.68 | 79.27 | 79.04 |
| LR | 81.28 | 80.69 | 80.43 | 80.54 |
| ETC | 80.58 | 81.21 | 80.82 | 81.04 |
| SVM | 82.54 | 81.31 | 82.14 | 81.78 |
| CNN | 85.27 | 84.39 | 84.47 | 84.43 |
| VGG19 | 83.73 | 82.97 | 83.53 | 83.48 |
| ResNet | 82.68 | 81.42 | 80.78 | 81.95 |
| EfficientNet-Lite | 88.42 | 86.56 | 87.21 | 86.97 |
| MobileNet | 85.23 | 85.64 | 85.95 | 85.81 |
| InceptionV3 | 86.67 | 85.86 | 86.78 | 86.35 |
Table 8: Age-classification performance of ML and DL models in terms of accuracy, precision, recall, and F1-score.
| Models | Accuracy | Precision | Recall | F1-score |
| RF | 90.47 | 92.82 | 90.85 | 91.32 |
| LR | 89.75 | 90.44 | 89.61 | 90.03 |
| ETC | 92.63 | 91.29 | 91.55 | 91.42 |
| SVM | 90.69 | 91.84 | 91.81 | 91.82 |
| CNN | 94.63 | 95.52 | 94.24 | 94.94 |
| VGG19 | 92.12 | 91.34 | 90.52 | 91.10 |
| ResNet | 92.19 | 91.98 | 92.27 | 92.25 |
| EfficientNet-Lite | 98.27 | 98.63 | 98.44 | 98.56 |
| MobileNet | 97.28 | 96.36 | 97.01 | 96.40 |
| InceptionV3 | 95.85 | 96.18 | 97.35 | 97.17 |
Table 9: External validation results for gender classification on the Mozilla Common Voice dataset using the hybrid MFCC–wav2vec 2.0 feature representation.
| Feature Configuration | Accuracy (%) | Precision (%) | F1-Score ( %) |
| Raw features (No MFCC) | 83.48 | 82.87 | 83.54 |
| MFCC only | 92.64 | 93.79 | 94.84 |
| wav2vec 2.0-only | 95.34 | 96.32 | 95.18 |
| MFCC + wav2vec (Proposed) | 97.87 | 98.61 | 98.65 |
Table 10: Ablation analysis of feature representations using EfficientNet-Lite.
| Evaluation Group | SubGroup | Accuracy (%) | F1-score (%) | FPR | FNR | Demographic Parity Difference | Equal Opportunity Difference |
| Gender | Male | 97.95 | 97.95 | 0.021 | 0.024 | _ | _ |
| Gender | Female | 97.62 | 98.50 | 0.024 | 0.027 | _ | _ |
| Gender disparity | Male vs. Female | _ | _ | _ | _ | 0.012 | 0.003 |
| High-resource languages | 98.10 | 98.80 | 0.018 | 0.021 | _ | _ | |
| Low-resource languages | 96.85 | 97.90 | 0.031 | 0.034 | _ | _ | |
| Language Disparity | High vs. Low | _ | _ | _ | _ | 0.028 | 0.014 |
Table 11: Fairness evaluation across gender and language-resource subgroups. Abbreviations: FPR = false positive rate; FNR = false negative rate. Demographic parity difference and equal opportunity difference represent between-group disparities, so they are reported for subgroup comparisons rather than individual groups. Lower disparity values indicate more consistent model behavior across groups.
| Reference | Approach | Accuracy |
| 16 | GBC | 90%. |
| 17 | Sequential Model | 91% |
| 18 | CNN | 80% |
| 19 | Bagging, KNN and RF | 98.10%. |
| 20 | ResNET50 | 98.57%. |
| 21 | SVM | 98% |
| 22 | LGBM | 91% |
| 23 | Stacked model | 99.64% |
| 24 | SVM | 97% |
| 25 | RF | 93% |
| 26 | CNN | 85.48% |
| 27 | ANN | 89.20% |
| This study | EfficientNet-Lite | 97.87% |
Table 12: Accuracy comparison of VoiceNet-RAI with previously reported state-of-the-art approaches for voice-based gender and age classification.
토론
본 연구에서는 MFCC 특징과 wav2vec 2.0 임베딩을 EfficientNet-Lite와 통합하여 음성 데이터로부터 성별 및 연령을 분류하는 자동화된 프레임워크를 개발하고 평가하였습니다. 초기 실험에서 EfficientNet-Lite는 기존 특징을 사용하여 83.48%의 정확도, 82.87%의 정밀도, 84.28%의 재현율 및 83.54%의 F1-score를 달성하였습니다. MFCC 특징을 통합한 후에는 성능이 크게 향상되어, 28개 언어로 구성된 데이터셋에서 92.64%의 정확도, 93.79%의 정밀도, 94.92%의 재현율 및 94.84%의 F1-score를 기록하였습니다. 영어 언어 서브셋에 하이브리드 MFCC–wav2vec 2.0 표현 방식을 적용했을 때, EfficientNet-Lite는 97.87%의 정확도, 98.61%의 정밀도, 98.70%의 재현율 및 98.65%의 F1-score를 달성하였습니다. 일반화 가능성은 Mozilla Common Voice 데이터셋을 사용하여 추가로 평가하였으며, 제안된 프레임워크는 해당 데이터셋에서도 강력한 성능을 입증하였습니다. 또한, 5-겹 교차 검증을 통해 모델의 안정성을 평가하였습니다.
MFCC 특징을 통합한 후 관찰된 성능 향상은 피치, 음색 및 성도 정보를 포함한 저수준 스펙트럼 특성이 성별 및 연령 분류에 있어 여전히 높은 판별력을 유지함을 나타냅니다. 하이브리드 MFCC–wav2vec 2.0 표현으로 달성한 추가적인 성능 이득은 컨텍스트 기반의 Transformer 임베딩이 수작업으로 설계된 음향 특징만으로는 완전히 포착되지 않는 상보적인 정보를 제공했음을 시사합니다. 이러한 상보성은 기존 설정 및 MFCC 전용 설정과 비교하여 제안된 하이브리드 표현의 성능이 향상된 이유를 설명할 수 있습니다. 영어 언어 서브셋에서 관찰된 더 강력한 성능은 언어적 변동성이 분류 난이도에 기여했을 수 있음을 시사합니다. 여러 언어가 결합되었을 때 발음, 억양, 음성 구조 및 샘플 분포의 차이가 추가적인 변동성을 유발했을 수 있는 반면, 단일 언어 설정은 더 균일한 특징 공간을 제공했습니다. Mozilla Common Voice 데이터셋을 이용한 검증 결과, 녹음 조건과 인구통계학적 분포의 차이가 여전히 성능에 영향을 미쳤을 수 있지만, 제안된 표현이 기본 데이터셋을 넘어 일반화될 수 있음이 추가로 입증되었습니다.
전반적으로, 결과는 VoiceNet-RAI의 성능이 단일 특성 유형보다는 스펙트럼 및 문맥적 음성 표현의 상호 보완적인 기여에 의해 구동되었음을 나타냈습니다. 그러나 언어 및 연령 그룹 간에 남아있는 성능 편차는 더 광범위한 하위 그룹 평가, 소음 강건성 테스트, 그리고 최신 자기지도 학습 음성 모델과의 추가적인 비교가 필요함을 강조했습니다.
음성 기반 성별 및 연령 분류를 위한 대안적 접근 방식에는 전통적인 ML 분류기를 이용한 수작업 기반 음향 특징 추출, 음성 표현으로부터의 CNN 기반 학습, 앙상블 방법, 그리고 HuBERT, WavLM, data2vec와 같은 자기지도 학습 모델 등이 있습니다. 이와 대조적으로, VoiceNet-RAI는 MFCC 기반의 스펙트럼 정보와 문맥적 wav2vec 2.0 임베딩을 결합하여 수작업 기반 음성 표현과 학습된 음성 표현의 상호 보완적인 강점을 활용합니다.
본 연구에는 몇 가지 제한점이 있었습니다. 첫째, 기본 데이터셋의 성별, 언어 및 연령 그룹별 분포가 불균형하여 하위 그룹의 성능에 영향을 미쳤을 수 있으며, 과소 대표된 인구 집단에 대한 일반화 가능성이 제한되었을 수 있습니다. 둘째, 녹음 장치, 억양, 발음 및 음향 조건의 차이가 분류의 신뢰도에 영향을 주었을 가능성이 있습니다. 셋째, Mozilla Common Voice 데이터셋을 이용한 검증을 통해 기본 데이터셋 이외의 일반화 가능성을 확인하였으나, 추가적인 실제 환경 데이터셋을 활용한 더 광범위한 평가가 여전히 필요합니다. 마지막으로, 음성 기반 인구통계학적 분류의 적용은 특히 통제되지 않았거나 영향력이 큰 응용 분야에서 개인정보 보호, 공정성 및 윤리적 문제를 야기할 수 있습니다. 따라서 책임감 있는 구현을 위해서는 지속적인 성능 모니터링, 인간의 감독 및 개인정보 보호를 고려한 배포 관행이 필요할 것입니다. 본 프레임워크는 인간-컴퓨터 상호작용, 음성 기반 인증, 음성 분석 및 디지털 포렌식 분야의 응용 가능성을 보여주었습니다. 향후 연구에서는 VoiceNet-RAI를 HuBERT, WavLM, data2vec를 포함한 최신 자기지도 학습 기반 음성 모델과 비교하고, 융합된 MFCC–wav2vec 2.0 표현에 대해 작업 특화 어텐션을 탐구할 예정입니다. wav2vec 2.0의 내부 셀프 어텐션 메커니즘과 달리, 제안된 향후 메커니즘은 성별 및 연령 분류를 위해 작업과 관련된 시간적 및 특징 수준의 정보에 명시적으로 가중치를 부여할 것입니다.
공개 사항
저자들은 공개할 이해관계 충돌이 없습니다.
감사의 글
저자들은 본 연구에 연구비를 지원해 준 사우디아라비아 리야드의 Princess Nourah bint Abdulrahman University 및 Princess Nourah bint Abdulrahman University 연구자 지원 프로젝트(번호: PNURSP2026R748)에 감사를 표합니다.
재료
| 이름 | 회사 | 카탈로그 번호 | 댓글 |
|---|---|---|---|
| BVC Challenging Voice Set | Biometrics Vision and Computing Group / OgeNI | BVC Challenging Voice Set | https://github.com/OgeNI/BVC_Challenging_Voice_Set |
| EfficientNet-Lite | EfficientNet-Lite, 사용된 정확한 변체 | https://github.com/tensorflow/tpu/tree/master/models/official/efficientnet/lite | |
| 그래픽 처리 장치 | NVIDIA | Tesla K80 | https://www.nvidia.com/ |
| Mozilla Common Voice 데이터셋 | Mozilla Foundation | Common Voice, 실험에 사용된 버전 | https://www.kaggle.com/datasets/mozillaorg/common-voice/data |
| NumPy | NumPy Developers | 실험에 사용된 정확한 버전 | https://numpy.org/ |
| 프로세서 | Intel | Intel Core i7-8265U | https://www.intel.com/ |
| Python | Python Software Foundation | 실험에 사용된 정확한 버전 | https://www.python.org/ |
| PyTorch | PyTorch Foundation | 실험에 사용된 정확한 버전 | https://pytorch.org/ |
| Scikit-learn | Scikit-learn Developers | 실험에 사용된 정확한 버전 | https://scikit-learn.org/ |
| SciPy | SciPy Developers | 실험에 사용된 정확한 버전 | https://scipy.org/ |
| wav2vec 2.0 Base | Meta AI | facebook/wav2vec2-base | https://huggingface.co/facebook/wav2vec2-base |
| Windows 1 | Microsoft | Windows 1, 사용 가능한 경우 정확한 에디션/빌드 | https://www.microsoft.com/windows/windows-1 |
참고문헌
- Pahwa A, Aggarwal G. Speech feature extraction for gender recognition. Int J Image Graph Signal Process. 2016;8:17.
- Ericsdotter C, Ericsson AM. Gender differences in vowel duration in read Swedish: Preliminary results. Work Pap Lund Univ Dep Linguist Phon. 2001;49:34-37.
- Gamit MR, Dhameliya K, Bhatt NS. Classification techniques for speech recognition: A review. Int J Emerg Technol Adv Eng. 2015;5:58-63.
- Rabiner LR, Juang BH. Fundamentals of Speech Recognition. PTR Prentice Hall; Englewood Cliffs, NJ; 1993.
- Hansen JHL, Hasan T. Speaker recognition by machines and humans: A tutorial review. IEEE Signal Process Mag. 2015;32(6):74-99.
- Zhang Y, et al. Towards end-to-end speech recognition with deep convolutional neural networks [conference presentation]. Presented at: Interspeech 2016; San Francisco, CA; 2016. p. 410-414. Available from: https://www.isca-archive.org/interspeech_2016/zhang16b_interspeech.html
- Kabil SH, Muckenhirn H, Magimai-Doss M. On learning to identify genders from raw speech signal using CNNs [conference presentation]. Presented at: Interspeech 2018; Hyderabad, India; 2018. p. 287-291. Available from: https://www.isca-archive.org/interspeech_2018/kabil18_interspeech.html
- Albawi S, Mohammed TA, Al-Zawi S. Understanding of a convolutional neural network [conference presentation]. Presented at: 2017 International Conference on Engineering and Technology (ICET); Antalya, Türkiye; 2017. p. 1-6. Available from: https://ieeexplore.ieee.org/document/8308186
- Abdi H, Williams LJ. Principal component analysis. Wiley Interdiscip Rev Comput Stat. 2010;2(4):433-459.
- Mavaddati S. Voice-based age, gender, and language recognition based on ResNet deep model and transfer learning in spectro-temporal domain. Neurocomputing. 2024;580:127429.
- Jiang H, et al. 3WD-DRT: A three-way decision enhanced dynamic routing transformer for cost-sensitive multimodal sentiment analysis. Inf Sci. 2026;725:122704.
- Jameel HK, Al Ghrairi AHT, Neamah MM. Self-supervised learning for speech recognition: A review. Dijlah J Eng Sci. 2026;3(2).
- Anidjar OH, Yozevitch R. Transformer-based language-independent gender recognition in noisy audio environments. Sci Rep. 2025;15(1):14421.
- Sinha A, Kathania HK, Kurimo M. A study on the layer-wise transferability of self-supervised learning features for children's speech processing tasks. Speech Commun. 2026;180:103392.
- Li M, Han KJ, Narayanan SS. Automatic speaker age and gender recognition using acoustic and prosodic level information fusion. Comput Speech Lang. 2013;27(1):151-167.
- Sánchez-Hevia HA, Gil-Pita R, Utrilla-Manso M, Rosa-Zurera M. Age group classification and gender recognition from speech with temporal convolutional neural networks. Multimed Tools Appl. 2022;81:3535-3552.
- Abu Mallouh A, Qawaqneh Z, Barkana BD. New transformed features generated by deep bottleneck extractor and a GMM–UBM classifier for speaker age and gender classification. Neural Comput Appl. 2018;30:2581-2593.
- Almomani A, et al. Age and gender classification using backpropagation and bagging algorithms. Comput Mater Contin. 2023;74(2):3045-3062.
- Sahar RM, Rao TS, Anuradha S, Rao BS. Performance analysis of ML algorithms to detect gender based on voice. In: Recent Trends in Intensive Computing. 2021. p. 163-171. Available from: https://journals.sagepub.com/doi/abs/10.3233/APC210192
- Kone VS, et al. Voice-based gender and age recognition system [conference presentation]. Presented at: 2023 International Conference on Advancement in Computation & Computer Technologies (InCACCT); Gharuan, India; 2023. p. 74-80. Available from: https://ieeexplore.ieee.org/document/10141801
- Alhussein M, Muhammad G. Voice gender recognition under unconstrained environments using self-attention. Appl Acoust. 2021;175:107823.
- Yücesoy E. Automatic age and gender recognition using ensemble learning. Appl Sci. 2024;14(16):6868.
- Alnuaim AA, et al. Speaker gender recognition based on deep neural networks and ResNet50. Wirel Commun Mob Comput. 2022;2022:4444388.
- Ibrahim F, Nahar KMO, Al-Shannaq MA. Gender identification and age estimation of Arabic speaker using machine learning. J Theor Appl Inf Technol. 2020;98(19):3242-3256.
- Kannapiran P, Sindha MMR. Voice-based gender recognition model using FRT and LightGBM. Teh Vjesn. 2023;30:282-291.
- Alkhammash EH, Hadjouni M, Elshewey AM. A hybrid ensemble stacking model for gender voice recognition approach. Electronics. 2022;11:1750.
- Mutiany M, Herlistiono IO. Gender detection by voice using deep learning. Int J Innov Sci Res Technol. 2020;5(10):841-845.
- Raahul A, Sapthagiri R, Pankaj PK, Vijayarajan V. Voice based gender classification using machine learning. IOP Conf Ser Mater Sci Eng. 2017;263(4):042083. Available from: https://iopscience.iop.org/article/10.1088/1757-899X/263/4/042083
- Iloanusi O, et al. Voice recognition and gender classification in the context of native languages and lingua franca [conference presentation]. Presented at: 2019 6th International Conference on Soft Computing & Machine Intelligence (ISCMI); Johannesburg, South Africa; 2019. p. 175-179. Available from: https://ieeexplore.ieee.org/document/9004306
- Gupta Y, Gangwar K, Singhal M, Hemavathi D. Gender and age recognition using audio data-artificial neural networks. In: Soft Computing for Security Applications: Proceedings of ICSCS 2021. Springer; 2022. p. 449-470. Available from: https://link.springer.com/chapter/10.1007/978-981-16-5301-8_34
- Qawaqneh Z, Mallouh AA, Barkana BD. Deep neural network framework and transformed MFCCs for speaker’s age and gender classification. Knowl-Based Syst. 2017;115:5-14.
- OgeNI. BVC Challenging Voice Set [Internet]. GitHub; 2025 [cited 2026 Aug 16]. Available from: https://github.com/OgeNI/BVC_Challenging_Voice_Set
- Oppenheim AV, Schafer RW. Discrete-Time Signal Processing. 3rd ed. Pearson; Upper Saddle River, NJ; 2010.
- Logan B. Mel frequency cepstral coefficients for music modeling [conference presentation]. Presented at: International Society for Music Information Retrieval Conference (ISMIR); Plymouth, UK; 2000. Available from: https://ismir.net/conferences/ismir-2000/
- Davis SB, Mermelstein P. Comparison of parametric representations for monosyllabic word recognition in continuously spoken sentences. IEEE Trans Acoust Speech Signal Process. 1980;28(4):357-366.
- Baevski A, Zhou H, Mohamed A, Auli M. wav2vec 2.0: A framework for self-supervised learning of speech representations [conference presentation]. Presented at: Advances in Neural Information Processing Systems 33 (NeurIPS 2020); Virtual; 2020. p. 12449-12460. Available from: https://proceedings.neurips.cc/paper/2020/hash/92d1e1eb1cd6f9fba3227870bb6d7f07-Abstract.html
- Yıldırım Ş, Bingöl MS. Metaheuristic approaches to enhance voice-based gender identification using machine learning methods. Appl Sci. 2025;15(23):12815.
- Breiman L. Random forests. Mach Learn. 2001;45:5-32.
- Hosmer DW Jr, Lemeshow S, Sturdivant RX. Applied Logistic Regression. 3rd ed. Wiley; Hoboken, NJ; 2013.
- Geurts P, Ernst D, Wehenkel L. Extremely randomized trees. Mach Learn. 2006;63:3-42.
- Yücesoy E, Nabiyev VV. A new approach with score-level fusion for the classification of a speaker age and gender. Comput Electr Eng. 2016;53:29-39.
- Cortes C, Vapnik V. Support-vector networks. Mach Learn. 1995;20:273-297.
- Abdel-Hamid O, et al. Convolutional neural networks for speech recognition. IEEE/ACM Trans Audio Speech Lang Process. 2014;22(10):1533-1545.
- Nasaruddin N, Pratama Tresma MAP, Muchamad MK, Fuadi Z. Voice frequency-based gender classification using convolutional neural network for smart home. IEEE Access. 2024;12:104190-104203.
- Simonyan K, Zisserman A. Very deep convolutional networks for large-scale image recognition [conference presentation]. Presented at: International Conference on Learning Representations (ICLR); San Diego, CA; 2015. Available from: https://iclr.cc/archive/www/2015.html
- Tan M, Le QV. EfficientNet: Rethinking model scaling for convolutional neural networks [conference presentation]. Presented at: 36th International Conference on Machine Learning (ICML); Long Beach, CA; 2019. p. 6105-6114. Available from: https://proceedings.mlr.press/v97/tan19a.html
- Ertam F. An effective gender recognition approach using voice data via deeper LSTM networks. Appl Acoust. 2019;156:351-358.
- Zhao L, Wang L, Jia Y, Cui Y. A lightweight deep neural network with higher accuracy. PLoS One. 2022;17(8):e0271225.
- Szegedy C, et al. Rethinking the Inception architecture for computer vision [conference presentation]. Presented at: IEEE Conference on Computer Vision and Pattern Recognition (CVPR); Las Vegas, NV; 2016. p. 2818-2826. Available from: https://openaccess.thecvf.com/content_cvpr_2016/html/Szegedy_Rethinking_the_Inception_CVPR_2016_paper.html
- Sokolova M, Lapalme G. A systematic analysis of performance measures for classification tasks. Inf Process Manag. 2009;45(4):427-437.
- Mozilla Common Voice Project. Common Voice Dataset [Internet]. 2024 [cited 2024 Jun 18]. Available from: https://www.kaggle.com/datasets/mozillaorg/common-voice/data