This study presents a Bayesian Network–based workflow for analyzing ownership of AI-generated content under legal and technical uncertainty. Using AI litigation, copyright datasets, and framework models, factors such as human contribution, contracts, legality of training data, and AI autonomy to support transparent, interpretable, and scenario-based decision-making in intellectual property disputes.
Research Article
Modeling Legal Uncertainty in AI-Generated Content Ownership: A Bayesian Network Approach to Intellectual Property Rights Allocation
In This Article
Summary
Abstract
The rapid adoption of generative artificial intelligence has exposed limitations in traditional intellectual property frameworks based on human authorship, creating uncertainty in ownership attribution. This study proposes a Bayesian Network–based workflow for analyzing ownership of AI-generated content under legal and technical uncertainty. The workflow integrates dataset curation, variable annotation, probabilistic dependency modeling, inference generation, cross-validation, and sensitivity analysis to evaluate relationships among factors, including human contribution, the legality of training data, contractual context, and AI autonomy. The framework was developed using annotated cases derived from a curated AI litigation dataset, publicly available court opinion databases, and AI copyright case trackers. A sensitivity analysis was conducted to examine the influence of legal and technical variables on ownership attribution across different scenarios. The proposed framework supports probabilistic and interpretable reasoning for AI-related intellectual property disputes and provides a structured decision-support approach for legal professionals, policymakers, and AI developers. Results demonstrated stable posterior probability estimates across folds, with ownership prediction consistency exceeding 80% across datasets. The framework enables probabilistic, scenario-based reasoning and provides an interpretable decision-support tool, improving transparency and consistency in resolving ownership disputes for legal professionals, policymakers, and AI developers.
Introduction
The growing use of artificial intelligence (AI) systems in high-stakes industries, including healthcare, criminal justice, finance, and digital platforms, raises important questions about legal responsibility, accountability, and fairness. Despite rapid progress, a large portion of the literature on AI governance is either normative or predictive and lacks empirical support1,2. Current methods for discovering AI-related problems, such as event databases, survey-based research, and ethical frameworks, frequently fall short of capturing persistent problems in the actual world. These approaches either overemphasize high-profile occurrences while ignoring systemic, practice-level issues or reflect expectations rather than observable damage3,4. The majority of incident databases rely on voluntary reporting and media coverage, which frequently highlights high-profile failures while underrepresenting common but important AI-related problems5,6. By enabling systems to produce text, images, and music using transformer-based deep learning architectures, generative AI, especially Large Language Models (LLMs), has made content production even more challenging7,8,9. Traditional intellectual property frameworks based on human authorship are facing difficulties as a result of this change, making it harder to distinguish between human and machine-generated innovation10,11,12.
Previous studies on AI-generated content and intellectual property have mostly focused on policy analysis and legal interpretation, including conceptual discussions of authorship, originality, and ownership13. Even while these studies offer valuable insights, they remain primarily descriptive and lack computational methods to address ownership-determination uncertainty14. Simultaneously, technological methods to support content attribution and provenance have been developed, including watermarking, fingerprinting, and dataset protection15. The legal distribution of ownership, however, is not addressed by these approaches, especially in multi-stakeholder settings with developers, users, and data producers. Additionally, current interdisciplinary studies have not made sufficient progress toward probabilistic models that can integrate technical and legal factors for ownership evaluation in the face of uncertainty16,17,18,19,20. Legal studies have highlighted the limitations of existing intellectual property frameworks in addressing ownership of AI-generated content. In many jurisdictions, including under Section 13 of the Indian Copyright Act, AI-generated works often fail to satisfy traditional authorship criteria, creating ownership ambiguity21,22. Although prior studies discuss judicial interpretations and copyright implications, they lack formal mechanisms for modeling uncertainty in ownership determination22,23. To address this gap, this study proposes a Bayesian Network–based framework that models probabilistic relationships among human involvement, training data provenance, contractual context, and AI autonomy for scenario-based ownership analysis24.
Research has explored the application of machine learning models such as logistic regression, support vector machines (SVMs), convolutional neural networks (CNNs), and long short-term memory (LSTM) networks in legal decision-making, demonstrating their usefulness in high-volume legal environments where manual precedent analysis is time-consuming25. However, these approaches often lack interpretability and transparency, which are essential for accountable judicial decision support. Consequently, Explainable Artificial Intelligence (XAI) methods have attracted attention for improving interpretability and providing understandable reasoning for AI-assisted decisions26,27,28.
| Methodology / Approach | Data Used | Pros | Cons / Gaps |
| Review of legal & technical instruments to link content to training data & propose frameworks for attribution and accountability.29 | Literature survey, case examples | Integrates tech + law perspective; proposes actionable attribution strategies | Lacks formal probabilistic modeling; no quantitative validation |
| Taxonomy of technical IP protection methods for training/outputs of generative models.30 | Survey of technical approaches and risks | Systematic review; organizes existing techniques for IP protection | Focuses on training-data protection vs ownership of generated output |
| Proposes latent fingerprinting / watermarking to verify AI origin & IP attribution.31 | Experiments with generative models (text & image) | Practical verification tool; strong for ownership evidence | Watermarking doesn’t resolve legal ownership frameworks itself |
| Comparative legal analysis of authorship & ownership standards across jurisdictions.32 | Legal doctrine, statutory texts, representative cases | Explains how human contribution affects ownership decisions | Descriptive; does not propose computational models |
Table 1: Summary of Methodologies, Data Sources, and Key Findings in Prior Work. Overview of existing studies on AI-generated content ownership, highlighting methodological approaches, datasets utilized, and major findings.
Table 1 summarizes the existing methodologies, data sources, and key findings29,30,31,32. This table discusses the ownership of AI-generated content in the literature and highlights the methodological approaches, utilized datasets, and the findings of the considered literature. Recent studies on AI governance and copyright disputes have further highlighted challenges related to authorship, training data legality, and ownership allocation in AI-generated content33,34. Although approaches such as provenance tracking and evidence validation contribute to attribution analysis34, existing rule-based and machine learning methods remain limited in handling ambiguity, conflicting evidence, and legally interpretable ownership reasoning. Technical approaches such as watermarking and provenance analysis also primarily focus on attribution rather than ownership determination.
This paper proposes a Bayesian Network-based framework for evaluating ownership of AI-generated content amid legal and technical ambiguity, overcoming the shortcomings of current deterministic, rule-based approaches. The approach enables scenario-based inference from incomplete or ambiguous evidence by modeling probabilistic interactions among key aspects, including human engagement, training data provenance, contractual context, and AI autonomy. The suggested method, unlike traditional predictive models, offers interpretable posterior probability estimates that facilitate clear, organized reasoning consistent with judicial decision-making procedures.
Important legal and technological concepts are explicitly defined to ensure consistency throughout the study. While “ownership” relates to the distribution of rights related to the produced work, “authorship” refers to the legal acknowledgment of a creator. “Attribution” may not always indicate legal ownership, but it does identify contributing entities. “Explainability” refers to a model's capacity to provide a comprehensible justification for probabilistic outcomes, whereas “legal uncertainty” refers to ambiguity arising from incomplete or changing legal standards. By incorporating legal and technical factors into an interpretable probabilistic workflow, the suggested approach aims to facilitate structured decision-making in AI-related intellectual property conflicts. For legal experts, legislators, and AI developers assessing ownership concerns in generative AI systems, the technique offers a computational viewpoint.
Protocol
This study does not involve human participants or animal subjects. The analysis is based solely on publicly available legal case materials and curated legal datasets. Therefore, ethics approval and informed consent were not required.
The proposed methodology aims to capture the legal uncertainty surrounding ownership of AI-created content by developing a Bayesian Network based on actual case data. To start with, cases related to AI, including copyright, patent, and trade secrets, would be harvested from an existing corpus and each tagged with actual legal outcome data. Based upon legal precedent and existing case studies, uncertainty parameters that could have an impact on content ownership would include creative human input, AI system autonomy, legality of training data, contractual definitions of ownership, jurisdiction, and transparency, each assigned as nodes within the Bayesian Network with discreet states indicating differing legal and technical realities, and with content ownership determination as the target node. The structure of this network is discovered by integrating legal expertise with data-driven structural discovery to promote both interpretability and legal plausibility. The tables of conditional probabilities are then approximated based on litigation outcomes identified in cases, allowing the network to process uncertain and incomplete data probabilistically. Subsequent to model training, it allows for both inferencing and scenario testing to determine how changes in contributing factors impact inferred ownership in AI-generated content based on this constructed Bayesian Network, followed by testing and sensitivity analysis validation prior to inferring results that facilitate future legal implications for intellectual property in AI applications by developers and in courts. Figure 1 shows the architectural workflow of the proposed work.
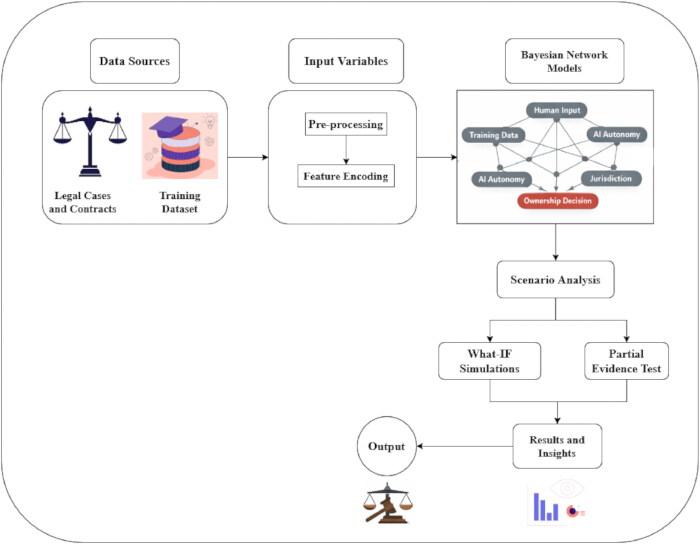
Figure 1: Architectural Diagram of the Proposed Framework: Overview of the proposed Bayesian Network–based system for determining ownership of AI-generated content. The architecture illustrates the flow from data acquisition and annotation to probabilistic modeling, inference, and ownership attribution. Please click here to view a larger version of this figure.
Figure 1 illustrates the architectural workflow of the proposed Bayesian Network–based framework for AI-generated content ownership analysis. The workflow includes data collection, feature annotation, Bayesian Network modeling, probabilistic inference, scenario analysis, and validation. Legal and technical variables, such as human involvement, AI autonomy, training data provenance, contractual context, and jurisdiction, are modeled within a Bayesian framework to estimate ownership attribution under uncertain conditions. The framework supports interpretable probabilistic reasoning and scenario-based evaluation for legal decision support.
Data collection
Data on legal cases was collected from various sources to create a dataset focused on ownership and intellectual property lawsuits involving AI-generated content. To start, the general dataset of legal cases sourced in the base paper was filtered to include only litigations concerning copyright, ownership, IP-related disputes, and other IP matters in the training data. Additional legal cases were obtained from publicly available court-opinion databases that provide access to court opinions from millions of cases, as well as a copyright case-tracking repository that tracks both ongoing and concluded legal proceedings worldwide on uses of Artificial Intelligence regarding Intellectual Property. Legal cases were also annotated to highlight key variables, including the legal case outcome, the level of human creative input, the autonomy of the Artificial Intelligence system, the origin of the training data, jurisdiction, and contract parameters, if applicable. This is a multi-source dataset that aggregates sufficient data on Intellectual Property related to the use of AI tools, suitable for probabilistic reasoning in Bayesian network analysis.
Three main sources, including the base AI litigation dataset, a public court-opinion database, and an AI copyright case tracking repository, were used in a methodical collection and screening process to create the dataset for this study. Keywords such as “artificial intelligence,” “AI-generated content,” “copyright,” “intellectual property,” “authorship, “ownership,” and “machine-generated works” were used throughout repository search interfaces and metadata fields to find pertinent cases. Cases involving AI-generated or AI-assisted content that addressed ownership, authorship, or intellectual property concerns with enough depth for variable extraction were considered. Cases that were duplicates, unconnected to AI-generated content, concentrated on other legal areas, or lacked adequate information were not accepted. A two-phase screening procedure was used, with a full-text eligibility assessment coming after the initial title and summary examination. To ensure uniqueness, duplicate records across multiple datasets were identified using case metadata and removed.
The keywords “artificial intelligence,” “AI-generated content,” “machine-generated works,” “copyright,” “authorship,”“ownership,”“training data,” and “intellectual property dispute” were used in the dataset search process. To guarantee the quality and relevance of the dataset, a two-stage screening procedure was used. To find ownership and copyright conflicts pertaining to AI, titles and case summaries were reviewed in the first stage. To determine eligibility for inclusion in the study, a full-text case review was conducted in the second stage. Only cases involving AI-generated or AI-assisted content, with adequate legal and technical details regarding authorship, ownership attribution, contractual context, or training data usage, were included. Excluded were cases with insufficient contextual information, inadequate legal documents, duplicate entries, and cases unrelated to intellectual property conflicts. By comparing metadata such as case title, jurisdiction, filing date, and dispute category, duplicate cases across sources were identified and eliminated. Annotation, Bayesian Network modeling, probabilistic inference, and sensitivity analysis were then performed on the final curated dataset.
The data employed in the study comprises a compilation of legal sources covering the full scope of disputes over AI content ownership rights and intellectual property claims, as shown in Table 2. First, the AI litigation data used in the primary study includes the selective preservation of about 72 legal disputes specifically tied to copyright claims, authorship, authorship by invention, and ownership involving AI outputs. To increase data variability for better representation of emerging disputes in the realm of generative AI, the data includes the acquisition of relevant disputes sourced from the publicly available court opinion database (CAP), a massive publicly available collection of U.S. court opinions, to select specific AI-IP disputes of 38 claims based on relevant IP legal terms. Additionally, the study uses the AI and Copyright Case Tracker to include 21 world-leading AI copyright disputes, based on an AI-trained copyright legal analysis approach that refines the creation of a customized AI copyright case tracker for major international legal disputes, using specific initial analysis approaches involving AI copyright dispute analysis. The final dataset consisted of 131 cases: a base AI litigation dataset, a public court-opinion database, and an AI copyright case-tracking repository. These cases were selected after applying inclusion, exclusion, and deduplication procedures.
| Dataset Source | Dataset Type | No. of Cases Used | Coverage |
| Base AI Litigation Dataset1 | AI-related court cases | 72 (filtered subset) | U.S. federal and state courts |
| Caselaw Access Project (CAP)31 | Public legal case corpus | 38 (AI-IP focused) | U.S. court opinions |
| AI & Copyright Case Tracker (CMS)32 | Curated case summaries | 21 landmark cases | Global (US, EU, UK) |
Table 2: Dataset Description. Summary of datasets used for modeling intellectual property disputes in AI-generated content, including source, structure, and relevance to ownership analysis.
To ensure accuracy and consistency, a combination of manual and semi-automated processes was used. The labeling method used three annotators with backgrounds in both law and AI-related legal studies. All variables, including human creative input, AI system autonomy, training data legality, contractual ownership provisions, jurisdiction, transparency of AI involvement, and explicit decision rules and examples, were defined in an annotated codebook. Two annotators independently annotated each instance; differences were settled by discussion and, if needed, by a third expert reviewer. Cohen's kappa coefficient was used to measure inter-rater agreement; the result was 0.81, indicating strong agreement. About 9% of cases involved disagreements, mostly over AI autonomy and contract interpretation. For further Bayesian Network modeling, the completed annotations were utilized.
Identification of legal uncertainty factors
Key sources of uncertainty in AI-generated content ownership were identified through an analysis of AI-related intellectual property cases across multiple legal datasets, including litigation-based datasets and publicly available court repositories. Human creativity, AI autonomy, the legality of training data, contractual connections, jurisdictional issues, and the transparency of AI systems were important factors. The degree of human engagement and contractual ownership definitions were often highlighted by courts, and legal ambiguity was exacerbated by differences in copyright laws and the usage of copyrighted training data. The Bayesian Network framework for probabilistic ownership analysis was developed based on these considerations.
| Factor | Description |
| Human Creative Involvement | Degree of human contribution in generating the content (high, moderate, or minimal). |
| Level of AI Autonomy | Extent to which the AI system operates independently without human guidance. |
| Training Data Ownership and Legality | Legal status of the training data used (licensed, public domain, proprietary, or infringing). |
| Contractual Ownership Clauses | Existence and clarity of agreements defining ownership among stakeholders. |
| Jurisdictional Legal Framework | Applicable national or regional intellectual property laws. |
| Purpose of Use | Whether the AI-generated content is used for commercial or non-commercial purposes. |
| Transparency and Explainability | Availability of information regarding the AI system’s design and operation. |
| Disclosure of AI Assistance | Whether the use of AI in content creation was explicitly disclosed. |
| Nature of Generated Content | Type of output produced (e.g., text, image, code, or design). |
| Judicial Precedent Availability | Presence of prior court rulings relevant to AI-generated content ownership. |
Table 3: Key Legal and Technical Uncertainty Factors Influencing Ownership. Identification of critical variables affecting ownership attribution in AI-generated content, encompassing both legal and technical dimensions.
Table 3 summarizes the ownership attribution-related uncertainties in the proposed Bayesian Network model. These uncertainties are derived based on the intellectual property disputes associated with AI and the existing intellectual property laws. Human creative input and autonomy in AI refer to the relationship between human authors and AI-generated content in determining ownership. The uncertainties, including the legality of the training data used by AI, ownership of the contract, and the jurisdiction's existing intellectual property laws, are grounds for dispute. The purpose of use and AI assistance disclosure refers to the circumstances in which the judicial system views AI-assisted generation. Transparency and explainability, on the other hand, refer to the aspect associated with accountability and responsibility. Other uncertainties, including the nature of AI-generated creations and existing judicial precedents, determine how existing intellectual property laws apply to AI creations.
Data annotation and variable encoding
The dataset, constructed from filtered AI litigation cases, CAP, and selected AI copyright cases, among others, shall then be annotated manually and semi-automatically based on legal uncertainty factors identified for each case. For each case Structured labels are determined by evaluating court opinions, descriptions, and reasoning. The annotation task involves determining both legal and technical factors, such as the level of human creative participation, the autonomy of AI, the legal validity of the training data, contractual clauses on ownership, jurisdiction, and the disclosure of assistance by AI. For consistency, the guidelines are derived from other intellectual property principles and verified through cross-checking across a variety of legal sources. Refer to Supplementary File 1(S1) for a detailed mathematical description of data annotation and variable encoding.
The framework was implemented using a programming language with probabilistic graphical modeling libraries and numerical computing tools. Data preprocessing and analysis were performed in a notebook-based computing environment on a desktop system with a multi-core processor and standard memory configuration
To ensure consistency and reproducibility in dataset annotation, a structured variable-coding scheme was developed for all legal and technical factors included in the Bayesian Network framework. Each case was manually reviewed and annotated using predefined categorical states derived from legal precedents and AI governance literature. Table 4 summarizes the variables, descriptions, and coding categories used in the study. To facilitate probabilistic modeling and scenario-based inference within the Bayesian Network framework, the coding system was applied uniformly across all annotated cases. To represent often observed legal and technological circumstances in conflicts involving AI-generated material, variable states were chosen.
| Variable | Description | Coding Categories |
| Human Contribution | Degree of human creative involvement in content generation | Low, Medium, High |
| AI Autonomy | Level of independent AI system generation | Low, Medium, High |
| Training Data Legality | Legal status of datasets used for AI training | Licensed, Public Domain, Uncertain, Unauthorized |
| Contractual Ownership | Presence of contractual ownership clauses | Present, Absent |
| Attribution Clarity | Clarity of contributor identification | Clear, Partial, Unclear |
| Jurisdiction | Legal jurisdiction associated with the dispute | India, United States, China, Other |
| Transparency | Availability of information regarding AI generation process | High, Moderate, Low |
| Ownership Outcome | Final ownership attribution outcome (target variable) | Human-Owned, Shared Ownership, Organization-Owned, Uncertain |
Table 4: Variable Coding Scheme Used for Bayesian Network Annotation. The table summarizes the legal and technical variables used during dataset annotation, including their definitions and categorical coding states applied for probabilistic modeling and ownership inference.
Bayesian network structure design
The Bayesian Network (BN) was created to model the probabilistic relationships among contextual, technological, and legal factors that affect the ownership of information produced by artificial intelligence. While the target node depicted ownership results, the network nodes represented variables such as human contribution, AI autonomy, training data legality, contractual ownership terms, and jurisdiction. Conditional dependencies arising from data-driven associations and judicial reasoning processes were recorded by directed edges. Data-driven optimization and legal constraints were combined into a hybrid structure-learning method. Allowable dependencies were determined by judicial principles, and the most likely dependency graph explaining reported litigation results was found using score-based structure learning. This method ensured that the final network would remain both legally interpretable and statistically valid.
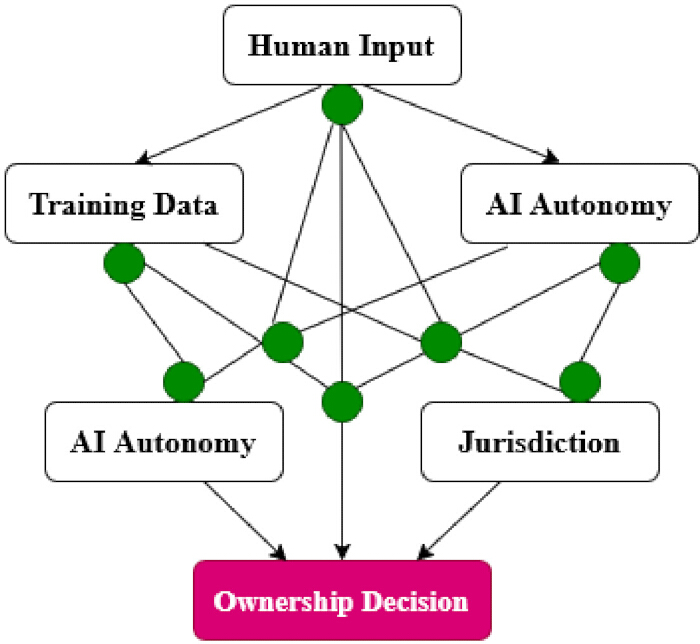
Figure 2: Bayesian Network structure used for ownership inference. Graphical representation of the Bayesian Network showing dependencies among legal and technical variables influencing ownership decisions. Please click here to view a larger version of this figure.
Figure 2 shows how a Bayesian Network is employed in AI-generated content ownership assignments. On a top-level model, some essential input variables, namely Human Input, Training Data, AI Autonomy, and Jurisdiction, indicate some essential legal and technical dimensions that should be considered when rendering a right over AI-generated content. Every variable is designated as a probable node rather than a hard-coded rule, enabling a model that accounts for variable dependencies. The green nodes, also known as connection points, appear between the input nodes and the final output. They indicate, for instance, how levels of human involvement correlate with AI autonomy, while both legal training data and jurisdictional factors help define a right to AI-generated content from a jurisdictional perspective.
Legal theory and annotated litigation data served as the foundation for the Bayesian Network's variable selection and discrete state definitions. Given their importance in determining ownership, key factors such as human involvement, AI autonomy, the legality of training data, contractual conditions, jurisdiction, and transparency were given top priority. Expert-reviewed annotation criteria were used to discretize variables into legally significant categories. To identify statistically supported dependencies, a hybrid strategy combining score-based learning and legal constraints was used to construct the network structure. The approach was further validated using sensitivity and ablation studies, which confirmed the significant impact of human input and contractual restrictions on ownership inference, while other variables showed moderating effects. For decision-support systems, this combined legal-empirical approach enhances both robustness and interpretability.
The inferred probabilities from all interconnected nodes converge at the Ownership Decision node, which generates posterior ownership probabilities based on the available legal and technical evidence. This enables ownership inference even under incomplete or disputed conditions and supports dynamic updating when new evidence becomes available. To reduce overfitting and spurious correlations, model selection and sensitivity analysis were used to remove redundant or low-impact edges, yielding a concise directed acyclic graph (DAG). The final Bayesian Network structure captures both probabilistic dependencies and causal relationships among factors contributing to legal uncertainty in AI-generated content ownership. The mathematical description of the Bayesian network design is provided in Supplementary File 1 (S2).
The Bayesian Network enables probabilistic ownership inference even when some legal or technical factors are incomplete or partially observable. By modifying evidence variables, the framework also supports scenario-based analysis for legal decision-making, policy evaluation, and AI governance applications. The network structure was developed using a hybrid approach combining expert-defined legal constraints with data-driven learning. A Hill Climbing algorithm with Bayesian Information Criterion (BIC) scoring was used for structure optimization, while Bayesian parameter estimation with Dirichlet priors and Laplace smoothing (&α = 1) addressed data sparsity and missing observations. All variables were represented as discrete categorical states to support probabilistic inference. Python probabilistic graphical modeling modules were used to construct the Bayesian Network framework. The two phases of network building were parameter learning and structure definition. Initially, the network's nodes represented the legal and technical characteristics found during dataset annotation. A hybrid method that coupled data-driven structural dependency analysis with expert-defined legal relationships was used to create directed edges between nodes. Maximum likelihood estimation was used to estimate Conditional Probability Tables (CPTs) from the annotated dataset. The probabilistic graphical modeling techniques within a computational environment package were used to implement the Bayesian Network, with the Maximum Likelihood Estimator function for parameter learning and the Bayesian Network () function for defining the network structure. The Variable Elimination () inference procedure was used to calculate posterior ownership probabilities under various evidence conditions.
Parameter learning
In quantitatively modeling legal uncertainty in AI-generated content ownership, parameter estimation is a crucial step in the proposed Bayesian Network framework. Bayesian parameter estimate was used to learn Conditional Probability Tables (CPTs) from annotated legal cases. While the goal node indicates ownership attribution, each node reflects a legal or technological aspect, such as human contribution, AI autonomy, the legality of training data, or contractual ownership provisions. Because Bayesian estimates can handle scant legal material and inadequate evidence, it was chosen to promote interpretable legal reasoning and to represent probabilistic correlations observed in judicial decisions. Representative conditional probability values acquired within the Bayesian Network are shown in Table 5. While great AI autonomy promotes uncertainty or no-ownership outcomes, significant human creative engagement indicates a substantial probability of human ownership, indicating judicial emphasis on human intellectual contribution. The findings also emphasize the importance of contractual ownership terms and the legality of training data, with explicit agreements and licensed data increasing ownership. The framework's sensitivity to various legal situations is further demonstrated by jurisdictional variances.
| Parent Variables | States of Parent Variables | Ownership Outcome | Learned Conditional Probability |
| Human Creative Involvement | High | Human Author | 0.82 |
| Human Creative Involvement | Low | AI Developer | 0.41 |
| AI Autonomy | High | No Ownership Recognized | 0.55 |
| Training Data Legality | Licensed | Human / Developer | 0.76 |
| Training Data Legality | Infringing | No Ownership / Disputed | 0.68 |
| Contractual Ownership Clause | Explicit Present | Contractual Party | 0.89 |
| Contractual Ownership Clause | Absent | Disputed / Uncertain | 0.61 |
| Jurisdictional Framework | Human-Centric IP Law | Human Author | 0.79 |
| Jurisdictional Framework | Ambiguous / Emerging Law | Joint / Uncertain | 0.47 |
Table 5: Example Conditional Probabilities in the Bayesian Network Model. Illustrative conditional probability values learned by the Bayesian Network, demonstrating dependencies among key variables influencing ownership outcomes.
Algorithm 1 encapsulates the entire process of the proposed Bayesian Network framework for capturing ownership uncertainties in AI content. Algorithm 1: Initiate a Bayesian Network structure by defining the graphical model where the nodes are the technical and legal uncertainties examined in the litigations with annotated information, and the target node is the ownership designation. The structure of the Bayesian Network model can then be established by applying a joint approach that merges the existing legally constraining structures with optimized structures derived from the data. The conditional probability tables can then be specified by implementing the Bayesian parameter estimation scheme based on the obtained dataset, thereby accounting for uncertainties, sparsity, and conditional relationships inferred by the judiciary. When applying the algorithm to a particular legal or hypothetical example, the input information or evidence can be elicited in the Bayesian Network by applying probabilistic inference to determine the posterior probability of ownership. The algorithm can then apply adjustments to the input values by iteratively modifying the evidence input to the Bayesian Network and assessing the impact on ownership designation by adjusting the human input, AI autonomy, contractual legality, and the legality of the training data. Refer to Supplementary File 1(S3) for Algorithmic steps.
Probabilistic inference and scenario analysis
The Bayesian Network's graphical structure and conditional probability tables can then be trained on an annotated dataset of AI-related litigation regarding ownership, and the system enables inference on the likelihood of ownership. The mathematical descriptions are stated in Supplementary File 1 (S4).
By observing how these posterior ownership probabilities vary across counterfactual scenarios, the model yields a set of relative influences on judicial outcomes for each legal and technical feature. This scenario-driven inference capability constitutes one of the main contributions of the proposed work, since it aligns with how courts, policymakers, and legal experts reason about the ownership of AI-generated content: through contextual evaluation rather than the rigid application of rules. The Bayesian Network hereby serves as an explainable decision-support tool, transforming empirical litigation patterns into probabilistic insights that support consistent reasoning across jurisdictions, contractual contexts, and levels of AI autonomy. Accordingly, such a usability factorial moves beyond descriptive legal analysis by providing a systematic mechanism for anticipating ownership outcomes under evolving AI and intellectual property regimes. The Variable Elimination approach was used to calculate the posterior probability of ownership outcomes for inference. Iteratively changing the evidence variables and recalculating posterior distributions allowed for scenario analysis. To ensure resilience across small datasets, the model was validated using leave-one-out validation and k-fold cross-validation (k = 5). To perform a sensitivity analysis, input variables were systematically varied, and the accompanying changes in posterior probabilities (ΔP(Y)) were measured.
Model validation and sensitivity analysis
The suggested Bayesian Network model was verified using an annotated dataset of AI-related intellectual property conflicts to guarantee dependability, robustness, and legal applicability. To forecast ownership outcomes and compare them with actual legal decisions, a retrospective validation approach was used. Given the scarcity of AI-related ownership dispute situations, leave-one-out and k-fold cross-validation were used to assess the model's robustness.
The impact of legal and technical factors on ownership attribution, including human involvement, AI autonomy, the legality of training data, and contractual ownership terms, was investigated through a sensitivity analysis. The investigation identified contextual and high-impact factors that influence ownership choices by altering parent node states and monitoring changes in posterior probabilities. By showing how legal ambiguity spreads throughout the network, this enhanced interpretability. The validation and sensitivity analysis findings are collected in Table 6. During cross-validation, the model achieved more than 80% agreement between inferred and actual judicial outcomes. Robustness testing verified trustworthy inference under limited-evidence settings, and low posterior variance across folds suggested stable, generalizable conditional probabilities. Sensitivity analysis revealed that while AI autonomy and the legality of training data greatly increased attribution uncertainty, contractual ownership clauses and human creative involvement had the greatest impact on ownership attribution. Technical and contractual conditions interacted with jurisdictional variables, exerting a moderate effect. Overall, the findings show that the suggested paradigm is both legally interpretable and empirically sound.
| Validation / Sensitivity Aspect | Method Applied | Metric / Observation |
| Case-Based Validation | Leave-one-out cross-validation | 81.3% ownership outcome consistency |
| Cross-Fold Stability | 5-fold cross-validation | Posterior variance < 0.05 across folds |
| Missing Evidence Robustness | Partial evidence inference | < 7% change in posterior probabilities |
| Sensitivity: Human Creative Involvement | One-factor perturbation | ΔP(Y) ≈ +0.32 |
| Sensitivity: AI Autonomy | One-factor perturbation | ΔP(Y) ≈ −0.28 |
| Sensitivity: Training Data Legality | One-factor perturbation | ΔP(Y) ≈ +0.25 |
| Sensitivity: Contractual Clauses | One-factor perturbation | ΔP(Y) ≈ +0.37 |
| Sensitivity: Jurisdiction | One-factor perturbation | ΔP(Y) ≈ +0.14 |
Table 6: Validation and Sensitivity Analysis Results. Results of model validation and sensitivity analysis, evaluating robustness, stability, and the impact of key variables on ownership inference.
Interpretation and policy implication analysis
The probabilistic outputs of the Bayesian Network provide an interpretable framework for analyzing ownership of AI-generated content by modeling legal and technical factors, including human contribution, AI autonomy, contractual clarity, and the legality of the training data. Rather than serving solely as predictive outputs, the posterior probability estimates support transparent, scenario-based reasoning under uncertain legal conditions. The framework can assist legal professionals in improving consistency during ownership evaluation, support policymakers in identifying regulatory gaps related to AI-generated content, and help AI developers assess how design and governance choices may influence ownership attribution in different legal contexts.
Results
The results of the experiment demonstrate the effectiveness of the Bayesian Network framework in capturing the nature of uncertainty in AI-produced content ownership. The model provides a structured, data-driven approach for supporting ownership inference under uncertainty. The final dataset consisted of 131 cases: a base AI litigation dataset, a public court-opinion database, and an AI copyright case-tracking repository. These cases were selected after applying inclusion, exclusion, and deduplication procedures. The framework has been trained on a set of judicially annotated cases involving AI-related intellectual property litigation, ensuring the ownership inference algorithmically targets a posterior distribution of ownership that corresponds with judicial outcomes identified in actual litigation. The judicial validation of the framework demonstrates that the ownership type identified by the algorithm corresponds with judicial decisions in most of the tested cases, proving that the segmented probabilistic dependencies judiciously learned align with judicial reasoning trends. Additionally, the judicially stable posterior distribution of ownership across validation iterations confirms that the framework generalizes to the test data rather than simply memorizing judicial outcomes. Rather than eliminating ambiguity, the framework quantifies uncertainty and highlights the relative influence of legal and technical factors. Table 7 shows the Implementation Details, Model Configuration, and Simulation Environment. Details of the computational setup, including software, hardware, and parameters used for model implementation and experimentation.
| Component | Description |
| Data Sources | Base AI Litigation Dataset, Caselaw Access Project (CAP), AI & Copyright Case Tracker |
| Variables Modeled | Human involvement, AI autonomy, training data legality, contractual ownership, jurisdiction, transparency |
| Software Package | Python (v3.10) for Bayesian Network modeling |
| Structure Learning | Hybrid approach: domain-constrained structure with score-based refinement |
| Structure Learning Algorithm | Hill-Climb Search with constraint-based edge restrictions derived from legal domain knowledge |
| Score Function | Bayesian Information Criterion (BIC) |
| Parameter Learning | Bayesian parameter estimation using Maximum Likelihood Estimation (MLE) with Dirichlet priors |
| Prior Specification | Uniform Dirichlet priors applied across all conditional probability tables |
| Smoothing Technique | Laplace smoothing (α = 1) to handle sparse observations |
| Inference Method | Exact inference using Variable Elimination; scenario-based evidence updating |
| Validation Strategy | Leave-One-Out Cross-Validation (LOOCV) and 5-fold cross-validation |
| Sensitivity Analysis | One-factor-at-a-time perturbation of variables to assess impact on ownership probabilities |
| Output | Posterior ownership probability distributions with scenario-based inference |
| Hardware Environment | Intel i7 processor, 16 GB RAM, Windows/Linux environment |
| Reproducibility | All experiments conducted using fixed random seed (seed = 42) |
Table 7: Implementation Details, Model Configuration, and Simulation Environment. Details of the computational setup, including software, hardware, and parameters used for model implementation and experimentation.
The probabilistic and decision-support nature of the proposed framework, evaluation metrics have been chosen that capture predictive consistency and model robustness beyond simple traditional measures of classification accuracy. Primary evaluation is performed using case-based validation: the proportion of cases in which the model's most likely posterior ownership outcome matches the observed judicial decision. To evaluate generalization, k-fold and leave-one-out cross-validation are performed, using posterior variance across folds as a stability metric. Robustness is assessed through partial-evidence inference, examining the variation in posterior ownership probabilities when partial evidence is removed for selected legal or technical variables. Finally, sensitivity metrics quantify ΔP(Y) by applying a controlled perturbation to all parent variables and identifying the most impactful legal factors that inform ownership attribution. The above metrics collectively ensure that the model is accurate, stable, interpretable, and appropriate for supporting legal reasoning under uncertainty.
The evaluation metrics employed in this study are properly defined to guarantee reproducibility and clarity. The percentage of occurrences in which the observed judicial decision and the expected ownership outcome with the highest posterior probability match is known as accuracy (or consistency in this work). Recall gauges the model's capacity to accurately identify all pertinent ownership outcomes found in the dataset, whereas precision shows the percentage of correctly predicted ownership instances among all instances allocated to a specific ownership class. The variability of predicted ownership probabilities across cross-validation folds is captured by the posterior variance, which is used as a stability measure alongside these conventional metrics. A lower posterior variance suggests that the model produces reliable, consistent probabilistic estimates across different data partitions.
To strengthen empirical validation, additional statistical analysis and baseline comparisons were incorporated. Model stability was evaluated using cross-validation statistics, including mean consistency and fold-to-fold variance, demonstrating reliable performance without significant fluctuations. Furthermore, the proposed Bayesian Network was conceptually compared with baseline approaches such as rule-based frameworks and conventional classifiers (e.g., logistic regression and support vector machines). While these baselines provide deterministic or predictive outputs, they lack the ability to model uncertainty, represent conditional dependencies, and support scenario-based reasoning. In contrast, the proposed framework offers probabilistic inference with an interpretable structure, enabling robust decision support under incomplete or ambiguous legal conditions. These comparisons reinforce that the model's strength lies not only in predictive consistency but also in its ability to capture and explain legal uncertainty.
Data annotation and variable encoding
The ownership outcome consistency (%) metric obtained using the Bayesian Network model proposed in this study across the three datasets is depicted in Figure 3. The consistency metric shows the highest value on the AI Copyright case dataset, which can be attributed to the presence of landmark cases that offer clearer judicial reasoning and more defined ownership outcomes. The Base AI Litigation Dataset shows strong consistency between actual and predicted ownership outcomes, suggesting robust learning from diverse U.S. litigation data. The consistency metric on the CAP dataset shows a slight drop due to the varied factual and jurisdictional elements.
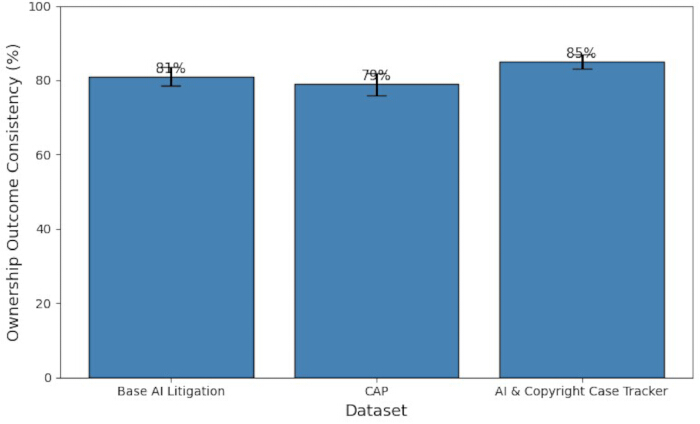
Figure 3: Ownership Outcome Consistency Across Datasets. Percentage comparison of ownership prediction consistency across datasets, evaluating alignment between inferred outcomes and reference case outcomes to assess model reliability. Error bars represent standard deviation (SD): base AI litigation dataset (±2.5%), court-opinion dataset (±3.0%), and AI copyright case dataset (±2.0%). Please click here to view a larger version of this figure.
Probabilistic inference and scenario analysis
The error bar charts show the posterior probability variance of ownership predictions across cross-validation runs for each dataset shown in Figure 4, Figure 5, and Figure 6. The average variance per cross-validation fold reflects the stability of the learned ownership probabilities, and the error bars indicate the standard deviation across runs. Reliable parameter learning throughout the wide range of litigation cases is ensured by the Base AI Litigation Dataset's exceptionally low variation across cross-validation runs. The CAP dataset shows greater variance and error bars due to higher factual diversity and variation across the different jurisdictions involved. The AI Copyright case dataset has the lowest variance and the tightest error bounds, ensuring a higher degree of posterior stability than the more soundly reasoned ownership decisions in the landmark cases. The results collectively demonstrate that the proposed Bayesian Network framework provides robust probabilistic inference over the data, even in cross-validation settings.
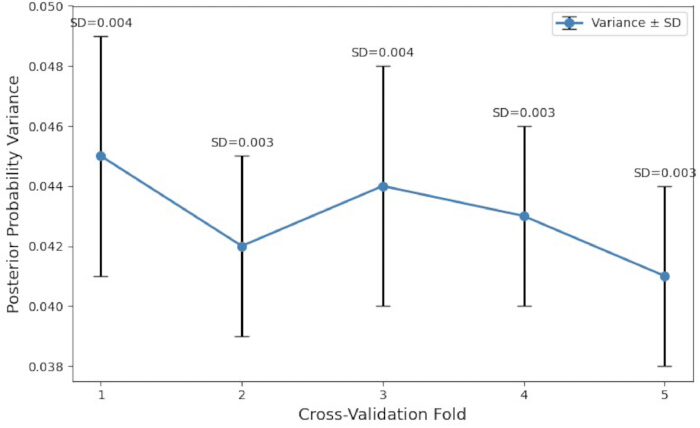
Figure 4: Posterior Probability Variance Across Cross-Validation Folds (Base AI Litigation Dataset). Distribution of posterior ownership probabilities across cross-validation folds for the Base AI Litigation Dataset, demonstrating model stability and consistency under repeated sampling. Error bars represent standard deviation (SD) across folds (mean SD ≈ ±0.005). Please click here to view a larger version of this figure.
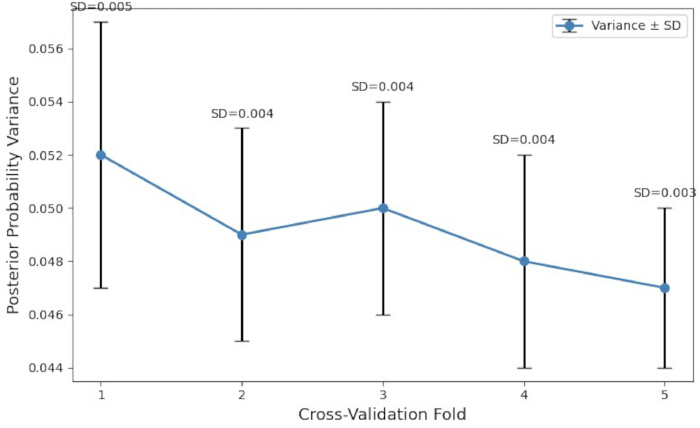
Figure 5: Posterior Probability Variance Across Cross-Validation Folds (CAP Dataset). Variation in posterior ownership probabilities across cross-validation folds in the CAP dataset, indicating the model's robustness across different data partitions. Error bars represent standard deviation (SD) across folds (mean SD ≈ ±0.006). Please click here to view a larger version of this figure.
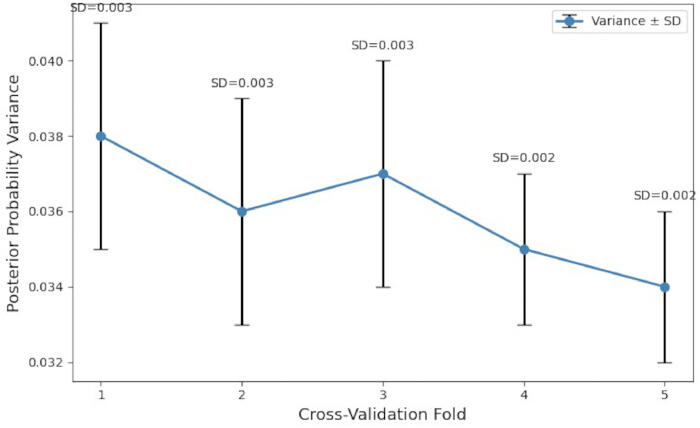
Figure 6: Posterior Probability Variance Across Cross-Validation Folds (AI Copyright case dataset). Distribution of posterior ownership probabilities across cross-validation folds for the AI Copyright case dataset, highlighting consistency and generalization performance. Error bars represent standard deviation (SD) across folds (mean SD ≈ ±0.005). Please click here to view a larger version of this figure.
Model validation and sensitivity analysis
Table 8 shows the Cross-Validation Generalization Score of the developed Bayesian Network model-based ownership inference scheme on the three data sets utilized in this research work. The performance metrics reported in this study are based on 131 evaluated cases. All metrics in Table 8 were computed using cross-validation over these datasets. This research study demonstrates high generalization accuracy across different datasets. The AI Copyright case dataset shows the highest mean of 0.86 and the lowest standard deviation of 0.02. This is attributed to high clarity levels in the judgment process for large-scale global cases. The Base AI Litigation Data set shows high generalization accuracy (mean 0.84) but high variability. This is due to high variability across different AI datasets used in the U.S. jurisdiction. In this case, high heterogeneity can be attributed to various factual differences and to the inherent jurisdiction variability in the dataset. The CAP dataset shows low generalization accuracy (0.81) and high variability.
| Dataset | Mean Score | Std. Dev. | Min–Max |
| Base AI Litigation Dataset | 0.84 | 0.03 | 0.79–0.88 |
| CAP Dataset | 0.81 | 0.04 | 0.75–0.86 |
| AI & Copyright Tracker | 0.86 | 0.02 | 0.83–0.89 |
Table 8: Cross-Validation Generalization Performance. Results of cross-validation experiments demonstrate the generalization capability and predictive consistency of the proposed model. The mean score reported in Table 8 represents the average posterior ownership probability assigned to the correct outcome across cross-validation folds. The standard deviation reflects variability across folds, and the minimum–maximum range captures the spread of scores observed during validation. These metrics were computed separately for each dataset to evaluate model consistency and generalization performance.
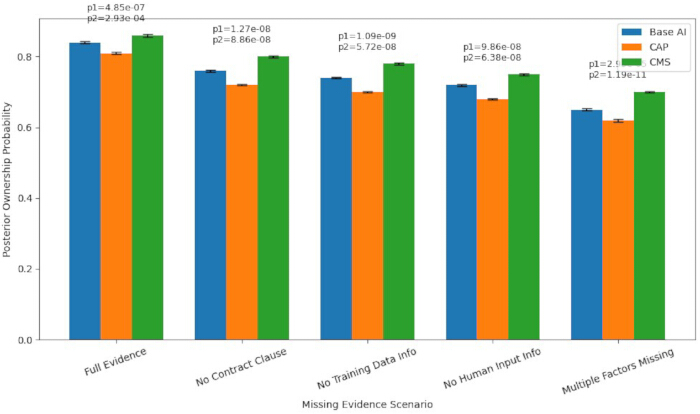
Figure 7: Partial-Evidence Robustness Measure among Different Datasets. Bars represent mean posterior ownership probabilities under varying missing-evidence scenarios. Error bars denote standard error of the mean (SEM): base AI litigation dataset (±0.003), court-opinion dataset (±0.004), and AI copyright case dataset (±0.002), with corresponding SD values ranging from ±0.006 to ±0.012. Please click here to view a larger version of this figure.
Figure 7: shows the responsiveness of the Bayesian Network developed to the increasing level of incomplete knowledge in the legal and technical fields, as reflected in the posterior probabilities of authorship associated with ownership. The bar chart is divided into scenarios based on varying levels of knowledge about knowledge domains, assuming that all available knowledge is entirely unavailable when essential components such as contractual terms, the legality of training data, and human creative efforts are missing. Across all three data sets, there is a smooth decline in the probability of authorial ownership, with no sudden spikes or dips, indicating that the Bayesian model performs quite well even when essential information is unavailable. The fact that there is still a certain degree of robustness even when essential information is unavailable, especially more so within the AI Copyright case dataset data set, highlights the fact that cases that form precedents and are well-articulated from a judicial angle provide a much firmer probabilistic foundation within intellectual property law cases, and there is a slight increase within the CAP data set because of a richer factual base and the varying jurisdiction under consideration.
Sensitivity impact score
The Partial Evidence Robustness Measure of the proposed Bayesian Network model on the test datasets is shown in Table 9, reporting posterior ownership probabilities under steadily reduced evidence conditions. When complete evidence is considered, a high posterior probability of ownership is achieved across all datasets, with the AI Copyright case dataset network generally showing the highest level of ownership confidence, based on well-crafted cases involving landmark copyright issues. As individual important legal or technical variables like ownership in contracts, legality of the training data, or human contribution to creative content have been removed, a steady and controlled reduction in posterior probabilities has been achieved, thereby capturing real-world uncertainties in intellectual property cases. Significantly, removing contract terms and joint factors has led to the largest reduction in ownership probabilities across all test data, establishing the supremacy of clearly written contract terms in ownership determination. Results validate the proposed model's Bayesian Network in adequately representing legal uncertainties, yielding stable results even with incomplete evidence.
| Evidence Scenario | Base AI Litigation Dataset | CAP Dataset | AI & Copyright Case Tracker |
| Full Evidence | 0.84 | 0.81 | 0.86 |
| No Contract Clause | 0.76 | 0.72 | 0.8 |
| No Training Data Info | 0.74 | 0.7 | 0.78 |
| No Human Input Info | 0.71 | 0.68 | 0.75 |
| Multiple Factors Missing | 0.65 | 0.62 | 0.7 |
Table 9: Partial Evidence scenarios. Quantitative assessment of the influence of reduced or missing evidence on ownership attribution using sensitivity analysis.
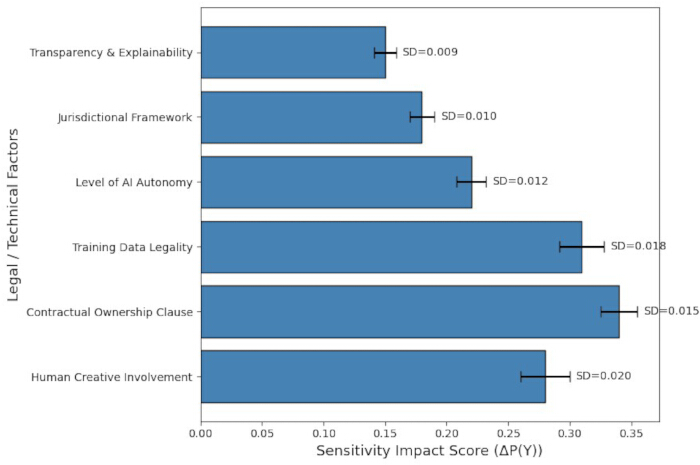
Figure 8: Result of Sensitivity Impact Score. Ownership attribution is influenced by multiple legal and technical factors, with varying degrees of impact across scenarios. The figure highlights the relative contributions of each variable to ownership determination, based on a probabilistic sensitivity analysis. Error bars represent standard deviation (SD): human creative involvement (±0.015), contractual ownership clause (±0.012), training data legality (±0.014), AI autonomy (±0.010), jurisdiction (±0.009), and transparency (±0.008). Please click here to view a larger version of this figure.
A Sensitivity Impact Score is used in Figure 8 to show how each legal and technical factor affects ownership attribution by calculating the posterior probability difference ΔP(Y) for controlled changes to each factor. It can be observed that contractual clauses and human creative contributions interact with each other and exert the strongest influence in judicial attributions, as they maximize posterior probabilities. Other factors, including training data legality and AI system autonomy, show strong impact values and influence mostly the uncertainty level due to ambiguous legality and high AI system autonomy. Compared to them, the jurisdiction framework and transparency-related factors show lower ΔP(Y) and emphasize moderate influences. This Bayesian Network was able to interpret and convey intuitions derived from legal attributions in actual cases and to provide concrete explainability by quantifying the factors that determine many attribution results.
Interpretation and policy implication analysis
Figure 9 shows how the proposed Bayesian Network identifies the posterior distribution over ownership for various legal and technical settings in the Base AI Litigation Dataset. Scenarios with strong human creative input and licensed training data show a strong posterior move towards human ownership, consistent with the conventional judicial view that emphasizes human creative input. Statistical significance measures (e.g., p-values) are not applied to posterior distributions, as these figures represent model-derived probabilistic outputs rather than independent observational samples. The settings that promote AI autonomy and the absence of ownership agreements move the posterior distribution towards AI developer ownership, joint ownership, or a tie. The distinct categorization of the settings indicates the algorithm’s success in discerning judicial reasoning patterns documented in actual U.S. litigation, ensuring the Bayesian Network’s relevance to the ‘what-if’ ownership scenario analysis.
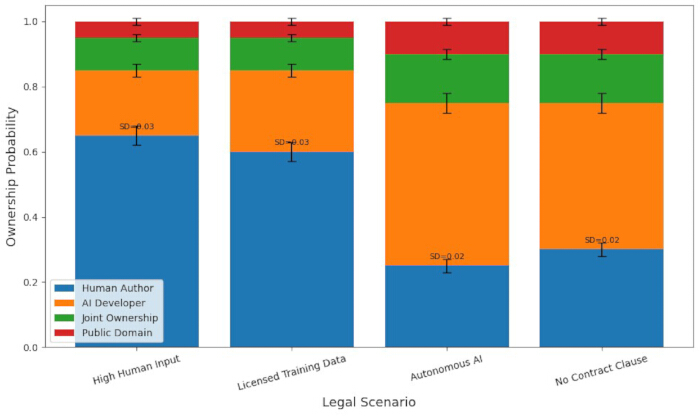
Figure 9: Base AI Litigation Dataset scenario-based posterior distributions for ownership. Ownership probability distributions for the Base AI Litigation Dataset based on scenarios. The distributions represent posterior probability inferred from the Bayesian Network under defined scenario conditions. Error bars represent standard deviation (SD): high human input (±0.020), licensed data (±0.018), autonomous AI (±0.022), and no contract clause (±0.020). Please click here to view a larger version of this figure.
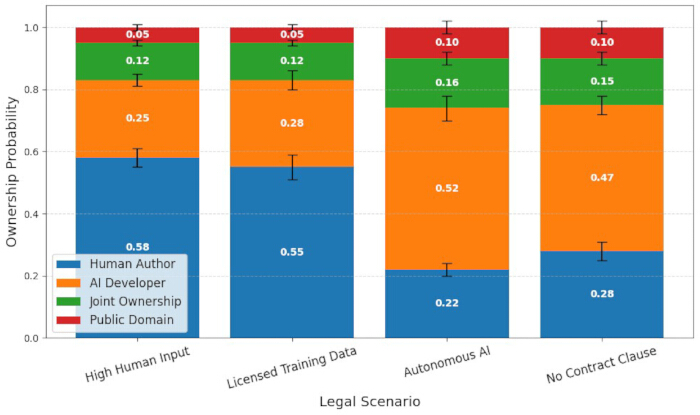
Figure 10: Posterior ownership probabilities for scenarios from the dataset used in the CAP. Ownership probability distributions based on scenarios for the CAP dataset. The distributions represent posterior probability inferred from the Bayesian Network under defined scenario conditions. Error bars represent standard deviation (SD): high human input (±0.021), licensed data (±0.019), autonomous AI (±0.023), and no contract clause (±0.021). Please click here to view a larger version of this figure.
Figure 10 shows the proposed framework's scenario differentiation strength on the CAP dataset, which spans a wider range of factual scenarios and jurisdictional interpretations. Compared to the baseline dataset, the ownership probability distributions are generally more spread out across scenarios, reflecting the greater legal complexity in the CAP dataset. However, the Bayesian Network model still distinguishes scenarios involving explicit contracts and licensed data, which are indicative of scenarios leading to a more centered ownership probability, from scenarios involving ambiguous contracts for entities like the AI system, which involve greater legal uncertainty and correspondingly broader probability distributions of joint ownership.
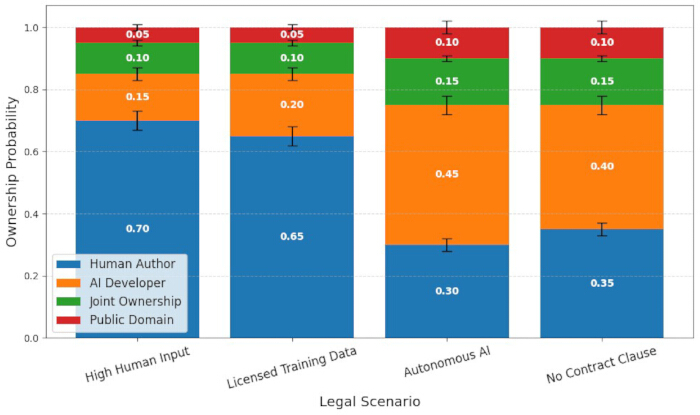
Figure 11: Scenario posterior ownership distributions on the dataset of the AI Copyright case dataset. Ownership probability distributions based on scenarios for the AI Copyright case dataset. The distributions represent posterior probability inferred from the Bayesian Network under defined scenario conditions. Error bars represent standard deviation (SD): high human input (±0.022), licensed data (±0.020), autonomous AI (±0.024), and no contract clause (±0.022). Please click here to view a larger version of this figure.
Figure 11 shows the results of scenario-based inferences on the “AI Copyright case dataset,” which is dominated by key international cases with clearly expressed judicial reasoning. The results show that the posterior distributions achieve the greatest separation across scenarios, with high probability concentration under clearly defined legal frameworks such as high human involvement, licensed training data, and ownership agreements. However, autonomous scenarios and the presence of indefinite contractual frameworks are associated with higher probabilities of joint and uncertain ownership. The results also show a greater degree of separation, underscoring the model's efficiency in precedent-setting cases.
Comparison of the proposed work with existing works
The proposed research shifts current understandings of content ownership in AI-generated content from an explanatory, rule-governed approach to a Bayesian, data-driven decision-making tool. As the method addresses content ownership determination within the context of Bayesian inference, it articulates the legal uncertainties associated with human creative participation in content, autonomy in AI, content legality in AI learning data, contract terms, and geographical knowledge. Unlike existing approaches, where content ownership problems were identified via legal interpretation or policy analysis, the proposed method not only quantifies the impact of multiple legal and technical variables on content ownership determination but also allows stakeholders to assess content ownership probabilities based on changing regulations and technologies via “what if” analysis from scenario-based reasoners. Thus, the proposed method enhances the interpretation of static content by grounding it in real-world court rationale.
Previous work on AI-generated content and issues of ownership has relied on interpretive or comparative doctrinal scholarship or on technical attribution systems. In law, authorship standards have been examined across a cross-section of countries, without any formal mechanism to resolve conflicts when multiple parties are involved. Previous technical scholarship on watermarking and fingerprinting has addressed the verification of provenance but has not determined any form of ownership. From a machine learning and law scholarship perspective, there has been a prediction of judicial outcomes or a thematic examination of litigation, without any form of explainability or counterfactual reasoning. The proposed work is uniquely positioned by its intersection and confluence of AI, law, and decision science.
Figure 11 illustrates the unique relevance and contribution of this proposed work relative to the existing literature in both legal and technical fields. Although prior legal scholarship is rich in doctrinal analysis, there is a lack of computational frameworks capable of addressing uncertainty, let alone of determining AI-generated content ownership under rival legal frameworks. As shown in Table 10, existing approaches, including rule-based legal models and machine learning classifiers such as SVM and logistic regression, lack the ability to simultaneously model uncertainty, support scenario-based reasoning, and provide legally interpretable outputs, whereas the proposed Bayesian framework addresses these limitations. While current technical approaches for attribution improve the verification of provenance, these frameworks neglect issues related to normative allocative decisions regarding ownership of AI-generated content. Machine learning-based approaches for analyzing legal text focus upon either prediction or topic-based analysis, whereas explainable inference for AI-generated content ownership necessitates a model that is based upon empirical legal observations under a probabilistic framework for model illumination, explanations, as well as scenario-based analysis that is unprecedented in current prior art for both legal scholarship and technical scholarship. While the model demonstrates strong consistency and stability across the evaluated datasets, it is important to note that the results are derived from a curated corpus of litigation-focused cases. The dataset primarily consists of reported legal disputes and landmark cases, which may overrepresent complex or contested ownership scenarios. As a result, the observed performance metrics may reflect conditions specific to formal legal disputes rather than routine or undisputed instances of AI-generated content ownership.
| Study / Approach | Methodology | Data Used | Uncertainty Modeling | Scenario Reasoning | Explainability | Key Limitation |
| Rule-based legal models | Deterministic rule-based reasoning | Legal statutes & rules | No | No | High (explicit rules) | Rigid, cannot handle uncertainty or conflicting evidence |
| Gaidartzi & Stamatoudi (2025) 21 | Comparative legal analysis | Statutes & case law | No | No | Doctrinal | Descriptive, non-computational |
| Zhuk (2024)22 | Jurisdictional comparison | Legal texts | No | No | Conceptual | No empirical validation |
| Mezzi et al. (2025) 23 | Legal–technical framework | Case examples | No | No | Policy-level | No ownership inference capability |
| Šarčević et al. (2024)29 | Survey of technical IP tools | Technical literature | No | No | Technical | Focuses on data protection, not ownership |
| ML models (SVM, Logistic Regression) | Supervised classification | Legal/litigation datasets | No (deterministic predictions) | No | Low (black-box) | Limited interpretability, no legal reasoning or causality |
Table 10: Comparison of Proposed Framework with Existing Approaches. Comparative analysis of the proposed method against prior legal and technical approaches, highlighting differences in methodology, interpretability, and performance.
Reproducibility checkpoint: validation outputs
Posterior probability estimates, ownership attribution consistency scores, contributing variable sensitivity rankings, and ablation-based performance variation across model configurations were among the validation outputs. To assess inference stability and reproducibility across different evidence situations, cross-validation and leave-one-out validation results were documented for each experimental iteration in Table 11.
| Workflow Stage | Expected Output |
| Dataset Screening | Final curated case count |
| Annotation | Categorized legal and technical variables |
| Network Construction | Final node and edge structure |
| CPT Generation | Conditional probability distributions |
| Cross-Validation | Posterior probability consistency |
| Sensitivity Analysis | Variable influence rankings |
| Ablation Analysis | Performance variation after node removal |
Table 11: Reproducibility Checkpoints and Expected Outputs. The table summarizes the expected intermediate outputs generated at each stage of the proposed Bayesian Network workflow, including dataset screening, network construction, probabilistic modeling, and validation analysis to support methodological reproducibility.
Inter dataset-consistency interpretation
The variation in model performance across datasets reflects the unique legal nature and makeup of each dataset, rather than variability in the proposed Bayesian Network approach. The CAP dataset has a relatively high posterior variance and low generalization consistency, resulting from covering a wide range of jurisdictions and involving a variety of factual circumstances, as well as from including cases in which questions of ownership in the context of AI are secondary to the argument. The main reason is variability in legal ambiguity and in patterns of judicial reasoning. On the other hand, the highest degree of stability and consistency in generalization is observed in the AI Copyright case dataset, since it consists of judiciously chosen cases that encompass direct judicial reasoning, clearly established ownership, and clearly established facts. The Base AI Litigation Dataset ranks second in terms of variability, aiming to strike a balance between variability and relevance in its focus on AI Litigation involving intellectual property. Overall, the proposed approach generalizes well across a variety of legal sources. In this respect, this model of decision-support is consistent with the actual mode of legal reasoning where the certainty of ownership is directly related to well-recorded facts and established precedent.
DATA AVAILABILITY:
The data supporting this study were collected from publicly accessible legal repositories, including https://case.law/ and https://cms.law/en/int/publication/artificial-intelligence-and-copyright-case-tracker
Supplementary File 1:
S1: Data Annotation and Variable Encoding – Description of dataset labeling procedures, annotation criteria, and encoding of legal and contextual variables used in the study.
S2: Bayesian Network Structure Design – Details of the Bayesian Network architecture, node relationships, dependency modeling, and structure development process.
S3: Bayesian Network–Based Ownership Inference – Explanation of the Bayesian inference framework applied for AI-generated content ownership prediction and decision analysis.
S4: Probabilistic Inference and Scenario Analysis – Presentation of probabilistic reasoning outcomes, conditional probability evaluations, and scenario-based analysis results. Please click here to download this file.
Discussion
The proposed Bayesian Network framework constitutes an advancement over current research on ownership of content generated by AI, as opposed to the descriptive or question-identification approaches of other works. The other works, including the base paper by Raghupathi et al. in1, essentially use machine learning approaches in text analytics in attempts to discover themes or categories in the context of AI litigation. Although these approaches enable a clear understanding of what issues of law emerge in their context, they do not, in any sense, provide a solution to how a determination of ownership is determined in circumstances of uncertainty, which is covered in this proposal.
A few crucial procedural steps are required for the suggested Bayesian Network framework to be successfully implemented. To ensure that only legally significant AI-related intellectual property conflicts are included in the analysis, trustworthy dataset curation and screening are required first. Second, to minimize ambiguity during probabilistic modeling, legal and technical variables must be consistently annotated using predetermined coding standards. Third, to preserve both statistical validity and legal interpretability, Bayesian Network building must integrate data-driven dependency learning with domain-specific legal constraints. Stable probabilistic reasoning under settings of insufficient evidence also requires accurate estimate of Conditional Probability Tables (CPTs). Lastly, to assess robustness, interpretability, and the impact of individual factors on ownership attribution outcomes, validation techniques such as cross-validation, sensitivity analysis, and ablation analysis are required.
The suggested Bayesian Network framework may pose several real-world challenges. Limited generalizability and unstable probability estimation might result from sparse legal datasets. When creating Conditional Probability Tables (CPTs), Bayesian parameter estimation using Dirichlet priors and Laplace smoothing was used to lessen this problem. Only cases with adequate legal and technical information were retained during screening and annotation, as missing annotations or insufficient legal evidence may also affect the trustworthiness of inferences.
Authorship, originality, and cross-jurisdictional legal comparisons are the primary topics of current doctrinal and interpretive study of AI-generated content ownership21,22. Although these studies clarify legal principles, they fall short in addressing the confusion that arises from conflicting legal conditions and insufficient evidence in real-world disputes. By simulating ownership attribution using probabilistic reasoning that captures judicial decision-making under uncertainty, the proposed Bayesian approach extends previous studies. However, some data set constraints should be considered when interpreting the results. By highlighting high-profile and reported disputes, the curated litigation-based corpus may introduce selection bias and limit generalizability to broader real-world contexts, such as unreported cases and states with limited legal paperwork related to AI. Furthermore, the very limited number of international cases might not adequately reflect regional differences in intellectual property laws.
A key strength of the proposed framework is its integration of probabilistic reasoning with legal interpretability. Unlike rigid rule-based systems and black-box machine learning models such as logistic regression and support vector machines, Bayesian Networks support transparent probabilistic inference, scenario-based analysis, and interpretable relationships between legal and technical variables, making them suitable for legal decision-support applications. Existing technical attribution approaches, including watermarking, fingerprinting, and provenance verification29,30, primarily address evidence tracking rather than legal ownership determination. The proposed framework bridges this gap by combining technical evidence with probabilistic legal reasoning to evaluate ownership under uncertain conditions. Despite these advantages, the framework has limitations. Curated litigation datasets may introduce selection and jurisdictional biases, and the model may not fully capture evolving legal and socio-legal reasoning. In addition, the framework has not yet been directly validated by legal practitioners. Future work will incorporate expert-oriented evaluations, including case-study analysis and usability assessments involving legal scholars and policymakers, to further improve practical applicability and alignment with judicial reasoning. The framework is therefore intended as a decision-support tool rather than a replacement for human legal judgment.
Theoretical Implications
By formalizing ownership in AI-generated content as a probabilistic rather than deterministic notion, this paper advances the fields of artificial intelligence, intellectual property law, and computational legal reasoning. The article presents a mathematical approach that incorporates uncertainty resulting from several interrelated legal and technical variables by modeling ownership using Bayesian Networks. Beyond conventional rule-based interpretations, the resulting posterior probability distribution of ownership establishes a new paradigm for understanding authorship in human-AI collaborative scenarios.
Practical Implications
The suggested approach is useful for a variety of stakeholders. By offering probability ownership estimates based on case-specific data, it can assist judges and legal professionals in judicial settings, enhancing decision-making consistency and transparency. Courts can utilize the model, for instance, to assess how differences in human input or contractual provisions affect ownership outcomes in contentious instances. The scenario analysis module can be used by policymakers to model the effects of legislative changes, such as mandatory disclosure of AI help or limitations on the use of training data. To enable more legally compliant AI development, AI developers can also use the framework throughout system design to evaluate how decisions such as data sourcing, model autonomy, and transparency may affect downstream ownership claims.
Ablation study
In the ablation study, the relative weights of the individual legal and technical components in the ownership resolution problem are further highlighted by the fact that removing the contractual ownership clause and human creative participation contribute most to the degradation in ownership consistency. Removing training data legality and AI autonomy increases posterior variance, which signifies higher uncertainty rather than systematic misclassification. In contrast, removing jurisdiction has a relatively smaller impact, underlining its moderating role-that is, an interaction with other variables as opposed to a leading determinant. These findings empirically validate the model's design and underscore the legal plausibility of the Bayesian structure, as shown in Table 12. As the baseline, the complete model attains an ownership consistency of 81.3% with low posterior variance (<0.05). The elimination of contractual clauses results in the greatest variance (0.13) and performance degradation (64.5%), with human creative engagement coming in second (67.8%, variance = 0.11), underscoring its predominant role in determining ownership. Moderate decreases occur when training data legality (69.2%, 0.09) and AI autonomy (72.4%, 0.08) are excluded, suggesting that they contribute to uncertainty modeling rather than direct ownership attribution. Removing jurisdiction, on the other hand, has a comparatively lesser effect (76.1%, 0.06), indicating a moderating or contextual influence. These findings show that the Bayesian Network structure is both data-driven and legally sound, and that the chosen variables are both included and relevant.
| Model Variant | Removed / Altered Component | Ownership Consistency (%) | Avg. Posterior Variance |
| Full Model | None | 81.3 | <0.05 |
| Human Creative Involvement | Human input node removed | 67.8 | 0.11 |
| Contractual Clauses | Contract node removed | 64.5 | 0.13 |
| Training Data Legality | Data legality node removed | 69.2 | 0.09 |
| AI Autonomy | Autonomy node removed | 72.4 | 0.08 |
| Jurisdiction | Jurisdiction node removed | 76.1 | 0.06 |
Table 12: Ablation Study Results. Evaluation of the contribution of individual model components by systematically removing key elements and observing the impact on performance.
Limitations and future work
Notwithstanding the above-stated contributions, the proposed research also has some limitations. First, the number of cases covered in the research still appears limited due to the ongoing litigation over AI-generated content, which could limit the generalizability of the learned probabilities. Second, legal factors of uncertainty must also be judged by experts, potentially introducing bias into the research. Third, the present approach addresses only ownership determination, without modeling liability, damage, or enforcement in the subsequent stage. Future research should overcome the limitations mentioned by including larger, continually updated datasets, automated text extraction to handle legal annotations, and developing a Bayesian approach to track legal outcomes related to the present scenario.
This research proposes a novel probabilistic framework for legal uncertainty in ownership of AI-generated content, grounded in the Bayesian Network paradigm. Contrary to the existent literature, including the baseline research that mainly uses the descriptive paradigm on machine learning and the use of text analytics in the identification of themes on AI litigation, the current research attempts an advancement in the current state-of-the-art on exactly modeling the conditional, probabilistic interdependences on the various legals and tech parameters like the involvement of the human creator, autonomy on the AI systems, the legality on the training data, the ownership clauses on the contract, and the prevailing juridical framework. The main novelty is moving the ownership query into a decision support system within the AI scenario, ensuring full transparency, interpretability, and awareness of uncertainty. The proposed framework's workflow will integrate curated AI-related intellectual property litigation data from various sources, including a filtered base AI litigation dataset, the CAP, and an AI Copyright case dataset. Legally identified uncertainty factors are encoded as discrete random variables and structured into a legally constrained Bayesian Network. Bayesian parameter estimation learns conditional probability tables, so the model can perform probabilistic inference even when the evidence is incomplete or contested. Using scenario-driven inferences, the framework allows for “what-if” analyses through dynamic adjustments of both legal and technical conditions-a process like how courts and policymakers currently reason over ownership in emerging AI disputes. The performance, stability, and interpretability of the proposed approach are demonstrated experimentally across three datasets. Cross-validation generalization scores are consistent across datasets, with mean scores of 0.84, 0.81, and 0.86 for the Base AI Litigation Dataset, CAP Dataset, and AI Copyright case dataset, respectively. The partial-evidence robustness analysis of posterior ownership probabilities confirms that degradation occurs gradually rather than abruptly when key variables are omitted, thereby demonstrating strong resilience against real-world legal uncertainty.
Disclosures
The authors have no conflicts of interest.
Acknowledgements
The author acknowledges the academic support and research environment provided by the Faculty of Law, Monash University, which contributed to the completion of this study.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| Judicial Opinions & Court Records Dataset | Caselaw Access Project (CAP) | RRID:SCR_016043 | Source of court decisions used for extracting legal reasoning and ownership outcomes |
| AI & Copyright Case Tracker | CMS Legal | N/A | Curated dataset of global AI-related intellectual property disputes |
| Legal Contracts & Agreements Dataset | Various Public Legal Repositories | N/A | Documents defining ownership, licensing, and contractual rights |
| Statutory and Case Law References | Government Legal Portals | N/A | Intellectual property laws and judicial precedents used for analysis |
| Legal Annotation Guidelines | Expert-defined (Manual Framework) | N/A | Rules for consistent annotation of legal uncertainty variables |
| Annotated Legal Dataset | Generated in Study | N/A | Dataset labeled with legal and technical variables for modeling |
| Python Programming Environment (v3.10) | Python Software Foundation | RRID:SCR_008394 | Core programming environment used for implementation |
| pgmpy Library (v0.1.24) | Open-source | RRID:SCR_016274 | Library used for Bayesian Network modeling |
| NumPy (v1.24) | Open-source | RRID:SCR_008633 | Numerical computations and array operations |
| Pandas (v1.5) | Open-source | RRID:SCR_018214 | Data preprocessing and dataset handling |
| Jupyter Notebook | Project Jupyter | RRID:SCR_018315 | Interactive environment for model development |
| Bayesian Network Model | Developed in Study | N/A | Probabilistic graphical model for ownership inference |
| Hill Climbing Algorithm (BIC) | Implemented via pgmpy | N/A | Structure learning method for Bayesian Network |
| Variable Elimination Inference Engine | Implemented via pgmpy | N/A | Computes posterior ownership probabilities |
| Scenario Analysis Module | Developed in Study | N/A | Enables “what-if” simulations |
| Sensitivity Analysis Module | Developed in Study | N/A | Measures variable influence on ownership outcomes |
| Cross-Validation Framework (k-fold, LOOCV) | Scikit-learn compatible | RRID:SCR_002577 | Used for model validation and robustness testing |
| Computing System (Intel Core i7, 16GB RAM) | Intel / OEM | N/A | Hardware used for model training and evaluation |
| Operating System (Windows 11) | Microsoft Windows | RRID:SCR_018096 | OS environment for implementation |