This study proposes an algorithm that tightly couples the hierarchical visual features captured by a shifted-window hierarchical transformer encoder with the prior depth of the Manhattan 3D bounding box generated by line-segment detection, thereby achieving high-precision semantic reconstruction of complex indoor scenes.
A subscription to JoVE is required to view this content. Sign in or start your free trial.
Research Article
A Semantic Parsing Method for Indoor Scene Images Based on Prior Knowledge of Building Structure
In This Article
Summary
Abstract
To address semantic prediction discontinuities and physical boundary distortions caused by furniture occlusion in complex indoor scenes, this paper proposes a semantic parsing method that leverages building-structure priors. The scheme uses a shifted-window hierarchical transformer encoder to extract multi-scale visual features and combines a gradient-direction-consistency line segment detection algorithm to construct a Manhattan 3D bounding box. This bounding box is transformed into a signed distance field (SDF) prior to encoding discrete geometric contours into a continuous physical potential field. A structure-guided cross-attention mechanism forces the visual signals to align with real 3D orthogonal geometric boundaries, restoring feature continuity in occluded areas. A spatial adjacency graph constructed from superpixel nodes drives a Graph Convolutional Network (GCN) to aggregate features, ensuring macroscopic semantic consistency within the physical load-bearing plane. A combination of pixel-level cross-entropy loss and a custom-designed structural consistency loss strengthens the constraints, penalizing out-of-bounds predictions. Experiments across multiple independent runs show that the mean intersection over union (mIoU) reaches 68.7% with a standard deviation of 0.2%, and the structural boundary F1 score reaches 76.4% with a standard deviation of 0.3%, confirming the robust performance of the proposed modules. With a single image node size of 256, the average inference time remained at 61 ms.
Introduction
Indoor scene image semantic analysis occupies a core position in three-dimensional spatial cognition and intelligent spatial reasoning tasks1,2. Visual feature extraction in real physical environments is often severely hindered by complex spatial layouts3. Solving the semantic discontinuity and physical boundary distortion of the building foundation structure building foundation structure caused by large-scale furniture occlusion is important for spatial cognition research4,5. Accurately removing interference from cluttered objects and restoring the physical continuity of the same wall and floor will directly determine the accuracy of three-dimensional scene reconstruction and global spatial logic analysis6. The semantic discontinuity caused by large-scale furniture occlusion and the structural repair effect of the proposed building-prior guidance are illustrated in Figure 1, where the occluded red green blue (RGB) input in Table 1A, baseline mask distortion in Figure 1B, and structure-prior repair result in Figure 1C are compared under the same indoor scene condition.
To meet the accuracy requirements of spatial logical reasoning, current mainstream pixel-driven visual networks face multiple obstacles when dealing with complex indoor environments7,8. Indoor spaces are often filled with dense furniture and cluttered furnishings, resulting in a significant loss of low-level visual boundary signals in the images9. Conventional feature extraction mechanisms rely excessively on local two-dimensional color and texture responses, lacking a macroscopic understanding of the rigid orthogonal laws of three-dimensional man-made structures10. This limitation of the local receptive field makes feature propagation easily interrupted, making it difficult to extend the global topology across occlusions11. Currently, there is an urgent need to solve the core problem of semantic prediction discontinuities and severe distortions of physical boundaries caused by occlusion and interference12.
To address structural faults in building foundations caused by occlusion and interference, the academic community has developed a variety of targeted intervention measures13. Cross-modal feature aggregation networks effectively compensate for the inherent deficiencies of a single visual modality in spatial perception by introducing depth maps or text priors to assist with red-green-blue (RGB) images14,15. Boundary perception and adaptive context selection frameworks inject physical contour enhancement strategies into the feature decoding stage, which greatly improves the edge fit of prediction results in complex scenes16,17. Inference models based on GCNs and feature interaction mechanisms significantly improve feature smoothness and macro-semantic consistency in homogeneous regions by constructing node-level connections18,19. Integrating explicit Manhattan structural priors into the visual feature extraction pipeline enforces geometric consistency boundaries, which addresses the feature discontinuity challenges caused by extensive foreground object occlusion20.
To address the core challenge of semantic prediction faults and severe distortions of physical boundaries associated with building infrastructure, a semantic parsing framework is proposed based on a closed-loop coupling mechanism incorporating architectural priors. This framework transcends naive engineering pipelines by establishing a bidirectional mapping alignment between continuous geometric potential fields and discrete visual feature manifolds, forming a non-trivial synergy that rectifies occlusion errors through structural laws. This scheme relies on a multi-scale visual backbone network and a line-segment detection algorithm based on vanishing-point estimation to acquire local appearance features and orthogonal edge priors that represent the Manhattan 3D bounding box in parallel, and then transform them into an SDF. The algorithm employs a structure-guided cross-attention mechanism, using visual features as query vectors and treating SDF features as keys and values for dot-product calculations, thereby forcing the visual signal to align with the real 3D geometric boundary in the feature space. A spatial adjacency graph constructed from superpixel nodes and spatial coplanarity edge features is fed into a GCN to perform cross-node feature aggregation and message passing. The end-to-end parameter optimization process jointly employs pixel-level cross-entropy and a custom structural consistency loss function, which strictly constrains and penalizes predicted pixels that cross the building-prior boundary. The complete semantic parsing pipeline is summarized in Figure 2, which links RGB image input, geometric prior extraction, cross-attention alignment, superpixel graph reasoning, and semantic mask decoding within a unified architecture.
Early scene parsing networks relied on convolutional operations to capture local appearance textures, but due to limitations in local receptive fields, they exhibited insufficient semantic coherence of large-scale targets21,22. Previous studies have applied the self-attention module of the visual Transformer architecture to extract global contextual information and construct long-distance pixel association features23,24. Cross-modal multi-view feature aggregation strategies extract the three-dimensional geometric spatial features of the scene by fusing depth-map point clouds and text command inputs25,26. Hybrid attention mechanisms for feature fusion targeting specific domains have gradually matured. By constructing feature interaction bridges, they have significantly reduced energy loss and feature sparsity in multi-scale transmission of visual signals and improved the robustness of complex-structure parsing. Cutting-edge encoder designs jointly integrate and infer high-frequency domain spatial details alongside global and local features, strengthening the network's ability to distinguish fine-grained semantic categories with high similarity and improving indoor parsing accuracy27,28. Recent advancements in semantic segmentation architectures provide valuable references for optimizing computational efficiency and spatial perception. Models designed for dense prediction and multi-scale contextual aggregation extract fine-grained geometric features from complex backgrounds. Feature decoupling and synergistic fusion strategies address the semantic ambiguity in boundary regions. Lightweight attention mechanisms and gated aggregation modules optimize the parameter distribution, thereby accelerating inference while preserving local structural details. Implementing these efficient architectural designs offers theoretical guidance for reducing the computational overhead of non-Euclidean topological inference operations in indoor scene parsing.
Building structure priors and 3D layout estimation are used to correct local visual parsing errors29. Previous studies have extracted orthogonal and parallel geometric features of indoor buildings as inference constraints to reduce network prediction bias caused by cluttered indoor backgrounds30,31. Existing schemes use line segment detection algorithms and image ablation point analysis techniques to generate Manhattan 3D bounding boxes to map the physical boundaries of rooms and assist in the localization of underlying visual features32. The joint architecture of the boundary awareness module and the multi-scale context implicitly embeds prior structural information into the high-dimensional feature decoding process, forcing the network to output semantic masks that closely match the real physical contours, effectively improving the jaggedness and blurring of object edges33. Semi-supervised or weakly supervised loss function designs with boundary enhancement properties have been widely explored. Relying on rigorous mathematical formulas to punish independent pixel classification behavior that violates spatial topological rules, the geometric smoothness and structural integrity of the final segmentation result are guaranteed from the source of gradient optimization34.
Some studies have used graph neural networks to perform cross-domain aggregation of visual features and reasoning about topological relationships in high-dimensional space35. The superpixel segmentation algorithm pre-aggregates adjacent pixel blocks with similar color response and texture features into independent connected nodes. The superpixel segmentation algorithm compresses the computational redundancy of the graph structure at the image level and preserves the basic geometric topology of the image36. The GCN built on the high-dimensional node feature vector, and the adjacency matrix representing spatial proximity drives the efficient directional transmission and interactive fusion of multi-scale visual information along the physical connected graph in the spatial domain37,38. The application of the temporal information enhancement module and the hybrid multi-scale skip connection mechanism suppresses the excessive smoothing and homogenization of node features generated in the process of multi-layer deep message passing39. The multi-scale graph wavelet transform technology, and the pseudo-label element learning optimization strategy optimize the anti-background noise mechanism of the node feature update formula, so that features with the same semantic attributes maintain a cooperative response mode in complex network topology40. The graph-based reasoning mechanism maps regular pixel grids to non-Euclidean topological spaces to perform feature aggregation calculations of irregular building structures and interior components41.
Access restricted. Please log in or start a trial to view this content.
Protocol
Indoor RGB scene datasets and their semantic annotations were prepared prior to network training. The large-scale indoor 3D dataset and RGB-D indoor scene dataset (see the Table of Materials) were obtained from their official repositories. Indoor acquisition scenes containing furniture occlusion, illumination variation, wall boundary interruption, and complex spatial layouts were retained to match the target parsing scenario. Semantic labels were converted into indexed single-channel PNG annotation masks, and all RGB images and semantic masks were resized to 512 × 512 pixels. Online data augmentation was applied during training, with random horizontal flipping at a probability of 0.5, random brightness scaling between 0.8 and 1.2, and random rotation between −10° and +10° to broaden the structural layout distribution. RGB channels were normalized with mean values of 0.485, 0.456, and 0.406 and standard deviation values of 0.229, 0.224, and 0.225. The large-scale indoor 3D benchmark followed the official release split used in this study, with 1201 training scenes and 312 validation scenes for model development and validation. The RGB-D indoor scene benchmark followed the official evaluation protocol, with 795 training images and 654 testing images. No additional percentage-based split was applied to these two public benchmarks.
A shifted-window hierarchical transformer visual backbone network (see the Table of Materials) was initialized as the moving-window transformer encoder backbone. The patch embedding size was configured as 4 x 4 pixels. The embedding dimensions of the four hierarchical stages were set to 128, 256, 512, and 1024, and the number of transformer blocks in the four stages was set to 2, 2, 18, and 2. The local attention window size was set to 7 x 7, and the number of attention heads was set to 4, 8, 16, and 32 for the four hierarchical stages. Nonlinear continuous activation functions were used inside all multilayer perceptron layers. Spatial downsampling was performed through patch-merging operations with a stride of 2 after each hierarchical stage. The core network architecture and convolutional inference module hyperparameters were summarized in Table 1.
Shifted-window self-attention feature extraction was then performed on the input feature maps. Each feature map was divided into non-overlapping local windows with spatial dimensions of 7 × 7. Regular window attention and shifted-window attention were alternated between adjacent shifted-window transformer blocks. The cyclic shift distance was set to 3 pixels, and relative positional bias encoding was applied within each local attention window. Local visual features were aggregated via multi-head self-attention to generate hierarchical, multi-scale feature representations.
Manhattan structural priors were extracted from indoor RGB images. Structural edge segments were detected using a gradient-direction-consistency line segment detection algorithm. Dominant structural directions were clustered through a random sample consensus (RANSAC) algorithm (see the Table of Materials) based on vanishing-point estimation. Three mutually orthogonal Manhattan directions were reconstructed to generate the Manhattan 3D bounding box representation. The reconstructed structural boundary was converted into an SDF map by computing the minimum Euclidean distance from each pixel to the nearest boundary line segment.
Structure-guided cross-attention features were generated after the visual features and SDF priors had been obtained. The visual feature manifold was mapped to the query tensor Q through the linear transformation matrix W sub Q element of double-struck cap R to the formation matrix W sub Q element of double-struck cap R to the formation matrix 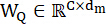 . The continuous distance field prior was mapped to the key tensor K and the value tensor V through the transformation matrices
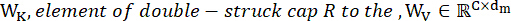 , and the model dimension was set to 512. Multi-head modulation divided the projection space into 8 independent subspaces, with each head having a dimension of 64. The spatial layout prior projected discrete pixel coordinates into a continuous potential field and generated the structural affinity matrix S as an explicit additive spatial bias for modulating the dot-product similarity matrix. The visual feature tensor was used as the query source because semantic parsing requires each visual location to actively retrieve structurally consistent evidence from the geometric prior space. The SDF prior was used as the key and value source because it stores continuous boundary distance and inside-outside structural cues derived from the Manhattan layout. The dot-product term measured the compatibility between the semantic appearance and the geometric prior, while the additive structural term λS shifted attention weights toward pixels on the same physical plane or near the same architectural contour. The coefficient λ represented the confidence in the extracted structural prior and controlled the extent to which rigid orthogonal constraints were incorporated into the attention distribution. This formulation reduced cross-boundary feature diffusion caused by furniture occlusion and retained adaptive relaxation in non-Manhattan layouts. The structure-guided attention distribution was calculated according to Equation 1.
Equation 1: 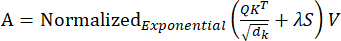
where A denotes the structure-guided attention aggregation matrix, Q denotes the query tensor generated from visual features, K denotes the key tensor generated from SDF prior features, V denotes the value tensor generated from structural prior representations, dk denotes the feature dimension of the key tensor, λ denotes the adaptive structural weighting coefficient used to identify the geometric confidence of local regions and relax rigid orthogonal constraints in non-Manhattan spatial layouts, and S denotes the SDF affinity matrix. The division by dk stabilized the scale of attention logits and prevented large feature dimensions from producing over-concentrated attention weights. The normalized exponential function (see the Table of Materials) transformed the modulated similarity scores into a normalized spatial distribution, allowing each pixel to aggregate structural prior information based on semantic and geometric consistency. This design explains why visual appearance and architectural boundary priors are fused at the attention level rather than by direct feature concatenation.
The superpixel topology graph was constructed from the structure-aligned feature map. The feature map was segmented using a spatial region generation algorithm. The superpixel number was set to 256, the compactness coefficient was set to 10, the Gaussian smoothing coefficient was set to 1.0, and the iteration number was set to 10. Spatial proximity constraints were enforced by setting the distance metric weight to a constant ratio of 1.0 to the feature color-space distance during clustering, thereby maintaining uniform node generation across dense clutter boundaries. Pixels with homogeneous semantic responses were aggregated into superpixel nodes. Graph edges were constructed according to spatial adjacency relationships, SDF affinity strength, and coplanar geometric consistency constraints. The construction process of the structural affinity matrix and topological connectivity is shown in Figure 3, presenting how SDF guidance was transformed into graph-level spatial relationships.
The graph formulation was introduced to convert dense pixel-wise reasoning into node-wise spatial reasoning over homogeneous structural regions. Each superpixel node represented a local region with similar semantic response and spatial continuity, while each edge represented a reliable path for feature transmission subject to adjacency, distance-field affinity, and coplanar-consistency constraints. This design reduced the influence of isolated noisy pixels and enabled occluded wall, floor, and ceiling regions to receive messages from physically adjacent nodes. The edge construction, therefore, served as a mathematical bridge between continuous SDF guidance and discrete non-Euclidean graph reasoning.
A three-layer graph convolutional reasoning network was configured with hidden feature dimensions of 512, 256, and 128. The graph convolutional layer performed feature smoothing over the graph structure based on the nodes' spatial relationships. The self-loop adjacency retained each node's original state during message passing, preventing the features of a small structural region from being erased by surrounding large regions. Symmetric normalization scaled the adjacency matrix elements by the product of the inverse square roots of the node degrees so that high-degree nodes and low-degree nodes contributed under comparable numerical magnitudes during propagation. Feed-forward propagation performed localized spatial aggregation, in which each node state absorbed high-dimensional features from adjacent coplanar clusters before the element-wise nonlinear rectification function was applied. This formulation made the graph convolution layer approximate semantic diffusion along physically meaningful indoor planes rather than unrestricted smoothing across the boundaries of unrelated objects. Graph node features were evaluated according to Equation 2.
Equation 2: 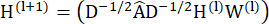
The projection from dense pixel features to superpixel nodes, graph-convolution message passing, and coordinate back-projection are presented in Figure 4, clarifying the feature-aggregation path from regular image grids to a non-Euclidean topology and back to a dense semantic representation. The projection from dense pixel features in Figure 4A to superpixel nodes in Figure 4B, graph-convolution message passing in Figure 4C, and coordinate back-projection in Figure 4D clarify the feature-aggregation path from regular image grids to a non-Euclidean topology and back to a dense semantic representation.
where H(l) denotes the node feature tensor of the l-th graph convolution layer, Â denotes the adjacency matrix with self-loop connections, D denotes the degree matrix corresponding to the adjacency matrix, W(l) denotes the learnable weight matrix of the l-th graph convolution layer, and σ denotes the Rectified Linear Unit activation function. The term ÂH(l) aggregated features from adjacent superpixel nodes, while D−1/2 and D−1/2 balanced the contribution of nodes with different connection densities. The learnable matrix W(l) projected aggregated node features into a new semantic space, allowing the graph layer to distinguish structural consistency from ordinary spatial closeness. The nonlinear activation preserved the difference in responses between coplanar and non-coplanar regions after feature aggregation.
Semantic segmentation features were decoded after graph reasoning. The decoder was constructed using three bilinear interpolation upsampling stages and cross-layer skip-connection fusion operations. Shallow spatial encoder features were concatenated with high-level semantic decoder features through channel-wise fusion. The feature resolution was restored to the original image size, and the final semantic probability prediction map was generated through a 1 × 1 convolution layer.
The full semantic parsing network was trained using a decoupled weight-decay optimizer (see the Table of Materials). The initial learning rate was set to 0.0001, the weight decay coefficient to 0.01, and the batch size to 8 for both public benchmarks. The first moment decay rate was set to 0.9, the second moment decay rate was set to 0.999, and the numerical stability epsilon coefficient was set to 1 × 10⁻8. The validation loss was monitored at the end of each epoch, and checkpoints were saved when the mIoU on the validation set increased. The network was trained for 300 epochs using a polynomial learning rate decay strategy with a decay power of 0.9. Five independent training runs were conducted using different random-seed initializations to establish a statistically rigorous evaluation baseline. The network was jointly optimized using pixel-level cross-entropy loss and structural consistency loss. All experiments were performed on a computing platform equipped with high-memory parallel computing hardware, and detailed hardware information was reported in the Table of Materials.
Joint optimization enforced geometric boundary alignment by computing the spatial gradient magnitude of the class probability tensor. The structural consistency loss was used as a regularizer, multiplying the norm of the spatial prediction gradients by the continuous SDF values. The mathematical rationale was that semantic category changes should concentrate near real architectural contours, where the SDF approaches zero, while flat wall, floor, and ceiling interiors should maintain smooth semantic responses. When a large prediction gradient appeared far from a structural boundary, the distance field term increased the penalty and discouraged false semantic transitions inside a homogeneous physical plane. When a prediction gradient appeared near a zero-distance contour, the penalty remained limited and preserved legitimate class transitions along architectural boundaries. Semantic transition regions were constrained to align with the zero-distance contours of the SDF, as given by Equation 3.
Equation 3: 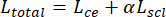
where Ltotal denotes the final optimization objective function, Lce denotes the pixel-level cross-entropy loss, Lscl denotes the structural consistency penalty loss, and α denotes the structural loss weighting coefficient. The cross-entropy term provided pixel-level semantic supervision via annotation masks, while the structural consistency term imposed geometric regularization using architectural priors. The weighting coefficient α balanced category recognition and boundary alignment, preventing the optimization from overfitting either local label accuracy or rigid structural contours. This joint objective linked visual semantics, physical boundary consistency, and trainable network parameters within a unified optimization target.
Access restricted. Please log in or start a trial to view this content.
Results
Experimental Setup
This study used two standard indoor scene parsing datasets, a large-scale indoor 3D dataset and an RGB-D indoor scene dataset, to evaluate performance and tune the model. The large-scale indoor 3D dataset contains realistically scanned, complex physical-space scenes and high-resolution RGB views, providing high-precision, pixel-by-pixel 3D point-cloud semantic labels and 2D spatial-projection segmentation masks. Its inherently realistic physical-space grid r...
Access restricted. Please log in or start a trial to view this content.
Discussion
This paper's algorithm tightly couples the hierarchical visual features captured by a shifted-window hierarchical transformer encoder with the prior depth of the Manhattan 3D bounding box generated by line-segment detection, thereby achieving high-precision semantic reconstruction of complex indoor scenes. A structure-guided cross-attention mechanism forces the visual signal to align with the true geometric boundary calibrated by the SDF, thereby restoring the continuity of low-level features in locally occluded area...
Access restricted. Please log in or start a trial to view this content.
Disclosures
The authors declare that they have no financial conflicts of interest.
Acknowledgements
Funding: Key Research and Development Program of Shaanxi (Program No. 2024CY2-GJHX-76).
Access restricted. Please log in or start a trial to view this content.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| AdamW optimizer | PyTorch Contributors | https://pytorch.org/ | |
| CCANet | Zihao Z. et al. | https://doi.org/10.1109/TCDS.2024.3455356 | |
| CMPFFNet | Zhou W. et al. | https://doi.org/10.1109/TASE.2023.3332021 | |
| ConvNeXt | Meta AI Research | https://github.com/facebookresearch/ConvNeXt | |
| InternImage | OpenGVLab | https://github.com/OpenGVLab/InternImage | |
| Mask2Former | Meta AI Research | https://github.com/facebookresearch/Mask2Former | |
| MaskDINO | IDEA-Research | https://github.com/IDEA-Research/MaskDINO | |
| NYUv2 | http://cs.nyu.edu/~silberman/datasets/nyu_depth_v2.html | ||
| OneFormer | SHI Labs | https://github.com/SHI-Labs/OneFormer | |
| RANSAC algorithm | scikit-learn developers | https://scikit-learn.org/ | |
| ScanNet V2 | http://www.scan-net.org/ | ||
| SegFormer | NVIDIA | https://github.com/NVlabs/SegFormer | |
| SGCA_GCN | Authors of this study | Proposed method (N/A) | |
| Softmax function | PyTorch Contributors | https://pytorch.org/ | |
| Swin Transformer | Microsoft Research | https://github.com/microsoft/Swin-Transformer |
References
- Zhang Z et al. CCANet: cross-modality comprehensive feature aggregation network for indoor scene semantic segmentation. IEEE Trans Cogn Dev Syst. 2024;17:366–378.
- Cui Y et al. Improving the segmentation of confusable indoor structures using point convolution and sparse vector attention. Geospat Inf Sci. 2025:1–22.
- Yang L, Cai H. Cost-efficient image semantic segmentation for indoor scene understanding using weakly supervised learning and BIM. J Comput Civ Eng. 2023;37:04022062–04022082.
- Uckan T, Aslan C, Hark C. A comprehensive hybrid approach for indoor scene recognition combining CNNs and text-based features. Sensors. 2025;25(17):5350. doi:10.3390/s25175350.
- Sun R et al. Training indoor and scene-specific semantic segmentation models to assist blind and low-vision users in activities of daily living. IEEE Open J Eng Med Biol. 2025;6:533–539.
- Ye S, Hu Y, Lin M. Indoor scene reconstruction with fine-grained details using hybrid representation and normal prior enhancement. IEEE Trans Vis Comput Graph. 2024;31:5275–5287.
- Naseer A et al. Multimodal scene recognition using semantic segmentation and deep learning integration. PeerJ Comput Sci. 2025;11. doi:10.7717/peerj-cs.2858.
- Bae JH, Yu GH, Lee JH. Superpixel image classification with graph convolutional neural networks based on learnable positional embedding. Appl Sci. 2022;12:9176–9190.
- Zhang H, Zou J, Zhang L. EMS-GCN: an end-to-end mixhop superpixel-based graph convolutional network for hyperspectral image classification. IEEE Trans Geosci Remote Sens. 2022;60:1–16.
- Mu Y, Ou L, Chen W. Superpixel-based graph convolutional network for UAV forest fire image segmentation. Drones. 2024;8:142–158.
- Khatun Z, Jonsson H Jr, Tsirilaki M. Beyond pixel: superpixel-based MRI segmentation through traditional machine learning and graph convolutional network. Comput Methods Programs Biomed. 2024;256:108398–108412.
- Yongyin L, Caixia Y. Cross-attention swin transformer for detailed segmentation of ancient architectural color patterns. Front Neurorobot. 2024;18:1513488–1513508.
- Zhou X, Zhou L, Gong S. Swin transformer embedding dual stream for semantic segmentation of remote sensing imagery. IEEE J Sel Top Appl Earth Obs Remote Sens. 2023;17:175–189.
- Ning X, Jiang L, Li W. Swin-MGNet: swin transformer-based multiview grouping network for 3D object recognition. IEEE Trans Artif Intell. 2024;6:747–758.
- Ke A, Luo J, Cai B. UNet-like network fused swin transformer and CNN for semantic image synthesis. Sci Rep. 2024;14:16761–16779.
- Li Y et al. IED-GCN: an internal and external decoupled graph convolutional network for landslide susceptibility assessment. IEEE Trans Geosci Remote Sens. 2025;63:1–17.
- He T, Chen J. DC-GCN: a lightweight graph convolutional network integrating local and global context for semantic segmentation. IEEE J Sel Top Appl Earth Obs Remote Sens. 2025;18:28283–28299. doi:10.1109/JSTARS.2025.3626006.
- Imani M. Superpixel-based graph convolutional neural network for polarimetric synthetic aperture radar image classification. Sci Rep. 2026;16:4736. doi:10.1038/s41598-025-34965-6.
- Wang S, Feng S, Wang Z. Structural prior-guided and feature-enhanced transformer with masked image modeling pretraining for retinal layers and fluid segmentation in macular edema OCT images. Biomed Opt Express. 2025;16:5096–5117.
- Yuan Z et al. Structure-aware progressive multimodal fusion network for RGB-T crack segmentation. J Imaging. 2025;11(11):384. doi:10.3390/jimaging11110384.
- Xu S, Shen R, Liu E. A structure-prior-guided adaptive context selection network for remote sensing semantic segmentation. Electron Lett. 2025;61. doi:10.1049/ell2.70161.
- Minaee S, Boykov Y, Porikli F. Image segmentation using deep learning: a survey. IEEE Trans Pattern Anal Mach Intell. 2021;44:3523–3542.
- Zhou E, Murray AT, Baik J. Mapping 3D classroom seats based on partial object point cloud completion. Cartogr Geogr Inf Sci. 2024;51:404–420.
- Nishi T, Kawasaki S, Iewaki K. M3R-CNN: on effective multimodal fusion of RGB and depth cues for instance segmentation in bin picking. Adv Robot. 2023;37:1143–1157.
- Zhou W, Xiao Y, Yan W. CMPFFNet: cross-modal and progressive feature fusion network for RGB-D indoor scene semantic segmentation. IEEE Trans Autom Sci Eng. 2023;21:5523–5533.
- Zhou W, Xiao Y, Liu Y. FIMKD: feature implicit mapping knowledge distillation for RGB-D indoor scene semantic segmentation. IEEE Trans Artif Intell. 2024;5:6488–6499.
- Liu J, Jiang Z, Xu X. Multi-robot collaborative complex indoor scene segmentation via multiplex interactive learning. CAAI Trans Intell Technol. 2025;10:1646–1660.
- Zhang S, Xie M. MIPANet: optimizing RGB-D semantic segmentation through multimodal interaction and pooling attention. Front Phys. 2024;12:1411559–1411572.
- Li JW et al. Construction of a multiscale feature fusion model for indoor scene recognition and semantic segmentation. Sci Rep. 2025;15:14701. doi:10.1038/s41598-025-95465-1.
- Liang X et al. Indoor building structure segmentation in unorganized point clouds based on corner feature. Eng Constr Archit Manag. 2025. doi:10.1108/ECAM-10-2024-1433.
- Wu LF, Wei D, Xu CA. CFANet: the cross-modal fusion attention network for indoor RGB-D semantic segmentation. J Imaging. 2025;11(6):177. doi:10.3390/jimaging11060177.
- Fan L, Zhou Y, Liu H. Combining swin transformer with UNet for remote sensing image semantic segmentation. IEEE Trans Geosci Remote Sens. 2023;61:1–11.
- Wang Z, Liao Z, Zhou B. SwinURNet: hybrid transformer-CNN architecture for real-time unstructured road segmentation. IEEE Trans Instrum Meas. 2024;73:1–16.
- Zhang H et al. Frequency-domain-guided swin transformer and global-local feature integration for remote sensing images semantic segmentation. IEEE Trans Geosci Remote Sens. 2025;63:5612611. doi:10.1109/TGRS.2025.3535724.
- Li GY, Chen J, Jang SI. SwinCross: cross-modal swin transformer for head and neck tumor segmentation in PET-CT images. Med Phys. 2024;51:2096–2107.
- Tang Y, Hu X, Ke T. Semantic segmentation of high-resolution remote sensing imagery via an end-to-end graph attention network with superpixel embedding. IEEE J Sel Top Appl Earth Obs Remote Sens. 2025;18:7236–7252.
- Wang R, Nie Y, Geng J. Multiscale superpixel-guided weighted graph convolutional network for polarimetric SAR image classification. IEEE J Sel Top Appl Earth Obs Remote Sens. 2024;17:3727–3741.
- Li S, Wu K, Liu H. Hyperspectral image classification based on multiscale feature search graph convolutional network with meta pseudo-labels. IEEE J Sel Top Appl Earth Obs Remote Sens. 2025;18:23485–23504.
- Yang B, Cheng X, Guo J. Temporal information-enhanced graph convolutional network with superpixel-pixel gated knowledge dynamic selection for change detection in satellite time series. IEEE J Sel Top Appl Earth Obs Remote Sens. 2024;17:18399–18412.
- Zhang H, Ku J, Zhao J. Multi-scale graph wavelet convolutional network for hyperspectral image classification. Front Remote Sens. 2025;6:1637820. doi:10.3389/frsen.2025.1637820.
- Zhou Q, Wang L, Gao G. Boundary-guided lightweight semantic segmentation with multiscale semantic context. IEEE Trans Multimedia. 2024;26:7887–7900.
- Xu X, Yen GG, Zhao C. Boundary-based active domain adaptation for semantic segmentation under adverse conditions. IEEE Trans Neural Netw Learn Syst. 2025;36:14721–14734.
- Tang Y, Feng S, Zhao C. A semantic change detection network based on boundary detection and task interaction for high-resolution remote sensing images. IEEE Trans Neural Netw Learn Syst. 2025;36:17184–17198.
- Guan L, Yuan X. Dynamic weighting and boundary-aware active domain adaptation for semantic segmentation in autonomous driving environment. IEEE Trans Intell Transp Syst. 2024;25:18461–18471.
- Fenglei W, Xin G, Zongze Z. A boundary-enhanced semantic segmentation model for buildings. IEEE J Sel Top Appl Earth Obs Remote Sens. 2025;18:5733–5748.
- Shan K, Tan L, Li Y, Jia T. Multi-scale boundary-aware network for remote sensing image semantic segmentation. Sci Rep. 2026;16:3797. doi:10.1038/s41598-025-33943-2.
- Wu D, Guo Z, Li A. Conditional boundary loss for semantic segmentation. IEEE Trans Image Process. 2023;32:3717–3731.
- Li Y, Zhang C, Wang H. Boundaries matter: a novel multibranch semisupervised semantic segmentation method. IEEE Intell Syst. 2024;40:35–44.
- Wang JQ, Chen T, Zheng L. A multiscale remote sensing semantic segmentation model with boundary enhancement based on UNetFormer. Sci Rep. 2025;15:14737. doi:10.1038/s41598-025-99663-9.
- Jung H, Choi HS, Kang M. Boundary enhancement semantic segmentation for building extraction from remote sensed image. IEEE Trans Geosci Remote Sens. 2021;60:1–12.
Access restricted. Please log in or start a trial to view this content.