This study presents a reproducible bioinformatics pipeline integrating transcriptomics, machine learning, and immune infiltration analysis to identify potential diagnostic biomarkers and regulatory networks in chronic obstructive pulmonary disease (COPD).
Research Article
UPP1 as a Diagnostic Biomarker: Insights from Integrative Bioinformatics and Immune Infiltration Analyses in COPD
* These authors contributed equally
In This Article
Summary
Abstract
COPD is a progressive respiratory disorder characterized by persistent airflow limitation and chronic inflammation, yet the role of N4-acetylcytidine (ac4C) RNA modification in its pathogenesis remains largely unexplored. This study aimed to systematically screen for ac4C-related genes (ac4C-RGs) from a published database and investigate their regulatory networks in COPD, thereby identifying potential biomarkers for further mechanistic studies without assuming a direct regulatory relationship between any specific gene and ac4C modification. Differentially expressed genes (DEGs) were identified from transcriptomic profiles, and weighted gene co-expression network analysis (WGCNA) was applied to uncover key co-expression modules. Cross-analysis among DEGs, significant modules, and ac4C-RGs was conducted. Key genes were screened using LASSO regression, XGBoost, and random forest algorithms, followed by logistic regression‑based diagnostic model construction. Model performance was evaluated by receiver operating characteristic (ROC) curve analysis, area under the curve (AUC) with 95% confidence intervals, calibration curve assessment, and decision curve analysis (DCA). A total of 160 overlapping genes were identified, and six hub genes (PTRF, PRKCDBP, UPP1, TOR3A, FAM168B, and B4GALT2) were consistently selected by all three machine learning algorithms. The diagnostic model demonstrated good discriminative performance, with AUCs of 0.766, 0.759, and 0.723 in the training, internal test, and external validation sets, respectively. Regulatory network analysis suggested potential ceRNA axes and transcription factor interactions, while immune infiltration profiling revealed significant correlations between key genes and multiple immune cell subsets. Drug-gene interaction analysis and molecular docking indicated that fluorouracil, capecitabine, and 5-benzylacyclouridine may exhibit favorable predicted binding affinities with UPP1. In conclusion, PTRF, PRKCDBP, UPP1, TOR3A, FAM168B, and B4GALT2 were identified as potential ac4C-related biomarkers in COPD, potentially involved in immune and metabolic regulation, providing a foundation for future functional investigations and therapeutic exploration.
Introduction
COPD is a chronic and heterogeneous respiratory disorder characterized by progressive airflow limitation resulting from abnormalities in alveolar and airway structures1,2. A protease-antiprotease imbalance, oxidative stress, chronic inflammation, and cellular senescence constitute the core pathophysiological mechanisms of COPD, leading to structural destruction and functional impairment of lung tissue3,4. Moreover, COPD is influenced by multiple risk factors, including long-term smoking, environmental pollution, occupational exposure, respiratory infections, and genetic susceptibility5,6. COPD has imposed a significant burden on the global economy. It is projected to account for 0.111% of global GDP annually from 2020 to 20507. Although current therapeutic strategies, such as bronchodilators, inhaled corticosteroids, pulmonary rehabilitation, and long-term oxygen therapy, can alleviate symptoms, halting disease progression remains challenging. Because of marked clinical heterogeneity, patient outcomes vary widely8. Therefore, novel diagnostic biomarkers and prognostic indicators are urgently needed to enhance COPD management and improve patient survival.
RNA modification refers to the chemical alteration of RNA molecules, which can change RNA structure and function to regulate gene expression9,10. Common RNA modifications include N6-methyladenosine (m6A), pseudouridine (Ψ), 5-methylcytosine (m5C), and ac4C11. The ac4C modification plays a crucial role in preserving mRNA stability and promoting mRNA translation12,13. NAT10 is the only known eukaryotic enzyme that catalyzes ac4C modification, and its activity is essential for the formation of this modification14. Studies have shown a strong correlation between oxidative stress, cellular senescence, inflammation, and ac4C modification. For example, CD4+ T lymphocytes in colon tissues from individuals with inflammatory bowel disease (IBD) exhibit markedly elevated levels of NAT1015. NAT10 enhances ac4C acetylation of the chemokines CCL2 and CXCL1, thereby promoting the infiltration of macrophages and neutrophils and exacerbating inflammatory damage16. The cellular response to oxidative stress may involve ac4C modification, as evidenced by the marked increase in ac4C levels under oxidative stress. In addition, NAT10 promotes PM2.5-induced pulmonary fibrosis by stabilizing TGFB1 mRNA via ac4C modification, thereby triggering epithelial-to-mesenchymal transition17. However, the role of ac4C modification in COPD remains largely unexplored, highlighting the need for further research in this area.
The GEO database was utilized in this study to identify DEGs between COPD patients and controls. A published list of ac4C-RGs, compiled from multiomics data18, was then integrated with the DEGs to identify overlapping candidates. Given that ac4C modification is known to influence inflammation and oxidative stress–key processes in COPD–we hypothesized that genes associated with the ac4C regulatory network might be dysregulated in COPD. However, the overlapping genes were not considered direct substrates of NAT10 or genes directly regulated by ac4C; rather, they were considered candidates associated with the ac4C-related network. Key genes were screened using multiple machine learning algorithms, followed by construction and validation of a diagnostic model. Subsequently, relevant pathways involved in COPD pathogenesis were determined, and potential targeted drugs were predicted. Finally, RT-qPCR assays were performed to confirm the expression levels of key genes, providing preliminary insights into COPD pathophysiology and potential avenues for therapeutic exploration.
Protocol
Institutional review board statement
This study was conducted in accordance with the Declaration of Helsinki. The protocol was approved by the Ethics Committee of Shenzhen Luohu Hospital of Traditional Chinese Medicine (approval no. 2024-LHQZYYYXLL-KY-039), and written informed consent was obtained from all participants prior to enrollment. Details of the research tools and materials used in this protocol are provided in the Table of Materials.
Data source and processing
COPD-related gene expression datasets were obtained from the Gene Expression Omnibus (GEO). The GSE54837 dataset was used as the transcriptome dataset, and the GSE112811 dataset served as the validation set (Table 1). The ac4C-RGs were collected from the literature18. DEGs between the COPD and control groups were identified using the R package limma. DEGs were considered statistically significant if |log2FC| > 0 and p < 0.05. Volcano plots were generated to visualize the overall distribution of gene expression changes.
Construction of WGCNA
WGCNA was performed on the GSE54837 dataset using R to identify COPD-related modules. Prior to network construction, outlier samples were identified and removed through hierarchical clustering analysis using the hclust function with the average linkage method and a Euclidean distance metric. The optimal soft-thresholding power (β = 10) was selected to achieve a scale-free topology fit index R2 ≥ 0.85, balancing scale-free topology and mean connectivity. An adjacency matrix was constructed and transformed into a topological overlap matrix (TOM). Gene modules were identified using the dynamic tree-cutting algorithm (deepSplit = 2, minClusterSize = 50). Modules with eigengene correlations > 0.75 were subsequently merged using the mergeCloseModules function. Module eigengenes were then correlated with clinical traits (COPD status, age, sex, and smoking status) using Pearson correlation coefficients to identify COPD-associated modules for subsequent analysis.
Screening, enrichment analysis, and PPI network analysis of overlapping genes
A Venn diagram was generated using the R package ggvenn to identify genes overlapping among the DEGs, MEsalmon module genes, and ac4C-RGs. Functional enrichment analysis of the overlapping genes was performed using Gene Ontology (GO) and Kyoto Encyclopedia of Genes and Genomes (KEGG) databases with the R package clusterProfiler. Protein-protein interaction (PPI) information was obtained from the STRING database (https://string-db.org/) to analyze protein-level interactions among the overlapping genes. Cytoscape software was used to visualize the resulting PPI network.
Identifying key genes through machine learning
Three machine learning techniques were applied: least absolute shrinkage and selection operator (LASSO) regression, extreme gradient boosting (XGBoost), and random forest (RF). LASSO regression was implemented using the glmnet package with 10-fold cross-validation to determine the optimal penalty parameter λ. The type.measure parameter was set to "deviance", and the family parameter was set to "binomial". The optimal λ was selected using the λmin criterion, which minimizes cross-validated deviance, yielding 17 genes. XGBoost was performed using the xgboost package with the following hyperparameters: nrounds = 100, max_depth = 6, eta = 0.3, subsample = 0.8, colsample_bytree = 0.8, and eval_metric = "logloss". Feature importance was ranked by the gain metric, and the top 30 genes were selected. Random forest was implemented using the randomForest package with ntree = 200. Feature importance was ranked by mean decrease in Gini, and the top 30 genes were selected. The genes selected by the three machine learning methods were intersected to identify key genes for subsequent analyses.
Building and assessing the logistic regression model for risk prediction
The GSE54837 dataset was randomly divided into a training set (70%) and a testing set (30%). A logistic regression model was constructed on the training set using the glm function from the MASS package, with the expression levels of key genes as input features. Model performance was evaluated using ROC curves generated with the pROC package. The 95% confidence intervals for the AUC were computed via 2,000 bootstrap replicates. Model calibration was assessed using calibration curves generated with 1,000 bootstrap resamples (rms package). DCA was performed using the dca package to evaluate net clinical benefit across a range of threshold probabilities. A nomogram was constructed using the nomogram function from the rms package to facilitate individualized risk estimation.
The regression equation was:
logit(P) = 0.5823 + 0.6010 × UPP1 - 0.6563 × PTRF + 0.3853 × B4GALT2 - 0.3972 × FAM168B + 0.1848 × PRKCDBP - 0.4787 × TOR3A. (1)
Here, P represents the predicted probability of COPD, and each coefficient represents the contribution of the corresponding gene-expression value to the log odds of COPD.
Expression analysis, GeneMANIA network, and molecular regulatory network
Gene expression levels between the COPD and control groups in the GSE54837 dataset were compared using the Wilcoxon rank-sum test. Box plots were generated using the ggplot2 package to visualize the distribution of expression levels, with median, interquartile range (IQR), and individual data points overlaid. GeneMANIA was used to construct gene networks and predict functional interactions. The search was performed with default parameters: species = Homo sapiens, maximum related genes = 20. The resulting network was downloaded and visualized, with edge colors indicating interaction types. A competitive endogenous RNA (ceRNA) network was constructed to investigate post-transcriptional regulatory mechanisms. miRNAs targeting the six key genes were predicted using two independent databases: DIANA-microT (score ≥ 0.8) and miRanda (score ≥ 140, energy ≤ −20 kcal/mol). The intersection of miRNAs identified by both databases was used to construct miRNA-mRNA pairs. Subsequently, lncRNAs targeting these miRNAs were predicted using the StarBase database. An lncRNA-miRNA-mRNA regulatory network was constructed and visualized using Cytoscape. Transcriptional regulatory relationships were predicted using ChIP-X Enrichment Analysis Version 3 (ChEA3). For each key gene with predicted TFs, the top 10 transcription factors with the highest enrichment scores were selected. A TF-target regulatory network was constructed in Cytoscape.
Gene set enrichment analysis and immune cell infiltration assessment
Gene set enrichment analysis (GSEA) was performed using the clusterProfiler package to investigate the biological functions of each key gene. For each key gene, samples were divided into high and low expression groups based on the median value. Differential expression analysis between the two groups was performed using limma, and the resulting gene list was ranked by the signed log₂ fold-change. GSEA was conducted using the gseGO function for GO biological process terms and the gseKEGG function for KEGG pathways, with the following parameters: minGSSize = 10, maxGSSize = 500, pvalueCutoff = 0.05, and nPerm = 1,000. The relative abundance of 28 immune cell types was estimated using single-sample gene set enrichment analysis (ssGSEA) implemented in the GSVA package. A curated gene set signature matrix comprising marker genes for 28 immune cell types was obtained from previous literature19. For each sample, the gsva function was applied with method = "ssgsea", ssgsea.norm = TRUE, and kcdf = "Gaussian". Spearman correlation coefficients between the ssGSEA enrichment scores and the expression levels of the six key genes were calculated using the cor.test function. The p values were adjusted for multiple testing using the Benjamini-Hochberg method. The correlation matrix was visualized as a heatmap using the pheatmap package.
Drug prediction, molecular docking, and disease association analysis
Potential therapeutic compounds targeting key genes were identified using the DrugBank database. A “key gene-targeting drug” interaction network was constructed in Cytoscape to visualize predicted drug-gene interactions. Molecular docking was performed using the CB-Dock2 platform to assess binding affinities. The 3D protein structure of human UPP1 was retrieved from the Protein Data Bank (PDB ID: 7B8T). Drug molecular structures (SMILES format) were obtained from PubChem. Docking was performed using the AutoDock Vina engine, and outputs were ranked by binding free energy (ΔG, in kcal/mol). Docking complexes were visualized using PyMOL. Associations between key genes and human diseases related to environmental exposures were investigated using the Comparative Toxicogenomics Database (CTD). Each gene was individually queried, and the top ten most strongly associated diseases were extracted and visualized using radar plots.
RT-qPCR protocol
Peripheral venous blood samples were collected from eight COPD patients and eight healthy controls at Shenzhen Luohu Hospital of Traditional Chinese Medicine. COPD was diagnosed according to the Global Initiative for Chronic Obstructive Lung Disease (GOLD) criteria, defined as a post-bronchodilator FEV1/FVC < 0.70. The control group comprised age- and sex-matched healthy volunteers with no history of respiratory diseases and normal pulmonary function tests (FEV1% predicted ≥ 80% and FEV1/FVC ≥ 0.70). The baseline information of the patients is shown in Table 2. Total RNA was extracted from COPD blood samples using a blood RNA extraction kit. For cDNA synthesis, 500 ng of total RNA was reverse-transcribed using a cDNA synthesis kit with genomic DNA removal following the provided protocol. The resulting cDNA was diluted to 150 ng/μL.
RT-qPCR was performed using a SYBR Green-based qPCR master mix on a real-time PCR system. Each 10 μL reaction contained 5 μL of 2x SYBR Green master mix, 0.5 μL each of forward and reverse primers (10 μM), 1 μL of diluted cDNA (15 ng/μL), and 3 μL of nuclease-free water. The cycling conditions were initial denaturation at 95 °C for 5 min, followed by 40 cycles of 95 °C for 10 s and 60 °C for 30 s, with a final melting curve analysis from 60 °C to 95 °C to verify amplification specificity. All reactions were performed in technical triplicates. β-actin was used as the internal reference gene. Primer efficiency for each target gene was validated using standard curve dilution series and ranged from 90% to 110%. Gene expression levels were normalized to β-actin, and relative expression was calculated using the 2-ΔΔCt method. Statistical comparisons between COPD and control groups were performed using the Mann-Whitney U test.
Statistical analysis
Network visualizations were created using Cytoscape, and statistical analyses were performed using R software. Unless otherwise indicated, the Mann-Whitney U test was used for nonnormally distributed data, and Student's t-test was used for normally distributed data to compare two groups. A value of p < 0.05 was considered statistically significant.
Results
Identification of overlapping genes, enrichment analysis, and PPI network construction
From the GSE54837 dataset, 3,371 DEGs were identified, including 1,675 upregulated and 1,696 downregulated DEGs. The top 10 genes with the most significant up- and downregulation are shown in Figure 1A. Hierarchical clustering of the GSE54837 data was performed (Supplementary Figure 1A), and a soft-thresholding power of 10 was applied to ensure scale-free network topology (Figure 1B). Gene co-expression modules were constructed using the dynamic tree cut method with a minimum module size of 50 genes, and each module was assigned a distinct color (Supplementary Figure 1B). Modules with eigengene correlations > 0.75 were subsequently merged (Supplementary Figure 1C, Figure 1C), resulting in 14 distinct modules. Based on Pearson correlation analysis between module eigengenes and clinical characteristics, the MEsalmon module (comprising 5,226 genes) exhibited the most significant positive correlation with COPD (r = 0.35, p = 7 x 10⁻8, Figure 1D). Venn analysis identified 160 overlapping genes among the 3,371 DEGs, 5,226 MEsalmon module genes, and 2,118 ac4C-RGs (Figure 1E). Functional enrichment analysis of these 160 genes showed that significant GO terms included single-stranded RNA binding, regulation of mRNA metabolic process, and RIG-I signaling pathway (Figure 1F). Additionally, KEGG analysis demonstrated that these genes were primarily enriched in Fc gamma R-mediated phagocytosis, the mRNA surveillance pathway, and focal adhesion (Figure 1G). The PPI network of overlapping genes contained 118 nodes and 196 edges (Figure 1H).
Identification of six key genes in COPD
To further identify potential key genes among the 160 overlapping candidates, three machine learning algorithms were applied. LASSO regression was first applied, with cross-validation used to determine the optimal penalty parameter (λ) ≈ 0.091 (Figure 2A). The coefficient profile plot indicated that 17 genes were retained at the optimal λ value (Figure 2B). XGBoost analysis identified the top 30 genes with the highest gain, among which PTRF, WBP11, and LDOC1L exhibited high predictive value (Figure 2C). The RF algorithm similarly ranked the top 30 genes according to their Gini importance scores, with PTRF, RFX5, and PRKCDBP among the most predictive (Figure 2D). Intersection analysis of genes selected by the three methods identified six key overlapping genes: PTRF, PRKCDBP, UPP1, TOR3A, FAM168B, and B4GALT2 (Figure 2E).
Diagnostic model construction and expression analysis of key genes
Using 70% of the GSE54837 dataset as the training set, a logistic regression model was established incorporating the six key genes. ROC curve analysis indicated moderate diagnostic performance, with AUCs of 0.766 (95% CI: 0.691–0.8417), 0.759 (95% CI: 0.6368–0.8817), and 0.723 (95% CI: 0.6085–0.8596) for the training, internal test, and external validation sets, respectively (Figure 3A–C). Calibration analysis confirmed high reliability, and DCA indicated clear net clinical benefit across a wide range of threshold probabilities in both training (Figure 3D–E) and validation sets (Figure 3F–G). A nomogram was constructed to visualize the contribution of each gene and facilitate individualized risk estimation (Figure 3H). Expression analysis revealed that B4GALT2, PRKCDBP, and UPP1 were significantly upregulated in COPD samples, whereas FAM168B, PTRF, and TOR3A were downregulated (Figure 3I).
Regulatory network and functional analysis of key genes in COPD
A functional interaction network comprising the top 20 genes most related to the identified hub genes was constructed using GeneMANIA analysis (Figure 4A). Physical interactions accounted for the majority of connections, followed by co-expression correlations and shared protein domains. Functional annotation indicated significant enrichment in processes such as nucleobase-containing small molecule catabolic process, nucleoside catabolic process, and plasma membrane raft. Post-transcriptional regulation was investigated by intersecting miRNA predictions from the DIANA-microT and miRanda databases, identifying eight overlapping miRNAs (Figure 4B). A lncRNA-miRNA-mRNA regulatory axis was subsequently constructed. According to the Sankey diagram, two of the identified miRNAs, both associated with the regulation of FAM168B, were predicted to be targeted by seven lncRNAs; no such regulatory interactions were identified for the remaining five hub genes (Figure 4C). Transcriptional regulation was further explored using the ChEA3 platform, which predicted upstream transcription factors (TFs) for B4GALT2, UPP1, FAM168B, and TOR3A. The top ten TFs for each gene were selected to construct a TF-target regulatory network (Figure 4D). GSEA was performed to investigate the biological functions of the six key genes. UPP1 was significantly enriched in biological processes such as diacylglycerol metabolic process and purine nucleoside triphosphate biosynthetic process, as well as pathways including proteasome and metabolism of xenobiotics by cytochrome P450 (Figure 4E–F). Enrichment results for the remaining five key genes are provided in Supplementary Figure 2A–J.
Immune infiltration of UPP1 and prediction of drug targets in COPD
Immune infiltration levels of 28 immune cell types were evaluated in control and COPD groups using the ssGSEA algorithm. In COPD patients, memory B cells, myeloid-derived suppressor cells, and activated dendritic cells showed significantly higher enrichment scores. In contrast, type 1 T helper cells, activated B cells, and immature B cells showed significantly lower enrichment scores (Figure 5A). It should be noted that ssGSEA provides relative immune cell enrichment estimates based on transcriptomic data rather than direct measurements of immune cell proportions. Correlation analysis revealed that the six key genes exhibited differential association patterns with immune cell subsets. Specifically, UPP1, PRKCDBP, and B4GALT2 were positively correlated with the infiltration levels of memory B cells, activated dendritic cells, and myeloid-derived suppressor cells (Spearman ρ > 0.4, p < 0.05), while PTRF, TOR3A, and FAM168B showed negative correlations with type 1 T helper cells and activated B cells (Spearman ρ < −0.3, p < 0.05). The complete correlation matrix is presented in the heatmap (Figure 5B). Drug prediction analysis identified UPP1 as the only gene among the six candidates with predicted interactions with small molecules. Three compounds, including fluorouracil, capecitabine, and 5-benzylacyclouridine, were identified from the database as potential UPP1-interacting compounds (Figure 5C). These compounds are primarily used in oncology or experimental settings, and their relevance to COPD requires further investigation. Binding free energy calculations revealed that 5-benzylacyclouridine exhibited the strongest binding affinity, suggesting a relatively higher predicted binding affinity (Table 3). Molecular docking visualizations for all three compounds indicated favorable predicted binding conformations with UPP1, consistent with computational docking predictions rather than experimental validation (Figure 5D–F). Additionally, CTD analysis indicated that all six key genes were strongly associated with various disease phenotypes, including delayed effects of prenatal exposure, weight loss, hepatomegaly, and inflammation (Figure 5G–L).
RT-qPCR validation of key diagnostic genes in clinical samples
To validate the expression levels of key genes, blood samples were collected from eight COPD patients and eight control subjects, and this analysis was considered a preliminary validation due to the limited sample size. As shown in Figure 6A–F, PTRF, TOR3A, and FAM168B were significantly downregulated, whereas PRKCDBP and UPP1 were significantly upregulated in COPD samples, consistent with the trends observed in the bioinformatics analysis. In contrast, no significant difference was observed for B4GALT2 expression between the two groups. This discrepancy may be attributed to the limited sample size or differences in sample types between datasets and clinical specimens.
DATA AVAILABILITY STATEMENT:
All RNA-sequencing data were obtained from the Gene Expression Omnibus database (GEO, https://www.ncbi.nlm.nih.gov), with GSE54837 selected as the training set and GSE112811 as the validation set. The code used in this analysis can be obtained from https://doi.org/10.5281/zenodo.21771476.
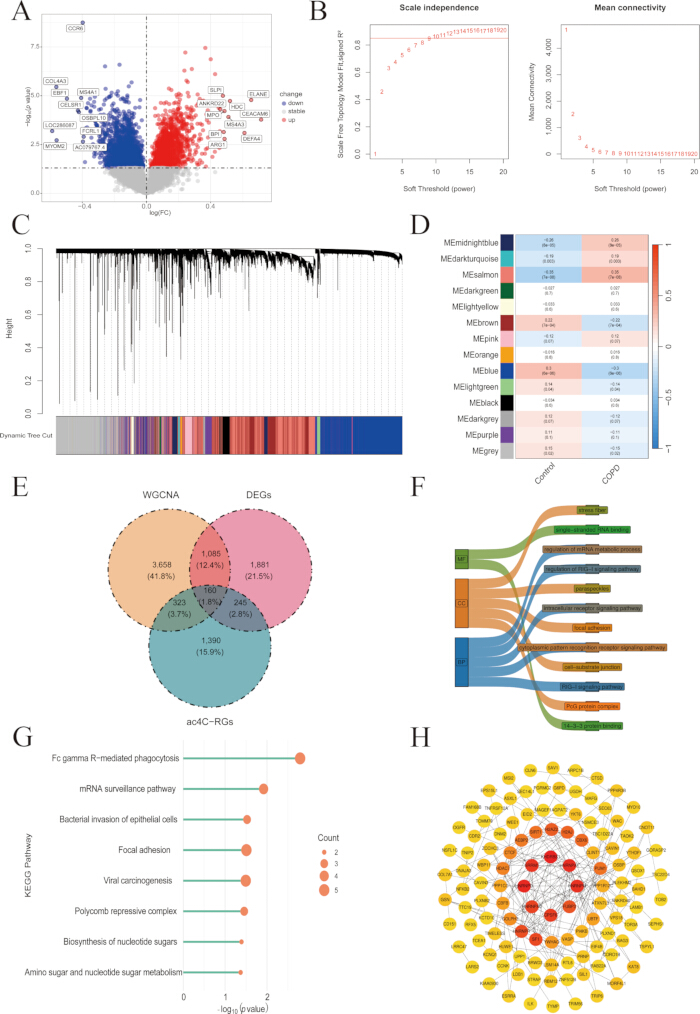
Figure 1: Identification of overlapping genes, enrichment analysis, and PPI network construction. (A) Volcano plot of DEGs in the GSE54837 dataset. (B) Soft threshold screening. (C) Module clustering dendrogram (after merging). (D) Heat map of the correlation between modules and traits. (E) Venn diagram for identifying overlapping genes. (F) Mulberry diagram of GO enrichment analysis, showing the main enrichment results of the intersection genes in MF, CC, and BP. (G) Lollipop diagram of KEGG signaling pathway enrichment analysis, the bubble size represents the number of enriched genes. (H) PPI network of the overlapping genes; nodes represent proteins, and edges represent protein-protein interactions. Abbreviations: DEGs = differentially expressed genes; PPI = protein-protein interaction; GO = Gene Ontology; MF = molecular function; CC = cellular component; BP = biological process; KEGG = Kyoto Encyclopedia of Genes and Genomes; ac4C-RGs = N4-acetylcytidine-related genes. Please click here to view a larger version of this figure.
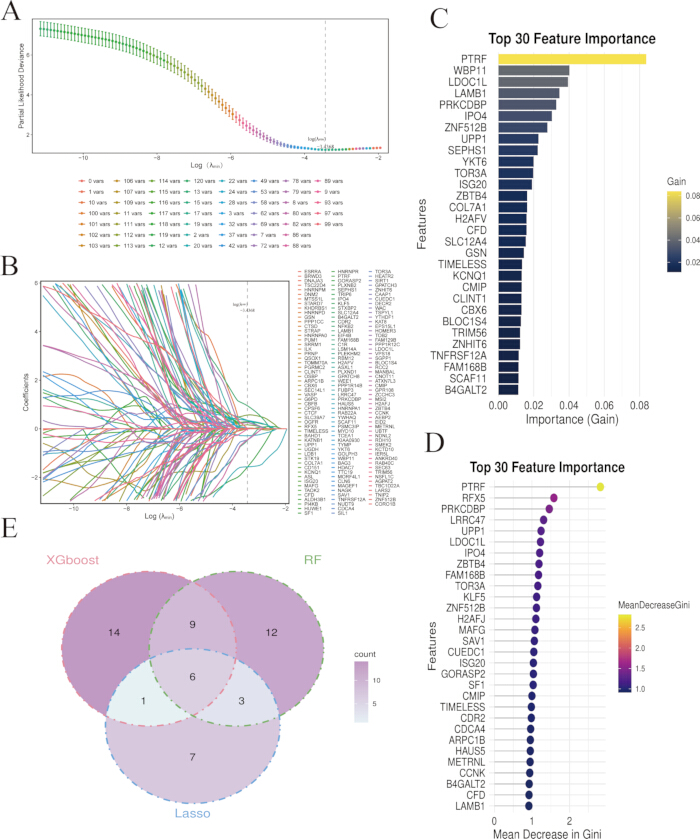
Figure 2: Identification of six key genes in COPD. (A) LASSO cross-validation curve. (B) LASSO regression coefficient path diagram. As λ increases, the coefficients of unimportant genes converge to 0. (C) XGBoost feature importance ranking. The x-axis represents the gain value, the y-axis represents the gene name, and the color depth represents the importance. (D) RF feature importance ranking. The x-axis represents mean decrease in Gini. (E) The Venn diagram of overlapping genes obtained by cross-analysis of the three algorithms. Abbreviations: LASSO = least absolute shrinkage and selection operator; XGBoost = extreme gradient boosting; RF = random forest. Please click here to view a larger version of this figure.
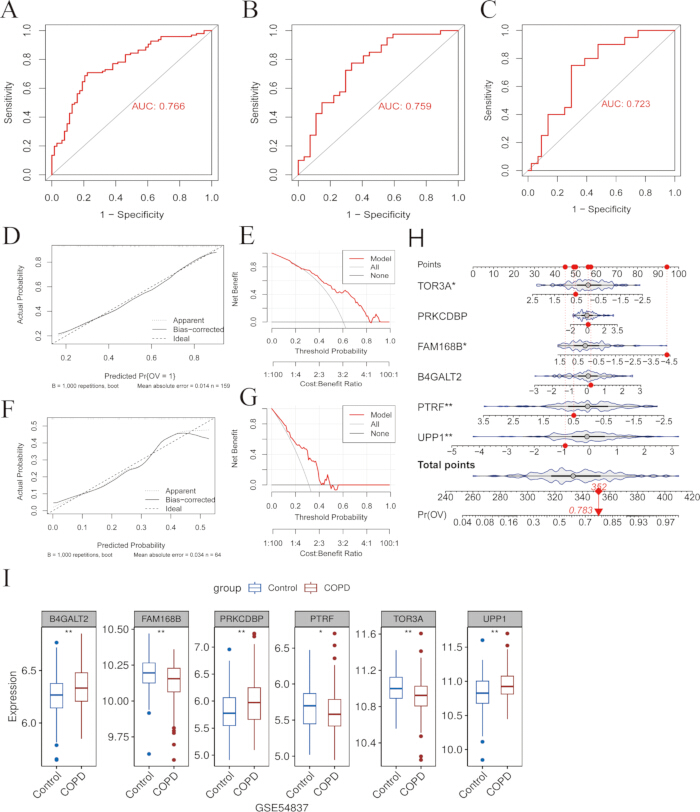
Figure 3: Construction of a diagnostic model and expression analysis of key genes. (A) ROC curve of the training set. (B) ROC curve of the internal test set. (C) ROC curve of the external validation set. (D) Calibration curve of the training set. (E) DCA of the training set. (F) Calibration curve of the external validation set. (G) DCA of the external validation set. (H) Nomogram of six key genes. For prediction of individual COPD risk, each gene is assigned a corresponding score. (I) Expression analysis of six key genes in COPD and control samples of the GSE54837 dataset. Abbreviations: ROC = receiver operating characteristic; AUC = area under the curve; DCA = decision curve analysis; COPD = chronic obstructive pulmonary disease. Please click here to view a larger version of this figure.
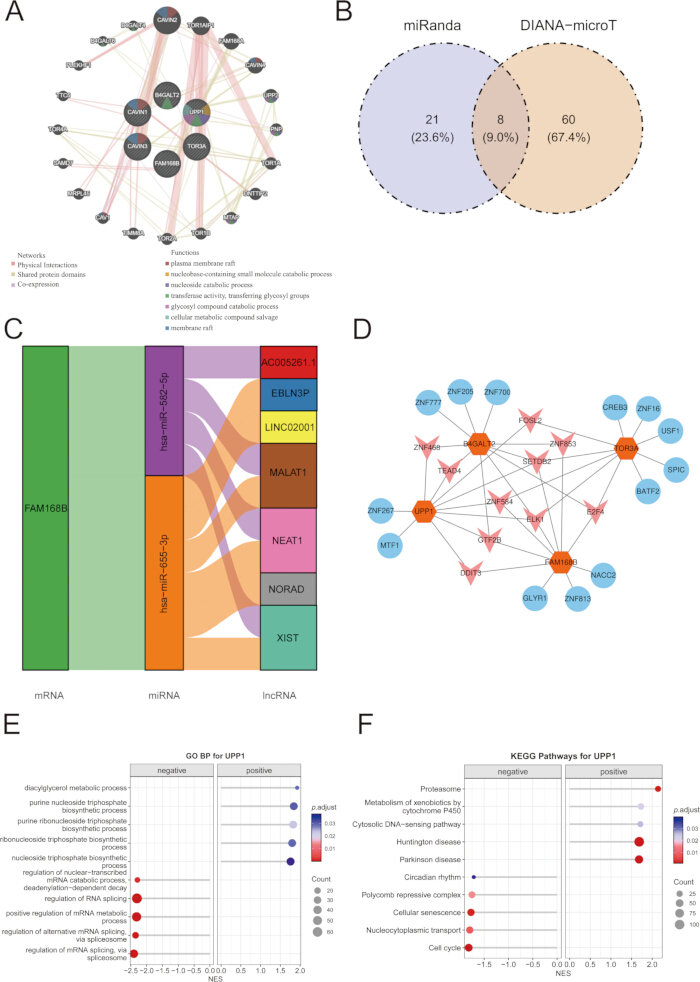
Figure 4: Regulatory network and functional significance of key genes in COPD. (A) GeneMANIA analysis results of 6 key genes. The color of the lines indicates the correlation between genes, and the color of the nodes indicates different functional categories. (B) Venn diagram of cross-analysis of DIANA-microT and miRanda databases. (C) Mulberry diagram of the ceRNA regulatory network. (D) Potential transcription factor regulatory network. Blue nodes represent transcription factors, and orange nodes represent target genes. (E) Single gene GSEA enrichment analysis of UPP1, including GO. (F) Single gene GSEA enrichment analysis of UPP1, including KEGG. Abbreviations: GO = Gene Ontology; KEGG = Kyoto Encyclopedia of Genes and Genomes. Please click here to view a larger version of this figure.
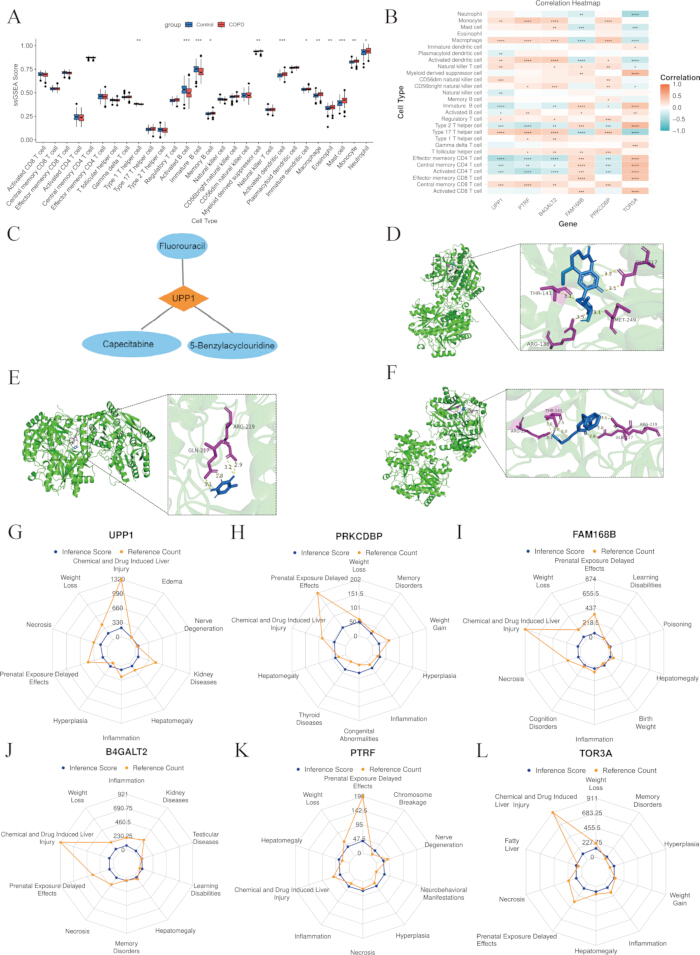
Figure 5: Immune infiltration of key genes and prediction of drug targets in COPD. (A) Differences in immune cell abundance between groups. (B) Heat map of the correlation between immune cells and key genes. (C) Interaction network between key genes and predicted drugs. (D) Molecular docking of fluorouracil with UPP1. (E) Molecular docking of capecitabine with UPP1. (F) Molecular docking of 5-benzylacyclouridine with UPP1. For each compound, the left image shows the overall docking conformation, and the right image shows the local binding interactions. (G) CTD analysis of B4GALT2. (H) CTD analysis of FAM168B. (I) CTD analysis of PRKCDBP. (J) CTD analysis of PTRF. (K) CTD analysis of TOR3A. (L) CTD analysis of UPP1. Please click here to view a larger version of this figure.
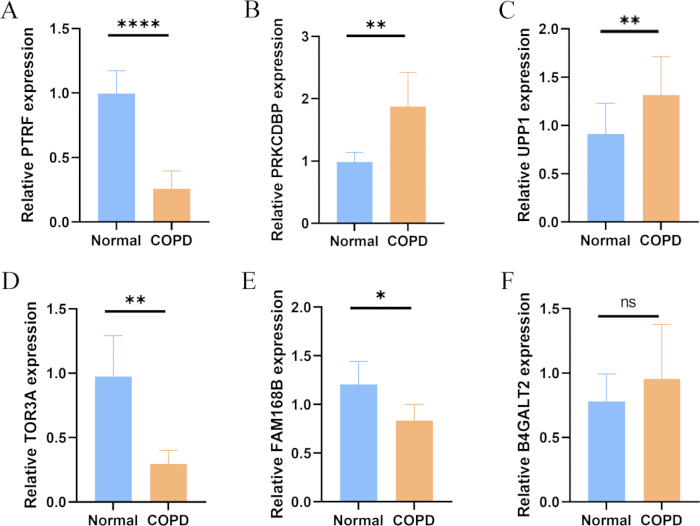
Figure 6: RT-qPCR validation of key gene expression in COPD and control samples. (A) Relative expression of PTRF. (B) Relative expression of PRKCDBP. (C) Relative expression of UPP1. (D) Relative expression of TOR3A. (E) Relative expression of FAM168B. (F) Relative expression of B4GALT2. ns = not significant, p > 0.05; * p < 0.05; ** p < 0.01; *** p < 0.001; **** p < 0.0001. Abbreviation: RT-qPCR = reverse transcription quantitative polymerase chain reaction. Please click here to view a larger version of this figure.
Supplementary Figure 1: GSE54837 dataset samples and gene module clustering. (A) Sample clustering diagram of the GSE54837 dataset. (B) Module clustering dendrogram before merging. Genes were grouped using the dynamic tree cut method to identify distinct modules. (C) Hierarchical clustering dendrogram of module eigengenes. Modules with similar expression patterns were clustered based on their eigengene similarity.Please click here to download this file.
Supplementary Figure 2: GSEA enrichment analysis. (A) GO analysis of PRKCDBP. (B) KEGG analysis of PRKCDBP. (C) GO analysis of PTRF. (D) KEGG analysis of PTRF. (E) GO analysis of TOR3A. (F) KEGG analysis of TOR3A. (G) GO analysis of FAM168B. (H) KEGG analysis of FAM168B. (I) GO analysis of B4GALT2. (J) KEGG analysis of B4GALT2. Abbreviations: GO = Gene Ontology; KEGG = Kyoto Encyclopedia of Genes and Genomes.Please click here to download this file.
| Dataset | Controls | Patients | Sequencing platform |
| GSE54837 | 90 | 136 | GPL570 |
| GSE112811 | 44 | 20 | GPL570 |
Table 1: Gene expression datasets used in the study. Characteristics of the GSE54837 and GSE112811 datasets used for model development/internal testing and external validation, respectively.
| Patient | 1 | 2 | 3 | 4 | 5 | 6 | 7 | 8 |
| Gender (F/M) | M | M | M | F | M | M | M | M |
| Age (years) | 69 | 72 | 75 | 73 | 68 | 70 | 69 | 71 |
| Smoking status | Yes | Yes | Quit smoking(2 years) | No | Yes | Yes | Yes | Quit smoking(5 years) |
| Pack-years | 20 per day / 30 years | 15 per day / 35 years | 20 per day / 50 years | 20 per day /40 years | 30 per day / 40 years | 15 per day / 40 years | 20 per day / 30 years | |
| COPD group | 2 | 3 | 3 | 2 | 2 | 3 | 2 | 3 |
Table 2: Baseline characteristics of the study participants. Baseline demographic and clinical characteristics of the COPD patients and healthy controls included in the RT-qPCR validation.
| Molecular name | Gene | Score(kcal/mol) |
| 5-Benzylacyclouridine | UPP1 | -9.6 |
| Capecitabine | UPP1 | -6.1 |
| Fluorouracil | UPP1 | -5.5 |
Table 3: Molecular docking results for UPP1 and candidate compounds.
Predicted molecular docking results for the interaction of UPP1 with fluorouracil, capecitabine, and 5-benzylacyclouridine, including their binding affinities.
Discussion
The conserved RNA modification ac4C, which predominantly occurs in messenger RNA (mRNA) and transfer RNA (tRNA), enhances mRNA stability and translation efficiency20. NAT10 is the only known RNA acetyltransferase mediating ac4C modification21. Studies have shown that NAT10 is upregulated in lung epithelial cells of COPD patients. Knockdown of NAT10 disrupts mitochondrial function and transcriptomic responses22. Based on integrated multiomics analysis, this study identified six key genes closely associated with COPD and developed a diagnostic model, which showed moderate diagnostic performance and potential value for further investigation. Further analysis revealed the key roles of these genes in transcriptional regulation, ceRNA networks, and the immune microenvironment. In addition, potential targeted drugs were predicted, providing insights into COPD pathogenesis and facilitating the development of personalized precision treatment strategies. We identified genes that were both differentially expressed in COPD and present in a previously published ac4C-related gene list using WGCNA and differential expression analysis. It is important to note that these genes are selected based on their association with the ac4C regulatory network, not on proven mechanistic links to NAT10 or ac4C acetylation, yielding a total of 160 candidate genes. Six key genes (PTRF, PRKCDBP, UPP1, TOR3A, FAM168B, and B4GALT2) were identified through machine learning algorithms. Among them, PTRF plays a critical role in house dust mite (HDM)-induced airway inflammation by regulating IL-33-ZBP1-mediated macrophage necroptosis, suggesting that it may be involved in chronic inflammatory lung conditions such as COPD23. Lai et al.24demonstrated that exogenous uridine administration inhibits ferroptosis in macrophages via the Nrf2/SLC7A11/GPX4 pathway, thereby alleviating acute lung injury caused by sepsis. Although upregulation of UPP1, a key enzyme in uridine metabolism, was observed in lung tissue from acute lung injury models, its exact role—and whether this upregulation represents a protective response or a consequence of tissue damage—remains to be further elucidated. However, this finding suggests that UPP1 may have a potential association with the pathophysiological processes of inflammatory lung diseases such as COPD, warranting further investigation. The remaining four key genes have been less investigated in lung-related disorders, but based on their functions in other diseases and our current findings, we hypothesize potential pathways through which they may contribute to COPD pathogenesis.
Based on the six key genes, we constructed a COPD diagnostic model and validated its good predictive performance. Expression analysis showed that UPP1, B4GALT2, and PRKCDBP were significantly upregulated, whereas FAM168B, PTRF, and TOR3A were markedly downregulated in COPD. Although B4GALT2 was identified as upregulated in the dataset analysis, no significant difference was observed in the RT-qPCR validation. This discrepancy may be attributed to the limited sample size, cohort heterogeneity, and differences in sample sources between the public datasets and clinical blood samples. Gene set enrichment analysis revealed that these key genes were significantly enriched in RNA splicing and mRNA processing, as well as in pathways such as the cell cycle and nicotine addiction. Irreversible cell cycle arrest has been recognized as a primary mechanism underlying cellular senescence, which may contribute substantially to the pathophysiology of COPD25,26. Further analysis indicated that the senescence-associated secretory phenotype (SASP) induced by DNA damage may promote the persistent progression of COPD by maintaining chronic inflammation and exacerbating lung tissue injury27. A previous study also reviewed the genetic links underlying nicotine addiction and COPD28. Although smoking is the primary risk factor for COPD, only a small proportion of smokers develop the disease, suggesting that genetic factors play an important role in both COPD and nicotine dependence. Liu et al.29 summarized the roles of RNA-binding proteins (RBPs) in COPD and pulmonary hypertension (PH), emphasizing their involvement in pulmonary vascular remodeling and inflammatory responses through the regulation of mRNA splicing and post-transcriptional gene expression, thereby highlighting their potential as biomarkers and therapeutic targets. In summary, the key genes and associated pathways identified in this study not only deepen our understanding of COPD pathogenesis but also provide a solid foundation for developing future diagnostic biomarkers and targeted therapeutic strategies.
The ceRNA network involves various RNA species, including lncRNAs, circRNAs, and mRNAs, which competitively bind to shared miRNAs, thereby forming mutual regulatory relationships and influencing gene expression30. This complex network participates in numerous physiological and pathological processes and contributes to elucidating gene regulatory mechanisms and the pathogenesis of diseases such as cancer and chronic inflammatory disorders. For instance, Wang et al. constructed a ceRNA coexpression network comprising 11 lncRNAs, five miRNAs, and 16 mRNAs, in which the core subnet was associated with changes in immune cell proportions and lung function in COPD31. Similarly, Zhang et al.32 developed a circRNA-miRNA-mRNA ceRNA network based on peripheral blood mononuclear cells from male smokers, identifying dysregulated circRNAs and key pathways related to COPD. Our coexpression network analysis revealed that the key genes primarily established functional connections through physical interactions, coexpression, and shared protein domains and were significantly enriched in multiple metabolism-related pathways. Based on these findings, we further constructed a transcription factor (TF)-target regulatory network and a miRNA-lncRNA-mRNA regulatory axis. These results suggest that the key genes may be cooperatively regulated through multilevel mechanisms involving lncRNAs, transcription factors, and miRNAs in COPD.
Immune infiltration reflects the immune status by indicating the distribution and activity of immune cells within tissues or blood. Based on this, potential candidate drugs were predicted using computational screening, followed by molecular docking simulations to assess binding affinity and stability with target proteins. Together, these analyses facilitate the identification of novel therapeutic agents and provide deeper insights into disease mechanisms. In this study, six key genes were positively correlated with most immune cell infiltrations. Drug prediction identified potential interactions between UPP1 and fluorouracil, capecitabine, and 5-benzylacyclouridine, with the latter exhibiting the strongest binding affinity, as further confirmed by molecular docking. Notably, fluorouracil and capecitabine are primarily used as antitumor agents and were identified in this study as database-predicted UPP1-interacting compounds rather than validated therapeutic options for COPD. Previous studies have reported that local administration of fluorouracil may improve airway patency in cases of severe airway obstruction33. However, other evidence indicates that fluorouracil and capecitabine may induce pulmonary toxicity, particularly in patients with pre-existing lung conditions34. Therefore, their potential relevance to COPD requires further experimental and safety verification. Moreover, the CTD analysis indicated that all six key genes were associated with multiple pathological processes. Collectively, the integrated analysis of immune infiltration, drug prediction, and molecular docking provides new molecular targets and a theoretical basis for the precision treatment of COPD, thereby promoting the development and clinical translation of related drugs.
Nevertheless, several limitations should be acknowledged. The study relied on public datasets with relatively limited sample sources, which may introduce batch effects and potential model overfitting. The RT-qPCR validation was conducted in a small cohort, and the observed inconsistency in B4GALT2 expression suggests possible cohort heterogeneity. In addition, immune infiltration and drug prediction analyses were computational in nature and require further experimental validation. Furthermore, as a discovery phase bioinformatics investigation, our diagnostic model was evaluated primarily using AUC values with 95% confidence intervals. Comprehensive performance metrics such as sensitivity, specificity, predictive values, and detailed calibration statistics were not fully assessed due to the retrospective nature of the public datasets and limited sample sizes. Therefore, our model should be regarded as a proof-of-concept tool, and its clinical utility warrants further validation in larger prospective cohorts.
Through integrative bioinformatics and machine learning analyses, this study identified six key genes significantly associated with COPD. A robust diagnostic model was established, demonstrating reliable predictive performance across multiple cohorts. Functional analyses revealed that these genes participate in critical regulatory networks involving transcriptional and post-transcriptional regulation, immune cell infiltration, and pathways related to nicotine addiction and the cell cycle. Drug prediction and molecular docking analyses highlighted UPP1 as a promising therapeutic target, with several candidate compounds exhibiting strong binding affinities. Overall, these findings enhance our understanding of COPD pathophysiology and provide valuable molecular targets for future therapeutic development and precision medicine strategies.
Disclosures
The authors declare no conflicts of interest. Informed consent was obtained from all subjects involved in the study.
Acknowledgements
We acknowledge the Shenzhen Luohu Hospital of Traditional Chinese Medicine for providing the clinical facilities and administrative support essential for this study. Finally, we are grateful to all the patients and healthy volunteers who participated in this research; their contribution was indispensable to this work. This work was supported by the Sanming Project of Medicine in Shenzhen (No. SZZYSM202401018), the Luohu District Priority Specialty Funds (No. LX202402021), and the Luohu District Priority Specialty Funds (No. LX202302064).
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| β-actin primers | Tsingke | N/A | Forward: 5’-CATGTACGTTGCTATCCAGGC-3’ Reverse: 5’-CTCCTTAATGTCACGCACGAT-3’ |
| B4GALT2 primers | Tsingke | N/A | Forward: 5’-GGGCAGACTGCTGATCGAG-3’ Reverse: 5’-CCGGTGTCTAAAGGGGATGAT-3’ |
| CB-Dock2 | LabShare | Online | Molecular docking |
| clusterProfiler | Bioconductor | v4.14.6 | Enrichment analysis |
| Cytoscape | Cytoscape Consortium | v3.8.3 | Network visualization |
| DrugBank | University of Alberta | Online | Drug prediction |
| FAM168B primers | Tsingke | N/A | Forward: 5’-TCTGGGGTTCCCTATGCAAAT-3’ Reverse: 5’-GTAGGATTCGCTCCAGGATACA-3’ |
| glmnet | CRAN | v4.1 | LASSO regression |
| GSVA | Bioconductor | v1.52.3 | ssGSEA analysis |
| Hifair III 1st Strand cDNA Synthesis Supermix | YEASEN | 11141ES | cDNA synthesis |
| Hieff RTPCR SYBR Green Master Mix | YEASEN | 11201ES | qPCR amplification |
| limma | Bioconductor | v3.54.0 | Differential expression |
| LightCycler 480 II System | Roche | LightCycler 480 II | Real-time PCR |
| PTRF primers | Tsingke | N/A | Forward: 5’-GGGCCGTAGACCAGATCCA-3’ Reverse: 5’-CTTGCTCACCGTATTGCTCGT-3’ |
| PRKCDBP primers | Tsingke | N/A | Forward: 5’-CACGTTCTGCTCTTCAAGGAG-3’ Reverse: 5’-TGTACCTTCTGCAATCCGGTG-3’ |
| R software | R Foundation | v4.4.2 | Statistical computing |
| randomForest | CRAN | v4.7 | Random Forest |
| RNA isolater MolPure Blood RNA Kit | YEASEN | 19241ES50 | RNA extraction |
| STRING database | EMBL | Online | PPI network |
| TOR3A primers | Tsingke | N/A | Forward: 5’-CCCTTGCTCTGTCGTTCCAC-3’ Reverse: 5’-CCCGTCCCGATACAGGTTC-3’ |
| UPP1 primers | Tsingke | N/A | Forward: 5’-CTGTCAGTCATGGTATGGGCA-3’ Reverse: 5’-GAGCACCGGGCATAGTACA-3’ |
| WGCNA | CRAN | v1.72 | Co-expression network |
| xgboost | CRAN | v1.7 | XGBoost algorithm |
References
- Hogg JC. Pathophysiology of airflow limitation in chronic obstructive pulmonary disease. Lancet. 2004;364(9435):709-21.
- Baraldo S, Turato G, Saetta M. Pathophysiology of the small airways in chronic obstructive pulmonary disease. Respiration. 2012;84(2):89-97.
- Fischer BM, Pavlisko E, Voynow JA. Pathogenic triad in COPD: oxidative stress, protease-antiprotease imbalance, and inflammation. Int J Chron Obstruct Pulmon Dis. 2011;6:413-21.
- Pandey KC, De S, Mishra PK. Role of proteases in chronic obstructive pulmonary disease. Front Pharmacol. 2017;8:512.
- Wang L, Xie J, Hu Y, Tian Y. Air pollution and risk of chronic obstructed pulmonary disease: the modifying effect of genetic susceptibility and lifestyle. EBioMedicine. 2022;79:103994.
- Elonheimo HM, et al. Environmental substances associated with chronic obstructive pulmonary disease-a scoping review. Int J Environ Res Public Health. 2022;19(7):3945.
- Chen S, et al. The global economic burden of chronic obstructive pulmonary disease for 204 countries and territories in 2020-50: a health-augmented macroeconomic modelling study. Lancet Glob Health. 2023;11(8):e1183-e93.
- Rutten-van Mölken MP, et al. Costs and effects of inhaled corticosteroids and bronchodilators in asthma and chronic obstructive pulmonary disease. Am J Respir Crit Care Med. 1995;151(4):975-82.
- Ontiveros RJ, Stoute J, Liu KF. The chemical diversity of RNA modifications. Biochem J. 2019;476(8):1227-45.
- Roundtree IA, Evans ME, Pan T, He C. Dynamic RNA modifications in gene expression regulation. Cell. 2017;169(7):1187-200.
- Wang C, et al. RNA modification in cardiovascular disease: implications for therapeutic interventions. Signal Transduct Target Ther. 2023;8(1):412.
- Zhang W, et al. ac4C acetylation regulates mRNA stability and translation efficiency in osteosarcoma. Heliyon. 2023;9(6):e17103.
- Qiu L, Jing Q, Li Y, Han J. RNA modification: mechanisms and therapeutic targets. Mol Biomed. 2023;4(1):25.
- Luo J, Cao J, Chen C, Xie H. Emerging role of RNA acetylation modification ac4C in diseases: current advances and future challenges. Biochem Pharmacol. 2023;213:115628.
- Li H, et al. RNA cytidine acetyltransferase NAT10 maintains T cell pathogenicity in inflammatory bowel disease. Cell Discov. 2025;11(1):19.
- Wang JN, et al. NAT10 exacerbates acute renal inflammation by enhancing N4-acetylcytidine modification of the CCL2/CXCL1 axis. Proc Natl Acad Sci U S A. 2025;122(17):e2418409122.
- Shenshen W, et al. NAT10 accelerates pulmonary fibrosis through N4-acetylated TGFB1-initiated epithelial-to-mesenchymal transition upon ambient fine particulate matter exposure. Environ Pollut. 2023;322:121149.
- Liu J, et al. Unveiling ac4C modification pattern: a prospective target for improving the response to immunotherapeutic strategies in melanoma. J Transl Med. 2025;23(1):287.
- Su F, et al. Multimodal single-cell analyses outline the immune microenvironment and therapeutic effectors of interstitial cystitis/bladder pain syndrome. Adv Sci (Weinh). 2022;9(18):e2106063.
- Schiffers S, Oberdoerffer S. ac4C: a fragile modification with stabilizing functions in RNA metabolism. RNA. 2024;30(5):583-94.
- Jiao L, et al. Emerging role of N-acetyltransferase 10 in diseases: RNA ac4C modification and beyond. Mol Biomed. 2025;6(1):46.
- Zheng N, et al. Regulatory roles of NAT10 in airway epithelial cell function and metabolism in pathological conditions. Cell Biol Toxicol. 2023;39(4):1237-56.
- Du J, et al. PTRF-IL33-ZBP1 signaling mediating macrophage necroptosis contributes to HDM-induced airway inflammation. Cell Death Dis. 2023;14(7):432.
- Lai K, et al. Uridine alleviates sepsis-induced acute lung injury by inhibiting ferroptosis of macrophage. Int J Mol Sci. 2023;24(6):5093.
- Kumari R, Jat P. Mechanisms of cellular senescence: cell cycle arrest and senescence associated secretory phenotype. Front Cell Dev Biol. 2021;9:645593.
- Ogrodnik M, Salmonowicz H, Jurk D, Passos JF. Expansion and cell-cycle arrest: common denominators of cellular senescence. Trends Biochem Sci. 2019;44(12):996-1008.
- Kumar M, Seeger W, Voswinckel R. Senescence-associated secretory phenotype and its possible role in chronic obstructive pulmonary disease. Am J Respir Cell Mol Biol. 2014;51(3):323-33.
- Pérez-Rubio G, et al. Role of genetic susceptibility in nicotine addiction and chronic obstructive pulmonary disease. Rev Invest Clin. 2019;71(1):36-54.
- Liu Y, Wang R, Jiang T. RNA-binding proteins as a molecular link between COPD and pulmonary hypertension. Int J Med Sci. 2025;22(8):1979-91.
- Marques TM, Gama-Carvalho M. Network approaches to study endogenous RNA competition and its impact on tissue-specific microRNA functions. Biomolecules. 2022;12(2):332.
- Wang J, Xia B, Ma R, Ye Q. Comprehensive analysis of a competing endogenous RNA co-expression network in chronic obstructive pulmonary disease. Int J Chron Obstruct Pulmon Dis. 2023;18:2417-29.
- Zhang J, et al. Construction of a ceRNA network and screening of potential biomarkers and molecular targets in male smokers with chronic obstructive pulmonary disease. Front Genet. 2024;15:1376721.
- Celikoğlu F, Celikoğlu SI. Intratumoural chemotherapy with 5-fluorouracil for palliation of bronchial cancer in patients with severe airway obstruction. J Pharm Pharmacol. 2003;55(10):1441-8.
- Chan AK, Choo BA, Glaholm J. Pulmonary toxicity with oxaliplatin and capecitabine/5-fluorouracil chemotherapy: a case report and review of the literature. Onkologie. 2011;34(8-9):443-6.