This study proposes a hybrid cost-forecasting model for power grids that combines physical cost quotas with dynamic macroeconomic/technological adjustments and XGBoost-based residual compensation. Achieving 2.34% MAPE, it balances accuracy and interpretability, addressing regulatory transparency needs in tariff setting.
A subscription to JoVE is required to view this content. Sign in or start your free trial.
Research Article
Retrospective Forecasting Using Provincial Grid Data and a Quota-Based Hybrid Physical-AI Model
In This Article
Summary
Abstract
The global energy transition and ongoing electricity market reforms require power grid enterprises to balance reliable power supply with increasingly stringent transmission and distribution tariff regulations. Traditional budgeting methods based on historical extrapolation often fail to reflect the physical basis of asset operations, whereas data-driven machine learning models achieve high predictive accuracy but lack the transparency required for regulatory cost verification. To address the trade-off between forecasting accuracy and interpretability, this study proposes a hybrid cost-forecasting model based on cost quotas. The framework uses standardized operating quotas as the physical budgeting baseline and incorporates a dynamic mechanism for quota evolution driven by macroeconomic conditions and technological progress. Extreme Gradient Boosting (XGBoost) is employed to capture nonlinear residuals beyond the quota-based estimates, while SHAP (Shapley Additive exPlanations) is used to interpret the contribution of key cost drivers. The model was evaluated using 16 years of anonymized operational data from a provincial power grid in China. It achieved a mean absolute percentage error (MAPE) of 2.34%, reducing forecasting errors by 61.8%, 46.6%, and 34.1% compared with SARIMAX, standalone XGBoost, and Attention-LSTM models, respectively. The proposed framework integrates engineering cost-quota principles with explainable artificial intelligence, providing both accurate long-term cost forecasts and a transparent decision-support tool for regulatory permitted-cost verification.
Introduction
The global energy transition is reshaping power grid asset management and operational practices through the integration of distributed renewable generation, increasing extreme weather events, and widespread deployment of IoT technologies, all of which demand greater operational flexibility and maintenance resources to ensure system reliability1,2. At the same time, electricity regulators have strengthened transmission and distribution tariff oversight through frameworks such as the UK's RIIO and the US Federal Energy Regulatory Commission's rate-of-return reviews, emphasizing transparency in cost justification3. China has similarly adopted a "permitted cost plus reasonable return" regulatory mechanism, requiring utilities to demonstrate clear links between engineering activities and financial expenditures4. However, utilities often lack transparent quantitative tools that connect physical asset operations with cost forecasts, limiting the effectiveness of regulatory cost verification5.
Existing forecasting approaches have important limitations in this environment6. Traditional methods, including incremental budgeting and ARIMA-based models, assume relatively stable historical patterns and often perform poorly under structural changes caused by economic fluctuations or extreme weather7. Conversely, modern machine learning models such as LSTM and Transformer architectures provide high predictive accuracy for short-term forecasting but lack the engineering interpretability required for regulatory decision-making8,9. Although recent hybrid forecasting approaches combine statistical and machine learning techniques, they generally overlook the standardized engineering cost quotas that underpin power grid accounting systems10. To address these limitations, this study proposes a quota-driven hybrid forecasting framework that combines dynamic quota evolution with machine-learning-based residual correction, preserving engineering interpretability while improving forecasting accuracy.
One major research direction stems from incentive regulation in natural-monopoly industries, including the UK's RPI-X mechanism and China's permitted-cost verification framework11. These studies primarily evaluate operational efficiency using Data Envelopment Analysis (DEA) and Stochastic Frontier Analysis (SFA)12. Previous research has examined long-term relationships between capital expenditure (CAPEX), operating expenditure (OPEX), and cost efficiency to support tariff regulation13,14. While these approaches provide valuable macroeconomic insights, their outputs are typically expressed as relative efficiency scores rather than monetary forecasts suitable for annual budgeting15,16. Furthermore, frontier models generally assume relatively stable physical asset structures and operating conditions, limiting their ability to capture abrupt cost changes driven by asset aging, infrastructure replacement, or rapid demand growth17,18.
A second research direction focuses on statistical and artificial intelligence-based forecasting models. Early studies employed multiple linear regression and autoregressive integrated moving average models with exogenous variables (ARIMAX) for cost prediction19. More recently, support vector regression, random forests, XGBoost, LSTM, and Transformer models have substantially improved forecasting performance by exploiting nonlinear relationships and high-dimensional feature spaces20,21,22. These approaches frequently incorporate macroeconomic indicators such as electricity demand, producer price indices (PPI), and climate variables23. However, power grid operating costs arise from engineering activities, asset deterioration, maintenance scheduling, and management decisions rather than macroeconomic variables alone24. Consequently, purely data-driven models often function as "black boxes," making it difficult to explain forecasted costs during regulatory reviews or permitted-cost verification25,26.
Engineering cost quota management provides a potential solution to this challenge27. Activity-based costing (ABC) has long relied on standardized operational quotas to estimate labor, material, equipment, and maintenance requirements for routine grid operations28. Major Chinese utilities have developed comprehensive quota databases covering inspection, maintenance, testing, repair, and equipment replacement activities. Nevertheless, these engineering standards are primarily used for project settlement and auditing rather than dynamic long-term forecasting29,30. Moreover, quota standards are typically revised only every several years, making them insufficiently responsive to changing commodity prices, technological progress, and operational practices31. Applying quota systems across millions of distributed assets also poses substantial computational challenges for large-scale forecasting32.
Despite significant advances in statistical forecasting, machine learning, and engineering cost management, no existing framework effectively integrates standardized engineering cost quotas, dynamic macroeconomic adjustment, and explainable machine learning into a unified forecasting model for regulatory cost verification. It was hypothesized that combining dynamically evolving cost quotas with XGBoost-based residual learning can improve long-term forecasting accuracy while preserving the engineering transparency required for regulatory decision-making. To test this hypothesis, a hybrid quota-driven forecasting framework was developed that integrates physical cost modeling, macroeconomic and technological adjustment mechanisms, XGBoost residual compensation, and SHAP-based model interpretation. The proposed approach aims to provide both accurate long-term cost forecasts and transparent evidence to support permitted-cost verification under modern electricity market regulation.
Access restricted. Please log in or start a trial to view this content.
Protocol
This study used anonymized operational and financial data collected from a provincial power grid in eastern China. All data were aggregated and de-identified before analysis, and no personally identifiable or sensitive individual-level information was included. Therefore, ethical approval was not required. Data access and analysis complied with applicable data protection regulations and institutional agreements governing power sector information.
Forecasting framework overview
To integrate physics-based and data-driven forecasting approaches, a hybrid forecasting framework was developed that combines engineering cost quotas with machine learning. Rather than simply combining multiple algorithms, the framework follows the principle that physical models establish the baseline forecast, whereas machine learning compensates for residual errors. This design ensures that the forecasting process is grounded in the physical mechanisms underlying power grid production and operation activities rather than relying solely on historical cost extrapolation.
The framework first establishes a hierarchical mapping between power grid assets, standardized operating activities, and financial cost accounts. Production and operation costs are treated as monetary representations of the resources consumed by physical assets—including substations, transmission lines, distribution feeders, metering devices, and digital inspection equipment—during routine activities such as inspection, maintenance, testing, repair, and replacement. Cost quotas serve as the link between measurable engineering workloads and corresponding financial expenditures.
As illustrated in Figure 1, cost quotas function as standardized accounting units embedded throughout the asset operation and maintenance process rather than as abstract financial allocation rules. Bottom-level asset workloads are converted into standardized operating quotas and subsequently mapped to cost categories, including labor, materials, construction equipment, outsourced services, and emergency supplies. This hierarchical mapping preserves engineering interpretability and regulatory traceability throughout the forecasting process and provides the physical foundation for constructing the static baseline quota model.
Methodological workflow overview
The proposed forecasting framework consists of three sequential stages: (1) construction of a physical baseline using asset-level workload quotas, (2) dynamic evolution of cost quotas through macroeconomic and technological adjustments, and (3) machine-learning-based residual compensation to capture systematic nonlinear effects. As illustrated in Figure 1, the framework establishes a hierarchical mapping from bottom-level assets and standardized operational activities to production and operation cost forecasts. The implementation details of each stage are described in the following subsections.
Physical baseline cost model based on asset-level workloads
The production and operation cost of a power grid, Ctotal, comprises expenditures associated with multiple business activities, including substation operation, transmission line maintenance, distribution network management, customer service, and supporting systems. In this study, the baseline operating cost is assumed to be determined by the workload generated by each standardized operational activity and its corresponding cost quota.
The static baseline cost is calculated as:
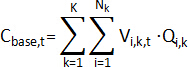 (1)
where Vi,k,t denotes the workload associated with the i-th asset or operational task within business category k during period t, and Qi,k represents the corresponding standardized unit cost defined by the engineering cost quota system. Business category includes major operational functions such as substation maintenance, transmission line inspection, distribution network operation, and customer service. The double summation aggregates the costs of all standardized operational activities to estimate the theoretical baseline expenditure required to maintain normal grid operation.
Equation (1) establishes the physical relationship between engineering workloads and financial expenditures by mapping standardized operational activities directly to cost accounts. Unlike purely statistical forecasting models, this formulation provides an interpretable engineering baseline that serves as the foundation for subsequent dynamic quota adjustment and machine-learning-based residual correction. The equation was developed from the operational practices and cost quota system used by provincial power grid enterprises in China. Table 1 summarizes the notation used in Equation (1), including workload (Vi,k,t), standardized unit cost (Qi,k), the number of operational tasks (Nk), and the business category index (k).
Dynamic evolution mechanism of quotas under external environmental disturbances
Standardized cost quotas (Qi,k) provide a physically interpretable baseline but do not account for changes in macroeconomic conditions or technological progress. To improve their long-term applicability, a dynamic evolution mechanism was introduced to adjust the baseline quotas in response to both price inflation and technology-driven efficiency gains.
The first adjustment accounts for changes in procurement costs resulting from macroeconomic inflation. Power grid operation and maintenance depend heavily on bulk materials, including copper, aluminum, and silicon steel, whose prices are closely related to fluctuations in the Producer Price Index (PPI). Because  is an index with a base value of 100, it is first converted into a standardized inflation rate:
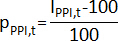 (2)
On this basis, the price correction function  is defined as:
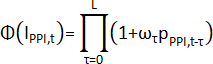 (3)
where  is a lag-weight vector of length L satisfying
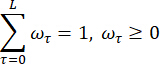
The lag structure represents the delayed transmission of macroeconomic inflation to procurement costs within the power grid supply chain. Converting the PPI index into a standardized inflation rate preserves the cumulative effect of price changes while avoiding scaling bias associated with direct use of index values. Equations (2) and (3) are adapted from established macroeconomic inflation adjustment models, with the lag structure calibrated for power-sector procurement cycles33,34.
Technological progress was incorporated through a cost-reduction factor that reflected improvements in operational efficiency resulting from advances such as unmanned aerial vehicle inspection, intelligent robotics, and digital maintenance technologies. The technology adjustment factor is defined as:
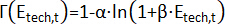 (4)
In this part, α and β are empirical elasticity coefficients estimated from historical panel data using nonlinear least squares. To ensure that the technological progress factor always represents a reasonable reduction in unit quota cost, the parameter estimation process constrains 0 < Γ(Etech,t) ≤ 1. It should be noted that this factor primarily reflects the long-term efficiency improvement resulting from the substitution of mature technology. Equation (4) is original to this work, adapting the learning-curve concept from energy technology cost literature35,36, to grid maintenance operations. Additional costs that may arise during the early stage of digital equipment deployment, such as parallel operation of old and new systems, platform integration, communication testing, and extra maintenance, are not forcibly deducted from the baseline quota; instead, they are identified by the subsequent machine learning residual compensation module:
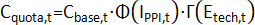 (5)
where Cbase,t denotes the static baseline cost calculated from bottom-level asset workloads and standardized operating cost quotas; captures the transmission effect of macro price fluctuations on materials, equipment, and external service prices; and Γ(Etech,t) reflects the efficiency-based reduction in unit operation and maintenance costs after technology maturity. Through the above dynamic evolution mechanism, the quota baseline no longer remains at a static accounting basis but can adaptively adjust with changes in economic environments and technological conditions. Equation (5) is original to this work and represents the novel integration of price and technology corrections into the quota baseline framework.
Systematic nonlinear residual capture under quota constraints
Despite complex evolutionary corrections, the quota model inevitably generates systematic deviations when facing unpredictable disaster-related weather disruptions and sudden policy directives, such as increased customer service complaint-handling costs during temporary tariff-reduction periods. This deviation forms the residual term on both sides of the equation:
Rt=Cactual,t-Cquota,t (6)
Since conventional physical rules cannot explain this aspect, machine learning can address these limitations. To avoid the curse of dimensionality caused by high-dimensional features, this study uses the XGBoost algorithm based on decision-tree ensembles to model the nonlinear relationship Rt37,38. A strong-disturbance feature matrix Xt, including meteorological features such as annual extreme freezing days Dice and macro policy intensity is defined.
For a nonlinear compensator composed of regression trees, the generation logic of the predicted residual  can be expressed as39:
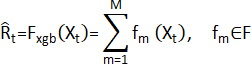 (7)
where F denotes the space of all possible classification and regression tree structures. To balance fitting accuracy and overfitting prevention, a regularized objective function containing a structural complexity penalty term is constructed and minimized in the m-th iteration:
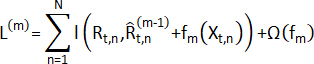 (8)
where  is a convex loss function measuring the difference between the true residual and the predicted residual. This paper adopts Huber Loss to enhance the model's robustness to abnormal peak expenditures. The regularization term
 is used to constrain the complexity of the tree structure and is defined as:
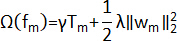 (9)
where Tm represents the number of leaf nodes in the m-th tree, wm represents the corresponding leaf weight vector, and γ and λ denote the leaf-node number penalty coefficient and the weight regularization coefficient, respectively.
The final forecasting equation is:
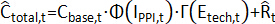 (10)
Further expanded as:
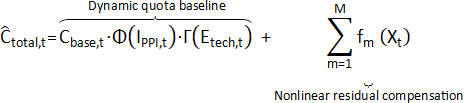 (11)
The formula above mathematically represents the closed-loop structure of the proposed forecasting model. The final production and operation cost demand is not directly generated by the machine learning model; instead, it is obtained by superimposing the nonlinear residual compensation identified by the machine learning module onto the dynamic quota baseline. Among these components, price and technology factors primarily reflect the dynamic evolution of the quota baseline, while factors that are difficult to explicitly characterize through rules, such as climate shocks, policy disturbances, and surges in repair events, are captured by the machine-learning residual compensation module. Equations (10) and (11) are original to this work and synthesize the physical baseline with ML-based residual capture into a unified forecasting framework.
Figure 2 shows that the proposed model's forecasting results exhibit a clear hierarchical generation logic. On the one hand, the baseline quota provides a stable, transparent, and auditable physical foundation for cost demand; on the other hand, price adjustments, technology effects, and external shock residuals enable the model to adapt to dynamic changes under complex environments. Compared with black-box models that directly output predicted values, this decomposition structure can clearly reveal "why costs rise or fall," thereby enhancing the interpretability of model results in budget review and transmission and distribution tariff regulation.
Data sources and collection procedures
Theoretical models must be rigorously validated through empirical data to demonstrate their practical utility. Since the core financial data of the power sector involves sensitive information related to national infrastructure operations, this study extracts high-precision, anonymized monthly accounting data from a typical provincial power grid in eastern China, referred to as E-Grid for convenience, covering 16 consecutive calendar years from 2010 to 2025. This province has experienced a typical economic cycle of shifting from traditional heavy-industry-driven growth to high-end manufacturing, with the compound annual growth rate of grid asset scale reaching 7.4%. The complex evolution of its cost structure, therefore, has potential relevance to other rapidly developing grid systems. The data originate from three primary sources: (1) internal operation and maintenance logs recording asset-level workloads, inspection frequencies, and repair events; (2) financial accounting systems providing monthly cost statements across labor, materials, equipment, and outsourced services; and (3) external environmental databases including meteorological records from the China Meteorological Administration and macroeconomic indicators from the National Bureau of Statistics.
Quality control and missing data treatment
For over 130 initial indicators integrated from multi-source systems, a rigorous quality control procedure was implemented. Missing data points, accounting for less than 3% of the total observations, were handled using linear interpolation for continuous variables with temporal trends, and mode imputation for categorical indicators. Outliers were identified using the interquartile range (IQR) method, with values exceeding 3.0 times the IQR above the third quartile winsorized to the 99th percentile to preserve data integrity and mitigate extreme-value distortion.
Sample size considerations
The dataset comprises 192 monthly observations (January 2010–December 2025), with 156 observations (2010–2022) allocated for training and validation and 36 observations (2023–2025) reserved for out-of-sample testing. While this sample size is relatively modest for deep learning applications, it is appropriate for the XGBoost algorithm, which is specifically designed to perform well with small-to-medium tabular datasets through its regularization and tree-pruning mechanisms. To mitigate potential overfitting risks, (1) strict regularization penalties were employed (γ = 0.1, λ = 1.0), (2) early stopping with a patience of 50 rounds, and (3) conservative tree depth constraints (max depth = 5). These measures collectively ensure model stability and generalization despite the limited sample size.
Data segmentation and multi-source heterogeneous integration
For rigorous testing, the data from January 2010 through December 2022 were assigned to the training-validation interval, containing 156 observations, which is used to train the quota evolution factors and the quota compensation residual network. January 2023–December 2025 is reserved as the held-out out-of-sample test set, containing 36 observations. Why is this period selected as the final testing arena? The reason is that these three years coincided with the acceleration of new-type power system construction, compounded by large-scale extreme El Niño-related high-temperature events and the rapid and uneven growth of distributed renewable generation. The power grid faced unprecedented pressure in material supply chains and repair labor allocation.
Scientific selection and quantitative definition of cost-driving factors are the foundation for ensuring that the machine learning residual network can effectively capture systematic fluctuations. Based on the management logic of standard operation costs in power systems, this study breaks through the single dimension of traditional financial forecasting, which relies only on historical cash flows, and instead reconstructs feature engineering from four core boundaries: physical asset scale, operation and maintenance conditions, macroeconomic evolution, and external climate environment, using original operation logs and external system ledgers. In the actual modeling process, for more than 130 original indicators resulting from multi-source system integration, this study uses Pearson correlation tests to eliminate highly collinear redundant variables, with a threshold of |r| > 0.85. Based on the prior knowledge of senior power grid experts, 42 core input features are ultimately selected to form the feature matrix Xt. To clearly present the underlying data structure and distribution of the input tensor, Table 2 selects 12 representative core features from the four evaluation dimensions above and summarizes their descriptive statistics over the observation period.
To further illustrate the spatial-topological basis of the multi-source feature system, Figure 3 presents an anonymized schematic topology of the provincial power grid under study. The figure overlays voltage-level substations, transmission corridors, distributed renewable clusters, load centers, and representative environmental disturbance zones. The topology helps explain why production and operation costs are jointly affected by asset scale, network structure, emergency repair intensity, and external climate shocks. It also provides a spatial interpretation basis for the residual-driving variables used in the XGBoost compensation module.
Table 2 shows that explanatory variables across different business dimensions exhibit distinctly different statistical forms. Physical asset variables representing endogenous enterprise development dynamics, such as substation capacity and line length, have relatively stable standard deviations and skewness values concentrated between 0.1 and 0.8. Their overall data structure is approximately normally distributed, objectively reflecting the attribute of steady power grid development in the infrastructure construction cycle. In sharp contrast are the meteorological and external environmental disturbance variables at the bottom of the table. For example, the cumulative number of warning-level high-temperature days over the past 90 days and the line trip impact index exhibit extremely strong right-skewedness, with skewness values of 2.15 and 2.45, respectively. This typical heavy-tailed distribution confirms an objective pain point that cannot be ignored in actual power grid operation and maintenance: although extreme weather disasters occur relatively infrequently over the annual timeline, once triggered, they often cause exponential increases in repair labor input and spare-parts consumption. From another perspective, the high non-uniformity and extreme-value skewness in the distribution of these multi-source features reveal the theoretical limitations of traditional linear time-series models, such as ARIMAX, which are based on the assumptions of normality and homoscedasticity when tracing complex power grid costs. This not only further establishes the rationality of introducing a machine learning module beyond the physical accounting baseline but also provides solid statistical support for this paper's selection of the XGBoost tree model, which can efficiently handle sparse feature distributions and nonlinear mappings to approximate cost residuals.
Hyperparameter optimization and evaluation system setup
After determining the feature input space, the setting of model hyperparameters directly affects the fitting performance of the residual approximation network. Since the XGBoost compensation network involves multiple parameters, including tree depth (max depth), learning rate, and regularization penalty terms, and these parameters have nonlinear interactions, conventional grid search not only has high computational complexity but also tends to become trapped in local minima in high-dimensional spaces. Therefore, this study introduces the Tree-structured Parzen Estimator (TPE), a Bayesian optimization method, in the parameter tuning process. The TPE algorithm can dynamically guide subsequent sampling directions using loss-function feedback from previous evaluations. By constructing a posterior kernel density estimate (KDE) of the objective variable, it adaptively narrows the parameter search space, allowing the model to approximate the global optimal hyperparameter configuration without incurring high computational cost. The TPE optimization objective was to minimize validation RMSE over 100 iterations, with early stopping after 50 rounds without improvement.
After completing parameter optimization on the internal validation set, to objectively evaluate the final performance of each model on the out-of-sample test set and to meet regulators' quantitative assessment requirements for cost verification, this study uses the mean absolute percentage error (MAPE) to quantify the relative deviation in the predicted sequence. Meanwhile, to address the practical need to control extreme cost prediction failures in operations, root mean square error (RMSE) is also introduced to impose stronger penalties on larger errors. Finally, the coefficient of determination, R2, quantifies the regression's overall explanatory power relative to the true target variance.
The mathematical definitions of the indicators are as follows:
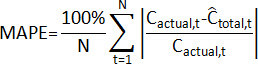 (12)
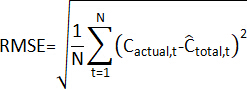 (13)
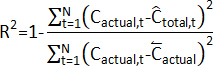 (14)
where  represents the actual production and operation cost in the period t,
 represents the model-predicted cost,
 represents the mean actual cost in the test sample, and N is the number of samples in the test set.
Access restricted. Please log in or start a trial to view this content.
Results
Panoramic dimensionality-reduced comparison of forecasting accuracy
When all Tree-structured Parzen Estimator (TPE)-optimized models were evaluated on the 2023–2025 out-of-sample test set, which included post-pandemic recovery fluctuations and extreme high-temperature events, the performance of mainstream forecasting algorithms could be objectively compared. To provide a rigorous and comprehensive evaluation, four benchmark models representing different methodological approach...
Access restricted. Please log in or start a trial to view this content.
Discussion
This study demonstrates that integrating industrial cost quotas with machine learning provides an interpretable and accurate framework for long-term power grid cost forecasting. The results show that climate-related variables, particularly extreme high-temperature days and line trip impact indices, are the dominant drivers of cost residuals, highlighting the increasing influence of external disturbances on utility expenditures. These findings suggest that weather-related costs should no longer be treated as incidental op...
Access restricted. Please log in or start a trial to view this content.
Disclosures
All authors declare no conflicts of interest.
AUTHOR CONTRIBUTION:
Xiaohui Wang conceived and designed the study, developed the methodology, performed the formal analysis, and drafted the original manuscript. Tong Li contributed to data curation, software implementation, and validation. Yanchao Lu contributed to the development of the methodology, investigation, and data interpretation. Quanfeng Lv provided resources, supervised data acquisition, and critically reviewed the manuscript. Fan Liu supervised the project, contributed to the conceptualization and interpretation of the results, secured funding, and critically revised the manuscript. All authors reviewed and approved the final version of the manuscript
Acknowledgements
This work was supported by the Technology Project of State Grid Corporation of China, with the name of "Research on Production and Operation Cost Allocation Analysis and Asynchronous Optimization Technology" (Project number:520600250029-183-ZN).
Access restricted. Please log in or start a trial to view this content.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| E-Grid anonymized monthly accounting dataset | Provincial power grid in eastern China | N/A | Anonymized monthly production and operation cost dataset (2010–2025) comprising 192 observations, including physical asset, operation and maintenance, macroeconomic, and environmental data. Used for model development (156 observations) and out-of-sample testing (36 observations). |
| Matplotlib plotting library | Matplotlib development team | 3.5.2 | Used to generate manuscript figures and graphical outputs, including model-performance plots, topology visualizations, residual diagnostics, radar charts, and SHAP-related visual summaries. |
| NumPy numerical computing library | NumPy developers | 1.22.3 | Used for numerical array operations, matrix calculations, and reproducibility control. A fixed random seed of 42 was applied where relevant. |
| Pandas data manipulation library | pandas development team | 1.4.2 | Used for data import, integration, restructuring, filtering, and preprocessing, including missing-value imputation, time-series alignment, and preparation of model input variables. |
| Python programming environment | Python Software Foundation | 3.9.13 | Programming environment used to implement the complete forecasting workflow, including data preprocessing, feature engineering, model training, hyperparameter optimization, prediction, statistical testing, and performance evaluation. |
| Scikit-learn machine learning library | scikit-learn contributors | 1.0.2 | Used for data preprocessing, training-validation splitting, auxiliary model evaluation, and statistical procedures, including Pearson correlation analysis and calculation of selected performance metrics. |
| SciPy scientific computing library | SciPy contributors | 1.9.0 | Used for statistical calculations, including Pearson correlation analysis and supporting procedures for outlier treatment and winsorization. |
| Tree-structured Parzen Estimator implementation | Optuna contributors | 3.1.0 | Bayesian optimization implementation used to tune XGBoost hyperparameters, including maximum tree depth, learning rate, and regularization parameters. The Tree-structured Parzen Estimator was implemented through the open-source Optuna package. |
| XGBoost software library | DMLC / XGBoost contributors | 1.7.1 | Decision-tree-based ensemble learning library used for nonlinear residual compensation. The model implemented a regularized objective function with Huber loss and tree-complexity penalties, as described in Equations 7–9. |
References
- Rao H, Li J, Sun X. Demand forecasting and allocation optimization of green power grid supply chain based on machine learning algorithm: A study based on the whole-process data of power grid materials. Sustainability. 2025;17(3):1247.
- Huang C, et al. Demand response for industrial micro-grid considering photovoltaic power uncertainty and battery operational cost. IEEE Trans Smart Grid. 2021;12(4):3043-3055.
- Phuangpornpitak N, Prommee W. A study of load demand forecasting models in electric power system operation and planning. GMSARN Int J. 2016;10:19-24.
- Nasir J, et al. A hybrid LMD–ARIMA–machine learning framework for enhanced forecasting of financial time series: Evidence from the NASDAQ Composite Index. Mathematics. 2025;13(15):2389.
- Matos C, et al. Model for integrating the electricity cost consumption and power demand into aggregate production planning. Appl Sci. 2022;12(15):7577.
- Valenzuela J, Mazumdar M, Kapoor A. Influence of temperature and load forecast uncertainty on estimates of power generation production costs. IEEE Trans Power Syst. 2000;15(2):668-674.
- Khan F, et al. A hybrid vector autoregressive model for accurate macroeconomic forecasting: An application to the US economy. Mathematics. 2025;13(11):1706.
- Fatema I, Kong X, Fang G. Electricity demand and price forecasting model for sustainable smart grid using comprehensive long short-term memory. Int J Sustain Eng. 2021;14(6):1714-1732.
- Singh AK, Ibraheem SK, Muazzam M, Chaturvedi DK. An overview of electricity demand forecasting techniques. Netw Complex Syst. 2013;3(3):38-48.
- Iftikhar H, et al. A novel hybrid framework for forecasting stock indices based on nonlinear time series models. Comput Stat. 2025;40(8):4163-4186.
- Jiang P, Li R, Lu H, Zhang X. Modeling of electricity demand forecast for power system. Neural Comput Appl. 2020;32(11):6857-6875.
- Chan SC, et al. Load/price forecasting and managing demand response for smart grids: Methodologies and challenges. IEEE Signal Process Mag. 2012;29(5):68-85.
- Hernandez L, et al. A survey on electric power demand forecasting: Future trends in smart grids, microgrids and smart buildings. IEEE Commun Surv Tutor. 2014;16(3):1460-1495.
- Zareipour H, Canizares CA, Bhattacharya K. Economic impact of electricity market price forecasting errors: A demand-side analysis. IEEE Trans Power Syst. 2009;25(1):254-262.
- Botterud A. Forecasting renewable energy for grid operations. In: Renewable Energy Integration. Academic Press; 2017:133-143.
- Mirowski P, Chen S, Ho TK, Yu CN. Demand forecasting in smart grids. Bell Labs Tech J. 2014;18(4):135-158.
- Sobu A, Wu G. Optimal operation planning method for isolated micro grid considering uncertainties of renewable power generations and load demand. In: IEEE PES Innovative Smart Grid Technologies [conference proceedings]. IEEE; 2012. Available at: https://ieeexplore.ieee.org/
- Han B, et al. Optimal design of an on-grid microgrid considering long-term load demand forecasting: A case study. Distrib Gener Altern Energy J. 2020;35:345-362.
- Tripathy SC. Demand forecasting in a power system. Energy Convers Manag. 1997;38(14):1475-1481.
- Adshead NS, Price DH. Demand forecasting and cost performance in a model of a real manufacturing unit. Int J Prod Res. 1987;25(9):1251-1265.
- Gellert A, et al. A study on forecasting electricity production and consumption in smart cities and factories. Int J Inf Manage. 2019;49:546-556.
- Hernández L, et al. A multi-agent system architecture for smart grid management and forecasting of energy demand in virtual power plants. IEEE Commun Mag. 2013;51(1):106-113.
- Klingler AL, Teichtmann L. Impacts of a forecast-based operation strategy for grid-connected PV storage systems on profitability and the energy system. Sol Energy. 2017;158:861-868.
- Ghalehkhondabi I, Ardjmand E, Weckman GR, Young WA. An overview of energy demand forecasting methods published in 2005–2015. Energy Syst. 2017;8(2):411-447.
- Aderibigbe AO, et al. Enhancing energy efficiency with AI: A review of machine learning models in electricity demand forecasting. Eng Sci Technol J. 2023;4(6):341-356.
- Arumugham V, et al. An artificial-intelligence-based renewable energy prediction program for demand-side management in smart grids. Sustainability. 2023;15(6):5453.
- Dudek G, Piotrowski P, Baczyński D. Intelligent forecasting and optimization in electrical power systems: Advances in models and applications. Energies. 2023;16(7):3024.
- Liu N, et al. A hybrid forecasting model with parameter optimization for short-term load forecasting of micro-grids. Appl Energy. 2014;129:336-345.
- Mohammad AA, et al. Mathematical and statistical modelling of electricity demand forecasting using artificial neural networks and SARIMA: Implications for energy supply chain planning. Alex Eng J. 2026;139:98-108.
- Singh AR, et al. A blockchain-enabled multi-agent deep reinforcement learning framework for real-time demand response in renewable energy grids. Energy Strateg Rev. 2025;62:101905.
- Lu R, et al. Data-driven real-time price-based demand response for industrial facilities energy management. Appl Energy. 2021;283:116291.
- Kondaiah VY, Saravanan B, Sanjeevikumar P, Khan B. A review on short-term load forecasting models for micro-grid application. J Eng. 2022;2022(7):665-689.
- Lee BL, Wilson C, Simshauser P, Majiwa E. Deregulation, efficiency and policy determination: An analysis of Australia's electricity distribution sector. Energy Econ. 2021;98:105210.
- Wang Y, et al. Transmission network expansion planning considering wind power and load uncertainties based on multi-agent DDQN. Energies. 2021;14(19):6073.
- Ding Q, Zhao H. Study on e-commerce logistics cost control methods in the context of COVID-19 prevention and control. Soft Comput. 2021;25(18):11955-11963.
- Duan Y, Xu Z, Chen H, Wang Y. Novel machine learning approach for enhanced smart grid power use and price prediction using advanced Shark Smell-tuned flexible support vector machine. Sci Rep. 2025;15(1):20909.
- Chen T, Guestrin C. XGBoost: A scalable tree boosting system. In: Proceedings of the 22nd ACM SIGKDD International Conference on Knowledge Discovery and Data Mining [conference proceedings]. San Francisco, CA, USA; 2016. Available at: https://doi.org/10.1145/2939672.2939785
- Lin KY, et al. Predictive maintenance in industrial systems: An XGBoost-based approach for failure time estimation and resource optimization. J Ind Prod Eng. 2025;42(8):876-899.
- Ajayi OO, Kurien AM, Djouani K, Dieng L. A proactive predictive model for machine failure forecasting. Machines. 2025;13(8):663.
- Lundberg SM, et al. From local explanations to global understanding with explainable AI for trees. Nat Mach Intell. 2020;2(1):56-67.
- Chen H, Gao T, Wang L, Guo P. Explainable machine learning methods for predicting electricity consumption in a long-distance crude oil pipeline. Sci Rep. 2025;15(1):43305.
- Neubauer A, Brandt S, Kriegel M. Explainable multi-step heating load forecasting: Using SHAP values and temporal attention mechanisms for enhanced interpretability. Energy AI. 2025;20:100480.
- Ahmad T, Chen H. Potential of three variant machine-learning models for forecasting district-level medium-term and long-term energy demand in smart grid environment. Energy. 2018;160:1008-1020.
- Masa-Bote D, et al. Improving photovoltaics grid integration through short-time forecasting and self-consumption. Appl Energy. 2014;125:103-113.
Access restricted. Please log in or start a trial to view this content.