This paper studies a dynamic scheduling optimization algorithm that integrates Transformer and PPO reinforcement learning, focusing on frequent resource conflicts and response delays in scheduling union activities.
Research Article
Dynamic Scheduling and Resource Optimization Algorithm for Union Activities by Integrating Transformer and Reinforcement Learning
In This Article
Summary
Abstract
To address the problem of reduced organizational efficiency caused by frequent resource allocation conflicts and delayed scheduling responses in managing trade union activities, this paper proposes a dynamic scheduling algorithm that integrates Transformer and PPO (Proximal Policy Optimization). In the specific implementation, a unified scheduling scenario modeling structure is first designed to convert activity, personnel, and resource states into tensor inputs, thereby achieving multidimensional constraint integration. Next, the Transformer multi-head attention mechanism is used to encode the time series of historical activity requests and resource status, extract multi-dimensional spatiotemporal features, and enhance the perception of conflict risks. Subsequently, based on the encoding results and the PPO strategy network, scheduling actions are generated from the current state to enhance the strategy's adaptability to complex environments. Finally, through the pruning update and the advantage function correction mechanism, the strategy's stability during iteration and improved scheduling performance are guaranteed. Experiments have shown that when the task density is 1000, the scheduling algorithm's average decision time is 0.72s and its average response delay is 1.59s, indicating high response speed and decision-making efficiency. Across seven activity types and complexity levels, the resource conflict rate is 0.05–0.12; the average resource utilization rate is 0.75–0.86; and the scheduling stability index is 0.8–0.91, effectively reducing frequent resource allocation conflicts and achieving high scheduling stability. Under high-concurrency conditions, the resource balance index and the strategy transfer robustness index are 0.88 and 0.85, respectively, indicating good adaptability to task concurrency loads.
Introduction
Union activities involve the complex scheduling of multiple tasks and resources, requiring the system to have efficient dynamic response capabilities1,2. Activity requirements change frequently, and the distribution of personnel and venue resources is complex, which can easily lead to scheduling conflicts and waste of resources3,4. Accurately capturing activity history and real-time resource status, as well as improving the ability to identify and respond to potential conflicts, are key to enhancing organizational operating efficiency5,6. The integration of advanced time series modeling technology and reinforcement learning algorithms can achieve a deep understanding of and intelligent optimization in complex scheduling environments, helping to maximize resource utilization, accelerate scheduling response, and promote the intelligent upgrade of union activity management.
However, existing scheduling approaches in practice are largely rule-based and static, failing to adapt to frequent task changes and resource fluctuations, which often results in prolonged response times and severe resource conflicts. In scheduling union activities, task types are highly diverse; resource usage is highly constrained, and frequently changes; and the dependencies between activities and the competitiveness among resources constitute a complex scheduling map7,8. In practice, the activity schedule cannot be efficiently matched to the available time windows of resources such as personnel and venues9,10, and conflicts often occur, weakening the overall coherence of organizational operations11,12. The scheduling system is not faced with a single optimization goal but rather a balance among multi-dimensional indicators, such as minimizing resource conflicts, maximizing response speed, scheduling strategy stability, and task completion rate13,14, which exhibit typical multi-objective optimization characteristics. In addition, trade union activities exhibit distinct phases and cycles, and scheduling strategies must dynamically adapt to the varying resource-demand structures across different task stages. Static plans generated once cannot support the execution environment with high-frequency changes15,16. The existing scheduling logic lacks in-depth exploration of historical task behavior and patterns of resource status changes. It is unable to provide accurate predictions and strategy deductions for the future17,18. The system's scheduling strategy responds slowly to sudden tasks and temporary changes in resources, affecting the overall sustainability of the operation19,20. Building a scheduling system with predictiveness, flexibility, and stability has become a key technical requirement in practical applications. It requires the model to have high-dimensional information perception, sequence memory, and strategy migration capabilities, and to maintain robust decision-making and resource balance in a multi-task environment, thereby enabling intelligent, optimal coordination of union activity scheduling.
Numerous studies have proposed various solutions to the dynamic scheduling problem. Among them, the combination of deep learning and reinforcement learning has shown strong adaptability and optimization capabilities. Some scholars use LSTM (Long Short-Term Memory)21,22 to model time series data and combine reinforcement learning strategies to optimize scheduling behavior, achieving certain results. Another type of research uses a heuristic method based on a greedy algorithm, emphasizing the simplicity and efficiency of scheduling decisions, which is suitable for scenarios with clear rules23,24. Other studies have explored the application of deep Q-network (DQN) to scheduling, achieving improved strategies through value function approximation25,26. However, these methods have problems such as insufficient capture of long-term dependencies, unstable strategy updates, and large response delays when facing complex and changing union activity scenarios, making it difficult to meet the scheduling needs of high-density and diverse tasks. Therefore, how to build a scheduling algorithm with efficient feature extraction and stable strategy update capabilities has become a bottleneck that needs to be broken through in current research.
In multi-domain scheduling research, the Transformer architecture has been applied to various time-series prediction and scheduling optimization tasks due to its multi-head self-attention mechanism, which effectively captures long-range temporal dependencies27,28. When combined with the PPO algorithm in reinforcement learning, the strategy is updated stably and efficiently by trimming the objective function, and this approach has shown good performance in fields such as robot control and intelligent manufacturing29,30,31. Some studies have attempted to integrate the Transformer with reinforcement learning for complex resource scheduling32. However, in the dynamic scheduling of union activities, few studies address the combination of diverse activity types and complex resource constraints. Some studies have utilized graph neural networks to model the relationship between resources and tasks, thereby improving the accuracy of conflict identification33,34. Some scholars have optimized resource scheduling based on edge computing to enhance the efficiency and performance of the model35,36. However, such methods still have limited modeling capabilities for temporal context. Based on this, this paper proposes using a Transformer to encode historical activity and resource state sequences, combined with the PPO policy network, to achieve a high perception of conflict risks and a stable update of scheduling strategies to cope with the changing and complex scheduling needs of union activities.
More recent studies have explored resource scheduling optimization from different perspectives, such as VM consolidation for energy efficiency in cloud computing37, authentication algorithms in cellular networks38, enhanced VM consolidation with live migration for sustainable cloud computing39, traffic optimization using waiting prediction and evolutive algorithms40, and blockchain-based cloud storage with enhanced optimization and integrity preservation41. While these works provide valuable insights into resource allocation and optimization algorithms, they primarily target cloud infrastructure, telecommunications, or storage systems, and do not specifically address the multi-type activity constraints, dynamic personnel-venue resource conflicts, and real-time scheduling requirements inherent in union activity management. This distinction further underscores the need for a dedicated scheduling framework tailored to the organizational context of union activities.
Existing scheduling methods for union activities often fail to capture long-term spatiotemporal dependencies and to maintain policy stability amid dynamic changes, leading to slow response times and high resource conflicts. To address these research gaps, this study proposes a scheduling optimization model based on the principle that Transformer multi-head attention can effectively encode historical sequences for conflict prediction, and that Proximal Policy Optimization (PPO) with a clipped objective ensures stable and adaptive policy updates. Specifically, Transformer is applied to encode activity and resource state sequences, extracting key spatiotemporal features to enhance conflict foresight, and PPO is combined for efficient scheduling action generation and stable updates. A unified constraint matrix is designed to map activities, personnel, and venues, improving the recognition of complex dependencies. The core innovations of this work include: (1) the integration of temporal encoding and reinforcement learning specifically for union activity scheduling; (2) a conflict-aware attention mechanism that prioritizes risk perception; and (3) a pruning update with advantage function correction to ensure strategy robustness under high concurrency. Extensive experiments under diverse task densities and complexities validate the model's superiority over existing methods in response speed, resource utilization, and stability, providing a practical and scalable intelligent scheduling solution for union activity management.
Protocol
Figure 1 shows the structure of a union activity scheduling system that integrates time series modeling and reinforcement learning. The input layer integrates activity schedules, resource availability, and personnel time-window information, and constructs a multi-dimensional task-and-resource conflict relationship matrix via the constraint graph module. The transformer performs multi-head attention encoding over the historical sequence of activity and resource states, producing hidden states with temporal dependencies. The policy module uses the encoding results to generate action distributions and state estimation, and executes scheduling decisions after sampling actions. The execution results are fed back to the environment, updating resource status and generating immediate rewards. On this basis, the optimization module constructs a clipping objective function, evaluates the advantage function, and corrects the value network's estimate to limit policy drift and ensure stable updates to scheduling behaviors. A closed data loop is formed among the modules to achieve a highly sensitive perception of resource conflicts and adaptive strategy updates in dynamic environments, thereby improving the intelligent response capability and resource allocation efficiency of the union activity scheduling system in multi-task and highly constrained scenarios.
Scenario modeling of union activity scheduling
All activity requests in the scheduling system are organized into discrete scheduling sequences based on time steps. Each activity is defined with clear start and end times, resource categories, stages, and priority levels. The site usage status is modeled as a two-dimensional time-slot matrix, where the horizontal axis represents the standardized time unit and the vertical axis represents the spatial resource number. The resource status is marked as available and occupied, forming an initial resource distribution map with a static structure. The personnel scheduling information is expanded in the time-identity dimension to construct a continuous time-window vector, each of which records the personnel's task-idle status and department number. All input information is integrated into a three-dimensional tensor structure, where denotes the discrete time step, denotes the number of resource entities, and denotes the corresponding resource usage attribute code (such as whether it is occupied, the activity number, the usage priority, etc.). This structure allows the scheduling system to read the resource configuration at any time, ensuring a unified representation of different resource status types.
After the task information is linked to the model, the task intensity vector is set based on the activity priority and the resource usage period. The task combination that may cause conflict is marked through the time window overlap detection method. Conflict combinations are converted into node sets, and edge sets are constructed based on shared resource types and periods to explicitly represent implicit dependencies. The final constructed task graph contains boundary information on time sequence, resource overlap, or constraint conflict, providing a structural basis for subsequent conflict detection and scheduling strategy generation. This structure retains the dynamic nature of task scheduling and the continuous changes in resource status, and supports real-time perception of changes in scheduling constraints.
Conflict detection uses the sparse overlapping regions of the time and resource dimensions in the tensor structure as the initial conditions for judgment. It implements static relationship encoding processing for task pairs with overlapping scheduling targets. It constructs a graph structure G=(V,E,C), where V represents the set of active nodes, E represents the edges generated based on resource conflicts, and C is the conflict-weight encoding matrix for the edges. The conflict weight function is defined in the following form:
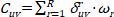 (1)
Among them, Cuv is the conflict weight between activities u and v; u, v are activity indices; R is the total number of resource types; δuvr ∈ {0,1} indicates whether the time windows of activities u and v overlap on the resource r; ωr is the conflict sensitivity weight of the resource r. This function performs a weighted sum of conflict intensities, accounting for differences in the importance of resource conflicts to the scheduling results, while retaining a quantifiable expression of the distribution of conflict strength.
The above conflict graph structure is converted into a constraint boundary matrix through sparse matrix representation. Each item in the matrix contains the degree of resource conflict. The matrix is embedded in the scheduling decision process to determine whether tasks can be scheduled in parallel, while the action-shielding logic is in the policy network. To cope with periodic activity aggregation and high-density task bursts, a dynamic update mechanism is implemented to monitor changes in task status and modify the matrix content in real time as resources are released or added, ensuring the continuity and consistency of the scheduling boundary throughout task evolution.
The application of this conflict graph structure enables the scheduling system to visually model potential resource bottlenecks and task overlap patterns, thereby improving the efficiency of the decision network's decoupling analysis of complex constraint scenarios. Scheduling behavior no longer relies on rule-based logical matching. Instead, it seeks the optimal path in the constraint space, enhancing the ability to dynamically balance local resource conflicts with the global task map. The system can maintain scheduling stability and task coherence in an environment where resources fluctuate, and tasks are frequently added or removed.
Figure 2 shows a network structure diagram based on the task conflict weight relationship. Each node in the figure represents a task to be scheduled, and the lines between nodes indicate resource usage conflicts. The thickness of the edge reflects the weight of the conflict. The more serious the conflict, the thicker the line. The weight calculation integrates resource overlap and combines the conflict sensitivity of various resources to form a composite conflict intensity between tasks. The graph structure reveals that some tasks form densely connected areas, indicating significant competition for resource utilization. This type of local conflict aggregation phenomenon is the primary source of resource bottlenecks and task delays in the scheduling process, and the scheduling algorithm can accordingly set priority mediation targets. The node arrangement employs a force-directed layout strategy to automatically aggregate high-conflict tasks, enabling the scheduling system to identify key task groups and optimize strategy distribution, thereby enhancing overall scheduling coherence and resource coordination.
Historical state sequence encoding
Based on the constructed conflict graph and constraint matrix, the next step is to encode the historical sequences of activities and resource states, so that the temporal patterns underlying these constraints can be extracted for subsequent decision-making. The core information in the scheduling scenario consists of activity requests, resource status changes, and task feedback records. This information constitutes multiple heterogeneous time series, corresponding to attributes such as event time points, resource usage identifiers, and activity execution status. To unify the processing structure, each input type is encoded as an equal-length vector sequence, and a unified time index is established to ensure state alignment under time synchronization. The input unit at each moment is represented by a concatenation of three sets of feature vectors: the activity feature vector represents the task type, priority and stage number; the resource feature vector records the current resource occupancy, remaining capacity and available window position; the feedback feature vector describes whether the task is executed smoothly at the previous moment, and whether a resource conflict or delay event occurred.
All features are linearly transformed and mapped to the same dimensional space to obtain a standardized embedding matrix X ∈ ℝT×d, where T represents the number of time steps and d is the unified embedding dimension. To preserve the temporal structure, the input matrix is added element by element to the position encoding matrix P to form the position-aware input:
Z = X + P (2)
Z is the final input sequence, which serves as the input of the subsequent attention mechanism. The position encoding design uses a fixed sine and cosine function template to prevent future information leakage and ensure causal constraints are strictly met during encoding. The above structure enables the model to perceive task characteristics, resource status, and time position simultaneously. It has a complete state memory foundation, providing a high-resolution, unified structure for the subsequent attention mechanism.
The attention module processes the input sequence to capture potential relationships among multiple time steps. Multiple groups of attention heads are used to process the sequence separately, enhancing the model's sensitivity to different types of state-evolution paths. Each attention head generates a query matrix Q, a key matrix K, and a value matrix V from the input sequence, calculates the weight distribution matrix, and generates a weighted representation. The output of a single-head attention is:
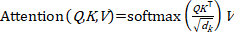 (3)
dk is the number of feature dimensions per head. In this formula, QK⊤ represents the similarity between moments, √dk is used for numerical stability, and the softmax function ensures weight normalization. Different attention heads focus on different combinations of time steps, and the dynamic dependencies they capture are also diverse, helping reveal implicit rules such as precursors to task conflicts, resource consumption patterns, and abnormal feedback trends.
All attention head outputs are concatenated and passed through a linear transformation layer to generate a unified coding sequence, which serves as the state input to the scheduling strategy generation network. This sequence embeds the task behavior trajectory, resource change characteristics, and the impact of previous execution deviations in the current scheduling window, effectively addressing the problem of high historical dependence in scheduling behavior and sparse feature expression. Residual connection and layer normalization modules are incorporated into the encoding output layer to enhance the training stability and expression retention capabilities of the deep network.
The output hidden state sequence not only retains time-evolution information but also responds to changes arising from sudden tasks or temporary resource mismatches, demonstrating strong adaptability. This structural design avoids explicit rule definition, enables structured modeling of dynamic scheduling environments, and supports subsequent policy modules in generating scheduling solutions with global consistency and local adaptability under multi-objective conditions.
Dynamic scheduling strategy generation
The encoded hidden state sequences, which embed both temporal dependencies and resource conflict information, are then fed into the policy network to generate scheduling actions that adapt to the current environment. The hidden-state sequence output by the encoding module is used as input to the scheduling strategy network. The state vector set at each moment constitutes the current environment observation expression, covering the evolution of task characteristics, resource usage trends, and historical feedback trajectories. The state representation dimension and time window length are fixed, and the continuity of state changes is captured via a sliding-update mechanism. Before the state vector is sent to the policy network, it is normalized and feature-reorganized to ensure that the input maintains a stable numerical distribution in the high-dimensional space, thereby reducing gradient explosion and convergence fluctuations.
The policy network structure employs a dual-branch output module, where one branch generates the action distribution and the other outputs the state-value function estimate. The action space comprises all schedulable tasks and allocatable resources. The candidate screening mechanism filters out illegal or redundant combinations of operations to form a limited, legal set of actions. The policy branch outputs a probability distribution π(at|st), where at represents the scheduling action at the time step, and st is the current state input. A standardized Gaussian sampling or softmax sampling strategy is used to select actions from the distribution for actual scheduling. The other output is the state-value function estimate, which represents the long-term reward expectation at the given state and is used for policy evaluation and update.
In the policy network, the hidden layer applies activation functions and batch normalization to improve nonlinear expressiveness and accelerate network convergence. In the decision-making process, the execution priority, resource scheduling cost, and historical performance of different tasks are considered attention factors and applied to the action selection mechanism via a specific weight matrix to form an adaptively adjustable policy-output framework. This design avoids relying on fixed rules, thereby enhancing the strategy's flexibility in handling sudden conflicts and structural bottlenecks.
The scheduling strategy uses a random sampling mechanism to generate the actual action sequence. In each scheduling cycle, an executable action is sampled from the current action distribution, and the resource status and task node mark are updated. After the action is executed, the system calculates the immediate feedback reward based on the resource changes and task progress results to measure the impact of this round of scheduling on the overall goal. The reward design considers multiple dimensions, including task completion rate, resource utilization efficiency, and the degree of conflict suppression. It provides feedback to the strategy update module through comprehensive indicators.
The entire scheduling process constructs a Markov decision chain and uses the empirical trajectory sampling method to record the state-action-reward sequence, denoted as (st, at, rt, st+1). Strategy optimization relies on the construction of the advantage function, where the advantage estimate is defined in the following form:
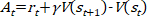 (4)
At represents the advantage value, rt is the current instant reward, γ is the reward discount factor, and V(st) and V(st+1) are the state value function outputs in the current and next states, respectively. The advantage function reflects the degree of superiority of the current action relative to the strategy's average performance. It is used to guide subsequent strategy improvement. If At > 0, it means that the current action is better than the average expectation, and its probability should be increased; otherwise, its selection tendency should be reduced.
During the strategy update process, to avoid strategy oscillations caused by excessive update amplitudes, a target distribution truncation mechanism is applied to limit the range of change between the new and old strategies, thereby maintaining the continuity and stability of the network output. A tight coupling is established between the action distribution and the feedback reward, allowing the strategy to respond immediately to changes in complex constraints. This mechanism maintains decision-making stability and rational resource scheduling in situations where tasks frequently change or resources suddenly mismatch, effectively avoiding problems such as duplicate allocation, resource congestion, or task queue backlogs. The scheduling system can maintain a better operating state across varying task densities and resource shortages, demonstrating strong adaptive capabilities.
Strategy iteration and stable update mechanism
To ensure that the generated scheduling strategies remain stable and do not degrade over repeated training rounds, an iterative update mechanism with clipping and advantage correction is introduced in this subsection. The truncation update interval between the old and new strategies is set, and the clipping objective function is used to limit the strategy drift to prevent scheduling shock during the strategy update process. The valuation network is corrected in combination with the advantage function to improve the accuracy of long-term scheduling.
The probability distribution of the policy network's action output is prone to drastic fluctuations during continuous scheduling iterations, which may lead to unstable behavior or disordered resource allocation. To mitigate the scheduling shock caused by policy drift, a truncated update interval is designed to control the range of change between the new and old policies, and a restriction term is constructed to refine the objective function. The historical policy probability is recorded in the sampling round, and the ratio term is constructed with the current policy probability. The policy update target is set as:
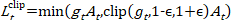 (5)
Here, gt = πθ(at|st)/πθold(at|st) denotes the probability ratio between the new and old policies; ε is the clipping threshold that bounds the policy update range. When the ratio exceeds the boundary, the clipping value is used instead to prevent the strategy from producing excessive gradients from extreme samples, ensuring that the network parameter adjustment remains within the preset range. This structure dynamically constrains the range of changes in the output strategy for each scheduling round, maintaining the smoothness and consistency of the strategy output under dense task distributions and significantly reducing the jitter rate of scheduling behavior.
The policy objective function is augmented with regularization and entropy reward terms during the update process to enhance the diversity of the action distribution and suppress early convergence. Each round of policy updates uses multiple batches of experience trajectory samples for rolling training, thereby maintaining breadth of coverage in the state space. When the probability distribution of the output action sequence is compared before and after the update, the deviation rate of the distribution is calculated, and a hard threshold screens out the acceptable disturbance range of the policy. This mechanism provides boundary control for migrating scheduling policies across cycles, thereby suppressing overfitting due to drastic changes in resource status.
Strategy updates rely on the state evaluation provided by the value function. Deviations in state-value estimation can directly affect the correctness of the advantage function, thereby altering the direction of strategy iteration. To improve valuation accuracy, a multi-timeseries backtracking mechanism is constructed, and the discounted cumulative value of future rewards is used to correct the current state value. The backtracking reward adopts the Generalized Advantage Estimation (GAE) structure, which is defined as:
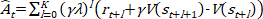 (6)
Ât is the corrected advantage value; λ is the backtracking balance coefficient; rt+l represents the immediate reward of the (t+l)-th step; V(st+l) is the state value output by the valuation network. This structure integrates short-term, immediate feedback and long-term state expectations to correct deviations in the strategy's response predictions for future resource conflicts, peak loads, and task accumulation. λ controls the backtracking depth and automatically adjusts during periods of drastic resource dynamic fluctuations to enhance the robustness of the valuation network's response to sudden events.
The multi-scale time-dependent structure embedded in the advantage function enables the valuation network to model long-term resource trends. In detecting policy output deviation, the policy behavior consistency index is used to assess whether the network exhibits an excessive response to the valuation error. Feedback-difference residual terms monitor policy update behavior, and the training target and the value function's weight update amplitude are dynamically corrected. The value network and the policy network are jointly optimized to ensure that value estimation does not deviate from the task completion goal while preventing high-frequency scheduling from misjudging resource-conflict status.
This stable policy update mechanism can effectively maintain the controllability and consistency of policy behavior updates in a high-dimensional dynamic task environment, improving task coverage efficiency and resource utilization flexibility, and forming a continuously iterative intelligent scheduling structure. Scheduling behavior prevents falling into local optimality in the long-term evolution and enhances overall adaptability to changes in task patterns and fluctuations in resource cycles.
Figure 3A shows the trend in the objective function value as a function of the number of training iterations under different truncation threshold conditions. The horizontal axis is the number of training iterations, and the vertical axis is the numerical value of the clipped objective function. ε is set to 0.1, 0.2, and 0.3, representing different degrees of policy drift control strength. The curve corresponding to a smaller ε value fluctuates less, and the objective function remains stable. When ε = 0.1, the overall objective function value is between 0.8 and 1, showing the gradualness and stability of the strategy update. However, a larger ε value leads to pronounced fluctuations. When ε = 0.3, the overall objective function value is between 0.65 and 0.95, and the objective function curve shows a larger oscillation amplitude, reflecting the risk of severe deviation in the strategy update process. The smaller the threshold, the more stable the strategy is, which is suitable for high-constraint scheduling environments. Figure 3B shows the changes in the generalized advantage estimate under different backtracking balance coefficients. λ is set to 0.8, 0.9, and 1.0, respectively, to control the backtracking depth of future rewards. The curve shows that the higher λ is, the smaller the GAE fluctuation, the smoother the long-term trend, and the more accurately it captures the potential impact of scheduling behavior after multiple steps. The curve with a λ of 0.8 exhibits pronounced periodic fluctuations, indicating it is more sensitive to immediate rewards and better suited to short-term, sudden tasks. In contrast, a λ of 1.0 focuses more on long-term trend modeling and is suitable for periodic task scenarios.
Computational complexity and scalability analysis
The computational complexity of the proposed Transformer-PPO framework is determined by two main components: the Transformer encoder and the PPO policy optimization.
For the Transformer encoder with L layers, H attention heads, embedding dimension d, and input sequence length T (the historical time window), the time complexity per forward pass is O(L·T2·d + L·T·d2), where the T2 term arises from the self-attention mechanism. In the implementation, L = 3, H = 4, d = 128, and T is fixed to 100 time steps, resulting in a manageable computational overhead. For longer historical windows, the quadratic term T2 becomes the dominant factor; however, in practice, union activity scheduling typically involves finite historical horizons (e.g., one-quarter or one-year rolling windows), and the time step resolution can be adjusted to balance accuracy and efficiency.
For the PPO component, the policy network and value network are lightweight MLPs (256 and 128 neurons per hidden layer), whose inference complexity is O(d·m), with m being the number of hidden units, which is negligible compared to the Transformer encoder. The policy update during training involves multiple epochs of mini-batch gradient updates, with complexity O(B·E·d2), where B is the batch size, and E is the number of update epochs.
In terms of scalability, the framework exhibits three favorable properties. First, the attention mechanism can be parallelized across time steps, enabling efficient GPU acceleration. Second, the model size is independent of the number of activities or resources, as the constraint matrix is dynamically constructed per scheduling step rather than embedded as fixed parameters. This allows the same trained model to be deployed across unions of different scales without retraining. Third, for extremely large-scale scenarios, the historical window length T and embedding dimension d can be reduced as a trade-off, or the sparse attention variant can be adopted to reduce the O(T2) complexity to O(T log T) or O(T).
Results
Experimental data
To comprehensively evaluate the performance of the Transformer-PPO dynamic scheduling algorithm presented in this paper, the experiment uses activity management data from a large enterprise union over the past three years as a benchmark dataset. This dataset contains over 5,000 activity records, encompassing various types, including meetings, training, and entertainment, with scheduling information for multiple resources, such as venues, equipment, and personnel. Each record details the start and end time of the activity, resource requirements, priority, and actual execution status (including conflict events and resource utilization). To simulate dynamic changes in real scenarios, the data is augmented with an additional 10% of random burst tasks and resource-change events (such as temporary site occupation and personnel time-window adjustments) to verify the robustness of the algorithm in a highly uncertain environment. The continuous state sequence provides structured input for Transformer timing modeling and PPO policy training. The experiment compared scheduling performance under different task densities and complexities to ensure the evaluation covers typical scenarios in actual applications, and compared it with the currently popular LSTM-PPO model, a greedy search scheduling model, and a DQN policy scheduling model.
The Transformer encoder comprises 3 layers, each with 4 attention heads, an embedding dimension of 128, and a feed-forward hidden size of 256. The policy network and value network share the same Transformer output as input and then diverge into two separate multilayer perceptrons (MLPs). Each MLP has two hidden layers with 256 and 128 neurons, respectively, using ReLU activation. All linear layers are initialized using Xavier uniform initialization.
The optimizer is Adam with a learning rate of 3 × 10⁻⁴, a batch size of 64, and an entropy coefficient of 0.01. The PPO clipping parameter ε is set to 0.2, the discount factor γ = 0.99, and GAE λ = 0.95. The model is trained for 5,000 episodes, with each episode containing up to 100 scheduling steps. Gradient clipping with a maximum norm of 0.5 is applied to prevent gradient explosion. These parameters are selected through preliminary grid search and are consistent with common practices in reinforcement-learning-based scheduling tasks. All experiments are run on a single GPU accelerator (40 GB memory), using Python 3.9 and a deep learning framework (see Table of Materials).
Temporal trend of multi-head attention output, residual enhancement under temporal variation of encoding features, and task priority stratification
Using the actual scheduling history as input, the task request, resource usage status, and feedback execution status are extracted at continuous time steps, and multi-type information is embedded in a unified feature space via linear mapping and positional encoding. The multi-head attention mechanism computes temporal correlations between different feature sequences in parallel and produces three types of attention weight sequences: task, resource, and feedback. Each weight type represents the model's attention intensity to the corresponding state at each time step. After normalization, a trend curve is drawn to reflect the encoding layer's perception focus and dynamic change structure of different information dimensions in the scheduling history. This process is completed based on the actual execution trajectory of activities and the resource usage log in the scheduling scenario.
Figure 4 shows the dynamic attention trend of the multi-head attention mechanism on different state information in the union activity scheduling. The time step is on the horizontal axis, reflecting the continuous advancement of the scheduling sequence, and the vertical axis is the normalized attention weight, which is bounded by [0,1], representing the model's relative importance to task characteristics, resource status, and feedback status. The attention to task characteristics shows a clear peak around the 15th step. In the early stage of scheduling, the model prioritizes capturing the timing characteristics of key tasks to predict potential conflicts and resource bottlenecks, reflecting the sensitivity to risk at this stage of activity scheduling. The attention curve for resource status shows periodic fluctuations, and the overall attention weight ranges from 0.2 to 0.8, reflecting the scheduling system's continuous tracking of changes in resource occupancy, supporting the complex processing of resource sharing and allocation, and effectively responding to the dynamic competition for resources among multiple concurrent tasks. The attention to the feedback state gradually increases, and the weight peak appears near step 35, highlighting the model's attention to the feedback of execution results and abnormal conditions in the middle and late stages of scheduling, which helps to adjust the strategy to deal with scheduling deviations and improve the robustness of the overall scheduling. This trend shows that an encoding structure integrating the multi-head attention mechanism can capture subtle changes in temporal features and enhance the adaptability of scheduling strategies to diverse resources and complex task dependencies, thereby improving the overall efficiency and stability of dynamic scheduling for union activities.
The hidden-state encoding sequence and the task-feature response structure are processed. The state comparison part constructs the feature propagation paths before and after the residual connection under the same input condition, observes the temporal evolution of the hidden state across consecutive time steps, and extracts its local stability and global continuity features to analyze the smooth evolution of state expression during information transmission. The task-priority response trend is extracted from the feature activation path across different scheduling-weight strategies. By tracking the activation levels of different task categories over time, the model's dynamic adjustment effect on task differentiation ability is captured.
Figure 5A shows the trend of the hidden state of the model before and after the application of the residual connection mechanism. The horizontal axis is the time step, and the vertical axis is the hidden state value. The original output without a residual connection fluctuates widely, exhibiting pronounced local instability and trend breaks. The blue solid line represents the state value after applying the residual structure. The overall trend remains stable, and fluctuations are significantly reduced, indicating that the model achieves gradient buffering and feature enhancement during state propagation. This phenomenon verifies the role of the residual mechanism in improving the stability of long-term dependent structures, effectively suppressing information attenuation caused by deeper layers, and enhancing the continuous expressive ability of historical state sequences. Figure 5B depicts the feature activation dynamics of three types of tasks in a time series. The horizontal axis is the time step, and the vertical axis is the feature activation value, reflecting the time sensitivity and strategy attention of tasks at different priority levels. The low-priority tasks show a decaying trend, and the feature activation value decays to below 0.5 in the later stage, indicating that the model pays proper attention to them in the early stage of scheduling, and gradually weakens the resource response over time; the characteristics of medium-priority tasks slowly increase over time, and there are periodic oscillations, reflecting that the model makes flexible perception and tracking of its demand fluctuations; high-priority tasks maintain a continuous upward trend over time, and the feature activation value always remains above 2, with a high and stable activation level, indicating that the model always maintains a high degree of responsiveness to such tasks. This differential response demonstrates the state encoding module's ability to accurately identify task attributes and provides a hierarchical basis for decision-making in scheduling strategy generation.
Multi-dimensional performance evolution analysis of transformer-ppo dynamic scheduling algorithm
Based on Transformer encoding of historical scheduling sequences and resource status, spatiotemporal features are extracted as the state input of PPO; then the policy network outputs the scheduling action, and the environment feedbacks immediate rewards and updates the status; during the training process, the original indicators of each round are recorded, and then the noise is eliminated through sliding average filtering, and the convergence trend of the algorithm is analyzed; in the final visualization, the original data shows instantaneous dynamics, and the smooth curve reflects the long-term performance improvement, verifying that the model achieves stable scheduling through time series modeling and policy optimization.
Figure 6A,B shows the multi-dimensional performance evolution analysis of the Transformer-PPO dynamic scheduling algorithm. The fluctuations in the original data reflect the instantaneous noise in the scheduling process, while the smoothed data extract the long-term trend via a sliding average, eliminating the interference of short-term disturbances on the algorithm's performance evaluation and making it easier to observe the performance evolution. Analyzing the smoothed data, the dynamic relationship between the reward and the policy entropy shows that the reward curve shows logarithmic growth, and the policy quickly learns to effectively schedule actions through exploration; the growth tends to be flat in the later stage, and the saturation value of the reward stabilizes at around 12, indicating that the policy is close to the local optimum. The policy entropy gradually decays from about 2.2 at the beginning to about 0.6. PPO retains the necessary exploration ability through the entropy reward item. High exploration (high entropy) in the early stage promotes a rapid increase in rewards, while the later strategy balances exploration and utilization through pruning and updating. The coordinated optimization of conflict rate and resource utilization shows that the conflict rate drops to a level below 10%, and its lower limit reflects conflicts that cannot be eliminated in the actual system due to task randomness. This downward trend is directly attributable to the Transformer's ability to encode historical activity sequences, enabling the model to proactively predict resource contention. Resource utilization has increased to nearly 75%, in line with the law of diminishing marginal returns. It is reasonable that utilization has not reached a higher level, as excessive utilization may cause queuing delays. Reduced conflicts have freed up more available resources, and optimized resource allocation has further suppressed conflicts.
Response speed and decision-making efficiency evaluation
Comparing the average decision time and average response delay under different task densities (number of tasks: 100, 300, 500, 700, 1000). Comparing the Transformer-PPO scheduling model in this paper with the LSTM-PPO model, the greedy search scheduling model, and the DQN strategy scheduling model.
Figure 7A,B shows the average decision time and average response delay for the four scheduling strategies across different task-density conditions, reflecting the algorithm's real-time decision-making ability and system responsiveness under high-load scenarios. As the number of tasks increases, each strategy shows an upward trend in both indicators, but the increases and stability differ. In task-intensive scenarios, the Transformer-PPO structure maintains relatively stable average decision-time performance. When the task density is 1000, the average decision time is 0.72s, and the average response delay is 1.59s, which is mainly due to the compression effect of its temporal feature encoding on the state space and the effective avoidance of invalid operations in the action space. In contrast, the DQN strategy exhibits longer decision times and response delays as the number of tasks increases, reflecting its limited ability to generalize policies across high-dimensional state transitions. Although the Greedy strategy makes decisions faster across varying task counts, its response performance degrades on complex task graphs due to a lack of long-term dependency modeling. LSTM-PPO has a certain time perception ability in sequence modeling, but it performs poorly in long-term dependency scenarios due to the limited structural depth. The results reveal the key impact of structural design on the scheduling system's responsiveness and emphasize the necessity of coordinated optimization of the encoding mechanism and policy sampling efficiency under high-concurrency conditions.
Conflict rate and resource utilization evaluation
Under different activity type complexity conditions (single type, multi-type independent, multi-type cross, multi-stage workflow, cross-departmental collaboration, temporary insertion, repeated cycle), the resource conflict rate and average resource utilization rate are statistically analyzed. The Transformer-PPO scheduling model in this paper is compared with the LSTM-PPO, greedy search, and DQN scheduling models.
Figure 8A,B shows the resource conflict rate and average resource utilization for different scheduling models across seven activity complexity levels. The vertical axis is the scheduling model, and the horizontal axis is the activity type. The overall trend shows that as the complexity of the activity structure (such as multi-stage processes, cross-departmental collaboration, temporary insertion, and repeated cycles) increases, the conflict rate across all models increases. The greedy strategy and DQN scheme exhibit limited adaptability to dynamic changes and are clearly insufficient in conflict control. The Transformer-PPO model still maintains a low conflict rate under high-complexity conditions, with an overall resource conflict rate of 0.05–0.12, reflecting its deep understanding of the task dependency structure and resource changes. In terms of resource utilization, Transformer-PPO maintains a high level across all conditions, especially with multi-type crossover and temporary insertion. Its dynamic adjustment strategy effectively reduces resource idleness, with an average resource utilization rate of 0.75–0.86. The data verify that the Transformer-PPO model achieves a better balance between scheduling flexibility and resource efficiency, and offers greater practicality and scalability.
Scheduling stability
The scheduling stability index is calculated under different activity type complexity conditions (single type, multi-type independent, multi-type cross, multi-stage process, cross-departmental collaboration, temporary insertion, and repeated cycle). The Transformer-PPO scheduling model in this paper is compared with the LSTM-PPO, greedy search, and DQN scheduling models.
Table 1 presents the comparison results for the scheduling stability index across different scheduling models under seven activity-type complexity conditions. The selected complexity type reflects the scheduling system's stability performance across multiple scenarios. The index value ranges from 0 to 1. The higher the value, the stronger the model's resistance to scheduling disturbances and the more stable the strategy output. Experimental results show that Transformer-PPO maintains a high stability index under all task structures. Especially in multi-type, cross-departmental collaboration and repeated-cycle scenarios, its scheduling strategy's stability is better than that of other models, demonstrating strong structural preservation and adaptive scheduling capabilities. The overall scheduling stability index ranges from 0.8 to 0.91. In contrast, the stability of the greedy algorithm and DQN decreased significantly as the task structure became more complex, with obvious policy jitter and execution deviations. LSTM-PPO exhibits some stability, but its overall performance remains lower than Transformer-PPO's. This comparison verifies the positive contributions of the multi-head attention mechanism and the policy-pruning update mechanism to the stability of the scheduling output, highlighting the model's advantage in stability in complex union activity scenarios.
Task concurrency load adaptation analysis
As the number of concurrent tasks continues to increase, the scheduling system must address the dual challenges of resource distribution conflicts and reduced policy generalization. To test the scheduling adaptability of different models under task load expansion, this section sets three levels of task concurrency (low: 100 items, medium: 500 items, and high: 1000 items) to monitor system resource distribution and policy response consistency during the scheduling cycle. The resource balance index is used to reflect the load balance of different resource units during the scheduling process, and is calculated as follows:
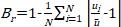 (7)
ui represents the actual utilization rate of resource units; ū represents the average utilization rate of all resources; and N represents the total number of resources. The value range is [0,1], and the closer it is to 1, the more balanced the resource distribution is.
The policy transfer robustness index Rs measures the degree of consistency of policy output under different task load conditions and is defined as:
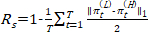 (8)
πt(L) and πt(H) are the scheduling strategy distributions under low load and high load scenarios, respectively, and T is the total time step. The closer it is to 1, the stronger the robustness of strategy migration and the higher the adaptability.
Table 2 systematically presents the performance of the four scheduling models in terms of resource balance and policy transfer robustness under varying task concurrency loads. The task concurrency levels are set to low (100 items), medium (500 items), and high (1000 items), respectively, reflecting the model's scheduling adaptability under different task-scale pressures. The results show that the Transformer-PPO model achieves the highest resource balance index across all load levels, reflecting its ability to rationally allocate resources in concurrent multi-task scenarios. At the same time, the policy transfer robustness index is also significantly better than the comparison model, showing strong policy consistency and adaptability. Under high-concurrency conditions, the resource balance index and the policy transfer robustness index are 0.88 and 0.85, respectively. In comparison, LSTM-PPO performed second, while the Greedy algorithm and the DQN model showed significant performance degradation under high load, with uneven resource distribution and increased policy fluctuations being more prominent. This evaluation clearly revealed differences in resource management and policy robustness in the scheduling system under task load expansion, and further verified the applicability and superiority of the Transformer-PPO fusion solution for dynamic and complex union activity scheduling.
Comparison with additional state-of-the-art methods
To further benchmark the proposed method against recent state-of-the-art (SOTA) approaches, three representative algorithms from the latest literature that combine deep learning with reinforcement learning are implemented for scheduling problems: (1) Transformer+DQN42 using the same Transformer encoder as ours but replacing PPO with DQN for policy learning, as explored in recent value-based scheduling studies; (2) GRU+PPO43 replacing the Transformer encoder with a Gated Recurrent Unit (GRU) to capture temporal dependencies, representing advanced RNN-based methods; and (3) GraphSAGE+PPO44 employing a GraphSAGE encoder to model task-resource relationships as graphs, reflecting recent graph neural network approaches for scheduling. All methods are trained under identical experimental conditions (same dataset, task density of 1000, and episode setup) with hyperparameters tuned via grid search for fair comparison. Each method is evaluated over 10 independent runs, and the average values of key performance metrics (response delay, resource conflict rate, resource utilization, and scheduling stability index) are recorded.
As shown in Table 3, the proposed Transformer+PPO method consistently outperforms all three SOTA baselines across all evaluated metrics. The average response delay of the proposed method (1.59s) is significantly lower than that of Transformer+DQN (2.13s), GRU+PPO (1.89s), and GraphSAGE+PPO (1.72s), indicating superior decision-making efficiency. The proposed method's resource conflict rate (0.09) is also the lowest, indicating better proactive conflict avoidance. This improvement is attributed to the Transformer's multi-head attention, which captures long-range dependencies more effectively than GRU or GraphSAGE, combined with PPO's stable policy updates. In terms of resource utilization, the proposed method achieves 0.82, outperforming the others by at least 8 percentage points, demonstrating more efficient resource allocation. The stability index of the proposed method (0.88) is also the highest, confirming that the clipping objective and GAE correction in PPO yield more robust scheduling policies than DQN or other PPO variants. Overall, the results validate that the specific combination of Transformer and PPO in the proposed framework offers clear advantages over recent alternative architectures, further strengthening the case for its application in dynamic union activity scheduling.
DATA AVAILABILITY STATEMENT:
The anonymized dataset used in this study, along with the data preprocessing pipeline and evaluation scripts, has been deposited in the Figshare repository and is publicly available at https://doi.org/10.6084/m9.figshare.33059243 (DOI: 10.6084/m9.figshare.33059243). The dataset contains activity schedules, resource usage logs, and conflict event records from a large enterprise union, with all personally identifiable and commercially sensitive information removed.
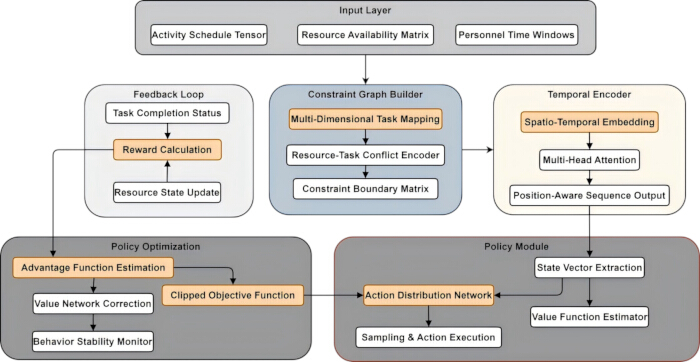
Figure 1: Structure of the union activity scheduling system. Activity requests, resource availability, and personnel time-window information are integrated to construct a task–resource constraint graph and conflict matrix. Historical activity and resource-state sequences are encoded using a Transformer with multi-head attention. The encoded states are supplied to the proximal policy optimization (PPO) policy and value networks, which generate scheduling-action probabilities and state-value estimates. Selected actions update the scheduling environment and generate rewards. The clipped PPO objective and generalized advantage estimation are then used to update the model, forming a closed feedback loop for adaptive scheduling and resource allocation. Please click here to view a larger version of this figure.
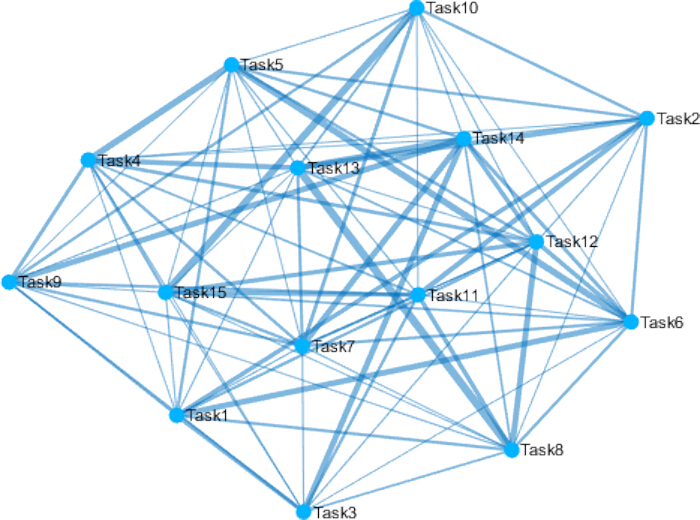
Figure 2: Task conflict weight network (edge thickness reflects the severity of the conflict). Each node represents an activity awaiting scheduling, and each edge represents a conflict caused by overlapping use of personnel, venues, equipment, or other resources. Edge thickness is proportional to the calculated conflict weight, with thicker edges indicating more severe conflicts. Densely connected node groups represent potential resource bottlenecks and competing task clusters. A force-directed layout is used to position strongly conflicting tasks closer together. Please click here to view a larger version of this figure.
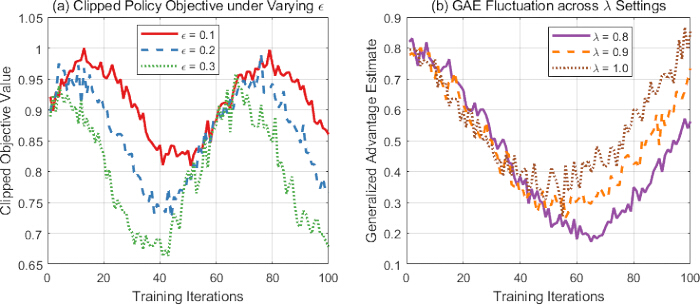
Figure 3: Strategy stability and advantage estimation dynamic characteristics during scheduling optimization iteration. (A) Clipped Policy Objective under Varying ε. (B) GAE Fluctuation across λ Settings. Please click here to view a larger version of this figure.
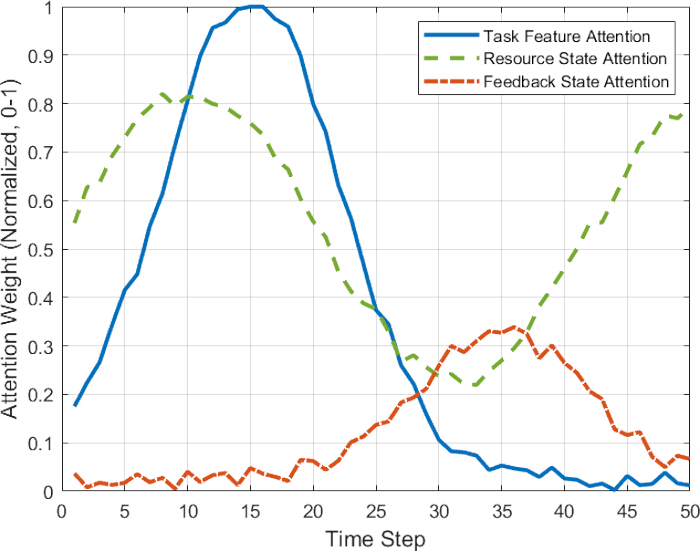
Figure 4: Time trend of multi-head attention output Please click here to view a larger version of this figure.
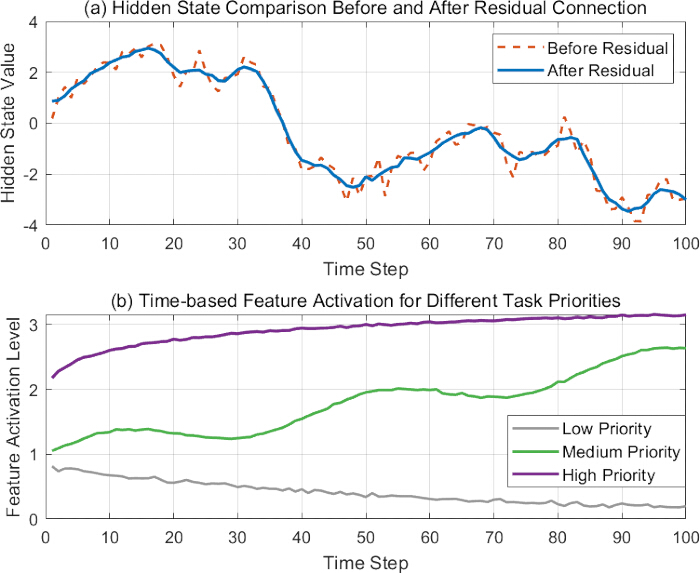
Figure 5: Residual enhancement and task priority stratification under temporal variation of encoding features. (A) Hidden State Comparison Before and After Residual Connection. (B) Time-based Feature Activation for Different Task Priorities. Please click here to view a larger version of this figure.
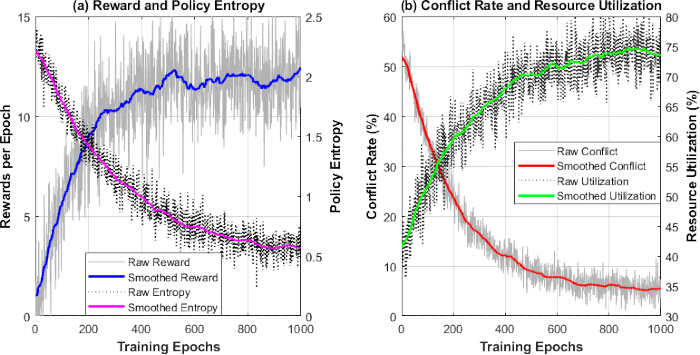
Figure 6: Multi-dimensional performance evolution analysis. (A) Reward and Policy Entropy (B) Conflict Rate and Resource Utilization. Please click here to view a larger version of this figure.
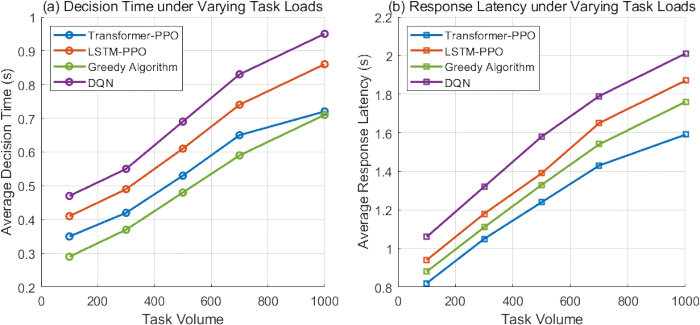
Figure 7: Average decision time and average response delay. (A): Decision Time under Varying Task Loads. (B): Response Latency under Varying Task Loads. Please click here to view a larger version of this figure.
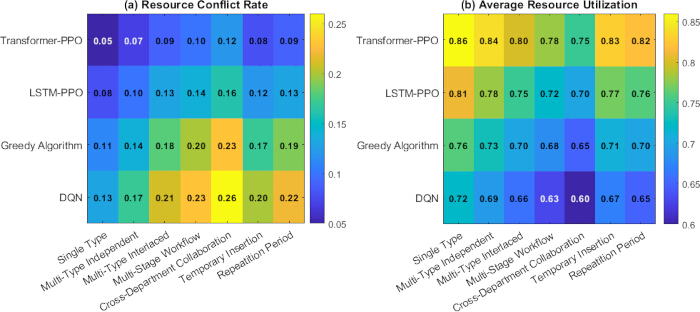
Figure 8: Comparison of resource conflict rate and average resource utilization (A) Resource Conflict Rate. (B) Average Resource Utilization Please click here to view a larger version of this figure.
| Activity Complexity Condition | Transformer-PPO | LSTM-PPO | Greedy Algorithm | DQN |
| Single Type | 0.91 | 0.86 | 0.74 | 0.78 |
| Multi-Type Independent | 0.88 | 0.81 | 0.7 | 0.73 |
| Multi-Type Interlaced | 0.85 | 0.76 | 0.65 | 0.68 |
| Multi-Stage Workflow | 0.83 | 0.73 | 0.61 | 0.66 |
| Cross-Department Collaboration | 0.8 | 0.7 | 0.59 | 0.63 |
| Temporary Insertion | 0.86 | 0.78 | 0.68 | 0.72 |
| Repeatition Period | 0.84 | 0.75 | 0.64 | 0.69 |
Table 1: Comparison of Scheduling Stability Index Across Different Activity Complexities. The scheduling stability indices of the Transformer–PPO, long short-term memory–PPO (LSTM–PPO), greedy-search, and deep Q-network (DQN) models are compared across seven conditions: single-type activities, independent multiple-type activities, intersecting multiple-type activities, multistage workflows, cross-departmental collaboration, temporary task insertion, and repeated-cycle activities. The stability index ranges from 0 to 1, with higher values indicating greater resistance to scheduling disturbances and more consistent policy outputs.
| Task Concurrency Condition | Scheduling Model | Resource Balance Index | Policy Transfer Robustness Index |
| Low Concurrency (100 Tasks) | Transformer-PPO | 0.94 | 0.92 |
| LSTM-PPO | 0.89 | 0.85 | |
| Greedy Algorithm | 0.83 | 0.78 | |
| DQN | 0.85 | 0.81 | |
| Medium Concurrency (500 Tasks) | Transformer-PPO | 0.91 | 0.89 |
| LSTM-PPO | 0.86 | 0.82 | |
| Greedy Algorithm | 0.78 | 0.71 | |
| DQN | 0.81 | 0.76 | |
| High Concurrency (1000 Tasks) | Transformer-PPO | 0.88 | 0.85 |
| LSTM-PPO | 0.82 | 0.76 | |
| Greedy Algorithm | 0.7 | 0.63 | |
| DQN | 0.75 | 0.68 |
Table 2: Evaluation of Task Concurrency Load Adaptability. The resource-balance index and policy-transfer robustness index of the four scheduling models are compared under low-, medium-, and high-concurrency conditions, corresponding to 100, 500, and 1,000 simultaneous tasks, respectively. Both indices range from 0 to 1, with higher values indicating more balanced resource allocation and greater consistency of scheduling policies across changes in task load.
| Method | Avg Response Delay (s) | Resource Conflict Rate | Resource Utilization | Stability Index |
| Transformer+DQN | 2.13 ± 0.12 | 0.18 ± 0.02 | 0.68 ± 0.03 | 0.76 ± 0.04 |
| GRU+PPO | 1.89 ± 0.09 | 0.15 ± 0.01 | 0.72 ± 0.02 | 0.79 ± 0.03 |
| GraphSAGE+PPO | 1.72 ± 0.08 | 0.13 ± 0.01 | 0.74 ± 0.02 | 0.82 ± 0.03 |
| Proposed | 1.59 ± 0.05 | 0.09 ± 0.01 | 0.82 ± 0.02 | 0.88 ± 0.02 |
| (Transformer+PPO) |
Table 3: Performance comparison with additional state-of-the-art methods. The proposed Transformer–PPO method is compared with Transformer–DQN, gated recurrent unit–PPO (GRU–PPO), and GraphSAGE–PPO under identical experimental conditions at a task density of 1,000. Results represent the mean values from 10 independent runs. The evaluated outcomes include response delay in seconds, resource-conflict rate, resource-utilization rate, and scheduling stability index. Lower response delays and conflict rates indicate better performance, whereas higher resource-utilization and stability indices indicate better performance.
Discussion
The experimental results demonstrate that the proposed Transformer-PPO algorithm consistently outperforms the baseline methods (LSTM-PPO, greedy search, and DQN) across all evaluation metrics. The superior performance can be attributed to two key factors. First, the multi-head self-attention mechanism of Transformer effectively captures long-range temporal dependencies in activity and resource state sequences, enabling proactive identification of potential conflicts. This explains why the conflict rate remains low even under high complexity (e.g., cross-departmental collaboration and temporary insertion), as the model can anticipate resource contention before it occurs. Second, the clipped objective function and GAE-based advantage correction in PPO ensure stable policy updates, preventing drastic fluctuations in scheduling decisions and maintaining high robustness under varying task loads.
Compared with existing scheduling approaches, the proposed method addresses the limitations of LSTM-based models that suffer from vanishing gradients in long sequences, and overcomes the poor generalization of greedy and DQN methods in dynamic environments. While LSTM-PPO shows moderate performance, it fails to maintain stability when task dependencies span over long time horizons, as reflected in its higher conflict rates and lower resource balance under high concurrency. The greedy algorithm, though computationally efficient, lacks foresight and leads to suboptimal resource allocation, increasing response delays. DQN, on the other hand, exhibits policy oscillation due to the lack of a trust-region constraint, which degrades its performance in multi-task scenarios.
Nevertheless, this study has several limitations. The dataset is derived from a single enterprise union, which may limit the generalizability of the findings to other organizational contexts. Additionally, the model assumes that all activity and resource information is fully observable, which may not hold in real-world settings where data are incomplete or noisy. The computational overhead of the Transformer encoder also increases with the length of the historical window, potentially affecting real-time applicability for extremely large-scale systems.
Future work can focus on extending the model to handle partially observable environments using recurrent state estimation, and incorporating meta-learning techniques to enable rapid adaptation to new unions with limited historical data. We also plan to deploy the algorithm in a cloud-edge collaborative architecture to reduce decision latency and support distributed scheduling. Furthermore, integrating explainable AI components could provide interpretable scheduling rationales for human operators, enhancing trust and practical adoption.
This paper studies a dynamic scheduling optimization algorithm that integrates Transformer and PPO reinforcement learning, focusing on frequent resource conflicts and response delays in scheduling union activities. The algorithm thoroughly examines the spatiotemporal characteristics of activity history and resource status through a multi-head attention mechanism, thereby enhancing the ability to identify potential conflict risks. Combined with the strategy's stable update mechanism for the clipping objective function, it achieves efficient response and resource allocation in a dynamic environment. This method demonstrates excellent scheduling stability, resource utilization, and conflict control capabilities for complex and diverse activity types and task loads. Empirical analysis shows that the algorithm has a small response delay under high task density. Under seven different activity types and complexities, the resource conflict rate is 0.05–0.12, the average resource utilization is 0.75–0.86, and the scheduling stability index is 0.8–0.91. It maintains a low resource-conflict rate and a high resource balance, which are significantly better than those of the current mainstream LSTM-PPO, greedy search, and DQN scheduling models. At the same time, the robustness of strategy transfer and scheduling stability are both good, indicating that the algorithm has strong adaptability and anti-disturbance ability. This performance advantage provides solid technical support for the union activity management system in dynamic, changing resource scheduling scenarios.
Disclosures
The authors declare that they have no financial conflicts of interest.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| Python 3.9 | Python Software Foundation | https://www.python.org/downloads/release/python-390/ | Core programming language |
| PyTorch 1.12 | Meta AI | https://pytorch.org/get-started/previous-versions/ | Deep learning framework (Transformer/PPO implementation) |
| NumPy 1.23 | NumPy Developers | https://numpy.org/doc/stable/release/1.23.0-notes.html | Numerical computation library |
| Matplotlib 3.5 | Matplotlib Development Team | https://matplotlib.org/stable/users/installing.html | Result visualization |
| Union activity scheduling dataset | Internal database of a collaborating enterprise (anonymized) | Not publicly available due to confidentiality agreement; researchers may contact the corresponding author for access | Over 5,000 activity records (meetings, training, entertainment) from a large enterprise union over three years |
| NVIDIA A100 GPU | |||
| PyTorch |
References
- Bosire RK, Muya J, Matula D. Employee recognition programs and employee output as moderated by workers’ union activities: evidence from Kenyatta National Hospital (KNH), Kenya. Saudi J Bus Manag Stud. 2021;6(3):61-70.
- Carneiro B, Costa HA. Digital unionism as a renewal strategy? Social media use by trade union confederations. J Ind Relat. 2022;64(1):26-51.
- Geelan T. Introduction to the special issue: the internet, social media and trade union revitalization—still behind the digital curve or catching up? New Technol Work Employ. 2021;36(2):123-39.
- Hennebert MA, Pasquier V, Lévesque C. What do unions do…with digital technologies? An affordance approach. New Technol Work Employ. 2021;36(2):177-200.
- Panagiotopoulos P. Digital audiences of union organising: a social media analysis. New Technol Work Employ. 2021;36(2):201-18.
- Wang W, Seifert R. Trade-union-engendered employee trust in senior management: a case study of digitalisation. Ind Relat J. 2024;55(6):472-91.
- Katsabian T. Collective action in the digital reality: the case of platform-based workers. Mod Law Rev. 2021;84(5):1005-40.
- Holgate J. Trade unions in the community: building broad spaces of solidarity. Econ Ind Democr. 2021;42(2):226-47.
- Ovi RP, Rana MS, Jodder PK, Sarkar B. Performance evaluation of e-service delivery of union digital centers at the local level using composite indexing method: a study of Batiaghata upazilla in Khulna district. Inf Dev. 2024;40(4):620-34.
- Crossan J, et al. Colours of democracy: trade union banners and the contested articulations of democratic spatial practices. Trans Inst Br Geogr. 2023;48(1):23-38.
- Victor C, Kavishe AM. The challenges faced by trade unions in improving employee welfare and strategies to address them: a case of the Tanzania Union of Government and Health Employees (TUGHE) at the National Health Insurance Fund (NHIF). Afr J Empir Res. 2025;6(1):189-200.
- Rogalewski A. Trade unions challenges in organising Polish workers: a comparative case study of British and Swiss trade union strategies. Eur J Ind Relat. 2022;28(4):385-404.
- Pacetti V, Rossi P, Romens AI. Remotizzare, o non remotizzare: questo è il dilemma. Imprese e sindacati di fronte alla remotizzazione ibrida del lavoro. Stato Merc. 2023;43(3):421-49.
- Hunt T, Connolly H. COVID-19 and the work of trade unions: adaptation, transition and renewal. Ind Relat J. 2023;54(2):150-66.
- Joyce S, Stuart M, Forde C. Theorising labour unrest and trade unionism in the platform economy. New Technol Work Employ. 2023;38(1):21-40.
- Dupuis M. Algorithmic management and control at work in a manufacturing sector: workplace regime, union power and shopfloor conflict over digitalisation. New Technol Work Employ. 2025;40(1):81-101.
- Suryadevara S. Real-time task scheduling optimization in WirelessHART networks: challenges and solutions. Int J Adv Eng Technol Innov. 2022;1(3):29-55.
- Roşu D, Cojanu F, Ştefănică V, et al. Experimental management of work collectives through social and socialization activities. J Phys Educ Sport. 2022;22(7):1742-47.
- Ahmed AAA, et al. Multi-project scheduling and material planning using Lagrangian relaxation algorithm. Ind Eng Manag Syst. 2021;20(4):580-87.
- Gao H, et al. TBDB: token bucket-based dynamic batching for resource scheduling supporting neural network inference in intelligent consumer electronics. IEEE Trans Consum Electron. 2024;70(1):1134-44.
- Ouhame S, Hadi Y, Ullah A. An efficient forecasting approach for resource utilization in cloud data centers using a CNN-LSTM model. Neural Comput Appl. 2021;33(16):10043-55.
- Valarmathi K, Kanaga Suba Raja S. Resource utilization prediction technique in the cloud using a knowledge-based ensemble random forest with an LSTM model. Concurr Eng. 2021;29(4):396-404.
- Yang Y, Shen H. Deep reinforcement learning enhanced greedy optimization for online scheduling of batched tasks in cloud HPC systems. IEEE Trans Parallel Distrib Syst. 2022;33(11):3003-14.
- Tang B, Luo J, Obaidat MS, Vijayakumar P. Container-based task scheduling in a cloud-edge collaborative environment using a priority-aware greedy strategy. Cluster Comput. 2023;26(6):3689-705.
- Zhang Y, Zou YH, Zhang XD. Manufacturing resource scheduling based on a deep Q-network. Wuhan Univ J Nat Sci. 2022;27(6):531-38.
- Mangalampalli S, et al. DRLBTSA: deep reinforcement learning-based task-scheduling algorithm in cloud computing. Multimed Tools Appl. 2024;83(3):8359-87.
- Wang Y, Wang Q, Chu X. Energy-efficient online scheduling of transformer inference services on GPU servers. IEEE Trans Green Commun Netw. 2022;6(3):1649-59.
- Liu L, et al. Dynamic sparse attention for scalable transformer acceleration. IEEE Trans Comput. 2022;71(12):3165-78.
- He X, et al. Channel assignment and power allocation for throughput improvement with PPO in B5G heterogeneous edge networks. Digit Commun Netw. 2024;10(1):109-16.
- Liu H, et al. A new multi-domain cooperative resource scheduling method using proximal policy optimization. Neural Comput Appl. 2024;36(9):4931-45.
- Jin J, Xu Y. Optimal policy characterization enhanced proximal policy optimization for multitask scheduling in cloud computing. IEEE Internet Things J. 2022;9(9):6418-33.
- Chavva M, Veera S. Dynamic cost-aware language models: a real-time framework for optimizing cloud resource recommendations. Int J Mach Learn Sustain Dev. 2023;5(2):1-15.
- Zhao Z, et al. Link scheduling using graph neural networks. IEEE Trans Wirel Commun. 2023;22(6):3997-4012.
- Zhang Z, et al. A resource optimization scheduling model and algorithm for heterogeneous computing clusters based on GNN and RL. J Supercomput. 2024;80(16):24138-72.
- Chai F, et al. Joint multi-task offloading and resource allocation for mobile edge computing systems in satellite IoT. IEEE Trans Veh Technol. 2023;72(6):7783-95.
- Luo Q, et al. Resource scheduling in edge computing: a survey. IEEE Commun Surv Tutor. 2021;23(4):2131-65.
- Gupta A, Namasudra S, Kumar P. An enhanced strategy for energy-efficient cloud computing environment through VM consolidation. In: Dagur A, Singh K, Mehra PS, Shukla DK, editors. Intelligent Computing and Communication Techniques. Boca Raton (FL): CRC Press; 2025. p. 330–34. https://doi.org/10.1201/9781003530176-46
- Sombo B, Apeh ST, Edeoghon IA. Review on authentication algorithms in cellular communication networks. Cloud Comput Data Sci. 2025;6(1):54-66.
- Gupta A, Kumar P, Namasudra S. Sustainable cloud computing: an enhanced energy-efficient VM consolidation approach using live migration. Iran J Comput Sci. 2026;9:27. doi:10.1007/s42044-025-00385-y.
- García F, et al. Traffic optimization through waiting prediction and evolutive algorithms. Int J Interact Multimed Artif Intell. 2025;9(3):96-103.
- Sharma P, Namasudra S, Lorenz P. Blockchain-based cloud storage system with enhanced optimization and integrity preservation. Presented at: IEEE International Conference on Communications (ICC); Rome, Italy; 2023. p. 3744-49.
- Ding F, et al. Transformer-enhanced DQN approach for energy- and cost-efficient large-scale dynamic workflow scheduling in a heterogeneous environment. IEEE Internet Things J. 2024;11(22):37351-67.
- Yu H, Tang N, Zhu Z, Guo Z. Flexible job-shop scheduling via gated recurrent unit and deep reinforcement learning. Knowl Based Syst. 2025;330:114734. doi:10.1016/j.knosys.2025.114734.
- Do KH, et al. Graph Neural PPO for joint user association and resource allocation in Open RAN [conference paper]. Presented at: 40th International Conference on Information Networking (ICOIN); Hanoi, Vietnam; 2026. p. 37-42.