This study develops a layered prompt optimization framework based on DeepSeek to enhance English writing transfer competence in cross-cultural contexts. Through a three-stage prompt chain and a quasi-experiment with 60 English majors, results show significant improvement in the experimental group compared with the control group.
Research Article
Optimizing DeepSeek Prompts for Cross-Cultural English Writing Instruction: A Practical Study of Transfer Competence
In This Article
Summary
Abstract
To address the limitation that traditional English writing instruction neglects systematic cultivation of language transfer and existing prompt frameworks fail to fit classroom teaching, this study constructs a hierarchical transfer training system based on the DeepSeek model covering four progressive task tiers: sentence, paragraph, discourse, and culture, with all tasks defined in triple form. A five-dimensional task library covering syntax, structure, culture, register, and logic is established, and targeted prompts are automatically generated from students’ authentic writing drafts. Integrated with the model’s Mixture of Experts (MoE) architecture, a nested prompt chain is developed to split complicated assignments into three sequential phases: semantic reorganization, linguistic revision, and cultural adaptation. Adopting a quasi-experimental design, this research recruits 60 second-year English majors from one university and assigns them to an experimental group and a control group of 30 students each for three weeks of staged intervention across three training rounds. Post-experiment results reveal that the experimental group’s cultural transfer score rises from 2.8 to 4.5, compared with a mere 0.3 increment in the control group; its average teacher-assessed score improves from 59.1 to 74.4, compared with the control group’s increase from 60.1 to 64.9. Most correlation coefficients between AI scoring and teacher evaluation exceed 0.8, and over 90% participants approve of the AI rewriting and structural optimization functions. Due to the small sample size in this trial, this optimization approach is feasible for implementation in university English writing classes.
Introduction
In the teaching of English writing in a cross-cultural context, non-native English learners often face the challenge of insufficient transfer ability as they transition from language knowledge to practical application1,2. Although students have a certain grammatical and vocabulary foundation, they struggle to effectively convert sentence patterns, structures, and cultural expressions into real writing, resulting in formalized language output and limited thinking, which in turn affects the overall writing quality3. In addition, cross-cultural differences in language structure, logical organization, and pragmatic norms further exacerbate the complexity of writing transfer4. In recent years, large language models (LLMs) have provided new technical support for writing teaching5. Intelligent writing tools, such as DeepSeek, have demonstrated strong capabilities in language generation and reconstruction. However, in teaching practice, they are mostly limited to surface-level language correction and have not yet been deeply integrated into the teaching process, which is centered on cultivating transfer ability. They lack teaching goal orientation and controllability of generation behavior6,7. Prevailing AI-assisted writing applications mostly confine their functions to surface-level grammatical error correction rather than targeting the cultivation of systematic transfer competence, resulting in poor teaching-oriented control over model outputs.
Existing research on ESL writing assistance falls into three mainstream categories: conventional prompt-driven writing feedback, generic AI polishing intervention, and manual-centered transfer training. First, general prompt engineering research prioritizes technical optimization of question answering and text rewriting without matching hierarchical transfer teaching goals8,9. Second, typical ChatGPT-based ESL tutoring focuses on overall writing accuracy improvement rather than layered syntactic, structural, and cross-cultural transfer cultivation10. Third, traditional transfer pedagogy relying on imitation and contrast writing lacks closed-loop feedback supported by intelligent tools11. Distinct from foregoing studies, this research customizes transfer-oriented hierarchical prompts aligned with multi-level teaching objectives and builds a sample-driven prompt auto-generation workflow, forming a unique closed-loop training mechanism combining model generation, teacher feedback, and student revision.
Prior literature hypothesizes a potential linkage spanning linguistic cultural divergence, inherent model structural constraints, and disjointed classroom practice, yet such a causal chain remains insufficiently empirically verified in existing empirical studies and becomes the core research hypothesis to be examined in this paper12,13. As for DeepSeek’s inherent characteristics cited in this paper, its open instruction interface and MoE-based expert routing design have been documented in existing model technical reports and applied language research. Building on these documented model features, this study tailors nested prompt chains to disassemble complex cross-cultural transfer tasks and develops dynamic submodel scheduling rules for differentiated transfer assignments. Centered on structured transfer ability development, the present work explores targeted DeepSeek prompt optimization, aiming to transform large language models from universal text-editing tools into specialized transfer training systems for college English writing instruction.
In the field of second-language writing research, the transfer phenomenon has long been a core topic14,15. Traditional language transfer theory primarily focuses on the positive and negative transfer effects of the mother tongue on the target-language acquisition process, with particular emphasis on phonetics, vocabulary, and syntax16. Mirzayev E pointed out that, in English as a Second Language (ESL) writing instruction, negative transfer from the first language remains a key factor limiting the development of students' writing abilities17. As the scope of research expands, the academic community has gradually expanded its focus to writing structure transfer18. Interlanguage writing often has language errors and fossilization due to multiple factors19. At the same time, cognitive transfer theory has also received increasing attention20. This theory emphasizes the differences in cognitive organization and expression patterns in the writing process. For example, Western writing emphasizes linear reasoning and explicit logic, whereas the Chinese tradition prefers a spiral approach and semantic ambiguity. There is a significant tension between the two. Therefore, language transfer not only involves the conversion of language units but also involves the adaptation and transformation of thinking structures and cultural expression norms at a deeper level, which is an important challenge in current English writing instruction21.
In the practice of cultivating transfer ability, existing studies often employ strategies such as imitative writing22, contrastive writing23, and translation training24 to enhance learners' understanding and application of the target language transfer mechanism. Imitative writing helps to build basic discourse ability, but it can easily lead to structural rigidity; contrastive writing can improve language style and cultural awareness, but it lacks systematic task stratification and personalized feedback; translation training can promote cultural metaphor recognition, but without guidance, it can easily lead to semantic deviation or pragmatic inappropriateness. The above strategies primarily rely on manual demonstration and experiential guidance25, lack explicit construction of transfer strategies and systematic feedback mechanisms, and are challenging to adapt to individual differences in language proficiency and cognitive styles. Although some studies have attempted to expand transfer training through diversified writing tasks26,27, the teaching process has not yet formed a closed loop of "transfer goal-language generation-strategy feedback"; the internalization effect of transfer strategies is limited, and students' transfer ability development in real writing tasks is still insufficient28.
With the development of large language model technology, its auxiliary potential in language teaching has garnered increasing attention29. Generative AI tools represented by ChatGPT (Chat Generative Pre-trained Transformer)30 and DeepSeek31 have been widely used in scenarios such as text polishing, language rewriting, and language adjustment. Diasamidze et al. found that ESL students using ChatGPT outperformed the traditional teaching group in terms of grammatical accuracy, vocabulary richness, and text organization ability32. However, existing applications are mostly limited to surface-level language processing and lack systematic guidance on transfer goals. Ranade pointed out that prompt-based projects in current educational scenarios are mostly based on general templates, and the generated content lacks contextual adaptability and task specificity33. In addition, mainstream model training relies on an open corpus and lacks deep modeling of the differences in Chinese and English cultural expressions. Cultural inappropriateness and unnatural pragmatics are prone to occur in the generated text34,35, which limits its in-depth application in cross-cultural writing transfer teaching.
Protocol
Ethical approval
Prior to the experiment, the authors obtained approval (Approval Number: NBCC-ETH-2026-037) from the college and distributed informed consent documents to all student participants. All students were clearly informed of the research objectives, experimental procedures, and data-use regulations. Participation was voluntary, and participants could withdraw from the study at any time. All personal data and written works were anonymized to protect privacy and were used only for academic analysis. All 60 participants signed the consent form before taking part in the research. Participants were selected from two parallel sophomore English writing classes at the same higher vocational college, recruited using convenience sampling. Inclusion criteria included: passing CET-6 with a score > 425, no absences this semester, and average scores in the last two unit writing tests. Exclusion criteria included: long-term use of commercial English AI writing software outside of class and severe dyslexia.
Variability for all continuous outcome variables was reported as mean ± standard deviation (SD). All analyses were conducted with a sample size of n = 30 participants per group (experimental group vs. control group), total N = 60. For longitudinal repeated-measures data, a repeated-measures analysis of variance (RM-ANOVA) was used to examine main effects of group and time, and the group-by-time interaction. Independent-samples t-tests were used for post-hoc pairwise comparisons at individual time points. The control group received traditional writing instruction plus a generic, free, uncustomized AI writing tool (no tiered prompts, no transfer-oriented templates). The instruction hours, writing tasks, feedback frequency, and training texts were identical to those of the experimental group, except for the lack of the customized nested prompt chain and five-level task library intervention used in this study. The experimental group used instructions based on the DeepSeek model to optimize writing instruction, including nested prompt-chain guidance, cross-cultural adaptation output, and the "generation-reflection-regeneration" mechanism. The control group, in contrast, employed traditional teaching methods or unoptimized AI-assisted tools. By comparing the teaching effects of the two groups, the effectiveness of the transfer training method based on the large language model in improving students' writing transfer ability was verified.
Overall research idea
This study aimed to improve students’ English writing transfer ability and develop effective instructional design methods, with a particular focus on adapting DeepSeek for educational use. First, it proposed an instruction optimization strategy to redesign model prompts. This improved the generated output's alignment with multiple transfer goals in writing instruction, including syntactic structure, paragraph logic, and cultural expression. Second, teachers’ writing tasks were converted into structured and goal-oriented prompt templates. A mapping relationship was then established between teaching tasks and model behaviors. This improved the model's controllability and ensured that the generated content was pedagogically relevant. Finally, the study developed a closed-loop transfer training process, “generation–reflection–rewriting–regeneration.” This process encouraged students to identify transfer strategies and actively refine their language expression with the support of the model. Through repeated iterations, students’ cross-linguistic and cross-cultural writing transfer abilities were continuously strengthened. The steps for sentence structure transformation are shown in Figure 1A–D.
To clarify the complete operation logic of the AI-assisted writing training system and improve replicability, the overall implementation workflow is summarized in Table 1, covering core links including raw input, teacher interventions, prompt application, student activities, final outputs, and corresponding evaluation criteria.
Transfer-oriented task construction strategy
This study focused on cultivating transfer ability in English writing. It constructed a transfer task path that progresses from shallow to deep, systematically guiding students in mastering and practicing multi-level language transfer strategies. To describe the path structure as a whole, it was defined as a four-level task set:
T = {T1,T2,T3,T4} (1)
T1 represents the sentence-level transfer task, which focuses on basic grammatical structure operations, such as short-sentence expansion, voice change, and clause replacement, to help students master diverse methods of sentence structure. T2 is the paragraph-level transfer task, which guides students to pay attention to the organization and connection of information within the paragraph, and trains them to improve the structural clarity and expression coherence of the paragraph through the extraction of the main sentence and the adjustment of the logic between sentences. T3 represents the discourse-level task, which further extends to the overall logical layout and argumentation rhythm of the chapter, and guides students to construct an English article with a complete argumentation system by adjusting the order of paragraphs and optimizing the structural juxtaposition relationship. T4 is the cultural-level transfer task, which requires students to identify implicit cultural expression characteristics in native-language writing, such as implicit wording and semantic hints, and transform them into direct expressions or logical explicit forms that conform to the target-language culture. Its evolution process is shown in Figure 2. To enhance the operability and evaluation of task design, this study further defined each level of task as a triple form:
Ti = (Si,Gi,Ei) (2)
Sj represents the task input sample, Gi represents the target transfer operation, and Ei represents the supporting evaluation criteria. Through this structured expression, it ensured that each level of the task was built upon the mastery of the strategy from the previous level and was equipped with corresponding samples, target descriptions, and performance criteria, providing a mechanism for the steady advancement of the transfer path. In the process of constructing the transfer training system, to achieve systematic coverage of task types and efficient management of teaching calls, this study built a structured task library covering five types of transfer goals based on the common language conversion dimensions in writing transfer. The task library was formally expressed as:
M = {(Dj,TDj)∣j = 1,2,3,4,5} (3)
Dj corresponds to five transfer dimensions: syntactic transfer, structural transfer, cultural transfer, register transfer, and logical transfer; the task set TDj associated with each dimension represents its operation subset. In the process of developing the task library, first, the authors summarized and classified common transfer difficulties and language error types based on a large number of real student writing samples, and combined with the actual teaching needs and evaluation standards, divided the different transfer types into functional areas, and established the core training objectives and operation modes of each task. Each task was abstractly represented as the following triple structure:
Ti,j = (Si,j,Gi,j,Ci,j) (4)
Si,j represents the task input sample, Gi,j is the transfer target description of the task, and Ci,j is the evaluation and control dimension of the task. In the syntactic transfer task, this study designed a sentence reorganization sequence that progressed from simple to difficult, covering sentence connection, clause nesting, passive-voice conversion, and related concepts, aiming to improve students' abilities in sentence expansion and grammatical transformation. The structural transfer task focused on optimizing paragraph logic, strengthening information organization, and enhancing logical construction ability through rewriting the main sentence, sorting supporting sentences, and reconstructing the cause-and-effect and example relationships. The cultural transfer task was based on a cross-cultural corpus and targets pragmatic deviations, such as implicit expressions and euphemisms. It designed expression conversions that are close to the real context to promote the development of cultural adaptability. The register transfer task guided students in transforming oral expressions into academic language and mastering strategies for switching registers. The logical transfer task focused on constructing reasoning chains and ensuring clarity of expression while conducting training on the use of conjunctions, explicitation of logical relationships, and paragraph transitions.
Based on students' actual writing samples, this study developed a prompt generation process closely tied to teaching tasks, aiming to enhance the relevance of instructions and the practicality of generated content. The process was led by teachers, who selected representative student text fragments during the teaching process, focusing on typical transfer problems such as redundant sentences, chaotic structures, and inappropriate cultural expressions. They then annotated the samples with transfer types through the system interface to clarify the training objectives. After receiving the annotation information, the system automatically activated the transfer task identification module. It then matched the input with the predefined task library and prompt template library. The matching process considered factors such as transfer type, linguistic features, and text structure. Based on these factors, the system selected the most appropriate template and generated an initial prompt. The system also supported structured enhancement processing. Teacher annotations were converted into a standardized format that can be easily interpreted by the model. Relevant instructional cues were embedded into the prompt to help the model accurately understand both the teacher’s intentions and the student’s questions. To improve the flexibility and controllability of instructions, the system included a teacher assistance module. This module allowed teachers to refine prompts by modifying instructional guidance, adjusting contextual settings, and customizing tone and style. As a result, teachers gained greater control over the generation process and better adapted it to different teaching scenarios.
Deepseek command optimization mechanism
Based on the practical needs of English writing transfer training, this study developed five types of transfer-oriented prompt templates. These templates were designed to guide and regulate the generation behavior of the large language model. The structural transfer template focused on paragraph organization and discourse structure. It helped students reorganize texts by adopting structures such as introduction–body–conclusion, and by improving the logical flow of ideas. The syntactic transfer template emphasized sentence-level complexity. It encouraged the use of diverse grammatical structures, including passive voice, parallel constructions, and complex clauses, to enhance the sophistication of written expression. The cultural transfer template addressed cultural appropriateness in writing. It guided students in adapting expressions influenced by their native language and culture to forms that were more natural and acceptable in English-speaking contexts. The register transfer template focused on style adaptation and register control. It helped students adjust their language use according to different writing purposes, audiences, and genres. The logic transfer template aimed to strengthen logical organization. It promoted the effective use of relationships such as cause and effect, comparison and contrast, and parallel development, thereby improving coherence and argumentative rigor. Together, these five templates covered the major dimensions of writing transfer. They provided structured instructional support for both teaching task design and model-based text generation.
Each template type followed a unified format to ensure its universality and adaptability across different teaching situations. The template contained four core elements: the first was the instruction target, which clearly indicated the required transfer task; the second was the sample input, which provided students with real language fragments as the corpus basis for the effectiveness of the instruction; the third was the target output, which showed the standard style of ideal language output after transfer for students to compare and use for model tuning; the fourth was the usage suggestion, which explained the language level, text type and usage strategy applicable to the template, and provided adjustable parameter prompts to enhance generation control and teaching guidance effect.
To further illustrate the design logic and practical application of the prompt templates, representative examples of five transfer-oriented prompts are presented below. All templates complied with the unified framework, which consisted of an instruction target, sample input, target output, and usage suggestion. Students were guided to expand simple sentences, convert sentence voices, and embed clauses to enrich syntactic diversity. For instance, given the student draft "I study English writing. It is very important for cross-cultural communication", the optimized output is "Learning English writing plays a vital role in improving learners’ ability of cross-cultural communication". This prompt was suitable for sentence-level training for sophomore English majors at a moderate difficulty level, focusing on basic syntactic reconstruction and voice transformation. Another type of prompt targeted cultural transfer, aiming to identify Chinglish expressions influenced by native cultural thinking and to rewrite sentences into natural English pragmatic expressions that conform to Western cultural norms. Taking the student sentence "Many people think you must work hard if you want to succeed" as an example, the revised version was "People generally believe that diligence is the key to success". This prompt was applied to cultural-level transfer training, focusing on eliminating implicit Chinese thinking patterns and fostering explicit expression in the English context.
This study also developed a three-stage nested prompt chain that took students’ paragraph drafts as unified input and ran in sequential phases. The first phase was semantic reorganization, with the prompt requiring the participant to rearrange sentences of the given paragraph, optimize the logical order of ideas, and form a complete paragraph with clear topic sentences. The second phase was linguistic revision, which asked to rewrite the revised paragraph into formal academic English, replace colloquial words, and appropriately use complex sentences and passive structures. The third phase was cultural adaptation, whose prompt guided users to check for cultural-pragmatic expressions in the text, remove native-language cultural interference, and polish the content to fit English cross-cultural writing conventions. The above examples fully demonstrated the operational modes of single-prompt templates and nested prompt chains. On this basis, the study designed a complete phased prompt chain combined with DeepSeek’s MoE architecture.
To overcome the limitations of single-round prompts in terms of generation control and task response depth, this study designed a nested prompt chain structure with phased and continuous characteristics, enabling hierarchical guidance and the gradual generation of complex transfer tasks. This mechanism broke down a complete transfer task into several sub-goals and designed corresponding prompt templates for each sub-goal, which were connected in series in the logical order of semantic reconstruction, language style adjustment, and cultural pragmatic adaptation, forming a generation chain with context dependence. This study implemented nested prompt chain optimization for DeepSeek through its standard open API. The DeepSeek model natively adopted a Mixture of Experts (MoE) architecture equipped with an automatic backend expert routing system, which operates as an inherent internal reasoning module independent of external prompts. The customized multi-stage prompts only adjusted the content characteristics of model inputs. Corresponding to the semantic, stylistic, and cultural requirements embedded in the optimized inputs, the model’s native MoE routing mechanism autonomously activated the most suitable expert modules during text generation. The three-stage prompt design focusing on semantic reorganization, stylistic adjustment, and cultural adaptation merely refined input texts and did not interfere with the model’s internal expert selection and allocation logic.
In terms of the operational process, the system received student texts uploaded by teachers, transferred target annotations, and automatically determined whether to enable the nested chain structure. If enabled, the system executed three stages in sequence: the first stage was semantic reorganization, calling the structure transfer template to optimize paragraph organization and logical clues; the second stage was language style adjustment, using the language template to convert colloquial expressions into academic written language; the third stage was cultural adaptation, calling the cultural transfer template to identify and replace expressions that do not conform to the target language culture, and generated more authentic text.
Each round of generation took the output of the previous round as input and retained the context vector cache to ensure semantic coherence. Teachers customized the prompt chain structure in the system interface, including template selection, instruction modification, and sequence adjustment. The system also supported the "template combination package" function, which was convenient for teachers to reuse or assign tasks in batches. Additionally, the system featured a built-in dynamic interruption and feedback mechanism that provided intermediate results after each generation. Teachers annotated or adjusted subsequent instructions in real time, forming a "generation-adjustment-regeneration" teaching closed loop.
Model generation, evaluation
In the text generation and evaluation process based on the DeepSeek model, this study constructed a multidimensional automatic scoring mechanism to systematically analyze and quantitatively evaluate generated text across three aspects: syntactic complexity, structural standardization, and discourse coherence. This study employed the spaCy dependency parser and the Coreferee coreference resolution extension module for text feature extraction and automated evaluation. The spaCy dependency parser parsed the syntactic structure of English text, extracting key indicators such as average sentence length and the number of nested clauses, enabling quantitative analysis of syntactic complexity. The Coreferee coreference resolution extension module, running within the spaCy framework, primarily identified internal referential relationships in text and assessed discourse referential coherence, providing technical support for automated writing quality scoring. Due to network limitations, the aforementioned overseas open-source websites were inaccessible.
First, the system evaluated syntactic complexity. It extracted features such as average sentence length, clause embedding depth, and sentence variety. These features were obtained through dependency parsing and deep syntactic tree modeling. Based on the results, the system assessed whether students have successfully progressed from simple sentence patterns to more complex structures. Second, the system evaluated paragraph organization. It combined BERT-based text representations with classification models to identify key paragraph elements, including topic, supporting, and concluding sentences. A paragraph structure map was then constructed to determine whether the organization conformed to the conventions of English academic writing. Third, the system assessed textual coherence. It examined the use of logical connectives, semantic consistency between sentences, and the quality of referential links throughout the text. These indicators were used to evaluate the clarity of logical development and the smooth progression of ideas. To measure topic consistency, the system calculated semantic similarity using vector-based representations. Referential coherence was evaluated through coreference resolution techniques, which helped reduce semantic gaps and ambiguous references. Finally, scores from all dimensions were integrated into a unified scoring vector. The results were standardized to form a comprehensive evaluation system, enabling reliable comparison across different writing samples.
In the manual evaluation phase, this study developed a three-dimensional scoring system for writing transfer training, encompassing the obviousness of transfer behavior, naturalness of expression, and cultural adaptability, to enhance the relevance of teacher evaluation and the effectiveness of teaching feedback. The system combined its auxiliary functions to achieve an organic combination of quantitative scoring and qualitative comments. In the transfer behavior dimension, teachers judged students' use of transfer strategies in rewriting texts based on preset task objectives. The system provided a side-by-side comparison view of the original text and the generated version to assist teachers in identifying whether operations such as sentence adjustment and structural reconstruction effectively reflected the required transfer type.
The evaluation of natural expression focused on the fluency and authenticity of language output. Teachers used the language indicators generated by the system to evaluate whether the sentences conformed to the expression habits of native English speakers and to judge whether the grammatical structure, word collocation, and sentence rhythm were natural and appropriate. They also pointed out problems and suggested alternative expressions through annotations. The cultural adaptability dimension focused on the appropriateness of cross-cultural pragmatics. Teachers needed to identify whether the text contains inappropriate expressions resulting from interference from the source-language culture, such as semantic ambiguity, rhetorical conflicts, or vague value judgments. The system provided common cultural deviation word examples and supported teachers to explain the basis for modification and cultural context requirements in the comments, guiding students to improve cultural transfer awareness and expression accuracy. Each dimension was scored on a 5-point scale and included free annotations and suggested fill-in modules. The final evaluation results were presented as a radar chart.
To improve evaluation efficiency and support practical classroom use, this study developed a collaborative assessment mechanism that combined AI-based scoring with teacher evaluation. The system first performed a multidimensional assessment of the text generated by DeepSeek. It evaluated key aspects such as syntactic complexity, paragraph organization, and textual coherence through the automatic scoring module. The scoring results were then displayed in real time on the teacher interface. Teachers reviewed the detailed scores for each dimension and adjusted them when necessary based on their professional judgment and understanding of students’ transfer performance. They also added targeted comments directly to the text to provide feedback and instructional suggestions that might not be captured by automatic scoring. Each evaluation dimension adopted a five-point rating scale. The interface also included free-text annotation and recommendation modules to facilitate personalized feedback. The evaluation results were visualized through a radar chart, allowing teachers to quickly identify students’ strengths and weaknesses across different transfer dimensions.
In addition, the system allowed teachers to adjust the weighting of specific dimensions or the overall scores to align with instructional goals. This feature ensured that the final evaluation more accurately reflected students’ actual performance and learning needs. After manual review was completed, the system automatically integrated machine-generated and teacher-generated assessment data. It then produced a visual feedback report. The report included a transfer-performance radar chart and a version-tracking chart. These visualizations clearly illustrated changes in students’ transfer abilities across multiple rounds of text generation and revision, enabling continuous monitoring of learning progress.
Transfer training process
This study designed a complete transfer training process. First, the teacher assigned specific English writing tasks based on the teaching objectives and students' actual level, and clarified the transfer type and focus of the training. Then, the system automatically generated corresponding prompt instructions based on the tasks set by the teacher and called the DeepSeek model to generate a first draft of the writing, serving as the basic material for students' rewriting and transfer training. After receiving the first draft, students needed to actively identify the transfer features reflected in the text and rewrite the content in a targeted manner, using the transfer strategies they have learned to improve the appropriateness of syntactic structure, paragraph organization, and cultural expression. After completing the rewriting, the teacher provided a detailed review of the student's submitted text, highlighting the effectiveness of the transfer strategy and offering specific suggestions for improvement and writing guidance. Based on the teacher's feedback, the DeepSeek model was reinvoked to generate an optimized version, further supporting students in refining their texts and deepening their practice of transfer strategies. Finally, the student completed the submission of the final draft, filled in the transfer cognition table, self-evaluated, and summarized the transfer methods and their effects, and promoted the improvement of metacognitive ability and the internalization of writing transfer skills. The transfer cognition table designed for this study is shown in Table 2.
All items adopted a 1–5 rating scale ranging from 1 (no mastery) to 5 (full mastery). Self-assessment data were collected after three rounds of sequential training; scoring benchmarks refer to pre-defined transfer operation standards in the five-dimensional task library.
Results
Teaching experiment design
This study used the basic open-source version of DeepSeek, relying on the platform's open API interface for program calls. The complete set of five prompt template texts, four levels of task example entries, transfer annotation category tags, and writing error-template matching mapping rules were compiled in the supplementary appendix. The system had fixed calling parameters: a temperature coefficient of 0.7, and the generated length was dynamically limited based on the writing question type. It strictly followed a fixed sequence of semantic reconstruction > stylistic adjustment > cultural adaptation, executing nested prompt chain calls. The model output was manually selected by the instructor for effective text in classroom teaching.
This study invited three full-time university-level English writing teachers with more than 5 years of experience to participate in manual scoring. All scorers received standardized training before the official scoring, familiarizing themselves with the assessment dimensions, the 5-point scoring system, cultural transfer, syntax, discourse, and other scoring details, and completed pre-scoring calibration. All student essays were scored independently by two teachers in a blind, double-blind scoring mode. If the difference between the two scorers' scores exceeded 1 point (out of 5), a third senior teacher would arbitrate the scoring, and the average of the two valid scores would be taken as the final manual score for that sample. Two groups of raters were involved in the evaluation phase for different research purposes. Three full-time university English writing teachers with over 5 years of teaching experience conducted blind, double-scoring of all student writing samples in the formal experiment, and a third senior teacher served as an arbitrator when scoring discrepancies exceeded 1 point on the 5-point scale. In contrast, five raters participated in the inter-rater reliability test using the Intraclass Correlation Coefficient (ICC), which was conducted separately to verify the consistency of evaluation standards across assessors. The difference in the number of raters stems from distinct functional requirements: three core teachers ensured the practical scoring of experimental data, while the expanded five-rater panel provided more robust evidence for the reliability of the whole evaluation system.
Syntactic complexity, BERT text structure scoring, and semantic similarity are all scored within a 0–5 point range. The weights for each dimension were set according to foreign language writing teaching and research standards: syntax 0.35, text structure 0.35, and logic and culture 0.3. The weight values were based on mature quantitative evaluation systems for writing in the same field. The AI automatic scoring module was calibrated using thresholds based on 15 pre-classified model essays. The human scoring followed a unified five-point grading scale. The machine scoring and human calibration were combined for a pre-experiment verification before the formal evaluation.
The teaching task was carried out around the three-level transfer goals of "syntax-structure-culture", with three rounds of training, each lasting one week. The first round involved sentence-level rewriting to improve syntactic diversity and expression accuracy; the second round entailed paragraph-level structural reconstruction to enhance paragraph organization and logical coherence; the third round involved cultural-level transfer to strengthen cross-cultural pragmatic awareness and expression adaptability. Given repeated measurements collected from identical participants across pre-test, three sequential training rounds, and post-test, repeated-measures analysis of variance (RM-ANOVA) was adopted as the primary statistical approach to examine main effects of group (experimental vs. control), main effects of testing time, as well as the group × time interaction effect, which reflected whether score changes over training differed between the two cohorts. The sphericity assumption was verified via Mauchly’s test; Greenhouse–Geisser correction was applied if sphericity was violated. Independent-samples t-tests were reserved only for post-hoc pairwise between-group comparisons at individual time points, while Pearson correlation and Cohen’s d remained for scoring consistency and effect size quantification, respectively.
All statistical analyses were pre-specified before data collection. Independent-samples t-tests were adopted to compare pre-post writing indicators between two groups, with the primary null hypothesis assuming no inter-group differences in writing transfer performance. Pearson correlation analysis was used to quantify the linear association between AI automatic scoring and teacher manual ratings, and Cohen’s d was calculated as the standardized effect size for between-group comparisons. The significance threshold was set at α = 0.05 for all hypothesis testing, and 95% confidence intervals were computed alongside all test statistics. SPSS 26.0 was utilized to conduct all statistical calculations. No missing data occurred across student test scores and questionnaire datasets, as all participants finished the full three-round training and relevant assessments; hence, no imputation or case deletion for missing values was required.
Construction of the evaluation index system
To comprehensively evaluate students' performance in English writing transfer training, this study constructed a multidimensional evaluation system that covered the three-level transfer goals of "syntax-structure-culture", integrated language ability, model response, teaching feedback, and self-cognition, and established six core indicators. First, the "writing transfer index" was a comprehensive evaluation indicator that covered syntactic diversity, structural clarity, and cultural adaptability, combining the system's automatic scoring and the teacher's manual scoring for quantitative analysis. The "syntactic complexity score" utilized natural language processing technology to extract features such as average sentence length, the number of clause nesting levels, and the frequency of verb phrase use to evaluate the richness and complexity of students' sentences. The "academic style matching" analysis examined the proportion of passive voice use and the proportion of formal vocabulary, based on an NLP (Natural Language Processing) model, to determine whether the text adhered to the style norms of English academic writing. In addition, the study introduced a subjective evaluation dimension, collecting feedback on the acceptance and practicality of the model-generated suggestions through teacher questionnaires to assess the actual impact of AI-assisted teaching. "Changes in teacher review scores" reflected the impact of AI-assisted teaching on the improvement of writing quality by comparing teachers' scores on students' essays before and after the experiment. Finally, "Student self-evaluation of transfer ability" utilized the transfer cognition table to guide students in self-evaluating their mastery of structure, syntax, culture, and other dimensions, thereby enhancing their metacognitive awareness and reflection abilities. The specific descriptions and data sources for each indicator are shown in Table 3.
Syntactic and stylistic indicators were automatically calculated via dependency parsing and BERT-based classification, with normalized scores ranging from 0 to 5; manual evaluation uses a 5-point scale. Calculation formulas for syntactic complexity used the total word count/clause count as the core denominator. Raw data source: pretest & posttest writing compositions of all 60 enrolled students.
Experimental results and analysis
To intuitively present the comprehensive performance differences of students in the three dimensions of syntactic transfer, structural transfer, and cultural transfer, Figure 3 compared the average writing transfer index of students in the experimental group and the control group before and after the experiment: Figure 3 showed the difference in average scores between the experimental group and the control group in the three dimensions of syntactic transfer, structural transfer, and cultural transfer. The experimental group showed a significant improvement in transfer ability in each dimension after the experiment, and the outer circle of the radar chart is significantly larger than the inner circle, indicating that the instruction optimization method based on the DeepSeek model has a positive effect in promoting the development of students' English writing transfer ability. In contrast, the control group's various transfer ability indicators remained relatively unchanged before and after the experiment. The overall improvement was limited, indicating that traditional teaching methods or AI-assisted tools that had not optimized system instructions have a limited role in transfer training. It was challenging to effectively stimulate students' learning potential in multidimensional language transfer.
The average writing transfer indexes of the experimental group in the dimensions of syntactic transfer, structural transfer, and cultural transfer before the experiment were 3.0, 2.9 and 2.8, respectively, which increased to 4.3, 4.1, and 4.5 after the experiment, with increases of 1.3, 1.2, and 1.7, respectively, indicating that the teaching method had a good intervention effect at different levels of transfer. The control group's scores before the experiment were 3.0, 3.0, and 2.9. After the experiment, the values increased to 3.4, 3.3, and 3.2, respectively, which are significantly lower than those of the experimental group. It is particularly noteworthy that in the dimension of cultural transfer, the experimental group showed the most significant improvement, increasing from 2.8 to 4.5, a 1.7-point increase, which is significantly higher than the 0.3-point increase of the control group. This result suggested that the proposed teaching method plays a significant role in helping students identify and adapt to English cultural expression norms. It was not only reflected in adjustments to language form but also in the enhancement of students' cross-cultural pragmatic awareness and the depth of their understanding of the target language's cultural expression habits. Language transfer was primarily reflected in syntactic complexity, language style adaptation, and other aspects. The study utilized automated NLP technology to conduct an in-depth analysis of students' writing texts, extracted key language features, and combined teacher scores to systematically evaluate changes in students' language transfer ability across three rounds of tasks.
Syntactic complexity and linguistic style
In terms of syntactic complexity, the study recorded the average sentence length and number of clause nesting levels of the text generated by students after completing the designated writing task in each round of tasks. These two indicators were widely used to measure the complexity of language expression. They effectively reflected the development level of students in sentence diversity and structural organization ability, as shown in Figure 4.
In the longitudinal evolution of syntactic complexity, the experimental group exhibited a clear upward trend in the three rounds of tasks, reflecting the effective promotion of transfer training on students' ability to express their language structure. From the perspective of average sentence length, the experimental group increased from 12.5 words in Task 1 to 16.1 words in Task 3, representing a 3.6-word increase, which was significantly higher than the control group's increase of only 0.9 words in the same period (from 12.4 to 13.3). Similarly, from the perspective of the structural complexity dimension, measured by the number of clause nesting layers, the experimental group increased from 1.8 layers to 2.7 layers, while the control group increased from 1.7 to 1.9 layers, with a relatively slow increase. To further verify whether the difference in syntactic complexity between the two groups of students is statistically significant, the study employed independent sample t-tests to analyze the average sentence length and the number of clause nesting levels at the three stages of the task. The results showed that there is a significant difference between the experimental group and the control group in terms of average sentence length, t(58) = 4.23, p < 0.001, Cohen’s d = 0.98; there was also a significant difference in the number of clause nesting levels, t(58) = 3.15, p = 0.002, Cohen’s d = 0.78. This comparison showed that systematic transfer training not only improved students’ ability to construct complex sentences but also strengthened their mastery of grammatical organization strategies. In particular, during the third stage of the task, students in the experimental group demonstrated greater flexibility in using multi-layered clauses and complex sentence structures. This reflected a notable shift in their language transfer from a “functional” level to a more “strategic” level. The transfer-oriented training pathway continuously enhanced students’ syntactic transfer skills, effectively overcoming the limitations of single-sentence writing and the fixed expression patterns often seen in traditional teaching. In terms of language style adaptation, the study extracted students' writing texts before and after the experiment. It used the NLP model to determine the proportion of formal vocabulary and the frequency of passive voice use as core indicators for evaluating academic language style matching. These indicators reflected whether students have the language awareness and expression ability to adapt to the target style in English writing. The relevant results are shown in Figure 5.
Figure 5 shows the changes in the academic style matching of the experimental group and the control group before and after the task, mainly focusing on the two core indicators of formal vocabulary proportion and passive voice usage frequency. Overall, after completing transfer training based on the DeepSeek model, the academic style adaptation ability of the experimental group was significantly improved, demonstrating the effectiveness of this teaching method in cultivating students' awareness of language norms and their ability to adapt to academic styles. Regarding the proportion of formal vocabulary, the experimental group increased from 0.42 before the task to 0.56 after the task, a relatively significant increase. In contrast, the control group increased only slightly, from 0.43 to 0.48, suggesting a limited improvement. This result showed that after receiving systematic prompt guidance and model feedback, the students in the experimental group were more inclined to use formal vocabulary that meets the requirements of academic style in the writing process, and their language style gradually approached the standards of English academic writing. In terms of the frequency of passive voice use, the experimental group increased significantly from 0.18 before the task to 0.27 after the task, representing an increase of 0.09; in contrast, the control group increased by only 0.02.
To further verify whether the above changes are statistically significant, the study conducted an independent sample t-test on the data before and after the task. The results showed that the experimental group had a significant improvement in the proportion of formal vocabulary, t(58) = 3.89, p < 0.001, Cohen's d = 0.92; the increase in the frequency of passive voice use was also significant, t(58) = 4.56, p < 0.001, Cohen’s d = 1.05. This showed that the students in the experimental group had made substantial progress in language style adaptation, and this progress was not accidental, but the result of the combined effect of systematic prompt guidance and model feedback.
Statistical verification
In addition, to further verify the reliability of AI-generated content in teaching practice, the study also compared the mean scores of AI-generated content and teacher-generated content under different prompt types. The consistency between the two was evaluated by calculating the Pearson correlation coefficient. The relevant comparison results are shown in Table 4. Table 4 shows the consistency of AI-generated content and teacher scores in five types of transfer-oriented prompts. From the perspective of the mean score, the AI score was slightly lower than the teacher score overall. Still, the gap was within a reasonable range in most task types, indicating that the DeepSeek model has high stability and reference value in evaluating writing transfer tasks. Under the syntactic transfer prompt, the average teacher score was 4.1, and the AI score was 4.0, with a difference of only 0.1 between the two. In the structural and logical transfer prompts, the AI score was only 0.1 points lower than the teacher's score, indicating that the model can better simulate the teacher's evaluation criteria in these tasks, which involve a high degree of language structure and clear rules. In contrast, the scoring deviations under the cultural transfer and register transfer prompts are relatively obvious, with AI scores of 3.6 and 3.7, respectively, which are 0.2 lower than the teacher's scores, reflecting that AI still had certain limitations when dealing with tasks with high subjectivity, such as semantic implications and cultural pragmatics. Inter-rater reliability was assessed via ICC (n = 5 raters). The overall ICC for manual scoring was 0.86, and ICCs for each dimension ranged from 0.82 to 0.89, indicating satisfactory inter-rater agreement.
Further analysis of the Pearson correlation coefficient revealed that the consistency of the scores under various prompts was at a high level, indicating that the AI score was not only close to the teacher's judgment in terms of value but also exhibits a good linear relationship in its scoring trend. Among them, the consistency coefficient of the syntactic transfer prompt was the highest at 0.87, and the structural transfer and logical transfer prompts were also 0.83 and 0.85, respectively, indicating that the AI's evaluation results in terms of syntactic complexity, paragraph organization, and logical coherence are highly consistent with the teacher's judgment. This may be because these tasks have clear objectives and quantifiable language features, which facilitated model recognition and stable judgment. The correlation coefficient of the domain transfer prompt is 0.81. Although it had decreased slightly, it still demonstrated a strong evaluation ability, indicating that AI possessed a certain degree of judgment at the level of stylistic adaptation. However, the consistency coefficient of the cultural transfer prompt was only 0.79, which was lower than other types, but still within an acceptable range.
To examine the applicability of different types of prompts in teaching practice and the degree of acceptance by teachers, a prompt response satisfaction questionnaire was designed. Five English teachers (numbered T1–T5) were invited to rate the generation suggestions of five types of prompts using a five-level scale (very dissatisfied to very satisfied), as shown in Figure 6: the scores of the five teachers on the five types of prompts vary somewhat, but overall recognition was high. Among them, the "syntactic transfer" and "cultural transfer" prompts scored the highest, with an average of 4.0, reflecting strong practicality and adaptability in teaching. In contrast, the "register transfer" prompt scores relatively low, averaging only 2.4, and some teachers, such as T4 and T5, gave the lowest scores, indicating that its guidance and adaptability in teaching applications still need improvement.
At the individual level, there were obvious differences in teachers' scoring tendencies. T1's overall score was positive, indicating a high degree of acceptance of AI-assisted writing, while T5's scores were low in multiple Prompt dimensions, especially in "register transfer" and "logic transfer". This difference might be related to teachers' teaching experience, language preference, or familiarity with AI tools, suggesting that future Prompt design needs to consider personalized adaptation mechanisms to enhance the acceptance of different teacher groups. To further verify the actual effect of AI-assisted teaching on improving students' writing quality, the study compared the changes in overall scores of the experimental group and the control group, as evaluated by teachers, before and after the experiment. The comparison results are shown in Figure 7.
As shown in Figure 7, the overall scores of the experimental group and the control group, as evaluated by teachers before and after the experiment, showed significant differences. Overall, after the instruction optimization teaching intervention based on the DeepSeek model, the experimental group's overall score showed a significant upward trend. In contrast, the score change in the control group was relatively gentle. The average teacher score of the experimental group before the experiment was 59.1 points, and the average score after the experiment increased significantly to 74.4 points, representing a 15.3-point increase. This indicated that AI-assisted teaching had a positive impact on students' writing quality. From the box plot, it was observed that the distribution range of the experimental group's scores had also expanded. In particular, the score box after the experiment is significantly higher than before, and the upper maximum and lower minimum values have increased, indicating that the overall level of students has improved significantly. In contrast, the score changes in the control group were relatively limited. Before the experiment, the average score of the control group was 60.1 points, and after the experiment, it was 64.9 points, representing a 4.8-point increase. This increase was much lower than that of the experimental group, and the scoring box of the control group did not change much before and after the experiment, indicating that traditional teaching methods or unoptimized AI-assisted tools have a limited effect on improving writing quality.
In addition, this study utilized the transfer cognition table to guide students through three rounds of self-assessment on their ability development in structural adjustment, sentence transformation, and cultural expression, among other areas, to reflect the changing trend of students' metacognitive awareness and their mastery of transfer strategies. The results are shown in Figure 8. According to the radar chart data of students' self-assessment of transfer ability shown in Figure 8, the self-assessment of students in the five dimensions of structural transfer, syntactic transfer, cultural transfer, register transfer and logical transfer in the three rounds of tasks showed a continuous increasing trend, indicating that under the instruction optimization teaching intervention based on the DeepSeek model, students' ability to use transfer strategies had been significantly improved. In the first round of tasks, the students' self-assessment scores were generally low. Among the five dimensions, "structural transfer" and "logical transfer" score 3.2 and 3.0, respectively, while "cultural transfer" and "register transfer" score 2.5 and 2.7, indicating that students were still immature in identifying and using transfer strategies. By the second round of tasks, the scores of each item had improved, with "structural transfer" rising to 3.8, "syntactic transfer" to 3.5, and "logical transfer" to 3.7. This showed that with the guidance of teachers and the support of model feedback, students had gradually mastered the key points of basic transfer operations and had initially applied them to actual writing. In the third round of tasks, students' self-evaluation scores increased significantly, with "structural transfer" and "logical transfer" reaching 4.5 and 4.3, respectively, and the other dimensions also stabilized above 4.0 points, showing the sustained effect of multiple rounds of transfer training in improving students' language form control and text construction ability. At this stage, students had formed a basic cognitive closed loop between understanding, execution, and reflection of transfer strategies. In addition to teacher feedback, the study also distributed a satisfaction survey questionnaire about the AI-assisted writing function to all students in the experimental group, and a total of 30 valid questionnaires were collected. The questionnaire assessed the performance of AI in three functional modules: rewriting suggestions, structural optimization, and cultural prompts, and requires students to select options according to five levels of standards. The results are shown in Table 5.
According to the results of the student satisfaction survey on AI-assisted writing functions shown in Table 5, students in the experimental group generally gave positive comments on the performance of AI in the three functional modules of rewriting suggestions, structural optimization, and cultural prompts, showing the good application prospects of AI-assisted writing systems in improving writing training efficiency and teaching support quality. Overall, more than 90% of students expressed "very satisfied" or "satisfied" in the two functional items of "rewriting suggestions" and "structural optimization", among which "rewriting suggestions" had the highest satisfaction, reaching 91%, indicating that students had a high degree of recognition of AI's ability in syntactic reconstruction and language polishing. In comparison, the satisfaction with the "cultural prompts" function was relatively lower. Still, it reached 83%, indicating that although AI has certain complexity and subjectivity in guiding cross-cultural expression, its role in assisting students to identify and adjust for native-language cultural interference was still recognized by most students. In terms of dissatisfaction, the percentage of students who chose "dissatisfied" or "very dissatisfied" across the three functions was less than 5%, indicating that AI-assisted functions had good usability and acceptance in most application scenarios. It is worth noting that the proportion of students who rated "average" in the "cultural prompts" item was relatively high, suggesting that the current AI might not fully meet students' expectations when dealing with cultural adaptation issues, and there was still room for improvement. A comprehensive analysis reveals that the DeepSeek-based instruction optimization method has been widely recognized by students, particularly for its support of language form.
RM-ANOVA
A two-way repeated-measures analysis of variance (RM-ANOVA) was conducted to examine the effects of group (between-subjects factor: experimental group vs. control group) and time (within-subjects factor: pre-test, Task 1, Task 2, Task 3, post-test), as well as their interaction on students’ English writing transfer performance. Mauchly’s test indicated a violation of the sphericity assumption (p < 0.05), so the Greenhouse–Geisser correction was applied to adjust the degrees of freedom for within-subjects effects. All analyses were based on n = 30 participants per group. The results are shown in Table 6:
The results of the repeated-measures ANOVA with Greenhouse–Geisser correction indicated significant main effects of Group, Time, and Group × Time interaction across all measured dimensions (p < 0.001). For the Overall Transfer Index, a significant Group effect was observed (F(1,58) = 76.32), alongside a significant Time effect (F(2.14,124.12) = 92.75) and a significant Group × Time interaction (F(2.14,124.12) = 68.49), suggesting that changes in overall transfer performance over time differed significantly between groups.
Similarly, syntactic transfer showed significant effects of Group (F(1,58) = 52.18), Time (F(2.11,122.38) = 71.26), and Group × Time interaction (F(2.11,122.38) = 45.73), indicating differential development patterns in syntactic transfer ability across groups and measurement points. For Structural Transfer, significant Group (F(1,58)=48.65), Time (F(2.09,121.22) = 67.81), and interaction effects (F(2.09,121.22) = 41.36) were also identified, reflecting consistent improvements with group-dependent trajectories. Notably, Cultural Transfer exhibited the strongest effects, with a significant Group effect (F(1,58) = 81.44), a pronounced Time effect (F(2.07,119.96) = 98.52), and a robust Group × Time interaction (F(2.07,119.96) = 79.27), suggesting the most substantial and differentiated growth pattern in this dimension. Overall, all indices demonstrate statistically significant effects, confirming that the intervention exerted a stable and differentiated impact on transfer development over time.
DATA AVAILABILITY:
All data generated or analyzed during this study are included in this article. The raw evaluation data are provided in Supplementary Table 1.
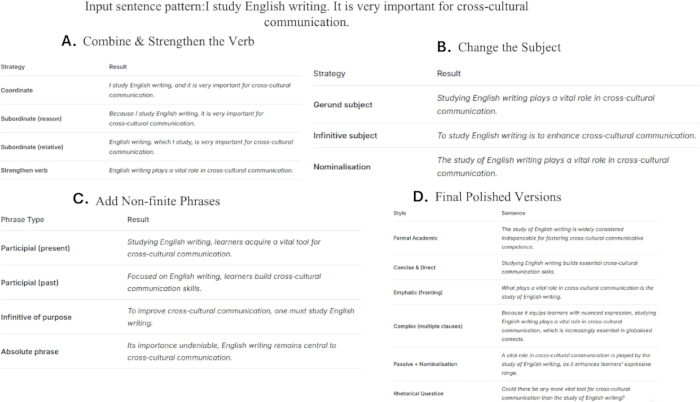
Figure 1: Steps for sentence structure transformation. (A) Strategies for combining and strengthening verbs to improve sentence structure. (B) Alternative subject transformations, including gerund, infinitive, and nominalized subjects. (C) Use of non-finite phrases to enhance sentence variety and conciseness. (D) Examples of polished final versions demonstrating improved academic style and cross-cultural English expression. Please click here to view a larger version of this figure.
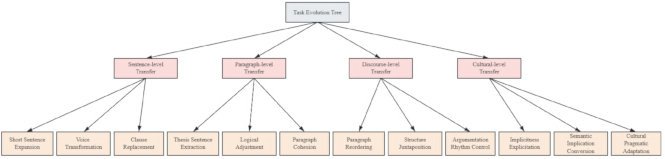
Figure 2: Task evolution tree diagram. It presents the progressive structure of four-tier transfer tasks ranging from sentence, paragraph, discourse, to the cultural level. Please click here to view a larger version of this figure.
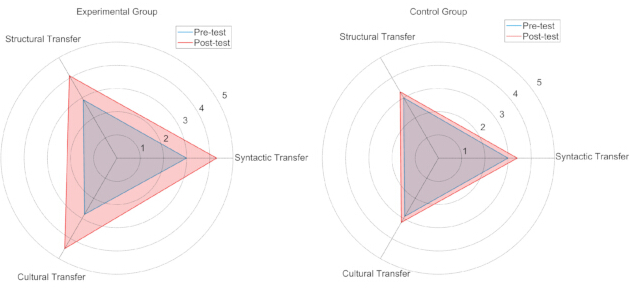
Figure 3: Comparison of writing transfer ability before and after the experiment. The radar chart shows pre-test and post-test scores of the experimental group and control group in syntactic, structural, and cultural transfer dimensions. Please click here to view a larger version of this figure.
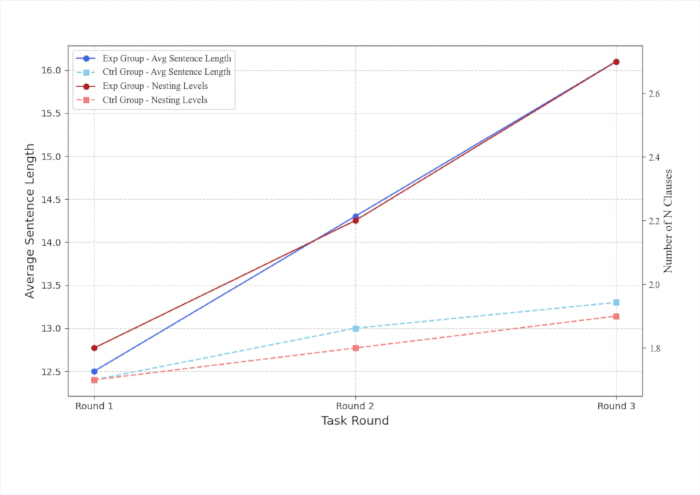
Figure 4: Syntactic complexity trend line chart. Changes in average sentence length and clause nesting layers across three training tasks are displayed. Please click here to view a larger version of this figure.
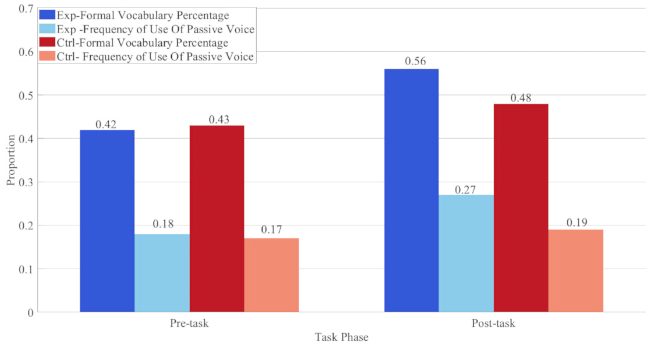
Figure 5: Academic terminology matching. This figure shows variations in the proportion of formal vocabulary and the frequency of passive voice before and after the intervention. Please click here to view a larger version of this figure.
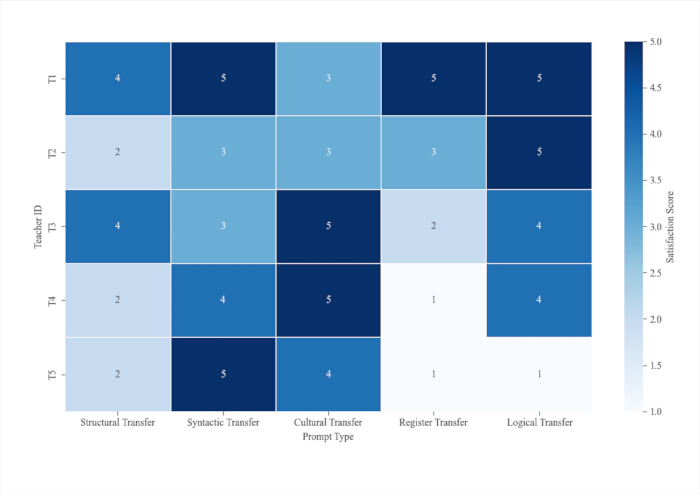
Figure 6: Prompt response satisfaction heat map. Ratings of five types of prompt templates from participating teachers are summarized here. Please click here to view a larger version of this figure.
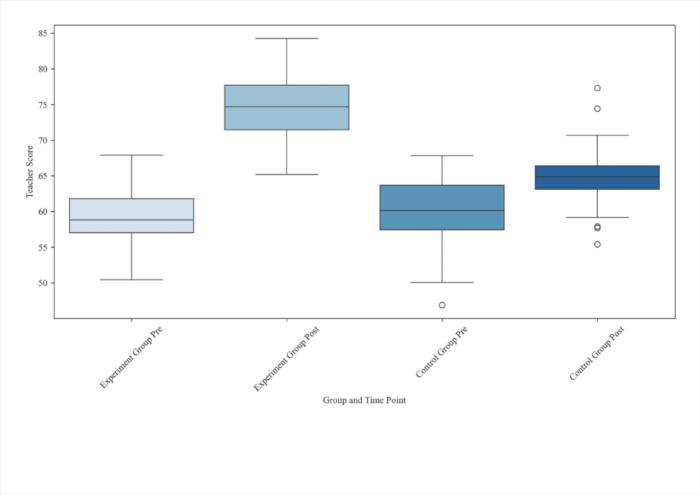
Figure 7: Box plot of changes in teacher ratings. The box plot demonstrates the distribution and overall changes of teacher-assessed writing scores for two groups pre- and post-experiment. Please click here to view a larger version of this figure.
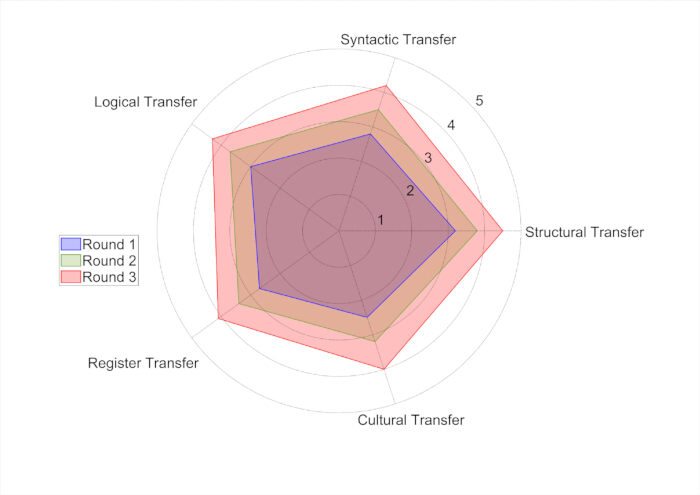
Figure 8: Radar chart of students' self-assessed transfer ability. It shows students’ self-evaluation scores across five transfer dimensions in three training rounds. Please click here to view a larger version of this figure.
| Input | Teacher Operation | Prompt Type | Student Operation | Output | Evaluation Criteria |
| Students’ original writing drafts (sentences/paragraphs/essays) | 1. Label transfer types and task levels2. Adjust prompt parameters if needed | Single transfer prompt / Three-stage nested prompt chain | 1. Learn transfer strategies 2. Revise drafts based on AI feedback 3. Complete self-assessment | AI revised text + Student revised final draft | Syntactic complexity, structural rationality, cultural appropriateness, logical coherence, register standardization (0–5 scale) |
Table 1: Workflow Summary Table. This table summarizes the complete operational workflow of the AI-assisted English writing transfer training, covering input materials, teacher and student operations, prompt types, final outputs and corresponding evaluation criteria.
| Project Category | Contents |
| Understanding of mission objectives | Please briefly describe the migration goals of this round of writing tasks, such as structural adjustment, cultural adaptation, and language conversion. |
| Migration strategy used | Please list the migration strategies you adopted (multiple selections are allowed): |
| Structural Adjustment | |
| Sentence transformation | |
| Language switching | |
| Cultural manifestation | |
| Strengthening logical connection | |
| Other:_______ | |
| Rewrite examples and instructions | Select 1–2 rewritten sentences, show the versions before and after the rewrite, and explain the reasons for the changes and the desired transfer goals. |
| Difficulties and doubts encountered | Describe any challenges you encountered during the migration or questions you had about a specific expression. |
| Self-assessment score (out of 5 points) | Please rate your text rewriting based on the following three aspects: |
| • Strategy application accuracy (/5) | |
| • Natural fluency of expression (/5) | |
| • Cultural fit (/5) | |
| Future writing improvement goals | Briefly describe the transferability you would like to strengthen or optimize in the next round of training |
Table 2: Transfer cognition table. A 1–5 rating scale (1 = no mastery, 5 = full mastery) is adopted for students’ self-assessment of writing transfer strategies.
| Indicator name | Description | Data Source |
| Writing transfer Index (0–5) | A quantitative indicator that comprehensively measures language transfer ability, covering three levels: syntax, structure, and culture. | Automatic scoring by the system + manual scoring by teachers |
| Syntactic complexity score | Including average sentence length, number of clause embeddings, verb phrase richness, etc. | NLP automatic analysis |
| Academic style matching | Does it conform to English academic writing standards? | Natural language processing model judgment |
| Prompt response satisfaction | Teachers’ acceptance and practical evaluation of model-generated suggestions | Teacher Questionnaire |
| Teacher review grading changes | Comparison of teacher scores before and after the experiment to reflect the improvement in writing quality | Teacher Rating Records |
| Students' self-assessed transfer ability | Students self-assess their mastery of different transfer dimensions | Fill out the migration awareness form |
Table 3: Summary of evaluation indicators, descriptions, and data sources. This table clarifies the definitions, measurement methods, and original data sources for each core evaluation indicator in this study.
| Prompt type | Teachers' average rating | AI score average | Pearson correlation coefficient |
| Structural transfer | 4 | 3.9 | 0.83 |
| Syntactic transfer | 4.1 | 4 | 0.87 |
| Cultural transfer | 3.8 | 3.6 | 0.79 |
| Register transfer | 3.9 | 3.7 | 0.81 |
| Logical transfer | 4.2 | 4.1 | 0.85 |
Table 4: Comparison of consistency between AI-generated content and teacher ratings. The results demonstrate the consistency between AI-generated content and teacher ratings across different Prompt types.
| Function items | Very satisfied | Satisfied | Generally | Dissatisfied | Very dissatisfied |
| Rewrite suggestion | 66% | 25% | 7% | 1.50% | 0.50% |
| Structural optimization | 60% | 30% | 7% | 2% | 1% |
| Cultural tips | 55% | 28% | 12% | 3.50% | 1.50% |
Table 5: Survey statistics on students' satisfaction with AI-assisted functions. The statistics show the distribution of student satisfaction for AI rewriting, structural optimization, and cultural prompt functions.
| Measure | Group F(df) | Time F(df)GG | Group × Time F(df)GG | p |
| Overall Transfer Index | 76.32 (1, 58) | 92.75 (2.14, 124.12) | 68.49 (2.14, 124.12) | <0.001 |
| Syntactic Transfer | 52.18 (1, 58) | 71.26 (2.11, 122.38) | 45.73 (2.11, 122.38) | <0.001 |
| Structural Transfer | 48.65 (1, 58) | 67.81 (2.09, 121.22) | 41.36 (2.09, 121.22) | <0.001 |
| Cultural Transfer | 81.44 (1, 58) | 98.52 (2.07, 119.96) | 79.27 (2.07, 119.96) | <0.001 |
Table 6: Summary of repeated-measures ANOVA results. It presents the two-way repeated-measures ANOVA results for overall writing transfer performance and its three sub-dimensions, including main effects of group, time, and the group-by-time interaction. Abbreviations: GG = Greenhouse–Geisser correction.
Supplementary Table 1: Raw data evaluation. Includes the raw data used in all analyses in this study.Please click here to download this file.
Discussion
This research constructs a multi-level instruction optimization framework grounded on DeepSeek’s MoE architecture for cross-cultural English writing transfer teaching. Centered on four-tier progressive tasks ranging from sentence to cultural dimension and a five-category standardized task library, the research realizes automatic prompt generation based on real student writing samples and establishes three-stage nested prompt chains to decompose complicated cross-cultural adaptive tasks. Different from conventional generic prompt design confined to text polishing, the proposed solution binds prompt compilation closely with language transfer teaching objectives and builds a closed-loop teaching flow of model generation, teacher annotation, and student iterative revision. From a disciplinary progress perspective, the present work expands the practical boundary of prompt engineering in second language acquisition, supplying a quantifiable template construction path for combining large language model parameter characteristics with EFL classroom targeted training. It also enriches empirical evidence for cross-cultural pragmatic transfer research under AI auxiliary environment, supplementing existing research findings focusing merely on syntactic negative transfer errors36,37.
Empirical quasi-experiment data confirm that the experimental group obtained obvious promotion across syntactic, structural, and cultural transfer indicators, yet several inherent constraints restrict the generalizability of research outcomes. Limited by research conditions, the study adopted non-randomized class grouping without evaluator blinding arrangement, and all samples were selected from English majors of a single university, which makes it difficult to exclude interference from learners’ autonomous learning motivation and long-term teacher teaching habits during score variation. In addition, this intervention only lasted for three weeks, representing a short-term training program. Combined with the single-center sampling design that all participants were recruited from one vocational college, the observed positive effects may not be fully stable in long-term teaching practice. Therefore, the research findings should be interpreted with caution, and it is inappropriate to directly generalize the conclusions to different types of colleges, longer teaching cycles, or student groups with varied language proficiency.
In practical teaching deployment, the current prompt optimization system combined with the DeepSeek model presents noticeable limitations and typical failure cases. In terms of cultural and register transfer tasks, the model occasionally produces pragmatically inappropriate expressions or rigid style conversion results when processing texts with subtle cultural connotations and context-dependent stylistic demands38,39; it also fails to accurately identify implicit native cultural thinking in long and complex paragraphs, leading to incomplete revision of Chinglish expressions. In automatic scoring, the consistency of AI evaluation drops significantly for highly subjective cultural pragmatic items, and it cannot effectively distinguish nuanced differences in rhetorical expression and cross-cultural implication. Additionally, the three-stage nested prompt chain is prone to semantic deviation in multi-round iterative generation, where errors from the first stage of semantic reorganization will be inherited and amplified in subsequent linguistic revision and cultural adaptation steps40,41.
In terms of follow-up development trend, further improvement can be launched from three practical dimensions. First, expand the scale of the task library by collecting a writing corpus from non-English majors and students with different language proficiency levels to strengthen template compatibility for diversified learner groups. Second, combine continual fine-tuning of lightweight DeepSeek submodules to lower the deviation existing in AI cultural transfer scoring, which has been found weaker in consistency compared with teacher evaluation in the present statistics. Third, embed the whole prompt optimization system into conventional online foreign language learning platforms to realize automatic long-term data accumulation for continuous iterative optimization of prompt rules. With the continuous enrichment of cross-lingual cultural corpus resources, the proposed technical framework is expected to expand its application to bilingual translation teaching and intercultural communication courses in subsequent research.
Disclosures
The authors declare that they have no financial conflicts of interest.
Acknowledgements
This work was supported by Zhejiang Provincial Education Planning Project 2026: Research on Reconstruction of Teaching Competency Framework and Promotion Strategies of Higher Vocational Teachers Under Digital and Intelligent Empowerment (Project No.: ZWT26024; Approval No.: 2026SCG360).
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| BERT Pre-trained Language Model | https://github.com/google-research/bert | Text representation, paragraph structure recognition, semantic similarity calculation, and text classification support automated scoring of writing content. | |
| Coreferee | Explosion AI | https://github.com/explosion/coreferee | Text referential relationships are identified, and discourse referential coherence is assessed to assist in the automatic scoring of writing quality. |
| DeepSeek Large Language Model | DeepSeek AI | https://chat.deepseek.com/ | Based on the MoE model architecture, instruction optimization and prompt word chain design were carried out. The model uses fixed parameters: a temperature coefficient of 0.7, and the generated length is dynamically limited according to the question type. |
| spaCy | Explosion AI | https://github.com/explosion/spaCy | The dependency syntax structure of English text is analyzed, and indicators such as average sentence length and the number of nested clauses are extracted to quantify syntactic complexity. |
| SPSS 26.0 | IBM | https://www.ibm.com/products/spss-statistics | Statistical analyses such as Repeated Measures ANOVA (RM-ANOVA), independent samples t-test, Pearson correlation analysis, effect size (Cohen’s d) calculation, and reliability (ICC) test were conducted. |
References
- Maqsood M, Zahid A, Asghar T, et al. Issues in teaching English in a cultural context. Migr Lett. 2024; 21(4): 1020–1027.
- Tran NT, Nguyen TT, Pham HH. Exploring the challenges of L1 negative transfer among Vietnamese English language learners: a qualitative study. rEFLections. 2024; 31(2): 837–857.
- Zhu P. Cultural dimensions as guidelines in handling language problems for effective written communication across cultures. Int J Linguist Lit Transl. 2023; 6(12): 85–95.
- Zeng Z, Nair SM, Wider W. A comparative study of Chinese EFL undergraduates' pragmatic competence in English letter writing between urban and suburban universities. World J Engl Lang. 2022; 12(6): 377–388.
- Litvinova TA, Mikros GK, Dekhnich OV. Writing in the era of large language models: a bibliometric analysis of the research field. Nauchnyi Rezultat Voprosy Teoreticheskoi i Prikladnoi Lingvistiki. 2024; 10(4): 5–16.
- Long M. Cultivating interdisciplinary foreign language talents through interdisciplinary synergy of on-campus teaching and off-campus practices under the new liberal arts. Educ Rev USA. 2025; 9(5): 520–526.
- Voss E, Cushing ST, Ockey GJ, et al. The use of assistive technologies including generative AI by test takers in language assessment: a debate of theory and practice. Lang Assess Q. 2023; 20(4-5): 520-532.
- Manyasa J. When language transfer is negative: analysis of morpho-syntactic interference errors by learners of French in Tanzanian higher learning institutions. J Foreign Lang. 2021; 13(1): 165-190.
- Fikri N. The study of language transfer in EFL students' translation work. J Pendidik Nonformal. 2023; 1(1): 9.
- Ahmat A, Yang Y, Ma B, et al. Cross-lingual prompting method with semantic-based answer space clustering. Appl Intell. 2025; 55(2): 1-17.
- Maity S, Deroy A, Sarkar S. Investigating large language models for prompt-based open-ended question generation in the technical domain. SN Comput Sci. 2024; 5(8): 1-32.
- Wu W, Cao Y, Yi N, et al. Detecting and reducing the factual hallucinations of large language models with metamorphic testing. Proc ACM Softw Eng. 2025; 2(FSE): 1432-1453.
- Kaganovich P, Münz-Manor O, Ezra-Tsur E. Style transfer of modern Hebrew literature using text simplification and generative language modeling. CEUR Workshop Proc. 2023; 1613: 73-95.
- Yuan Y. Influence of native language transfer on senior high school English writing. Theory Pract Lang Stud. 2021; 11(2): 170-176.
- Jiamin M. The influence of cultural factors on language transfer in second language acquisition. Res J Engl Lang Lit. 2024; 12(1): 186-195.
- Zhang L. Native language transfer in vocabulary acquisition: an empirical study from connectionist perspective. J Lang Teach Res. 2023; 14(2): 446-458.
- Mirzayev E. The influence of first language interference on ESL writing skills. EuroGlob J Linguist Lang Educ. 2024; 1(1): 33-39.
- Fujiwara Y, Iwao T, Ito H, et al. Exploring the transfer of topic-comment structures called unagi-sentences in Asian L2 Englishes: cross-proficiency-level and cross-varietal studies. Asian Englishes. 2025; 27(1): 25-40.
- Guo Q. Interlanguage and its implications to second language teaching and learning. Pac Int J. 2022; 5(4): 8-14.
- Vereeck A, Janse M, De Herdt K, et al. Why Plato needs psychology: proposal for a theoretical framework underpinning research on the cognitive transfer effects of studying classical languages. Psiholoska Obzorja. 2023; 32: 121-130.
- Zhang W. Study on the negative transfer of mother tongue on college students. Int J Front Sociol. 2023; 5(16): 164-171.
- Li C. A review of theories, pedagogies and vocabulary learning tasks of English vocabulary learning apps for Chinese EFL learners. J China Comput Assist Lang Learn. 2024; 4(2): 346-375.
- Nsengimana I, Niyibizi E, Ngabonziza JDA. The impact of language transfers on learners' writing skills in English learning among students in Mahama Refugee Camp, Rwanda. Afr J Empir Res. 2024; 5(3): 605-613.
- Jovein S K, Sharifabad E D, Yazdani M. On the relationship between university translator training programs and the translation market requirements: The case of English translation graduates and postgraduates of Imam Reza International University. Journal of Critical Studies in Language and Literature. 2024; 5(6): 1-13.
- Qin X. Collaborative inquiry in action: a case study of lesson study for intercultural education. Asian Pac J Second Foreign Lang Educ. 2024; 9(1): 66-91.
- Sun L, Asmawi A. The effect of WeChat-based instruction on Chinese EFL undergraduates’ business English writing performance. International Journal of Instruction. 2023; 16(1): 43-60.
- Moro G, Piscaglia N, Ragazzi L, et al. Multi-language transfer learning for low-resource legal case summarization. Artificial Intelligence and Law. 2024; 32(4): 1111-1139.
- Sun Y. A study of college English writing teaching based on dynamic assessment. Pac Int J. 2023; 6(1): 83-88.
- Jeon J, Lee S. Large language models in education: a focus on the complementary relationship between human teachers and ChatGPT. Educ Inf Technol. 2023; 28(12): 15873-15892.
- Kostka I, Toncelli R. Exploring applications of ChatGPT to English language teaching: opportunities, challenges, and recommendations. TESL-EJ. 2023; 27(3): n3-n22.
- Antara IMAR, Anggreni NPY. Analyzing grammatical errors in EFL students' opinion essays using DeepSeek AI: patterns and pedagogical implications. Stilistika. 2025; 13(2): 210-218.
- Diasamidze L, Tedoradze T. Enhancing ESL students' writing skills through natural language processing model ChatGPT. Eurasia Proc Educ Soc Sci. 2024; 35: 230-238.
- Ranade N, Saravia M, Johri A. Using rhetorical strategies to design prompts: a human-in-the-loop approach to make AI useful. AI Soc. 2025; 40(2): 711-732.
- Zhou W, Gao B. Construction and application of English-Chinese multimodal emotional corpus based on artificial intelligence. Int J Hum Comput Interact. 2025; 41(3): 1782-1793.
- Chen B, Bao L, Zhang R, et al. A multi-strategy computer-assisted EFL writing learning system with deep learning incorporated and its effects on learning: a writing feedback perspective. J Educ Comput Res. 2024; 61(8): 60-102.
- Jeon H. Designing teaching for transfer in English for academic purposes. RELC Journal. 2024; 55(2): 567-577.
- Pei Y J. Construction of a" Feedback-Revision" Teaching Model for Senior High School English Continuation Writing Based on Generative AI. International Journal of Educational Development. 2026; 3(1): 16-25.
- Holubnycha L, Kuznetsova O, Shchokina T, et al. AI-Powered Teaching: Literature Review of ChatGPT's Impact on University Educators. International Journal of Interactive Mobile Technologies. 2025; 19(15): 41.
- Almuhanna M A. Teachers' perspectives of integrating AI-powered technologies in K-12 education for creating customized learning materials and resources. Education and Information Technologies. 2025; 30(8): 10343-10371.
- Hastomo T, Mandasari B, Widiati U. Scrutinizing Indonesian pre-service teachers’ technological knowledge in utilizing AI-powered tools. Journal of education and learning (EduLearn). 2024; 18(4): 1572-1581.
- Cai H, Lu L, Han B, et al. Exploring pre-service teachers’ reflection mediated by an AI-powered teacher dashboard in video-based professional learning: a pilot study. Educational technology research and development. 2025; 73(2): 1129-1154.