This protocol demonstrates a structured and auditable workflow for processing anonymized undergraduate well-being questionnaire data, from raw export and response screening to scale scoring, reliability checking, regression diagnostics, figure-source verification, and visualization-ready analytic outputs.
Method Article
A Structured Workflow for Screening, Scoring, and Visualizing Undergraduate Student Well-Being Questionnaire Data
In This Article
Summary
Abstract
Questionnaire-based studies are widely used to examine student well-being, but the procedural route from raw responses to analyzable variables, statistical tables, and visual outputs is often insufficiently documented. This protocol demonstrates a structured and auditable workflow for processing anonymized undergraduate well-being questionnaire data collected with multiple Likert-type scale sections. The workflow begins with ethics approval, consent documentation, questionnaire configuration, and raw-data export, and then proceeds through response screening, duplicate-response review, missing-data handling, item coding, reverse scoring, reliability assessment, descriptive analysis, correlation analysis, contrastive group comparison, regression modeling, diagnostic checking, and visualization-source preparation. The example questionnaire uses source-documented and study-adapted scale sections informed by the Depression Anxiety Stress Scales-21, Tuckman Procrastination Scale, Psychological Sense of School Membership Scale, higher-order thinking measurement literature, and subjective well-being scale documentation. Negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being are used as example scale-level variables to show how item-level responses can be converted into traceable analytic outputs. Representative outputs include a screening-flow table, demographic summary, descriptive and range-verification statistics, internal-consistency estimates, a correlation matrix, contrastive comparison results, regression coefficients, residual and influence diagnostics, and figure-source files. The protocol emphasizes prespecified decision rules, a linked scale map, a pre-analysis screening log, reverse-scoring verification, and numerical-source verification for figures. Rather than proposing a new psychometric scale, validating a measurement model, or establishing causal relationships, this method provides a practical and auditable procedure for researchers who need to screen, score, analyze, and visualize questionnaire-based undergraduate well-being data. The workflow may be adapted to related questionnaire-based studies when the scale map, ethics approval, scoring rules, response-screening thresholds, and visualization-source files are defined before analysis.
Introduction
Subjective well-being is an important outcome in student research because it reflects how students evaluate their lives, emotional experiences, social relationships, and daily functioning within learning environments. In higher education, student well-being is multidimensional rather than limited to life satisfaction or psychological distress alone1. Questionnaire data, therefore, remain useful when researchers need to examine emotional, behavioral, social, cognitive, and well-being-related experiences within the same analytic framework.
The value of questionnaire data depends not only on the constructs selected but also on how raw responses are converted into analytic variables. Many studies report scale scores, correlation matrices, group comparisons, or regression models without showing the intermediate decisions that connect raw records to final tables and figures. Missing responses may be handled inconsistently, reverse-scored items may be miscoded, duplicate submissions may remain in the dataset, and inattentive responses may be treated as valid observations. Missing-data decisions should therefore be planned, documented, and reported rather than treated as an invisible post hoc step2. Online questionnaire data also require explicit response-quality rules because speeding, straight-lining, inconsistent answers, and other low-effort patterns can distort descriptive statistics, reliability estimates, and observed associations3.
The novelty of this protocol lies in its linked audit trail from the raw questionnaire export to the final statistical and visual outputs. Specifically, the workflow adds a completed scale map, a pre-analysis screening log, a reverse-scoring checkpoint, a scoring verification log, numerical-source verification for figures, and an audit trace linking each table or figure to its source file. This distinguishes the method from standard survey cleaning, scale scoring, reliability testing, or visualization practices. Rather than only stating that questionnaire data were cleaned and analyzed, the protocol specifies which file is locked, which file is screened, which rules are applied, which scale scores are generated, and which verified numerical table is used to create each visual output.
The workflow is demonstrated with anonymized college-student questionnaire data containing five scale-level variables: negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being. These constructs were selected to provide emotional, behavioral, school-contextual, cognitive, and outcome-oriented examples within one structured and auditable workflow. Academic procrastination has been linked to later mental-health difficulties among university students, including depression, anxiety, and stress-related outcomes4. School belongingness and subjective well-being are also closely connected among student populations, supporting the inclusion of belonging- and well-being-related measures within the same questionnaire-processing framework5. In this protocol, however, these constructs are used to demonstrate the workflow rather than to establish a causal psychological model.
A central feature of the protocol is the separation of data-processing decisions from substantive interpretation. The scale map is prepared before analysis, response-quality criteria are fixed before scale scoring, reverse-scoring verification is completed before statistical testing, and figures are generated only after their numerical source tables have been checked. This sequence is important because Likert-type response scales require careful alignment among item wording, response anchors, scoring direction, and statistical treatment6. The protocol also prioritizes model complexity behind transparent preprocessing and scoring verification. Predictive or multivariable models may be useful in student research7, and graphical summaries can improve interpretation when they remain tied to verified numerical matrices8, but both depend on transparent preparation of the input variables. For this reason, the workflow uses correlation analysis, contrastive group comparison, regression modeling, diagnostic checking, and visualization as example modules rather than as mandatory substantive claims.
This protocol is intended for researchers who need a practical questionnaire-processing workflow for anonymized student well-being data. It is suitable when item-level questionnaire responses are exported from an online platform, scale-level variables must be computed from Likert-type items, and the goal is to produce transparent descriptive, correlational, group-comparison, regression, diagnostic, and visualization-ready outputs. It is not designed to establish causal relationships, validate new scales, replace confirmatory factor analysis, replace measurement invariance testing, or substitute for item response or latent-variable modeling. Its contribution is procedural: it makes the path from questionnaire records to reported tables and figures visible, repeatable, and auditable. This focus is consistent with current concerns about online survey data quality9, regression and influence checking10, and auditable questionnaire-based analysis workflows11.
Protocol
This study involving human participants was reviewed and approved by the Ethics Committee of the College of Aeronautics, Guizhou Open University (Approval No. GZOU-EDU-2024-015). The committee determined that the study qualified for ethical exemption because it used anonymous, voluntary questionnaire procedures and posed no more than minimal risk to participants. All participants provided electronic informed consent before completing the questionnaire and could stop answering at any time without penalty. Because several items addressed negative emotions, stress, loneliness, helplessness, dissatisfaction, or related well-being experiences, the consent page and final questionnaire page provided contact information for the researcher and the institution for participants who experienced discomfort. The dataset used in this protocol was anonymized before screening, scoring, analysis, and visualization. The complete questionnaire is provided as Supplementary File 1.
1. Prepare the questionnaire, ethics materials, and workflow artifacts
- Define the eligible population, study setting, questionnaire constructs, and planned analytic outputs before programming the questionnaire.
- Prepare an ethics application covering the target population, recruitment channel, questionnaire content, estimated completion time, anonymity protection, data storage, withdrawal procedure, participant-support information, and planned analyses.
- Store the ethics approval or exemption document, consent wording, recruitment text, questionnaire version, participant-support information, and planned workflow in the project folder before data collection begins.
- Define the target population as full-time undergraduate students who are at least 18 years old, currently enrolled in higher education, able to understand the questionnaire, and able to provide informed consent.
- Define exclusion criteria before recruitment. Exclude respondents who decline consent, do not meet the target-population definition, submit duplicate responses, exceed the missing-data threshold, or meet the combined invalid-response criteria described in Step 1.4.
- Place the informed consent statement at the beginning of the questionnaire. State the study purpose, voluntary nature of participation, approximate completion time of 12 min, anonymity protection, withdrawal right, data-use plan, researcher contact information, and support-contact information.
- Do not collect directly identifiable information, including student identification numbers, national identification numbers, mobile phone numbers, personal email addresses, dormitory addresses, or other personal identifiers.
- Arrange the questionnaire in this order: informed consent, demographic information, negative emotion items, academic procrastination items, school belongingness items, higher-order thinking items, and subjective well-being items.
- Select the source instruments before programming the questionnaire. In this protocol, negative emotion was assessed using the 21-item Depression Anxiety Stress Scales-21, academic procrastination using the 16-item Tuckman Procrastination Scale, school belongingness using the 18-item Psychological Sense of School Membership Scale, higher-order thinking using a 20-item higher-order thinking item set adapted from published higher-order thinking measurement literature, and subjective well-being using a 20-item subjective well-being scale for college-student research12,13,14,15,16.
- Prepare a locked scale map before programming the questionnaire. Include construct name, original scale name, original citation, language version, permission or authorization status, translation or adaptation procedure, item code, item wording, response range, response anchors, score direction, reverse-scored item status, final scale-level variable, and scoring rule.
- Describe an item set as a validated scale only when the source instrument, citation, validation evidence, and adaptation or translation status are documented. Identify any author-developed or study-specific item set in Table 1 and Supplementary File 1.
- Lock the measurement framework before data collection. For translated or adapted instruments, complete translation, review, reconciliation, and pilot checking before recruitment begins.
- Prepare a workflow audit package that includes the locked questionnaire file, scale map, raw data export checklist, screening log, scoring verification log, analysis log, figure-source table template, and analysis syntax or script file.
- Use versioned file names for all workflow artifacts.
- Define the required columns for each audit file.
- The screening log includes record ID, screening criterion, flag status, exclusion status, reason for exclusion, decision date, and reviewer initials.
- The scale map includes construct name, scale source, item code, item wording, response range, response anchors, reverse-scoring status, final variable name, scoring rule, and permission or adaptation status.
- The scoring verification log includes item code, original value range, recoded value range, reverse-scoring formula, range-check result, discrepancy status, correction made, and date of correction.
- The figure-source table includes the figure number, panel number, source table, variables plotted, statistic displayed, sample size, and verification status.
- Define the analytic workflow before programming the questionnaire: survey administration, raw data export, response screening, scale scoring, reliability assessment, descriptive analysis, correlation analysis, high-low group comparison, regression modeling, diagnostic checks, and visualization preparation17.
- Structure the protocol around decisions, operations, and verification outputs rather than software menu paths.
- Provide workflow resources when permitted by institutional and journal policies, including the questionnaire file, scale map, screening-log template, scoring-log template, analysis syntax or script file, and figure-source tables.
NOTE: Figure 1 shows the route from questionnaire preparation to raw data export, response screening, scale scoring, statistical analysis, diagnostic checks, and visualization output. Table 1 reports the source instrument, item count, response range, scoring framework, reverse-scoring rule, permission or adaptation status, and final scale-level variable for each construct.
2. Configure and distribute the questionnaire
- Confirm that the questionnaire platform supports consent gating, required items, duplicate-submission review, timestamp capture, and response-duration recording.
- Create the questionnaire using the online survey platform listed in the Table of Materials. Program the questionnaire according to the locked scale map.
- Compare the programmed questionnaire with the locked scale map item by item before releasing the survey link. Record any corrections in the study log.
- Set the informed consent item as the first required item. Stop the questionnaire automatically when a participant selects “I do not agree to participate.”
- Program the demographic and psychological scale sections according to the order fixed in Step 1.8. Use item codes that match the scale map.
- Set psychological scale items as required only when permitted by the ethics approval or exemption and when participants can withdraw without penalty. If forced responses are not permitted, record the missing-data rule before data collection.
- Display the response anchors before each scale section and keep anchors consistent within each scale18.
- Disable repeated submissions when the survey platform provides this function. Retain any anonymous device, browser, platform, or submission identifier needed for duplicate-response review.
- Enable automatic recording of submission time and completion duration.
- Set the questionnaire opening period to 7 calendar days, or use the collection window approved by the ethics committee.
- Send the questionnaire link through the approved institutional recruitment channel. Provide the same written instructions to all participants.
- Close the questionnaire after the prespecified collection window ends.
NOTE: Retain the recruitment wording, questionnaire link, opening and closing dates, platform settings, consent wording, final questionnaire version, and platform-export settings in the study log.
3. Export and secure the raw data
- Export the completed questionnaire responses as a spreadsheet file immediately after the collection window closes.
- Save the first exported file as the locked raw dataset. Do not edit this file.
- Create one working copy for screening, scoring, and analysis. Name the file with the date, version number, and project identifier.
- Confirm that the exported file contains one row per respondent and one column per demographic variable, questionnaire item, timestamp variable, platform variable, or derived platform field.
- Store the locked raw dataset, working copy, scale map, questionnaire file, study log, screening log, scoring verification log, analysis log, figure-source tables, and syntax or script file in a password-protected project folder.
- Check that the dataset contains no directly identifiable information. Remove any unexpected identifying field from the working copy before analysis and record the field name, reason for removal, date of removal, and responsible reviewer in the study log.
- Check indirect identifiability before sharing or publishing participant-level data. Review small demographic cells created by combinations of sex, age, year level, institution category, and academic major category. If a cell contains fewer than five respondents, combine categories, suppress the cell, or provide only aggregated data.
- Record the data-availability status in the study log, including whether participant-level data are available, restricted because of ethics or privacy requirements, or replaced by an aggregated workflow dataset.
- Create a screening log before data cleaning. Record the raw sample size, screening criterion, number of records flagged, number of records removed, number of records retained, reason for exclusion, decision date, and reviewer initials.
- Create an analysis trace file before statistical analysis. Record the software name, software version, operating system, file names, data version, script or syntax version, and date of each analysis run.
NOTE: Use the locked raw dataset only for verification. Conduct all screening, scoring, and analysis using the working copy.
4. Screen responses and construct the analytic dataset
- Apply prespecified exclusion and quality-control rules before calculating any scale-level score.
- Apply the screening rules to the working copy in this order: consent status, eligibility, duplicate submissions, missing data, response duration, straight-line responding, out-of-range values, and combined response-quality indicators.
- After each screening operation, record the number of records flagged, removed, and retained in the screening log. Do not overwrite earlier versions of the working file.
- Remove all records in which the informed consent item is marked “No” or left unanswered.
- Remove all records that do not meet the inclusion criteria defined in Step 1.4.
- Screen for duplicate submissions using anonymous response identifiers, submission time, platform duplicate-submission flags, and repeated response patterns.
- Retain the first complete submission when duplicate entries are detected, unless a documented reason supports retaining a later complete response.
- Fix all response-quality rules before calculating scale scores. Table 2 summarizes the exclusion thresholds, flagging thresholds, rationale, literature support, and sensitivity-analysis plan used in the workflow.
- Screen for missing data. Remove a respondent when more than 20% of all scale items are missing. Replace an isolated missing item with the respondent’s mean score for the same scale only when at least 80% of that scale has been completed. Do not impute demographic variables unless the variable is not used in any analysis.
- Record the number of respondents excluded for more than 20% missing scale items and the number receiving within-scale mean imputation. In the current dataset, 4 respondents were excluded for more than 20% missing scale items, and 21 respondents received within-scale mean imputation for 37 isolated missing items.
- Screen for response duration. Flag responses completed in less than 180 s. Treat this value as a speeding flag rather than an automatic exclusion rule.
- Screen for straight-line responses. Flag a response when the same option is selected for more than 90% of all Likert-scale items. Treat this value as a response-pattern flag rather than an automatic exclusion rule.
- Screen for additional low-effort indicators, including evidence of duplicate submissions, impossible timestamps, repeated response strings across separate submissions, or conflicts between platform metadata and questionnaire content.
- Remove a flagged response only when at least two quality-control indicators suggest invalid responding, such as extremely short completion time combined with straight-line responding, duplicate-submission evidence, or impossible platform metadata19.
- Record all flagged records, even when they are retained. In the current dataset, 19 responses were flagged for completion duration < 180 s, 8 responses were flagged for >90% straight-line responding, and 13 records were excluded because they met two or more response-quality indicators.
- Screen for out-of-range values. Confirm that negative emotion items fall within 1–4, academic procrastination, school belongingness, and higher-order thinking items fall within 1–5, and subjective well-being items fall within 1–6.
- Correct a value only when the original export clearly shows a formatting error. Do not alter valid psychological scores because they appear unusually high or low.
- Generate a screening-flow table reporting submitted questionnaires, consent and eligibility exclusions, duplicate exclusions, missing-data exclusions, response-quality flags, combined quality-control exclusions, isolated item imputations, retained analytic cases, and final analytic sample size.
- Complete the screening-flow table using the locked screening log and retain an exported audit record of the screening decisions. In the current dataset, the screening flow was as follows: submitted questionnaires, n = 448; consent or eligibility exclusions, n = 6; duplicate submissions removed, n = 5; records excluded for >20% missing scale items, n = 4; records excluded for two or more response-quality indicators, n = 13; final analytic dataset, n = 420.
- Save the retained records as the analytic dataset. Use a new versioned file name and retain the screening log with the analytic dataset.
NOTE: Retain valid extreme scores unless a documented response-quality problem is present.
5. Score the psychological scales
- Convert item-level responses into scale-level variables only after response screening has been completed and the analytic dataset has been saved.
- Code all Likert-type items according to the response anchors in the locked questionnaire and the scoring rules in the scale map.
- Keep the original item variables unchanged. Create separate derived variables for recoded or reverse-scored items.
- Score each scale according to the locked scale map and the corresponding source instrument or scoring manual.
- Reverse-score the designated subjective well-being items before calculating the subjective well-being score. For the 1–6 response scale, calculate each reversed item as 7 minus the original score and add _R to the derived variable name.
- Use the reverse-scored variables, not the original variables, when calculating subjective well-being.
- Calculate each scale-level score as the mean of its retained items: negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being.
- Name the final scale-level variables as Negative emotion, Academic procrastination, School belongingness, Higher-order thinking, and Subjective well-being.
- Verify the minimum and maximum value of each scale-level variable against its theoretical response range. Recheck coding, reverse scoring, and missing-value handling if any score falls outside the expected range.
- Verify the direction of each scale against the scale map before inferential analysis. Higher scores should reflect the intended direction of the construct.
- Conduct a reverse-scoring audit before analysis. Recalculate the reverse-scored items for a random subset of records or for all reverse-scored items when feasible, and record the audit result in the scoring verification log.
- If a scoring error is detected, correct the derived variable, regenerate the affected scale score, update the scoring verification log, and rerun all downstream analyses and figure-source tables based on the corrected analytic dataset.
NOTE: Treat reverse scoring and range verification as required checkpoints before correlation analysis, group comparison, regression modeling, or visualization.
6. Assess internal consistency and descriptive properties
- Calculate internal consistency, corrected item-total correlations, and descriptive statistics for each scale using the item variables defined in the locked scale map.
- Record Cronbach’s alpha, item number, valid sample size, corrected item-total correlations, and alpha-if-item-deleted values for each scale.
- Use Cronbach’s alpha of 0.70 as the minimum acceptable reliability threshold for this workflow. Before removing any item, check item wording, score direction, reverse scoring, construct alignment, and the source-instrument documentation20.
- Calculate McDonald’s omega as a supplementary reliability estimate when the analysis environment supports it. Report omega with Cronbach’s alpha when the two estimates lead to different reliability interpretations.
- Inspect any item with a negative or very low corrected item-total correlation before considering removal. Treat this first as a possible coding, reverse-scoring, or construct-alignment problem.
- Do not remove an item only to increase Cronbach’s alpha. Item removal must be justified by the scoring manual, item wording, corrected item-total correlation, conceptual fit, and documented scoring verification.
- Calculate descriptive statistics for all five scale-level variables, including mean, standard deviation, minimum, maximum, skewness, and kurtosis.
- Check floor or ceiling concentration by recording the proportion of respondents at the minimum and maximum possible scores for each scale.
- Record the reliability estimates, item-total diagnostics, descriptive statistics, and any scoring decisions in the analysis log.
NOTE: Cronbach’s alpha is used as a reliability checkpoint, not as a complete psychometric validation procedure. When formal measurement evaluation is required, supplement this workflow with McDonald’s omega, confirmatory factor analysis, measurement invariance testing, item response modeling, or other latent-variable methods.
7. Conduct correlation analysis
- Use the five verified scale-level variables: negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being.
- Before calculating Pearson correlations, inspect the distributions and bivariate scatterplots for each pair of scale-level variables.
- Assess whether the variables show approximately continuous score variation, severe skewness, nonlinear relationships, or influential outlying patterns.
- Calculate Pearson correlation coefficients and two-tailed p-values for all pairs of scale-level variables when the assumptions are acceptable for descriptive association analysis.
- Record the correlation coefficient, p-value, sample size, and direction of association for each variable pair.
- Report correlation coefficients to three decimal places.
- Compare the direction of each coefficient with the scale map. Recheck item scoring if a coefficient contradicts the intended construct direction.
- Save the verified correlation matrix as the numerical source table for the correlation heatmap in the Representative Results section.
- When distributions are markedly skewed, ordinal-scale sensitivity is required, or scatterplots suggest monotonic but non-linear associations, repeat the analysis using Spearman correlation and compare the direction and relative magnitude of the associations.
- Record whether the Pearson and Spearman results led to the same substantive interpretation.
NOTE: Use correlation analysis as both a descriptive association check and a scoring-direction audit.
8. Create high and low subjective well-being groups
- Use the cleaned and scored analytic dataset. Do not return to the raw export for group construction.
- Use the continuous subjective well-being score as the primary outcome for regression modeling. Use the high-low grouping only for contrastive profile comparison.
- Sort respondents by subjective well-being score from highest to lowest.
- Apply the prespecified 27% extreme-group rule to define the high and low subjective well-being groups. Document the rationale for this threshold in Table 2 and the analysis log.
- Assign respondents in the top 27% to the high subjective well-being group and respondents in the bottom 27% to the low subjective well-being group.
- Retain the middle 46% in the full analytic dataset for descriptive statistics, correlation analysis, sex comparison, and regression modeling, but exclude these cases from the high-low contrast.
- Create a grouping variable named Subjective well-being group. Code the top group as High, the bottom group as Low, and the remaining respondents as Middle.
- Confirm that the high and low groups contain the intended number of cases. If tied scores occur at the 27% boundary, apply the prespecified tie-handling rule and record the decision in the analysis log.
- Conduct a sensitivity check when the 27% boundary creates unstable group membership because of tied scores or a small sample size. Use an alternative prespecified rule, such as tertile grouping, and report whether the interpretation is unchanged.
NOTE: The high-low grouping is a descriptive contrast procedure. It should not replace the continuous subjective well-being score in the primary regression model.
9. Compare high and low subjective well-being groups
- Filter the analytic dataset to retain only respondents coded as High or Low in the subjective well-being grouping variable.
- Compare the high and low groups on negative emotion, academic procrastination, school belongingness, and higher-order thinking.
- Before group comparison, inspect group-specific distributions, sample sizes, and variance equality for each variable.
- Use an independent-samples t-test when distributional and variance assumptions are acceptable. Use Welch’s t-test when the equality-of-variance assumption is not supported.
- Record group means, standard deviations, mean differences, t-values, degrees of freedom, p-values, and 95% confidence intervals.
- Calculate Cohen’s d for each group difference and interpret the effect size with the p-value.
- Inspect whether the direction of each group difference is consistent with the construct definitions and the correlation matrix.
- Save the verified group-comparison table as the numerical source for any group-comparison visualization.
- Report this analysis as a contrast between extreme subjective well-being profiles.
NOTE: Do not interpret the high-low comparison as causal evidence.
10. Examine sex differences
- Remove the high-low group filter and return to the full analytic dataset.
- Use sex as a descriptive grouping variable rather than as a causal exposure.
- Compare female and male respondents on negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being.
- Before comparison, inspect group-specific sample sizes, missingness, distributions, and variance equality.
- Use an independent-samples t-test when assumptions are acceptable. Use Welch’s t-test when the equality-of-variance assumption is not supported.
- Record group means, standard deviations, mean differences, t-values, degrees of freedom, p-values, 95% confidence intervals, and Cohen’s d values.
- Interpret sex differences descriptively and report effect sizes with p-values.
- Do not use the sex-comparison results to justify post hoc exclusion, scale modification, or causal interpretation.
NOTE: Sex comparisons are included as descriptive subgroup checks within this cross-sectional questionnaire workflow.
11. Estimate the regression model
- Use subjective well-being as the dependent variable.
- Use negative emotion, academic procrastination, school belongingness, and higher-order thinking as simultaneous scale-level predictors21.
- Use the continuous scale-level variables created during scale scoring. Do not replace the continuous subjective well-being score with the high-low grouping variable.
- Fit the primary model using simultaneous-entry multiple linear regression.
- Record unstandardized coefficients, standardized coefficients, standard errors, t-values, p-values, 95% confidence intervals, R2, adjusted R2, tolerance, and variance inflation factor.
- Use variance inflation factor values below 5.00 as the threshold for absence of severe multicollinearity.
- Inspect bivariate scatterplots, partial-regression plots, or component-plus-residual plots to assess whether the associations between predictors and subjective well-being are approximately linear.
- Assess residual independence using the Durbin-Watson statistic.
- Assess residual normality using a residual Q-Q plot and a formal normality test when appropriate for the sample size.
- Assess homoscedasticity using a plot of standardized residuals against standardized predicted values.
- Save standardized residuals, standardized predicted values, leverage values, and Cook’s distance for diagnostic checking.
- Estimate a supplementary adjusted model including the four psychological predictors and the demographic variables reported in the sample description, including sex, age, year level, institution category, and academic major category, when these variables are available and adequately distributed.
- Compare the primary model with the supplementary adjusted model. Record whether the direction, magnitude, and statistical interpretation of the four psychological predictors remain stable after demographic adjustment.
- Save the verified standardized coefficients and 95% confidence intervals from the primary model as the numerical source table for the coefficient plot in the Representative Results section22.
NOTE: Interpret regression coefficients as conditional associations, not causal effects. The demographic-adjusted model is used in a sensitivity analysis to assess whether the workflow conclusions remain stable after accounting for available background variables.
12. Diagnose the regression model
- Inspect standardized residuals from the fitted regression model. Flag cases with absolute standardized residuals greater than 3.00.
- Inspect leverage values and Cook’s distance for influential observations.
- Flag observations with Cook’s distance greater than 4/n as potentially influential, where n is the analytic sample size. Treat Cook’s distance greater than 1.00 as a severe-influence reference threshold rather than the only screening boundary.
- Inspect the residual-versus-predicted plot for nonlinearity, unequal variance, and unusual clustering.
- Inspect the residual Q-Q plot and the residual normality test result. Record whether the normality assessment supports the use of the linear model for descriptive association analysis.
- Record the Durbin-Watson statistic and determine whether residual independence is acceptable.
- Review all flagged cases against the screening log, scoring verification log, and eligibility criteria.
- Retain flagged cases when they represent valid observations and do not reflect data-entry errors, scoring errors, duplicate submissions, eligibility violations, or documented response-quality problems.
- Correct or remove a flagged case only when the audit trail identifies a documented procedural, eligibility, coding, scoring, or data-entry error.
- Rerun the regression model after any documented correction and compare the coefficients, confidence intervals, R2, adjusted R2, and diagnostic outputs with the original model.
- Conduct an influence sensitivity check by refitting the model after excluding cases with Cook’s distance greater than 4/n. Report whether the substantive interpretation changes.
- Record the final diagnostic decision in the analysis log, including the number of cases flagged by standardized residuals, the number flagged by Cook’s distance greater than 4/n, the maximum Cook’s distance, the Durbin-Watson statistic, and the conclusion from residual normality and linearity checks.
NOTE: Do not remove influential cases only to improve model fit. Removal or correction must be based on a documented audit-trail reason.
Results
Analytic dataset generated after response screening
The response-screening workflow generated an analytic dataset of 420 anonymized student records from 448 submitted questionnaires. The screening log recorded each decision point. Six records were removed because consent or eligibility requirements were not met, five duplicate submissions were removed, four records were excluded because more than 20% of all scale items were missing, and 13 records were excluded because they met two or more response-quality indicators. Nineteen responses were flagged for completion duration <180 s, eight responses were flagged for >90% straight-line responding, and 21 respondents received within-scale mean imputation for 37 isolated missing items. The final analytic dataset contained no directly identifiable participant information, no retained case exceeded the missing-data exclusion threshold, and all retained item responses fell within the predefined response ranges. The screening flow is summarized in Table 3.
The retained sample included 275 female respondents and 145 male respondents, accounting for 65.5% and 34.5% of the analytic dataset, respectively. The mean age was 20.1 ± 1.2 years. Respondents were distributed across four undergraduate year levels, with Year 1 to Year 4 accounting for 27.1%, 27.4%, 25.5%, and 20.0% of the sample. The dataset also included three institutional categories and five academic major categories. No published demographic cell contained fewer than five respondents after category review. The demographic characteristics of the analytic dataset are summarized in Table 4.
Scale construction, range verification, and suboptimal workflow examples
After item coding and reverse scoring, five scale-level variables were computed: negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being. Each score remained within its theoretical response range. Negative emotion scores ranged from 1.048 to 3.143 on a 1-4 scale. Academic procrastination, school belongingness, and higher-order thinking ranged from 1.312 to 4.250, 2.333 to 4.444, and 2.350 to 4.850 on their respective 1–5 scales. Subjective well-being ranged from 2.000 to 5.300 on a 1–6 scale. Reverse-scoring verification identified no discrepancy between the derived reverse-scored variables and the locked scoring rule in the final analytic dataset. These checks confirmed that item coding, reverse scoring, missing-item handling, and score aggregation were completed without detectable range errors.
The workflow also generated suboptimal audit examples that illustrate how errors or questionable outputs are detected before final analysis. During an audit run, an incorrectly derived subjective well-being reverse-scored value was detected because the scoring verification log compared the original value, the expected formula “reversed score = 7-original score,” the derived value, and the final scale range. The derived variable was corrected, the subjective well-being score was regenerated, and all downstream descriptive, correlation, comparison, regression, diagnostic, and figure-source outputs were rerun. In another intermediate working file, an out-of-range item value was identified during range verification and traced to spreadsheet handling rather than to the locked raw export. The working copy was corrected and documented without altering any valid extreme response. A reliability warning was also reviewed when one item showed a lower corrected item-total correlation than other items in the same scale; because the item wording, score direction, and construct alignment were correct, the item was retained. A draft visualization mismatch was identified when a figure did not match its verified numerical source table; the figure was regenerated from the verified table, and the figure-source record was updated. These examples demonstrate that the workflow not only generates successful outputs but also detects coding errors, range problems, reliability warnings, figure-source mismatches, and response-quality concerns through the audit trail.
Descriptive properties and internal consistency
The five scale-level variables showed usable variation. The mean negative emotion score was 2.099 ± 0.391, and the mean academic procrastination score was 2.639 ± 0.484. School belongingness and higher-order thinking showed moderately high mean values, at 3.343 ± 0.390 and 3.627 ± 0.418, respectively. The mean subjective well-being score was 3.784 ± 0.543. No scale showed an evident floor or ceiling pattern, and the proportion of respondents at the theoretical minimum or maximum was below 2.0% for each scale.
Internal consistency was acceptable for all five scales. Cronbach’s alpha values ranged from 0.834 to 0.899, exceeding the prespecified threshold of 0.70. Negative emotion showed the highest internal consistency, with Cronbach’s alpha of 0.899, followed by subjective well-being at 0.895. McDonald’s omega values ranged from 0.842 to 0.906, and the omega estimates did not change the reliability interpretation. Corrected item-total correlation review did not identify any item requiring removal. The descriptive statistics and reliability estimates are reported in Table 5.
Correlation structure among scale-level variables
The correlation matrix was used as a descriptive measure of association and as a scoring-direction check. Before Pearson correlations were calculated, scale distributions and bivariate scatterplots were inspected. No variable showed severe skewness or kurtosis, and no bivariate plot showed a strong nonlinear pattern that would invalidate descriptive Pearson correlation analysis. Subjective well-being was negatively correlated with negative emotion (r = -0.496) and academic procrastination (r = -0.294), and positively correlated with school belongingness (r = 0.481) and higher-order thinking (r = 0.386). The remaining associations followed the same scoring logic: negative emotion was positively associated with academic procrastination (r = 0.270) and negatively associated with school belongingness (r = -0.346) and higher-order thinking (r =-0.205); academic procrastination was negatively associated with school belongingness (r = -0.222) and higher-order thinking (r = -0.134); and school belongingness was positively associated with higher-order thinking (r = 0.310). The complete Pearson correlation matrix is presented in Table 6.
A Spearman sensitivity check produced the same directional interpretation for all variable pairs. The Spearman correlations between subjective well-being and the four predictors were ρ = -0.502 for negative emotion, ρ = -0.301 for academic procrastination, ρ = 0.477 for school belongingness, and ρ = 0.392 for higher-order thinking. The verified Pearson matrix was used as the numerical source table for visualization. Figure 2A presents the full correlation heatmap across the five scale-level variables. Figure 2B shows the four correlations with subjective well-being.
Contrastive demonstration using high and low subjective well-being groups
The 27% grouping rule was used as a contrastive workflow demonstration rather than as a substantive classification of real-world well-being profiles. The rule produced two groups of equal size: 113 respondents in the high subjective well-being group and 113 in the low subjective well-being group. The middle 194 respondents were retained in the full analytic dataset but excluded from this contrastive comparison. No boundary tie changed the group assignment.
This module showed that the workflow could generate a prespecified grouping variable, filter the analytic dataset, calculate group-specific descriptive statistics, run assumption-appropriate group comparisons, and export a verified source table for visualization. The high subjective well-being group showed lower negative emotion than the low subjective well-being group (1.864 ± 0.358 vs. 2.335 ± 0.343; mean difference = -0.472) and lower academic procrastination (2.455 ± 0.476 vs. 2.801 ± 0.483; mean difference = -0.346). School belongingness and higher-order thinking were higher in the high subjective well-being group, with mean differences of 0.454 and 0.351, respectively. All four comparisons were significant (p < 0.001), with Cohen’s d values of -1.346 for negative emotion, -0.722 for academic procrastination, 1.279 for school belongingness, and 0.860 for higher-order thinking. Welch’s t-test was used when the equality-of-variance assumption was not supported; otherwise, the standard independent-samples t-test was retained. These outputs should not be interpreted as evidence that the selected predictors define real-world student well-being profiles, because the groups were created from the outcome variable and then compared on correlated variables. The high-low group comparison is summarized in Table 7.
Descriptive comparison by sex
Sex was examined as a descriptive grouping variable. Female respondents showed a slightly higher mean negative emotion score than male respondents (2.129 ± 0.380 vs. 2.042 ± 0.407). This difference was statistically significant but small in magnitude (p = 0.033; Cohen’s d = 0.224). Academic procrastination, school belongingness, higher-order thinking, and subjective well-being did not show meaningful sex-based differences. Subjective well-being means were nearly identical between female and male respondents (3.781 ± 0.521 vs. 3.789 ± 0.583; p = 0.887; Cohen’s d = -0.015). Welch’s t-test sensitivity checks did not change the interpretation of the sex-comparison results. The sex difference results are presented in Table 8.
Regression model as an example of model generation and diagnostic checking
The multiple linear regression model was used as an example of generating, diagnosing, and verifying a model from scored questionnaire data. Subjective well-being was entered as the dependent variable, while negative emotion, academic procrastination, school belongingness, and higher-order thinking were entered simultaneously as scale-level predictors. The purpose of this module was to demonstrate coefficient extraction, multicollinearity checks, residual diagnostics, influence assessment, demographic-adjusted sensitivity analysis, and figure and source preparation.
The model explained a moderate proportion of variance in subjective well-being, with R2 = 0.411 and adjusted R2 = 0.406. Negative emotion showed the largest negative standardized coefficient (B = -0.450, standardized β = -0.324). Academic procrastination also showed a negative coefficient (B = -0.130, standardized β = -0.116). School belongingness and higher-order thinking showed positive standardized coefficients of β = 0.275 and β = 0.218, respectively. All four predictors were statistically significant in the fitted model: negative emotion, school belongingness, and higher-order thinking at p < 0.001, and academic procrastination at p = 0.004. Multicollinearity was not indicated, as all variance inflation factor values were below 1.24. These regression outputs are representative model-checking outputs, not a definitive psychological explanation of student well-being. Table 9 provides the complete regression output.
A supplementary demographic-adjusted model was estimated by adding sex, age, year level, institution category, and academic major category to the four psychological predictors. The adjusted model explained a similar proportion of variance, with R2 = 0.427 and adjusted R2 = 0.414. The direction and statistical interpretation of the four psychological predictors remained unchanged after demographic adjustment. The demographic-adjusted sensitivity model is summarized in Table 10. Figure 3A displays the standardized coefficients and 95% confidence intervals for the four predictors. Figure 3B presents the diagnostic display based on standardized predicted values, standardized residuals, and Cook’s distance.
Regression diagnostics and model retention
Regression diagnostics did not indicate that the fitted model was driven by a single influential record. The bivariate and partial-regression plots did not show strong nonlinearity. The residual-versus-predicted plot did not show severe heteroscedasticity or unusual clustering. The Durbin-Watson statistic was 1.93, supporting acceptable residual independence. The residual Q-Q plot showed no severe departure from normality. A formal residual normality test was statistically significant, W = 0.992, p = 0.031, but the Q-Q plot and sample size supported retaining the linear model for descriptive association analysis.
Two records had absolute standardized residuals greater than 3.00. No record had Cook’s distance greater than 1.00. Using the more sensitive threshold of Cook’s distance >4/n, where n = 420 and 4/n = 0.0095, 17 records were flagged as potentially influential. The largest Cook’s distance was 0.037. The flagged residual and influence cases were reviewed against the screening log, scoring verification log, and eligibility criteria. None showed evidence of data-entry errors, incorrect scoring, duplicate responses, eligibility failures, or documented response-quality problems; therefore, these cases were retained in the final model. An influence sensitivity check, excluding cases with Cook’s distance >4/n, yielded the same workflow interpretation as the primary model. The maximum absolute change in standardized coefficients was 0.026, and the adjusted R2 changed from 0.406 to 0.405. The diagnostic and sensitivity results are summarized in Table 11.
Analytic pipeline internal verification
The workflow was repeated from the cleaned and scored analytic dataset using the same scoring rules, decision thresholds, and analysis trace file. Internal consistency analysis, descriptive statistics, correlation analysis, high-low group comparisons, sex comparisons, regression modeling, diagnostic checking, and visualization source preparation were repeated. The repeated outputs matched the original descriptive statistics, correlation matrix, group-comparison values, regression coefficients, diagnostic outputs, and visualization source files. This confirmed the computational stability of the analytic pipeline when applied to the same locked analytic dataset. This check does not constitute independent procedural reproducibility, which would require an independent analyst to apply the full workflow from the locked raw export and reach the same documented outputs.
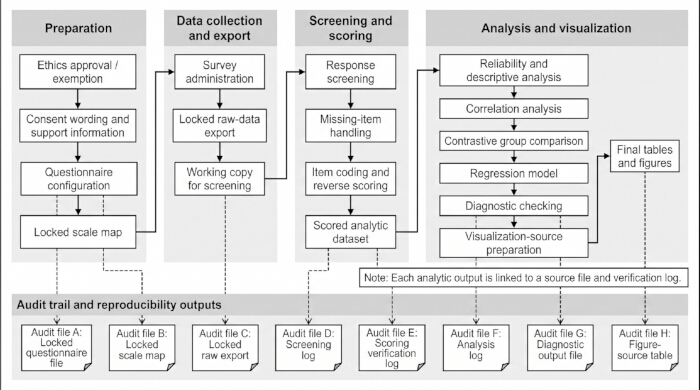
Figure 1: Workflow for questionnaire-based subjective well-being data processing. The schematic shows the protocol sequence and key audit outputs, including ethics preparation, questionnaire configuration, survey administration, raw data export, scale map, screening log, scored analytic dataset, verified analysis tables, regression diagnostics, figure source files, and visualization outputs. Please click here to view a larger version of this figure.
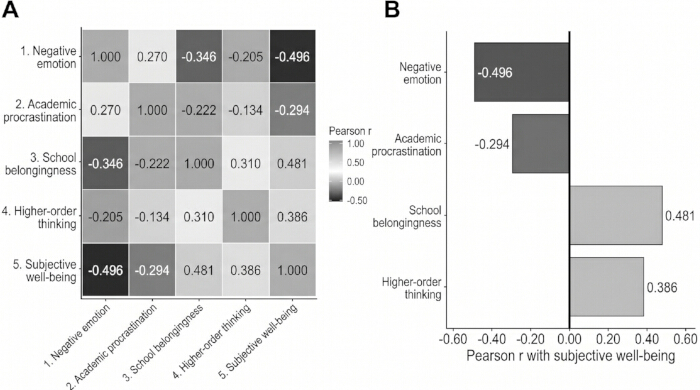
Figure 2: Correlation structure among scale-level variables. (A) Pearson correlation heatmap generated from the verified correlation matrix in Table 6. (B) Subjective well-being-centered correlation profile generated from the same verified source table. All five scale-level variables are displayed: negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being. Please click here to view a larger version of this figure.
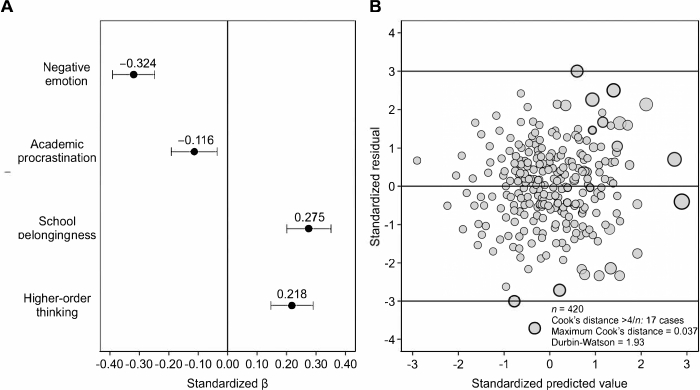
Figure 3: Regression coefficient and diagnostic visualization. (A) Standardized regression coefficients and 95% confidence intervals generated from the primary regression output in Table 9. (B) Regression diagnostic display generated from standardized predicted values, standardized residuals, and Cook’s distance values summarized in Table 11. Larger Cook’s distance values indicate observations with greater potential influence on the fitted model. Please click here to view a larger version of this figure.
Table 1: Questionnaire structure and scale scoring framework. This table summarizes the measurement framework, including the construct name, source instrument, source citation, adaptation or documentation status, item number, response range, score direction, reverse-scoring requirement, scoring method, final scale-level variable, and protocol role. Please click here to download this Table.
Table 2: Response screening and analytic decision criteria. This table lists the prespecified criteria for consent screening, eligibility screening, duplicate-response review, missing-data handling, response-duration flagging, straight-line response detection, valid response ranges, reliability assessment, high-low group classification, regression diagnostics, and sensitivity checks. Please click here to download this Table.
Table 3: Screening flow from submitted questionnaires to the final analytic dataset. This table reports the number of submitted questionnaires, flagged records, removed records, retained records, and verification sources at each screening step. Completion duration and straight-line responding were treated as response-quality flags rather than automatic exclusion criteria. Please click here to download this Table.
Table 4: Demographic characteristics of the analytic dataset. This table summarizes the retained anonymized student records after response screening, including sex, age, undergraduate year level, institution category, and academic major category. Demographic cells were reviewed for indirect-identifiability risk before reporting. Please click here to download this Table.
Table 5: Descriptive statistics, range verification, and internal consistency of the five scale-level variables. This table reports item number, theoretical range, observed range, mean, standard deviation, Cronbach’s alpha, McDonald’s omega, and floor/ceiling concentration for negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being. Please click here to download this Table.
Table 6: Pearson correlation matrix of scale-level variables. This table presents Pearson correlation coefficients among negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being. The matrix was used as a descriptive association output and as a scoring-direction verification step. Please click here to download this Table.
Table 7: Contrastive comparison between high and low subjective well-being groups. This table compares negative emotion, academic procrastination, school belongingness, and higher-order thinking between respondents in the top 27% and bottom 27% of subjective well-being scores. The comparison demonstrates the grouping and comparison workflow rather than a substantive classification of well-being profiles. Please click here to download this Table.
Table 8: Descriptive comparison by sex. This table reports descriptive comparisons of negative emotion, academic procrastination, school belongingness, higher-order thinking, and subjective well-being by sex. Sex was treated as a descriptive grouping variable. Please click here to download this Table.
Table 9: Primary multiple linear regression model predicting subjective well-being. This table presents the primary regression model in which subjective well-being was the dependent variable, and negative emotion, academic procrastination, school belongingness, and higher-order thinking were entered simultaneously as scale-level predictors. Standard error, confidence interval, and variance inflation factor values are included. Please click here to download this Table.
Table 10: Demographic-adjusted regression sensitivity model predicting subjective well-being. This table reports the four psychological predictors after adjustment for sex, age, undergraduate year level, institution category, and academic major category. Categorical demographic variables were entered using dummy coding. Standard error, confidence interval, and variance inflation factor values are included. Please click here to download this Table.
Table 11: Regression diagnostics and influence sensitivity checks. This table summarizes residual, influence, and model-diagnostic outputs, including standardized residuals, Cook’s distance > 1.00, Cook’s distance > 4/n, maximum Cook’s distance, Durbin-Watson statistic, residual Q-Q plot, residual normality test, residual-versus-predicted plot, linearity check, and influence sensitivity analysis. Please click here to download this Table.
Supplementary File 1: Questionnaire structure, scale provenance, and scoring documentation. This supplementary file provides the questionnaire administration order, informed-consent wording, demographic variables, source-instrument documentation, item codes, response anchors, adaptation and documentation-status information, scoring direction, reverse-scoring rules, final scale-level variable construction, missing-item handling rules, response-quality linkage fields, range-verification rules, and reference linkage for the five questionnaire constructs. It functions as the questionnaire/codebook supplement for documenting scale programming, scoring, and verification in the workflow. Please click here to download this file.
Discussion
This protocol standardizes a common but often underreported process in questionnaire-based well-being studies: the movement from raw response records to screened data, scored scale variables, statistical outputs, and visualization-ready files. Its contribution is not the development of a new subjective well-being theory or the proposal of a causal model. Instead, the workflow provides an auditable route for questionnaire configuration, response screening, scale scoring, reliability checking, descriptive analysis, association analysis, regression diagnostics, and figure-source verification. This distinction is important because auditability in survey-based questionnaire research depends on procedural decisions that are often made before statistical interpretation begins, including which records are retained, how missing items are handled, how reverse-scored items are processed, and how numerical source tables are linked to visual outputs. Making these decisions explicit reduces questionable measurement practices in scale-based research23 and supports a more transparent research culture24.
A central feature of the protocol is the use of concrete audit artifacts rather than verbal description alone. The revised workflow links each construct to its source instrument, item range, response anchors, score direction, reverse-scoring rule, final scale-level variable, and adaptation or documentation-status information. The audit trail includes the locked questionnaire file, locked scale map, locked raw export, screening log, scoring verification log, analysis log, diagnostic output file, and figure-source table. These files clarify which version of the questionnaire was administered, which records were excluded or retained, how scores were generated, and which verified table was used to create each figure. When participant-level data cannot be publicly shared, a synthetic dataset with the same variable structure and completed screening/scoring logs can enable readers to test the computational workflow without accessing identifiable or indirectly identifiable records. This artifact-based structure is consistent with the FAIR principle that reusable research outputs require clear provenance, structure, and access conditions25.
The representative results should be interpreted as workflow outputs rather than substantive evidence about the psychological determinants of student well-being. The high-low subjective well-being comparison was included to demonstrate how a prespecified grouping rule can be implemented, checked, and reported; it should not be interpreted as a real-world classification of well-being profiles. Similarly, the regression model demonstrates how scored questionnaire data can be modeled, checked for multicollinearity, evaluated with residual and influence diagnostics, and linked to a verified figure-source table. It does not establish that negative emotion, academic procrastination, school belongingness, or higher-order thinking causally determines subjective well-being. Because all major variables were collected through the same self-report questionnaire at one time point, common-method bias, response-style effects, and shared measurement context cannot be excluded26.
This workflow also does not replace full psychometric validation. Cronbach’s alpha, McDonald’s omega, observed-range checks, item-total review, and reverse-scoring verification are useful quality-control steps for an auditable scoring workflow, but they do not establish factorial validity, measurement invariance, item response properties, or cross-group comparability. Studies that use the questionnaire for substantive theory testing should conduct confirmatory factor analysis, measurement invariance testing across relevant demographic or institutional groups, and additional validity checks when appropriate27. Therefore, the present protocol should be understood as an auditable data-processing and reporting framework, not as a complete validation study for the included constructs.
The workflow was demonstrated in a sample of one undergraduate student, using self-reported questionnaire data collected at a single time point, without external validation. Its portability to other populations, disciplines, institutions, languages, and cultural settings should not be assumed. If the workflow is reused in another context, the scale map should be rebuilt rather than copied mechanically. Researchers should review item provenance, translation or adaptation status, cultural and contextual dependence of well-being items, response anchors, reverse-scoring rules, score interpretation, and local ethical requirements. Translation and adaptation procedures require explicit documentation rather than informal wording changes28, and the interpretation of educational and psychological test scores should remain tied to evidence for the intended use and population29.
In practice, the protocol is most useful as an auditable framework for data processing and reporting in questionnaire-based well-being research. It helps researchers make decisions about cleaning, scoring, diagnostics, and visualization visible before interpretation begins. Future applications should test the workflow across independent samples, different institutional settings, longitudinal designs, and independently replicated analyst teams. External validation, preregistered decision rules, shared synthetic datasets, completed example screening/scoring logs, and independent analyst replication would further strengthen the workflow's portability and credibility.
Disclosures
The authors have no conflicts of interest to declare.
Acknowledgements
The authors thank the college students who participated in the questionnaire survey for their support during data collection. The authors also thank the relevant instructors and research assistants for their assistance with questionnaire distribution, data organization, verification of results, and the preparation of tables and figures. This work received no specific funding.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| broom R package | CRAN | R package | Used to convert regression outputs into structured coefficient and model-summary tables. |
| car R package | CRAN | R package | Used for variance inflation factor verification and regression diagnostic support. |
| Depression Anxiety Stress Scales-21 source documentation | Psychology Foundation of Australia | Lovibond and Lovibond, 1995 | Source documentation for the negative emotion section. The workflow used study-adapted wording aligned with recent negative emotional-state assessment. |
| dplyr R package | CRAN | R package | Used for data filtering, recoding, grouping, screening-flow summaries, and analytic table preparation. |
| ggplot2 R package | CRAN | R package | Used to generate the correlation heatmap, subjective well-being correlation plot, regression coefficient plot, and diagnostic display. |
| Higher-order thinking measurement source documentation | Springer Nature | DOI: 10.1038/s41598-024-70908-3 | Source documentation for the higher-order thinking section. The workflow used a study-adapted item set aligned with analytical, evaluative, reflective, integrative, and evidence-based thinking. |
| IBM SPSS Statistics | IBM Corp. | Version 29.0.2.0 | Used for descriptive statistics, Cronbach’s alpha, Pearson correlation, independent-samples and Welch’s t-tests, multiple linear regression, Durbin-Watson statistic, standardized residuals, leverage values, Cook’s distance, and variance inflation factors. |
| psych R package | CRAN | R package | Used for psychometric summaries, Cronbach’s alpha verification, and McDonald’s omega. |
| Psychological Sense of School Membership Scale source documentation | Wiley | Psychol Sch. 1993;30(1):79-90 | Source documentation for the school belongingness section. The workflow used study-adapted wording aligned with perceived acceptance, connection, support, and belonging in the school environment. |
| R statistical environment | R Foundation for Statistical Computing | Version 4.4.2 | Used for secondary analytic verification, McDonald’s omega, Spearman sensitivity checks, regression-output preparation, diagnostic-output preparation, and visualization-source preparation. |
| readxl R package | CRAN | R package | Used to import spreadsheet questionnaire exports into the R verification workflow. |
| Subjective Well-being Scale for Chinese Citizens source documentation | Scientific & Academic Publishing | DOI: 10.5923/j.ijap.20190905.01 | Source documentation for the subjective well-being section. The workflow used study-adapted wording and reverse-scored items aligned with life satisfaction, meaning, support, progress, dissatisfaction, helplessness, and stress-related well-being experiences. |
| Supplementary File 1: Questionnaire structure and scale documentation | Authors | Supplementary File 1 | Provides the administered questionnaire structure, construct order, scale provenance, item codes, response anchors, scoring direction, reverse-scoring rules, scale-level score construction, and documentation-status information. |
| Tuckman Procrastination Scale source documentation | SAGE Publications | Educ Psychol Meas. 1991;51(2):473-480 | Source documentation for the academic procrastination section. The workflow used study-adapted wording aligned with academic delay and task-postponement behavior. |
| Wenjuanxing online questionnaire platform | Changsha Ranxing Information Technology Co., Ltd. | Web-based platform | Used for electronic consent, questionnaire programming, item response collection, timestamp capture, completion-duration recording, duplicate-submission review, and raw-response export. |
References
- 1. Khatri P et al. Student well-being in higher education: scale development and validation with implications for management education. Int J Manag Educ. 2024;22(1):100933.
- Mirzaei A, Carter SR, Patanwala AE, Schneider CR. Missing data in surveys: key concepts, approaches, and applications. Res Social Adm Pharm. 2022;18(2):2308-16.
- Gummer T, Roßmann J, Silber H. Using instructed response items as attention checks in web surveys: properties and implementation. Sociol Methods Res. 2021;50(1):238-64.
- Johansson F et al. Associations between procrastination and subsequent health outcomes among university students in Sweden. JAMA Netw Open. 2023;6(1):e2249346.
- Li X, Kuo YL, Huggins TJ. Perceived feedback and school belonging: the mediating role of subjective well-being. Front Psychol. 2024;15:1450788.
- Sönning L. Ordinal response scales: psychometric grounding for design and analysis. Res Methods Appl Linguist. 2024;3(3):100156.
- Song P et al. Predictive analysis of college students’ academic procrastination behavior based on a decision tree model. Humanit Soc Sci Commun. 2024;11:869.
- Dudáš A. Graphical representation of data prediction potential: correlation graphs and correlation chains. Vis Comput. 2024;40(10):6969-82.
- Niessen ASM, Meijer RR, Tendeiro JN. Detecting careless respondents in web-based questionnaires: which method to use? J Res Pers. 2016;63:1-11.
- Parsons J, Bao L. A unified approach for outliers and influential data detection: the value of information in retrospect. Stat. 2022;11(1):e442.
- Donche V et al. Careless responding in online student learning surveys: profiles and impact on data quality. Frontline Learn Res. 2026;13(3):1-14.
- Lovibond SH, Lovibond PF. Manual for the Depression Anxiety Stress Scales. 2nd ed. Psychology Foundation; Sydney; 1995.
- Tuckman BW. The development and concurrent validity of the Procrastination Scale. Educ Psychol Meas. 1991;51(2):473-80.
- Goodenow C. The psychological sense of school membership among adolescents: scale development and educational correlates. Psychol Sch. 1993;30(1):79-90.
- Li D, Fan X, Meng L. Development and validation of a higher-order thinking skills (HOTS) scale for major students in the interior design discipline for blended learning. Sci Rep. 2024;14:20287.
- Huang L, Xing Z. A nationwide study on Subjective Well-being Scale for Chinese Citizens (SWBS-cc). Int J Appl Psychol. 2019;9(5):117-27.
- DeSimone JA, Harms PD, DeSimone AJ. Best practice recommendations for data screening. J Organ Behav. 2015;36(2):171-81.
- Revilla MA, Saris WE, Krosnick JA. Choosing the number of categories in agree-disagree scales. Sociol Methods Res. 2014;43(1):73-97.
- Muszyński M. Attention checks and how to use them: review and practical recommendations. ASK Res Methods. 2023;32(1):3-38.
- McNeish D. Thanks coefficient alpha, we’ll take it from here. Psychol Methods. 2018;23(3):412-33.
- Romeo I, Stanislaw H, McCreary J, Hawley M. The importance of belonging for well-being in college students. PLOS Ment Health. 2024;1(1):e0000057.
- Kastellec JP, Leoni EL. Using graphs instead of tables in political science. Perspect Polit. 2007;5(4):755-71.
- Flake JK, Fried EI. Measurement schmeasurement: questionable measurement practices and how to avoid them. Adv Methods Pract Psychol Sci. 2020;3(4):456-65.
- Nosek BA et al. Promoting an open research culture. Science. 2015;348(6242):1422-5.
- Wilkinson MD et al. The FAIR Guiding Principles for scientific data management and stewardship. Sci Data. 2016;3:160018.
- Podsakoff PM, MacKenzie SB, Lee JY, Podsakoff NP. Common method biases in behavioral research: a critical review of the literature and recommended remedies. J Appl Psychol. 2003;88(5):879-903.
- Vandenberg RJ, Lance CE. A review and synthesis of the measurement invariance literature: suggestions, practices, and recommendations for organizational research. Organ Res Methods. 2000;3(1):4-70.
- van de Vijver FJR, Hambleton RK. Translating tests: some practical guidelines. Eur Psychol. 1996;1(2):89-99.
- American Educational Research Association, American Psychological Association, National Council on Measurement in Education. Standards for educational and psychological testing. American Educational Research Association; Washington, DC; 2014.