This study presents a lightweight framework for reducing hallucinations in large language models through claim-level verification and adaptive statistical thresholding. By selectively correcting unsupported claims using Natural Language Inference, the approach improves factual accuracy while maintaining low response latency and practical deployment efficiency.
A subscription to JoVE is required to view this content. Sign in or start your free trial.
Research Article
Adaptive NLI-Driven Claim Verification with Statistical Decision Modeling for Low-Latency Hallucination Reduction in Large Language Models
In This Article
Summary
Abstract
Large Language Models (LLMs) exhibit a critical tendency to generate factually incorrect yet linguistically fluent outputs - a phenomenon termed hallucination - which poses serious risks in precision-critical applications. Existing mitigation strategies, including retrieval-augmented generation and self-consistency sampling, either introduce substantial inference latency or depend on external knowledge infrastructure, limiting their applicability in real-time deployments. This paper proposes a lightweight two-step claim verification framework that decomposes LLM responses into atomic factual claims and independently verifies each extracted claim against a separately generated reference produced through an isolated factual recall prompt. Although the generator and verifier share the same underlying language model, separating response generation from factual recall reduces direct response conditioning and mitigates confirmation bias during verification, using Natural Language Inference, and applies an adaptive statistical threshold - defined as τ = µ + kσ over the NLI confidence score distribution - to selectively correct only contradicted claims. Unlike prior NLI-based methods that rely on fixed decision boundaries, the proposed framework dynamically adapts its verification threshold to the confidence distribution of each response, showing consistent performance across the evaluated benchmarks without requiring model retraining. Evaluated on TruthfulQA and FEVER, the framework reduces the hallucination rate from 28% to 9% on TruthfulQA - a 67.9% relative reduction - while incurring only 160 ms of additional latency over the baseline LLM and outperforming SelfCheckGPT and FActScore in hallucination detection accuracy. These results indicate that the framework can provide a favorable balance between factual reliability and response latency on the evaluated benchmarks, while further validation across domains and deployment settings is needed.
Introduction
Large Language Models (LLMs) have emerged as foundational components of modern artificial intelligence systems, demonstrating remarkable capability across a broad spectrum of natural language tasks, including text generation, question answering, summarization, and complex reasoning1. Their ability to produce fluent, contextually coherent responses has accelerated adoption across high-impact domains such as clinical decision support, legal analysis, software engineering, and educational technology2. However, a critical and persistent limitation undermines their reliability in these settings: hallucination, in which models generate responses that are linguistically fluent yet factually incorrect, unsupported, or entirely fabricated 3. Empirical studies report hallucination rates ranging from 15% to over 40% depending on the task and model, with even state-of-the-art systems such as GPT-4 exhibiting measurable factual inconsistencies under domain-specific evaluation2,3. This limitation poses serious risks in precision-critical applications where erroneous outputs can lead to misinformation, misdiagnosis, or flawed decision-making4. Hallucinations arise fundamentally from the probabilistic nature of language modeling - LLMs generate tokens by predicting statistically likely continuations of input sequences rather than by retrieving or reasoning over verified factual knowledge5. As a consequence, generated outputs may embed plausible-sounding but inaccurate claims, introduce unsupported assertions, or conflate semantically related but factually distinct concepts6.
Existing mitigation strategies address this problem through several paradigms, each with notable limitations. Retrieval-Augmented Generation (RAG) reduces hallucination by grounding responses in externally retrieved documents, but introduces significant latency overhead, requires access to maintained knowledge bases, and remains vulnerable to retrieval failures in specialized or low-resource domains7,8,9.
Although the response generator and reference generator are instantiated using the same underlying GPT-3.5 Turbo model, they operate under different prompting objectives and execution contexts. The response generator produces an unconstrained answer to the user query, whereas the reference generator performs an isolated factual recall task without access to the previously generated response. This separation reduces direct response-conditioning effects and limits confirmation bias during claim verification. The framework, therefore, treats the generated reference as procedurally independent rather than statistically independent.
Recent research has also explored lightweight decoding strategies to reduce hallucinations in text generation without relying on external retrieval or repeated verification. One representative approach is Decoding by Contrasting Layers (DoLA), which improves factuality by contrasting representations from intermediate and final transformer layers during decoding. Unlike post-generation verification frameworks, such methods intervene directly during token generation and therefore optimize a different stage of the language generation process. These complementary strategies demonstrate that hallucination mitigation can be achieved either during decoding or through post-generation verification, with each approach offering distinct trade-offs in computational overhead, implementation complexity, and factual reliability.
Self-consistency methods improve factual reliability by sampling multiple responses and selecting the most frequent or coherent output, yet their computational cost scales linearly with the number of samples, making them unsuitable for latency-sensitive deployments8. Iterative refinement approaches, which repeatedly revise outputs through self-feedback loops, progressively reduce error rates but substantially extend inference time with each additional pass9. NLI-based verification methods offer a more targeted alternative by evaluating semantic entailment between generated claims and reference texts, but existing implementations rely on fixed decision thresholds that fail to adapt across varying confidence distributions, domains, or model behaviors10,11. Collectively, these approaches either impose unacceptable computational overhead, depend on external infrastructure, or lack the adaptability required for generalized deployment. A comparison of the principal characteristics of these hallucination-verification approaches is provided in Supplementary Table 1.
This paper proposes a lightweight, two-step claim-verification framework designed to reduce hallucinations in LLM outputs while maintaining low response latency. In the first step, the LLM generates an initial response, which is then decomposed into atomic factual claims. In the second step, each claim is verified using Natural Language Inference against a separately generated factual reference produced through an isolated reasoning pass that does not access the original generated response, and a statistically derived confidence threshold governs the accept-or-correct decision at the claim level. The primary contributions of this work are as follows: (1) A two-step claim-level verification pipeline that decouples response generation from factual validation, enabling independent and targeted evaluation of each atomic claim without requiring external retrieval or full response regeneration; (2) An adaptive statistical thresholding mechanism based on the distribution of NLI confidence scores (τ = µ + kσ), which dynamically determines acceptance and correction boundaries rather than relying on fixed decision rules, improving robustness across varying confidence distributions; (3) A selective correction strategy that restricts regeneration to only those claims classified as contradictory, substantially reducing computational overhead compared to full-response resampling or iterative refinement approaches; (4) Empirical evaluation on a hallucination-focused benchmark demonstrating that the proposed framework reduces hallucination rates from 28% to 9% while maintaining response latency within practical deployment bounds.
Access restricted. Please log in or start a trial to view this content.
Protocol
This study did not involve human participants, animals, biological specimens, or patient data. Therefore, institutional ethical approval and informed consent were not required.
Study design overview
A two-stage verification framework was implemented to improve the factual reliability of large language model (LLM) outputs. The procedure consisted of response generation, claim extraction, Isolated Reference Construction, Natural Language Inference (NLI)-based verification, adaptive statistical decision-making, selective correction, and final response assembly. The framework was evaluated using TruthfulQA and FEVER benchmark datasets.
Overall workflow
User Query → Initial Response Generation → Claim Extraction → Independent Reference Generation → NLI Verification → Statistical Threshold Computation → Claim Correction → Final Verified Response. The overall workflow of the adaptive claim-verification framework is illustrated in Figure 1.
Dataset preparation
The TruthfulQA dataset12, containing 817 fact-oriented questions, was downloaded and prepared for evaluation. The FEVER dataset13 comprises 185,445 annotated claims labeled as Supported, Refuted, or Not Enough Information; the evaluation used the labeled development data with its claim, evidence, and ground-truth label fields. Each claim was evaluated against its provided evidence, while the original FEVER label was retained as the reference outcome for verification. The FEVER dataset, which contains fact-verification claim-evidence pairs, was obtained and preprocessed. Input questions and claims were converted into a standardized text format. Duplicate entries and incomplete samples were removed before experimentation. TruthfulQA was divided into validation and testing subsets. Approximately 20% of the TruthfulQA samples (164 questions) were used for threshold tuning, while the remaining 653 questions were reserved for performance evaluation. For FEVER, the benchmark-provided claims were used directly as verification units and did not undergo the response-generation and claim-extraction procedure applied to TruthfulQA. The characteristics of the benchmark datasets used for framework development and evaluation are summarized in Table 1.
Initial response generation
Each query was submitted to the base language model. Responses were generated using nucleus sampling with a temperature of 0.7 and a top-p of 0.9. The maximum output length was limited to 256 tokens. Generated responses were stored without any post-processing or manual modification. The generated text was forwarded directly to the claim extraction stage.
Claim extraction
Each generated response was decomposed into independently verifiable factual statements. A structured decomposition prompt was used to identify atomic claims. Compound statements were separated into minimal factual units. Subjective opinions, stylistic expressions, and conversational fillers were removed. Each extracted claim was stored as an independent verification unit.
Example:
Original response:
"Marie Curie was a Polish-born physicist and chemist who conducted pioneering research on radioactivity."
Extracted claims: (1) Marie Curie was Polish-born; (2) Marie Curie was a physicist and chemist; (3) Marie Curie conducted research on radioactivity.
Isolated reference construction:
For every extracted claim, an independent factual reference was generated. The verifier model received only the original user query. Access to the original generated response was restricted to avoid confirmation bias. A factual recall prompt was used to encourage concise, evidence-based responses. Generated references were stored for subsequent verification.
Natural language inference verification
Each claim-reference pair was submitted to a pre-trained NLI model. The NLI model classified the relationship as: Entailment, Neutral, or Contradiction. Confidence probabilities for all three classes were recorded. A signed verification score was assigned: Positive value for entailment, zero for neutral, or a negative value for contradiction. All verification scores were collected for threshold computation.
Adaptive statistical threshold computation
The verification confidence produced by the NLI model varies substantially across responses because different queries generate different numbers of claims, level of semantic complexity, and confidence distributions. A fixed global threshold assumes that all responses follow a similar confidence profile, which is rarely observed in practice. To accommodate this variability, the proposed framework estimates the decision boundary individually for each response using the mean and standard deviation of its verification scores. The mean reflects the overall confidence level of the response, while the standard deviation captures the dispersion of confidence values among the extracted claims. This adaptive formulation allows the acceptance criterion to adjust to response-specific uncertainty rather than relying on a single threshold for all inputs.
The mean (µ) and standard deviation (σ) of all signed verification scores were calculated.
The adaptive decision threshold was computed as:

where τ represents the adaptive threshold, µ denotes the mean verification score, σ denotes the standard deviation, and k represents the sensitivity parameter.
The sensitivity parameter was initialized at 0.7. Claims classified as Entailment with scores greater than or equal to +τ were accepted. Claims classified as Contradiction with scores less than or equal to −τ were marked for correction. Claims with scores within the interval (−τ, +τ) were retained as neutral.
Selective claim correction
A claim was forwarded for correction only when the NLI model classified the claim-reference pair as Contradiction, and its corresponding signed verification score satisfied the adaptive threshold criterion si ≤ -τ. Thus, the correction decision was jointly determined by the NLI class label and the response-specific statistical threshold. Claims classified as Entailment with si ≥ τ were accepted, whereas claims falling within the interval -τ < si < τ were treated as neutral and retained without correction. This combined criterion ensured that correction was applied only to claims exhibiting both semantic contradiction and sufficiently strong negative verification evidence.
Response reconstruction
Accepted and corrected claims were arranged in their original sequence. Sentence boundaries were restored to maintain readability. Minor grammatical adjustments were applied when necessary. The assembled output was stored as the final verified response.
Performance evaluation
The framework was evaluated using four metrics: (1) Accuracy: The proportion of responses that remained factually correct after verification; (2) F1 Score: The harmonic mean of hallucination detection precision and recall; (3) Response Latency: The total processing time from query submission to verified response generation; (4) Hallucination Rate
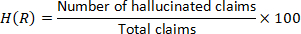
Latency was reported as the mean execution time across repeated measurements. Because individual per-run latency values were not retained, standard deviations and confidence intervals were not calculated.
Benchmark-specific correctness evaluation
For TruthfulQA, the final verified response was compared against the benchmark's human-validated answer references and lists of incorrect answers. A response was counted as correct when its factual claims were consistent with the accepted answer information and did not contain content corresponding to the identified incorrect response patterns. For FEVER, each claim in the final output was evaluated against its associated evidence and original FEVER annotation; Supported claims were treated as factually verified, while Refuted claims were counted as incorrect. Not Enough Information cases were retained as indeterminate rather than treated as positive factual evidence. The resulting claim-level decisions were aggregated across each benchmark to calculate the reported Accuracy and Hallucination Rate.
Experimental environment
The framework was implemented using Python 3.9. Data processing operations were performed using numerical and tabular analysis libraries. The NLI model operated in inference mode without additional fine-tuning. Experiments were executed on a workstation equipped with an Intel Core i5 processor, 16 GB RAM, and a 64-bit operating system. All evaluations were conducted using a single-pass inference setting to ensure low-latency operation. All experiments were conducted using identical hardware and software configurations to ensure consistent evaluation across datasets and baseline methods.
Expected outcome
The protocol is designed to generate claim-level verification decisions by identifying potentially unsupported claims and selectively forwarding strongly contradicted claims for correction. The expected output is a verified response with reduced factual inconsistencies and limited additional processing overhead, subject to the performance observed during experimental evaluation.
Access restricted. Please log in or start a trial to view this content.
Results
Initial response generation
The baseline language model generated fluent and contextually relevant answers for questions from both benchmark datasets. However, a detailed examination revealed unsupported and factually inaccurate statements in several responses. On the TruthfulQA dataset, the baseline system exhibited a hallucination rate of 28%, while a hallucination rate of 26% was observed on the FEVER dataset. These findings confirmed that direct language generation alone w...
Access restricted. Please log in or start a trial to view this content.
Discussion
The proposed framework improved factual-verification performance while avoiding repeated sampling and external retrieval. On TruthfulQA, the hallucination rate decreased from 28% for the baseline LLM to 9% with the complete framework, while accuracy increased from 0.72 to 0.87. On FEVER, the hallucination rate decreased from 26% to 10%, with accuracy increasing from 0.74 to 0.89. These comparisons should be interpreted within the experimental settings and implementations used in this study rather than as evidence of univ...
Access restricted. Please log in or start a trial to view this content.
Disclosures
The authors have no conflicts of interest to declare.
Acknowledgements
The authors would like to express their sincere gratitude to their institution for providing the academic environment and computational resources necessary to conduct this research. The authors also acknowledge the developers and maintainers of the publicly available benchmark datasets used in this study, which enabled a comprehensive evaluation of the proposed framework. Appreciation is extended to colleagues and reviewers for their constructive feedback, which helped improve the quality and clarity of this work. The authors further acknowledge the open-source research community for providing the software libraries and tools that facilitated experimentation, data analysis, and visualization of results. Their continued efforts have significantly advanced research in natural language processing and trustworthy artificial intelligence. The authors declare that no external financial support or funding was received for this research.
Access restricted. Please log in or start a trial to view this content.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| FEVER benchmark dataset | FEVER Shared Task (Thorne et al.) | https://fever.ai/dataset/fever.html | Publicly available fact-verification dataset of claim-evidence pairs used for evaluation |
| GPT-3.5 Turbo (large language B10+2:12:12 | OpenAI | Model ID: gpt-3.5-turbo; https://developers.openai.com/api/docs/models/gpt-3.5-turbo | Used as both the response generator and the independent reference generator, accessed via the OpenAI API |
| NumPy | NumPy Developers (open source) | https://numpy.org/ | Numerical computation library used for statistical calculations, including mean and standard deviation of NLI verification scores |
| Openai (Python API client library) | OpenAI | https://github.com/openai/openai-python | Python client library used to submit prompts to and retrieve completions from GPT-3.5 Turbo |
| pandas | pandas Development Team (open source) | https://pandas.pydata.org/ | Tabular data-analysis library used for dataset preprocessing and results handling |
| Pretrained Natural Language Inference (NLI) classification model | Hugging Face model hub (model built on Microsoft's DeBERTa-v3-large architecture) | MoritzLaurer/DeBERTa-v3-large-mnli-fever-anli-ling-wanli | Used in inference mode, without fine-tuning, to classify each claim-reference pair as entailment, neutral, or contradiction |
| Python | Python Software Foundation | Version 3.9; https://www.python.org/downloads/release/python-390/ | Core programming language used to implement the verification framework |
| SciPy | SciPy Developers (open source) | https://scipy.org/ | Scientific computing library used to support statistical analysis of experimental results |
| Transformers (Hugging Face Transformers library) | Hugging Face | https://github.com/huggingface/transformers | Python library used to load and run the pretrained NLI model |
| TruthfulQA benchmark dataset | Originally released by Lin, Hilton, and Evans | https://github.com/sylinrl/TruthfulQA | Publicly available benchmark of 817 fact-oriented questions used for threshold tuning and evaluation |
| Workstation computer | Not specified in manuscript (please confirm manufacturer/model) | Intel Core i5 processor; 16 GB RAM; 64-bit operating system | Hardware used to execute all experiments under identical configurations |
| Note: All URLs listed above were checked and confirmed active as of the date of this table. |
References
- Dai Z, et al. Promptagator: Few-shot dense retrieval from 8 examples [conference presentation]. Presented at: The Eleventh International Conference on Learning Representations; 2022. [https://iclr.cc/virtual/2023/poster/10937]
- Achiam J, et al. GPT-4 technical report. arXiv. 2023;arXiv:2303.08774. [https://arxiv.org/abs/2303.08774]
- Ji Z, et al. Survey of hallucination in natural language generation. ACM Comput Surv. 2023;55(12):1-38.
- Bender EM, McMillan-Major A, Shmitchell S, Gebru T. On the dangers of stochastic parrots: Can language models be too big? [conference presentation]. Presented at: 2021 ACM Conference on Fairness, Accountability, and Transparency; 2021. [https://dl.acm.org/doi/10.1145/3442188.3445922]
- Devlin J, et al. BERT: Pre-training of deep bidirectional transformers for language understanding [conference presentation]. Presented at: 2019 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies; 2019. [https://arxiv.org/abs/1810.04805]
- Maynez J, Narayan S, Bohnet B, McDonald R. On faithfulness and factuality in abstractive summarization [conference presentation]. Presented at: 58th Annual Meeting of the Association for Computational Linguistics; 2020. [https://arxiv.org/abs/2005.00661]
- Brown T, et al. Language models are few-shot learners. Adv Neural Inf Process Syst. 2020;33:1877-901.
- Guu K, et al. Retrieval augmented language model pre-training [conference presentation]. Presented at: International Conference on Machine Learning; 2020. [https://arxiv.org/abs/2002.08909]
- Izacard G, Grave E. Leveraging passage retrieval with generative models for open domain question answering [conference presentation]. Presented at: 16th Conference of the European Chapter of the Association for Computational Linguistics; 2021. [https://arxiv.org/abs/2007.01282]
- Bowman SR, Angeli G, Potts C, Manning CD. A large annotated corpus for learning natural language inference [conference presentation]. Presented at: 2015 Conference on Empirical Methods in Natural Language Processing; 2015. [https://arxiv.org/abs/1508.05326]
- Platt J. Probabilistic outputs for support vector machines and comparisons to regularized likelihood methods. Adv Large Margin Classif. 1999;10(3):61-74.
- Lin S, Hilton J, Evans O. Truthfulqa: Measuring how models mimic human falsehoods. InProceedings of the 60th annual meeting of the association for computational linguistics (volume 1: long papers) 2022 May (pp. 3214-3252).
- Thorne J, Vlachos A, Christodoulopoulos C, Mittal A. FEVER: A large-scale dataset for fact extraction and verification [conference presentation]. Presented at: 2018 Conference of the North American Chapter of the Association for Computational Linguistics: Human Language Technologies; 2018. [https://aclanthology.org/N18-1074/]
- Williams A, Nangia N, Bowman SR. A broad-coverage challenge corpus for sentence understanding through inference. arXiv. 2017;arXiv:1704.05426.
- Manakul P, Liusie A, Gales M. SelfCheckGPT: Zero-resource black-box hallucination detection for generative large language models [conference presentation]. Presented at: 2023 Conference on Empirical Methods in Natural Language Processing; 2023.
- Min S, et al. FActScore: Fine-grained atomic evaluation of factual precision in long-form text generation. arXiv. 2023;arXiv:2305.14251.
- Cohen J. Statistical power analysis for the behavioral sciences. Routledge; New York; 2013.
- Kadavath S, et al. Language models (mostly) know what they know. arXiv. 2022;arXiv:2207.05221.
- Hendrycks D, et al. Aligning AI with shared human values. arXiv. 2020;arXiv:2008.02275.
- Lewis P, et al. Retrieval-augmented generation for knowledge-intensive NLP tasks. Adv Neural Inf Process Syst. 2020;33:9459-74.
Access restricted. Please log in or start a trial to view this content.
Reprints and Permissions
This article has been published
Video Coming Soon