This study examines decision-making and revision behaviors of English majors translating China-focused narratives, integrating keystroke-logging records and a danmu corpus to reveal how textual salience influences processing effort and translation quality.
Research Article
Decision-Making and Revision Behavior in Chinese-to-English Translation: Evidence from English Majors Translating China-Focused Narratives
In This Article
Summary
Abstract
As China-focused narratives increasingly enter international circulation, Chinese-to-English translation has become a site of meaning negotiation rather than a straightforward linguistic transfer. For student translators, the primary challenge extends beyond lexical selection; it involves deciding how to render culturally saturated references, evaluative stances, and narrative positioning for readers outside the source context. This study examines the real-time decision-making and revision behaviors of 72 English majors translating China-focused narratives. Using a process-product design, the research integrates keystroke-logging data collected with Translog-II, translation product evaluations, and an auxiliary danmu (time-synced commentary) corpus treated as an audience-salience layer rather than as a direct measure of segment-level linguistic difficulty. Translation processes were analyzed across pause duration, revision frequency, revision location, and stage distribution, while product quality was assessed through expert rating and targeted coding of culture-related segments. A corpus of 18,642 danmu comments from 24 Bilibili videos was used to identify publicly salient narrative themes and culturally sensitive expressions. Results show that culture-loaded and evaluatively dense segments triggered longer pauses, increased recursive revisions, and denser mid-process reformulations. Higher-quality translations were associated with selective, strategically timed revisions at the discourse and cultural-adaptation levels rather than with a higher total revision count. The overlap between danmu-salient narrative triggers and high-effort translation segments is interpreted as convergent evidence of audience salience and translator processing pressure, not as evidence of causation. The study advances research on the translation process by linking revision behavior to culturally embedded narrative translation and offering implications for translator training in cross-cultural communication.
Introduction
In recent years, the translation of China-related discourse has moved from a relatively specialized concern to a central issue in international communication1. What is at stake in such translation is not simply the transfer of propositional content, but the re-articulation of public narratives that carry political positioning, cultural framing, and audience design. Work on the translation of Chinese political discourse has made this point increasingly clear: when texts are translated for readers outside China, choices about wording, modality, and textual emphasis also become choices about how China is narrated and interpreted abroad2. Once the problem is framed in that way, a product-only approach becomes insufficient. A finished translation can show what was chosen, but it cannot show when uncertainty emerged, where reformulation started, or how competing solutions were tested and abandoned3.
These limitations help explain why empirical translation process research has become an important strand within translation studies, using process-tracing tools to capture pauses, deletions, insertions, and the temporal shape of decision-making rather than inferring them indirectly from the final text4. This does not displace product, sociological, cultural, or corpus-based approaches; rather, it adds evidence about the moment-by-moment formation of translation decisions. Recent work has moved from describing isolated pauses to modeling translation as a temporally structured activity. The hesitation-orientation-flow taxonomy, for instance, treats translation behavior as a patterned alternation between uncertainty, search, and fluent production, explaining why particular stretches of a task become unstable and trigger reformulation5. This shift is especially relevant in student translation, where language proficiency, subject knowledge, and strategic control are still developing concurrently6.
Evidence from combined eye-tracking and keystroke logging shows that novice translators do not distribute attention evenly, and that target-text production often becomes a major site of cognitive load during Chinese-to-English translation7. Consequently, what appears as a local wording problem in the product may actually reflect a broader reorganization of attention and effort during the real-time process8. Recent evidence further suggests that student translators may produce texts with similar surface adequacy while differing substantially in the amount of effort, uncertainty, and self-monitoring required. A satisfactory final rendering may still rest on a fragile or inefficient decision path that can only be captured through process-sensitive measures9. Furthermore, comparative work indicates that translation expertise involves stable metacognitive control over when to pause, search, continue drafting, or return for revision10.
Revision is the exact point at which this hidden cognitive process becomes most visible. It is where translators return to earlier wording, test alternatives, and decide whether a problem is lexical, syntactic, discursive, or cultural. Consequently, revision should not be treated as a late polishing step but as a core indicator of translator development. Better outcomes are linked to how alternatives are consolidated during production, demonstrating that effective revision is selective, strategically timed, and responsive to greater textual demands rather than a simple accumulation of edits11,12,13.
The complexity of decision-making and revision becomes sharper when the source text is a China-focused narrative rather than a neutral informational passage. Such texts frequently rely on culturally saturated assumptions, historically situated expressions, and evaluative cues whose meaning depends on shared background rather than explicit exposition14,15,16. Text difficulty alters the very granularity of processing; narrative texts carrying cultural or evaluative density compel translators to work in smaller units, produce non-linear operations, and engage in repeated local restructuring8. For student translators, the central problem is deciding how much of that implicit background to unpack or reorganize for readers outside the original discourse community, without flattening cultural specificity.
Three specific gaps motivate the present study. First, translation process metrics such as pause duration, long-pause frequency, cursor interruption, and dictionary consultation are often examined separately from revision typologies, making it difficult to see how decision pressure becomes visible as later reformulation. Second, culturally specific narrative categories have received less process-based attention than general academic or expository texts, even though China-focused narratives often require translators to handle cultural load, evaluative density, and compressed background implication at the same time14,15,16. In this study, cultural load refers to the density of culture-bound references and shared presuppositions; evaluative density refers to explicit or implicit stance-taking, affective intensity, and value-laden framing; and narrative compression refers to the degree to which background information, causal relations, or social positioning is condensed into short textual spans. Third, translation tasks are usually designed solely on the basis of text-internal analysis, with little consideration of whether segments identified as difficult align with points that attract public attention in digital circulation. Danmu (time-synced video comments) can function as paratext and participatory discourse, highlighting what audiences notice, contest, and reinterpret17,18; however, danmu salience must be treated as a semantic-level indicator of audience engagement rather than as a direct substitute for segment-level linguistic difficulty.
Addressing these gaps, the present study examines how English majors make decisions and revise as they translate China-focused narratives from Chinese into English. By bringing translation-process data and digital audience discourse into the same analytical frame, the study aims to explain not only where student translators struggle but also why those struggles cluster around particular kinds of narrative meaning.
Specifically, this study addresses four research questions: (1) What decision-making patterns characterize English majors’ Chinese-to-English translation of China-focused narratives? (2) How do revision behaviors vary across segments with different levels of cultural load and narrative density? (3) Which dimensions of revision behavior are associated with higher translation quality? and (4) Do culturally salient points identified in danmu discourse overlap with the segments that generate the greatest processing effort during translation?
Correspondingly, the study tests four linked hypotheses in a single analytic sequence: H1 proposes that segments with higher cultural load will trigger longer pauses, greater decision uncertainty, and more frequent revision than segments with lower cultural load; H2 distinguishes two pathways, predicting that evaluative density will increase delayed revision while narrative compression will increase discourse-level reformulation; H3 predicts that translation quality will be explained more strongly by the selectivity and timing of revision than by total revision count alone; and H4 predicts that danmu-salient segments will overlap with high-effort translation segments as an associative convergence between audience salience and translator processing pressure.
Protocol
All methods involving human subjects were conducted in compliance with institutional guidelines and were approved by the institutional review board (IRB) or the human research ethics committee of Hanshan Normal University. Informed consent was obtained from all participants prior to the experiment.
Conceptual framework and research design
This study employed a process–product research design with an auxiliary discourse layer to examine how audience-generated danmu comments influence subtitle translation. The analytical framework integrated textual characteristics, indicators of the translation process, and translation quality outcomes. Specifically, it investigated whether audience attention, as reflected by danmu density, directed translators' cognitive resources toward particular textual features and whether this attentional allocation subsequently affected translation quality.
To operationalize this framework, the study first established segment-level textual features based on four dimensions: cultural load, evaluative density, narrative compression, and danmu salience. Cultural load referred to the presence of culturally specific references that required adaptation or explanation. Evaluative density measured the concentration of emotionally or attitudinally charged language within a segment. Narrative compression captured the extent to which semantic content was condensed under subtitle constraints. Danmu salience represented the degree of audience attention directed toward each subtitle segment, quantified by the volume of synchronized danmu comments. Unlike conventional measures of translation difficulty, danmu salience reflected socially distributed attention rather than intrinsic textual complexity. A segment receiving extensive audience engagement was not necessarily more difficult to translate; instead, it represented a point of heightened communicative significance within the viewing experience.
The analytical framework comprised three interconnected datasets. The participant-level dataset included individual demographic characteristics and translation expertise. The process–product dataset linked each subtitle segment to behavioral indicators extracted from keystroke logging, together with expert translation quality ratings. The danmu dataset contained synchronized audience comments aligned with subtitle timing, from which danmu salience values were computed. These datasets were linked via participant and segment identifiers, enabling simultaneous analysis of each translated subtitle segment in relation to translator characteristics, cognitive processing behavior, audience attention, and translation outcomes. The final integrated database comprised 216 complete translation sessions and 3,168 participant–text–segment observations, providing the empirical foundation for the subsequent process–product analyses.
Participant screening and background profiling
The sample comprised 72 English majors recruited from a public university in southern China, evenly distributed across the second, third, and fourth years of undergraduate study (24 participants per year group). All participants were native Chinese speakers receiving formal instruction in English writing and translation. To ensure comparability within the trainee-translator population, individuals who had resided in an English-speaking country for more than 6 months or held professional translator certification were excluded. Participants were not stratified into separate experimental groups according to translation experience, cultural familiarity, or second-language proficiency. Instead, year level, recent English proficiency test scores, prior translation coursework, self-rated familiarity with China-related cultural topics, and average weekly engagement in bilingual practice were recorded and included as participant-level covariates in the statistical models. This clarification also resolves the participant-number inconsistency raised during peer review: both the manuscript and the replication dataset include 72 participants, 216 task sessions, and 3,168 segment-level observations.
Source text selection and task construction
The translation materials consisted of three contemporary China-focused narrative texts developed specifically for this study to reflect authentic public discourse and avoid reproducing copyrighted materials. Each text contained 205–225 Chinese characters but differed systematically in its internal characteristics. Text A presents a Spring Festival homecoming narrative with moderate cultural load and relatively straightforward syntax. Text B recounts a Dragon Boat Festival memory and contains a higher density of culture-specific expressions and implicit background knowledge. Text C describes a rural livestreaming and e-commerce narrative characterized by dense evaluative language and compressed narrative positioning.
The texts were systematically segmented using clause boundaries, followed by meaning-unit boundaries, yielding 44 analyzable units across the three translation tasks (Table 1). Before formal coding, a coding manual defined cultural load, evaluative density, and narrative compression using 1–5 ordinal scales. A pilot study involving 12 students who did not participate in the main experiment confirmed the intended difficulty calibration, the clarity of the task instructions, and the stability of the segment boundaries for keystroke alignment.
Auxiliary corpus construction and salience mapping
To identify publicly salient narrative cues, an auxiliary danmu corpus was compiled from 24 Bilibili videos uploaded between January 2023 and December 2025. Videos were included only if they matched one of the three semantic domains represented in the source texts, had accumulated more than 50,000 views, contained dense danmu interaction, and permitted the export and thematic mapping of time-synchronized comments. After duplicate removal and filtering of emojis, onomatopoeic fillers, and irrelevant fragments, the final corpus comprised 18,642 comments.
Content words were standardized and clustered using source-text-related keyword anchors. Each source-text segment was then assigned a continuous danmu salience score based on a weighted composite of normalized keyword-cluster frequency, comment concentration within the corresponding thematic cluster, and mean evaluative intensity. This procedure enables comparisons between translator processing effort and audience salience at the semantic-cluster level rather than through direct lexical matching. Because danmu reflects audience responses to online videos rather than the experimental translation task itself, danmu salience is interpreted as an external indicator of audience engagement rather than direct evidence of the linguistic difficulty of a source segment.
Experimental procedure and data capture
Translation sessions were conducted individually in a controlled computer laboratory under standardized hardware, software, and internet-access conditions (Figure 2). Following a five-minute orientation emphasizing the production of readable English for an international audience, participants completed a three-minute English typing warm-up to minimize the effects of keyboard acclimatization. The three translation tasks were administered sequentially using Translog-II, with the task order counterbalanced in a Latin-square design to distribute potential fatigue and order effects evenly across participants. Participants were allocated a maximum of 20 minutes per text, separated by five-minute rest intervals.
Although the built-in bilingual dictionary was permitted, machine translation systems and external search engines were prohibited. All keystrokes, pauses, and cursor movements were logged automatically and supplemented by synchronous screen recordings to verify non-linear revision episodes. After completing each task, participants completed a self-reported difficulty assessment used solely to assist in interpreting borderline coding cases.
Process measurement and variable coding
Keystroke records were aligned with the predefined segment structure. An alignment episode began with the first target-language keystroke corresponding to a segment and ended when the participant definitively progressed to the next segment. Overlapping revisions were reassigned using time-stamped cursor-tracking records.
Decision-making behavior was quantified using five indicators: first-pause duration before initial segment translation, mean within-segment pause duration, the frequency of pauses exceeding two seconds, dictionary consultation counts, and cursor-based interruption counts indicating departures from linear drafting (Table 2). Revision behavior was classified along two dimensions: timing and function. Timing distinguished immediate local revisions from delayed revisions performed after drafting had progressed beyond the current segment. Functional coding classified revisions as surface revisions (form-level corrections without semantic change), meaning revisions (lexical or syntactic modifications), discourse-level revisions (adjustments to clause relationships or coherence), and cultural adaptation revisions (target-audience-oriented reformulations). Two trained coders independently analyzed each revision episode before adjudication and assigned a single primary functional category to each event. Inter-rater reliability was robust across all coded measures. Cohen’s ĸ indicated substantial agreement for the categorical coding of revision functions (ĸ = 0.84, p < 0.001). For the ordinal text-level variables, intraclass correlation coefficients (ICC, two-way mixed-effects model, absolute agreement) demonstrated high reliability for cultural load (ICC = 0.86), evaluative density (ICC = 0.78), and narrative compression (ICC = 0.82). Any initial coding discrepancies were subsequently resolved through joint adjudication.
Translation quality assessment
Translation quality was evaluated independently of the process data by two raters with doctoral-level training and extensive experience in translation instruction. Blinded to participant identities and process measures, the raters applied a 100-point rubric, evenly distributed across five dimensions: semantic accuracy, linguistic fluency, narrative coherence, cultural rendering, and register appropriateness (Table 3). Score discrepancies greater than eight points triggered joint review and consensus rescoring, with the adjudicated average used as the final translation quality score. The pre-adjudication rating records were retained to facilitate transparent reporting of inter-rater reliability in the replication materials.
Statistical modeling
The analyses proceeded in three sequential stages. First, descriptive statistics were computed to summarize all variables across year groups and text types. Second, segment-level processing effort was analyzed using mixed-effects regression models to account for the nested structure of segments within texts and repeated observations from individual participants. Dependent variables, including first-pause duration and revision frequency, were modeled as functions of cultural load, evaluative density, narrative compression, and danmu salience while controlling for participant proficiency. Predictor correlations, variance inflation diagnostics, 95% confidence intervals, effect-size estimates, and model-fit indices were included to improve statistical transparency.
Finally, translation quality was modeled to evaluate the predictive contributions of revision timing and revision function relative to overall revision frequency. The overlap between danmu-salient segments and high-effort translation segments was assessed using the upper quintile of each distribution, a standardized composite effort index, and a chance-overlap analysis. No exploratory factor analysis or structural equation modeling was performed. Accordingly, the accompanying figures are presented solely as conceptual, descriptive, or regression-based summaries.
Results
Overall profile of the translation sessions
All 72 participants completed the three translation tasks under standardized experimental conditions, yielding 216 complete translation sessions. Following segment alignment, the final analytical dataset comprised 3,168 participant-text-segment observations. The mean task completion time across the sample was 998.4 s per text, with clear differences across year groups and source texts (Table 4; Figure 3). Accordingly, both the manuscript and the accompanying data consistently support a sample size of n = 72 participants; any figures summarizing subsets should explicitly identify those subsets.
Fourth-year students completed the translation tasks more quickly and with fewer interruptions than second-year students. This difference extended beyond processing speed. The fourth-year cohort also exhibited shorter mean first-pause durations, fewer long pauses, and a lower total number of revisions, while achieving the highest translation quality scores. In contrast, second-year students produced the most revisions, most of which were surface-level modifications and immediate local corrections. Advanced students demonstrated a higher proportion of delayed revisions and cultural adaptation revisions, indicating that superior translation performance was associated with selective revision strategies rather than greater revision volume.
Differences among the three source texts were similarly pronounced. Text A produced the shortest completion times, the fewest long pauses, and the lowest revision density. Texts B and C both imposed greater processing demands, although through different mechanisms. Text B elicited the highest number of culture-related revision events, whereas Text C produced the highest frequency of discourse-level revisions and the longest mean within-segment pause duration. Thus, the source of processing difficulty differed across texts. In Text B, difficulty clustered around culture-bound references and implicit background assumptions, whereas in Text C, it was primarily associated with narrative compression and evaluative positioning.
A one-way analysis of variance confirmed significant differences among year groups in total translation quality, F (2, 69) = 31.84, p < 0.001, with a large effect size (η2 ≈ 0.48 based on participant-level mean scores). Post hoc comparisons showed that fourth-year students achieved significantly higher scores than third-year students, who in turn outperformed second-year students. The same pattern was observed for first-pause duration, long-pause frequency, and the delayed revision ratio. Collectively, these baseline findings establish two important points for the subsequent analyses. First, the three source texts differed in processing difficulty rather than merely in topical content. Second, higher translation quality was associated with a reorganization of translation processes rather than with a simple reduction in processing effort.
Effects of textual salience on decision-making and revision behavior
To determine whether segment-level textual properties predicted processing effort, mixed-effects models were estimated for first-pause duration, long-pause frequency, total revision density, and delayed revision density. Cultural load, evaluative density, narrative compression, and danmu salience were entered as fixed effects, with participant and segment included as random intercepts (Table 5; Figure 4). Predictor screening confirmed the absence of problematic multicollinearity, with all Variance Inflation Factor (VIF) values well below the conservative threshold of 2.5 (Maximum VIF = 1.45). To evaluate model fit and the proportion of variance explained, both marginal and conditional R2 values were calculated for all mixed-effects models (marginal R2 ranging from 0.08 to 0.19; conditional R2 ranging from 0.46 to 0.64). The complete variance components for random effects (participant and segment intercepts) and corresponding model-fit indices are detailed in Table 5. Coefficient estimates are interpreted together with their 95% confidence intervals rather than p-values alone.
Cultural load exhibited the strongest and most consistent effect across the models. In the first-pause model, each one-unit increase in cultural-load score was associated with a 0.91 s increase in first-pause duration (b = 0.91, SE = 0.12, 95% CI [0.67, 1.15], p < 0.001). Cultural load also significantly increased long-pause frequency (b = 0.19, SE = 0.04, 95% CI [0.11, 0.27], p < .001) and total revision density (b = 0.27, SE = 0.06, 95% CI [0.15, 0.39], p < .001). Thus, culture-loaded segments not only delayed initial processing but also increased the likelihood of subsequent reformulation.
Narrative compression demonstrated an equally robust but distinct pattern of effects. It was a strong predictor of discourse-level revision (b = 0.31, SE = 0.07, 95% CI [0.17, 0.45], p < .001) and significantly increased mean within-segment pause duration (b = 0.58, SE = 0.14, 95% CI [0.31, 0.85], p < .001). In practical terms, segments that condensed substantial background information into short textual spans were less likely to prompt immediate lexical substitution and more likely to require broader structural reconsideration.
Evaluative density also contributed significantly, although its primary effect was on delayed revision rather than initial decision latency. In the delayed-revision model, evaluative density yielded a positive coefficient (b = 0.23, SE = 0.05, 95% CI [0.13, 0.33], p < .001). Its effect on first-pause duration was comparatively modest (b = 0.34, SE = 0.13, 95% CI [0.09, 0.59], p = 0.010). These findings suggest that evaluative cues were not always recognized as bottlenecks in processing during initial translation. Instead, they frequently became problematic only after an initial draft had been produced, prompting translators to revisit issues of stance, tone, or narrative appropriateness.
Danmu salience remained a significant predictor after controlling for text-internal variables. It significantly predicted both first-pause duration (b = 0.36, SE = 0.14, 95% CI [0.09, 0.63], p = 0.011) and total revision density (b = 0.17, SE = 0.06, 95% CI [0.05, 0.29], p = 0.006). Although its effect size was smaller than those of cultural load and narrative compression, its consistent contribution suggests that segments that attract greater public attention in the danmu corpus also tend to require greater processing effort during translation. This finding is interpreted as convergent evidence of semantic salience rather than as evidence that danmu frequency directly causes translation difficulty.
Revision behavior and translation quality
Subsequent analyses examined whether translation quality was better explained by the overall quantity of revisions or by their temporal and functional characteristics. The quality model (Table 5) produced a clear pattern of results. The total number of revisions did not significantly predict translation quality (b = 0.04, 95% CI [-0.06, 0.14], p = 0.412), whereas both revision timing and revision function were significant predictors. Specifically, the delayed revision ratio (b = 1.12, 95% CI [0.39, 1.85], p = 0.003), discourse-level revisions (b = 1.76, 95% CI [0.96, 2.56], p < 0.001), and cultural adaptation revisions (b = 2.04, 95% CI [1.14, 2.94], p < 0.001) were all positively associated with translation quality. In contrast, surface revisions exhibited a small but statistically significant negative association (b = -0.63, 95% CI [-1.18, -0.08], p = 0.028).
These findings indicate that revision quantity alone cannot distinguish productive reformulation from unstable drafting (Figure 5). Qualitative inspection of the translation scripts supported this interpretation. In lower-scoring translations, revisions tended to cluster around local lexical substitutions and grammatical corrections without resolving deeper mismatches between Chinese narrative cues and English rhetorical framing. In higher-scoring translations, delayed revisions frequently involved reorganizing the information structure, introducing selective explicitation, or adjusting evaluative language to improve accessibility for an international readership. Representative translated danmu comments—including “this expression is very Chinese,” “the background needs to be explained,” and “foreign audiences may not understand this reference”—illustrate the types of culturally salient audience concerns associated with the corresponding segment clusters. These examples are presented solely to facilitate interpretation and should not be construed as evidence of participants’ intentions.
Overlap between danmu salience and translation bottlenecks
The final analysis examined whether publicly salient segments in the danmu corpus overlapped with those generating the greatest processing effort during translation. A composite effort index was calculated for each segment by standardizing and summing first-pause duration, long-pause frequency, and revision density. The top 20% of segments based on this composite effort index were then compared with the top 20% ranked by danmu salience.
The overlap was substantial: six of the nine highest-effort segments also appeared among the nine most danmu-salient segments, corresponding to a 66.7% overlap rate. Because the top-quintile comparison involved only nine segments, the Wilson confidence interval was relatively wide (95% CI approximately 35.4%–87.9%). Nevertheless, an exact chance-overlap analysis indicated that an overlap of six or more segments would be unlikely under random allocation (p ≈ .001). At the segment level, danmu salience was positively correlated with the composite effort index (Spearman's ρ = 0.41, p = 0.006). Most overlapping segments occurred in Texts B and C and centered on culturally embedded references, digital entrepreneurship, and evaluative positioning. These findings suggest that public discourse serves as an external indicator of where narrative meaning becomes particularly salient, though the relationship remains correlational rather than causal.
Taken together, these findings demonstrate that processing effort in translating China-focused narratives is segment-specific and primarily shaped by cultural load, narrative compression, and evaluative density. Translation quality depends not on overall revision volume but on delayed, discourse-sensitive, and culturally oriented revision strategies. Finally, the observed alignment between high-effort translation segments and danmu-salient narrative points supports an associative relationship between audience salience and translator processing effort, without implying that danmu salience itself causes translation difficulty.
DATA AVAILABILITY:
All raw data, keystroke logging files, processed segment-level observations, session-level observations, danmu-video metadata, and the first 5,000 displayed danmu comments are provided in the replication dataset workbook. The full danmu-comment file contains 18,642 comments and is deposited with the dataset package. The dataset can be accessed through the Zenodo repository at https://doi.org/10.5281/zenodo.19289665.
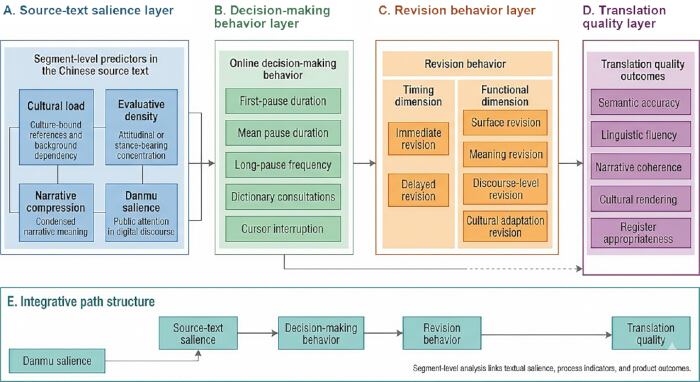
Figure 1: Conceptual framework of the study. (A) Segment-level textual predictors, including cultural load, evaluative density, narrative compression, and danmu salience. (B) Process indicators used to operationalize online decision-making behavior, including first-pause duration, mean pause duration, long-pause frequency, dictionary consultations, and cursor interruptions. (C) Two-dimensional classification of revision behavior according to revision timing and revision function. (D) Five dimensions used to evaluate translation quality: semantic accuracy, linguistic fluency, narrative coherence, cultural rendering, and register appropriateness. (E) Overall analytical framework showing the relationships among source-text salience, decision-making behavior, revision behavior, and translation quality, with danmu salience serving as an external indicator of semantic audience prominence. No exploratory factor analysis (EFA) or structural equation modeling (SEM) was performed or is presented in this study. Please click here to view a larger version of this figure.
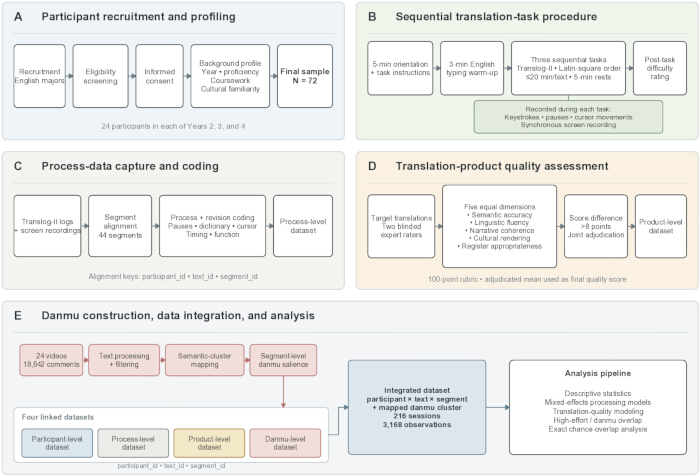
Figure 2: Workflow of data collection and data alignment. (A) Participant recruitment, eligibility screening, informed consent, and collection of background information. (B) Administration of the three translation tasks in Translog-II under standardized experimental conditions. (C) Collection of process data, including keystrokes, pauses, cursor movements, revision episodes, and synchronized screen recordings. (D) Blind expert assessment of translation products, followed by adjudication of scoring discrepancies. (E) Construction of the auxiliary danmu corpus and its alignment with participant-, text-, segment-, process-, and product-level datasets to generate the final integrated dataset used for inferential analyses. Please click here to view a larger version of this figure.
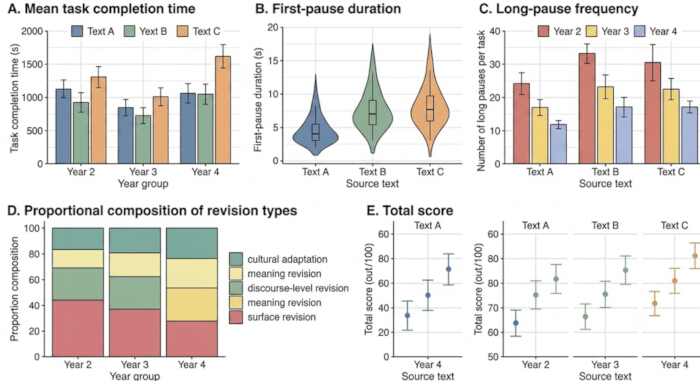
Figure 3: Distribution of process and product measures across year groups and source texts. (A) Mean task completion time by source text and year group. (B) Distribution of first-pause duration across the three source texts. (C) Long-pause frequency by source text and year group. (D) Proportional distribution of revision categories across year groups, including surface revisions, meaning revisions, discourse-level revisions, and cultural adaptation revisions. (E) Total translation quality scores by year group for each source text. Collectively, the panels show that higher year levels are associated with fewer processing interruptions, more selective revision strategies, and higher translation quality, whereas Texts B and C impose greater processing demands than Text A. Please click here to view a larger version of this figure.
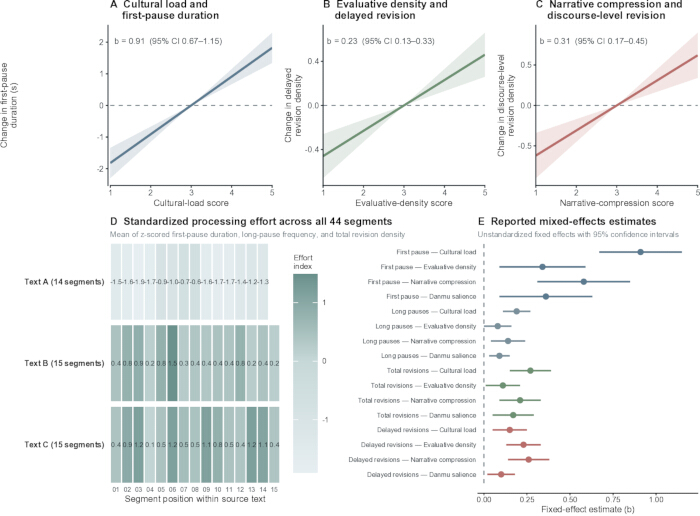
Figure 4: Effects of segment-level textual salience on translation process behavior. (A) Fitted marginal effect of cultural load on first-pause duration. (B) Fitted marginal effect of evaluative density on delayed revision density. (C) Fitted marginal effect of narrative compression on discourse-level revision density. (D) Heatmap of the standardized processing-effort index across all source-text segments, grouped by source text. (E) Standardized fixed-effect coefficients estimated from the mixed-effects regression models. The figure demonstrates that different textual characteristics activate distinct processing pathways, with cultural load, evaluative density, and narrative compression contributing to hesitation and revision through partially different mechanisms. Please click here to view a larger version of this figure.
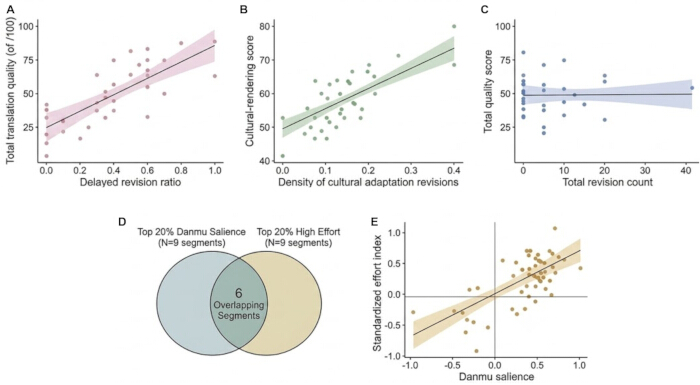
Figure 5: Relationships between translation process, translation quality, and danmu salience. (A) Association between the delayed revision ratio and total translation quality score. (B) Relationship between revisions to cultural adaptation and the cultural-rendering score. (C) Association between total revision count and overall translation quality, demonstrating the limited predictive value of revision quantity alone. (D) Overlap between the top 20% of danmu-salient segments and the top 20% of high-effort translation segments. (E) Segment-level association between danmu salience and the standardized processing-effort index. Collectively, the panels show that successful translation performance is associated with strategically timed, functionally targeted revision rather than revision volume alone, and that publicly salient narrative segments also tend to coincide with translation bottlenecks. Please click here to view a larger version of this figure.
| Text ID | Narrative topic | Chinese characters | Number of segments | Cultural-load score (1–5) | Evaluative-density score (1–5) | Narrative-compression score (1–5) | Predicted difficulty | Validation note |
| Text A | Spring Festival return-home narrative | 212 | 14 | 3 | 2 | 3 | Moderate | Pilot-tested with 12 non-participant students |
| Text B | Dragon Boat Festival memory narrative | 219 | 15 | 5 | 3 | 4 | High | Pilot-tested with 12 non-participant students |
| Text C | Rural livestreaming and hometown development narrative | 223 | 15 | 4 | 5 | 4 | High | Pilot-tested with 12 non-participant students |
Table 1: Source-text profile and segment structure.
| Variable | Level | Operational definition | Measurement unit |
| First-pause duration | Segment | Time from segment onset to the first relevant target-language keystroke | Seconds |
| Mean within-segment pause duration | Segment | Mean duration of all pauses within the segment | Seconds |
| Long-pause frequency | Segment | Number of pauses longer than 2 seconds | Count |
| Dictionary consultations | Segment | Number of dictionary-window activations during segment processing | Count |
| Cursor interruptions | Segment | Number of cursor-based departures from linear drafting before stable completion | Count |
| Immediate revision | Segment | Revision made before drafting moves beyond the current local text area | Count / density |
| Delayed revision | Segment | Revision made after drafting has progressed to a later text area | Count / density |
| Surface revision | Revision function | Form-level correction without a semantic shift | Count / density |
| Meaning revision | Revision function | Lexical or syntactic alteration affecting meaning expression | Count / density |
| Discourse-level revision | Revision function | Adjustment to clause relations, coherence, or information order | Count / density |
| Cultural adaptation revision | Revision function | Target-audience-oriented reframing or explicitation of culture-bound meaning | Count / density |
| Composite effort index | Segment | Standardized composite of first-pause duration, long-pause frequency, and revision density | z-score |
| Danmu salience | Segment / semantic cluster | Weighted semantic-cluster proxy based on normalized keyword-cluster frequency, comment concentration, and evaluative intensity | Continuous score |
Table 2: Operational definitions of process variables.
| Dimension | Score range | Scoring focus |
| Semantic accuracy | 1-20 | Fidelity to source meaning, precision of transferred content, and absence of major distortion |
| Linguistic fluency | 1-20 | Grammaticality, naturalness, idiomaticity, and sentence-level readability |
| Narrative coherence | 1-20 | Information flow, clause linkage, progression, and textual stability |
| Cultural rendering | 1-20 | Handling of culture-bound references, explicitation, framing, and interpretive accessibility |
| Register appropriateness | 1-20 | Fit to intended readership, stylistic suitability, and control of tone |
Table 3: Translation quality rating rubric.
| Section | Variable | Year 2 (n = 24), mean ± SD | Year 3 (n = 24), mean ± SD | Year 4 (n = 24), mean ± SD |
| Participant-level session profile | Task completion time (sec) | 1070.84 ± 18.22 | 996.59 ± 20.08 | 927.76 ± 19.91 |
| Participant-level session profile | Mean first-pause duration (sec) | 7.09 ± 0.50 | 6.65 ± 0.40 | 6.38 ± 0.41 |
| Participant-level session profile | Long-pause frequency per task | 21.04 ± 0.32 | 18.47 ± 0.30 | 16.31 ± 0.19 |
| Participant-level session profile | Total revisions per task | 28.65 ± 2.87 | 26.24 ± 2.63 | 24.59 ± 2.42 |
| Revision configuration | Delayed revision ratio | 0.45 ± 0.01 | 0.54 ± 0.01 | 0.63 ± 0.01 |
| Revision configuration | Discourse-level revision ratio | 0.37 ± 0.01 | 0.40 ± 0.01 | 0.45 ± 0.01 |
| Revision configuration | Cultural adaptation revision ratio | 0.38 ± 0.01 | 0.42 ± 0.00 | 0.48 ± 0.01 |
| Revision configuration | Surface revision ratio | 0.04 ± 0.00 | 0.02 ± 0.00 | 0.00 ± 0.00 |
| Product quality | Total quality score | 77.82 ± 4.65 | 84.03 ± 4.44 | 88.27 ± 4.56 |
| Product quality | Cultural-rendering score | 77.73 ± 4.49 | 83.95 ± 4.85 | 88.18 ± 4.86 |
Table 4: Descriptive statistics for process and product variables.
| Outcome variable | Predictor | b | SE | 95% CI | t/z | p |
| First-pause duration | Cultural load | 0.91 | 0.12 | [0.67, 1.15] | 7.58 | < 0.001 |
| First-pause duration | Evaluative density | 0.34 | 0.13 | [0.09, 0.59] | 2.62 | 0.01 |
| First-pause duration | Narrative compression | 0.58 | 0.14 | [0.31, 0.85] | 4.14 | < 0.001 |
| First-pause duration | Danmu salience | 0.36 | 0.14 | [0.09, 0.63] | 2.55 | 0.011 |
| Long-pause frequency | Cultural load | 0.19 | 0.04 | [0.11, 0.27] | 4.75 | < 0.001 |
| Long-pause frequency | Evaluative density | 0.08 | 0.04 | [0.00, 0.16] | 2 | 0.046 |
| Long-pause frequency | Narrative compression | 0.14 | 0.05 | [0.04, 0.24] | 2.8 | 0.005 |
| Long-pause frequency | Danmu salience | 0.09 | 0.03 | [0.03, 0.15] | 3 | 0.003 |
| Total revision density | Cultural load | 0.27 | 0.06 | [0.15, 0.39] | 4.5 | < 0.001 |
| Total revision density | Evaluative density | 0.11 | 0.05 | [0.01, 0.21] | 2.2 | 0.028 |
| Total revision density | Narrative compression | 0.21 | 0.06 | [0.09, 0.33] | 3.5 | < 0.001 |
| Total revision density | Danmu salience | 0.17 | 0.06 | [0.05, 0.29] | 2.75 | 0.006 |
| Delayed revision density | Cultural load | 0.15 | 0.05 | [0.05, 0.25] | 3 | 0.003 |
| Delayed revision density | Evaluative density | 0.23 | 0.05 | [0.13, 0.33] | 4.6 | < 0.001 |
| Delayed revision density | Narrative compression | 0.26 | 0.06 | [0.14, 0.38] | 4.33 | < 0.001 |
| Delayed revision density | Danmu salience | 0.1 | 0.04 | [0.02, 0.18] | 2.5 | 0.013 |
| Total quality score | Total revisions | 0.04 | 0.05 | [-0.06, 0.14] | 0.82 | 0.412 |
| Total quality score | Delayed revision ratio | 1.12 | 0.37 | [0.39, 1.85] | 3.03 | 0.003 |
| Total quality score | Discourse-level revisions | 1.76 | 0.41 | [0.96, 2.56] | 4.29 | < 0.001 |
| Total quality score | Cultural adaptation revisions | 2.04 | 0.46 | [1.14, 2.94] | 4.43 | < 0.001 |
| Total quality score | Surface revisions | -0.63 | 0.28 | [-1.18, -0.08] | -2.25 | 0.028 |
| Total quality score | Year group | 3.48 | 0.69 | [2.13, 4.83] | 5.04 | < 0.001 |
Table 5: Mixed-effects models predicting segment-level process behavior and translation quality.
Discussion
The present findings demonstrate that difficulty in the Chinese-to-English translation of China-focused narratives is not evenly distributed across a text. Instead, it clusters in segments where cultural references, evaluative stances, and compressed narrative meanings converge. This supports a process-based, rather than a vocabulary-deficit, view of translation difficulty. Empirical translation process research emphasizes that translation is a temporally organized activity in which hesitation, orientation, and production are unevenly distributed19. The concentration of effort observed in this study reflects how specific segments impose greater interpretive pressure, disrupting linear drafting more profoundly than others do. Hypothesis testing can be summarized as follows: H1 was supported because cultural load increased early hesitation and revision density; H2 was refined because evaluative density and narrative compression operated through different revision pathways; H3 was supported because revision timing and function predicted quality more strongly than total revision count; and H4 was supported as an associative overlap between danmu salience and high-effort segments, not as a causal relationship.
Regarding revision behavior, the data reveal that the total revision count does not predict translation quality; rather, delayed, discourse-level, and cultural adaptation revisions are the primary drivers of better performance. This distinction suggests that revision is productive only when executed as a structured re-evaluation rather than as repeated local repair. Consistent with eye-tracking and keystroke-logging research indicating that novice translators allocate effort differently when tasks become difficult, stronger students in this study were not merely more active7. They selectively interrupted provisional solutions, reassessed them at later stages, and directed revisions toward narrative or cultural fit. Consequently, product scores alone are insufficient for explaining translator performance, as comparable final scores often emerge from vastly different process trajectories9.
This phenomenon is best understood through the lens of effort conversion. In lower-scoring translations, cognitive effort remained trapped at the local level—students paused, substituted lexical items, or adjusted articles, yet failed to resolve deeper mismatches between source-text implications and target-text framing. Conversely, higher-scoring scripts showed effort converted into structural decisions that optimized the text for the target reader. Paralleling research on student post-editing performance, these results confirm that process effort is not automatically beneficial; its value depends on its conversion into interpretable textual improvement20.
Furthermore, different textual properties activate distinct process mechanisms. Cultural load reliably increased early hesitation and revision density, whereas narrative compression strongly predicted discourse-level revision. This distinction clarifies why difficult segments manifest differently during the translation process: some disrupt cognitive access at the initial formulation stage, while others become problematic only during the maintenance of coherence across broader stretches of discourse. Aligned with studies showing that difficult texts yield smaller processing units and denser interruptions, these findings underscore how compressed cultural and evaluative meanings force translators to oscillate between local expression and global narrative framing8.
A significant methodological contribution of this study is the integration of danmu salience as an audience-discourse layer. The substantial overlap between high-effort translation segments and danmu-salient segments indicates that the bottlenecks students encounter often coincide with points that attract heightened audience attention in digital circulation. This connects translation difficulty to participatory discourse without collapsing the two constructs. Danmu comments reveal what audiences notice or contest in video-mediated circulation, whereas keystroke and revision records reveal how student translators process semantically related segments of the source text. The most plausible interpretation is therefore a common-cue account: culturally loaded references, compressed background assumptions, and evaluative positioning can simultaneously attract audience attention and increase translator processing pressure21.
Pedagogically, this overlap suggests that China-focused narratives circulate in contexts where meaning is negotiated publicly and rapidly, governed by competing priorities such as immediacy, intelligibility, and audience alignment22. Consequently, translator training must shift from viewing revision as a generic proofreading stage to emphasizing functional and temporally strategic interventions. The bottlenecks observed were rarely created by terminology alone; they emerged where narrative meaning depended on culturally grounded presuppositions, relational framing, and selective audience access. Similar to the dissemination of Chinese ethnic narrative literature, transferring these narratives requires moving beyond lexical fidelity to determine how local cultural meaning should be restructured for broader global circulation23. The method can be applied in translator training by using keystroke logs, screen recordings, and audience-discourse examples to help students identify when a segment requires explicitation, reordering, cultural framing, or register adjustment rather than simple lexical replacement.
Several limitations bound the interpretation of these findings. First, danmu salience is a semantic-cluster proxy for audience engagement, not a direct measure of linguistic difficulty, and the present correlational design cannot establish causation between public salience and translation effort. Future work could manipulate cultural load, evaluative density, and narrative compression experimentally to test causal pathways. Second, the sample is limited to trainee translators from one university, and participant experience, cultural familiarity, and second-language proficiency were controlled statistically rather than through fully stratified sampling. Replication with professional translators, students from multiple institutions, and broader proficiency bands would strengthen generalizability. Third, the source texts were researcher-constructed and pilot-tested to calibrate the task, but future studies should include additional validation using authentic public texts and independent material-development panels. Fourth, the coding of cultural load, evaluative density, narrative compression, and revision functions depends on transparent operational definitions, independent coder records, and verifiable inter-rater reliability alongside the adjudicated coding file. Future research may also combine keystroke logging with eye-tracking, retrospective interviews, think-aloud protocols, or post-editing tasks to triangulate the cognitive mechanisms underlying revision decisions.
Ultimately, this study clarifies the process basis of student performance in the Chinese-to-English translation of China-focused narratives. By connecting keystroke-logging data, product assessment, and digital audience discourse, the findings demonstrate that translation bottlenecks arise at points of publicly charged narrative meaning. The decisive factor in cross-cultural translation is not the sheer volume of revision but the translator’s ability to recognize segments that require interpretive restructuring and to strategically delay closure until a stable, audience-appropriate solution is formulated.
Disclosures
The authors have nothing to disclose.
Author Contributions
Weijia Chen: Conceptualization, methodology, formal analysis, investigation, writing-original draft.
Chunming Wu: Study design, guidance on formal analysis and data-handling procedures, and review and feedback on revisions in response to reviewer comments.
Acknowledgements
This research was financially supported by two grants from Hanshan Normal University. Specifically, it constitutes a phased research outcome of the 2023 First-Class Undergraduate Course (Offline First-Class Course) program for "Theory and Practice of Chinese–English Translation II" (Approval No. YHS [2023] 172). Furthermore, the study was supported by the 2025 Teaching Quality and Teaching Reform Project, designated as a Model Course for Curriculum-Based Ideological and Political Education for "Chinese–English Translation" (Approval No. YHSJ〔2025〕126). The authors gratefully acknowledge the institutional support provided for the completion of this research.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| Bilibili danmu corpus | Bilibili | 24 videos; 18,642 comments;https://www.bilibili.com | Construction of the auxiliary danmu corpus and calculation of segment-level danmu salience |
| Microsoft Excel | Microsoft Corporation | Excel 2021;https://www.microsoft.com/microsoft-365/excel | Data cleaning, coding organization, and preliminary data management |
| R | R Foundation for Statistical Computing | R 4.3.1;https://www.r-project.org | Mixed-effects modeling, correlation analysis, and figure generation |
| Screen recording software | Laboratory workstation | Local workstation utility; no catalog number | Verification of non-linear revision episodes and backup of process data |
| SPSS | IBM Corporation | SPSS Statistics 27.0;https://www.ibm.com/products/spss-statistics | Descriptive statistics, ANOVA, and basic statistical analyses |
| Translog-II | Copenhagen Business School / CRITT | Translog-II;https://sites.google.com/site/centretranslationinnovation/translog-ii | Keystroke logging and recording of pauses, cursor movements, and revision episodes during translation tasks |
References
- Valdeón RA, Li S. Political discourse translation in contemporary Chinese and Western contexts. Translator. 2024;30(4):1-14.
- Du L, Afzaal M. Analyzing modality-mediated ideology in translated Chinese political discourses: An ideological square model approach. Humanit Soc Sci Commun. 2024;11:956.
- Carl M. Empirical translation process research: Past and possible future perspectives. Transl Cogn Behav. 2024;6(2):252-274.
- Qassem M, Al Thowaini BM. Cognitive processes and translation quality: Evidence from keystroke-logging software. J Psycholinguist Res. 2023;52(5):1589-1604.
- Carl M, et al. Hesitation, orientation, and flow: A taxonomy for deep temporal translation architectures. Ampersand. 2024;12:100164.
- Swar O, Mohsen M. Students' cognitive processes in L1 and L2 translation: Evidence from a keystroke logging program. Interact Learn Environ. 2023;31(10):6247-6263.
- Wang Y, Li S, Rasmussen YZ. Translators' allocation of cognitive resources in two translation directions: A study using eye-tracking and keystroke logging. Appl Sci. 2025;15(8):4401.
- Wang F, Xu Q. Processing of translation units by student and semi-professional translators in translating texts with different levels of translation difficulty. PLoS One. 2025;20(4):e0320809.
- Chen X, Yan JX. Examining student translators' writing and translation products: Quality, errors, and self-perceived mental workload. Interpret Transl Train. 2024;18(3):465-485.
- Dong D, Chen ML. Metacognitive strategies in translation: A comparative study of student and professional translators. Humanit Soc Sci Commun. 2025;12:890.
- Chen X, Yan JX. Investigating the processing effort in translation students' L2 writing and L2 translating: Evidence from keylogging. Humanit Soc Sci Commun. 2025;12:1810.
- Cao L, Doherty S, Lee JF. The process and product of translation revision: Empirical data from student translators using eye tracking and screen recording. Interpret Transl Train. 2023;17(4):548-565.
- Van Egdom GW, Schrijver I, Verplaetse H, Segers W. The impact of collaborative processes on target text quality in translator training. Interpret Transl Train. 2024;18(3):486-506.
- Riondel A. How to teach revision: Tips from an interview study. Interpret Transl Train. 2024;18(3):507-522.
- Lu S, Chen X. An experimental study on viewing perception and gratification of danmu subtitled online video streaming. J Spec Transl. 2024;42:217-238.
- Lei Y, Peng M, Han Y. Mistaken presuppositions and the translation of cultural texts: A study of two English translations of The Classic of Tea. Perspectives. 2025. doi:10.1080/0907676X.2025.2599854.
- Kim HR. Danmu as paratext: An exploratory study of paratextual functions in Chinese fan-subtitled videos. J Transl Stud. 2025;26(3):197-231.
- Wu X, Fitzgerald R. The danmu discourse of user engagement with cross-posted broadcast interviews in Chinese social media. Journalism. 2025;26(3):733-751.
- Yamada M, Carl M, Schaeffer MJ. Introduction to the special Ampersand issue on empirical translation process research. Ampersand. 2024;12:100179.
- Peng X, Wang X, Li X. When student translators meet with machine translation: The impacts of machine translation quality and perceived self-efficacy on post-editing performance. SAGE Open. 2024;14(4):21582440241291624.
- Yang Y. Making sense of the raw meat: A social semiotic interpretation of user translation on the danmu interface. Discourse Context Media. 2021;44:100550.
- Zeng D. Danmu subtitling as a self-regulative practice: A descriptive discourse analysis of Bilibili danmu subtitles from ethical perspectives. Front Psychol. 2025;16:1577260.
- Li Y, Cai X. The translation of ethnic literature: An analysis of the Chinese and English translations of the Yi folk narrative poem Ashima and their dissemination. Perspectives. 2025. doi:10.1080/0907676X.2025.2502935.