This protocol presents MAS4SysML, a multi-agent approach that automatically generates SysML v2 code through coordinated task division, requiring few repair iterations and significantly reducing manual modeling time while improving system modeling efficiency.
Research Article
MAS4SysML: A Multi-Agent Framework for SysML v2 Model Generation from Natural Language
In This Article
Summary
Abstract
Automatically generating accurate SysML models from natural-language requirements can substantially accelerate the adoption of Model-Based Systems Engineering (MBSE) in complex system development. However, using large language models (LLMs) to generate model code often fails to meet the strict syntactic constraints of formal modeling languages, and consistently ensuring semantic alignment between generated models and requirements remains challenging. To address these challenges, this paper presents MAS4SysML, a multi-agent collaborative framework for SysML v2 code generation that improves syntactic correctness and semantic consistency under a constrained repair budget. The framework decomposes a modeling task into hierarchical subtasks, formalizes them as structured task cards, and generates model code in a bottom-up manner. During generation, an official validation environment is used for syntax diagnostics; after completion, the framework verifies semantic consistency between the code and the task cards. If syntax or semantic validation fails, the framework iteratively repairs and revalidates the code within a predefined repair budget, guided by diagnostic feedback, until the validation criteria are satisfied or the budget is exhausted. To evaluate the proposed method, we construct a SysML v2 dataset spanning five core task types—requirements, use cases, structure, parametrics, and state machines—and conduct comparative experiments. Results show that MAS4SysML reduces the average syntax error rate to 2.63, increases semantic similarity to 0.91, and outperforms existing code-generation methods overall.
Introduction
MBSE has become a key methodology for requirements analysis, system architecture design, and verification planning in the development of complex equipment in domains such as aviation and aerospace1. Using unified modeling languages such as SysML as the modeling backbone, information—including requirements, structure, behavior, and constraints—can be organized into a coherent model framework, improving process structure and the efficiency of cross-disciplinary collaboration2. However, as system scale continues to grow, the number of models that must be developed increases accordingly, leading to a sustained rise in the workload of manual SysML modeling. Moreover, modelers must work under strict syntactic and methodological constraints, which require substantial expertise and strong abstraction capabilities. These factors have become a major bottleneck in the engineering adoption of MBSE3.
In recent years, LLMs have demonstrated strong capabilities in natural language understanding, structured information representation, and code generation, enabling new opportunities for automating MBSE modeling from natural language to model code4. Prior studies have explored the direct generation of SysML model code using LLMs5. Nevertheless, significant challenges remain. Syntactically, SysML's type system, scoping mechanisms, and reference semantics are governed by strict formal constraints and are often more intricate than those of general-purpose programming languages6. Semantically, LLMs may fail to fully capture behavioral logic, structural relationships, and cross-layer constraints, resulting in missing relations, logical inconsistencies, or incomplete models7. These limitations hinder the reliability, controllability, and interpretability of direct-generation approaches.
To address these challenges, this paper presents MAS4SysML, a SysML v2 code-generation framework comprising four agent roles. Rather than directly targeting the one-shot generation of a complete cross-view system model, this study focuses on generating and iteratively repairing multiple representative SysML v2 modeling tasks. Driven by task decomposition and structured task cards, and integrating code generation, tool-level syntax diagnostics, and semantic consistency verification, MAS4SysML establishes a closed-loop workflow of generation, validation, and repair. This design improves the syntactic correctness, semantic consistency, and structural completeness of the generated code under a constrained repair budget.
The main contributions are summarized as follows: (1) MAS4SysML framework. We propose MAS4SysML, a multi-agent, LLM-driven framework that enables end-to-end generation from natural-language requirements to executable SysML v2 model code, providing a practical pathway to reduce modeling cost and improve modeling efficiency. (2) Task parsing and dual validation. We introduce a task-structure-tree parsing mechanism and a dual validation scheme (syntax and semantics). In task parsing, modeling objectives are hierarchically decomposed and formalized into structured task cards. For validation, syntax diagnostics leverage an official validation environment8 to check generated code and return repair-oriented diagnostics, while semantic validation uses key fields in the task cards as references to assess overall consistency between the generated model and modeling objectives. (3) Experimental evaluation. We conduct comparative experiments using syntax error rate and semantic consistency score as the primary metrics. The results show that MAS4SysML reduces the average syntax error rate to 2.63 and increases semantic similarity to 0.91, outperforming baseline methods in generation accuracy and automation.
Protocol
The code generation process of the MAS4SysML framework is summarized in Supplementary File 1. It should be noted that this study does not aim to achieve the one-shot generation of a complete system model from natural language with strict cross-view consistency, including requirements, structure, parametrics, and behavior. Instead, the protocol focuses on generating several representative types of SysML v2 view code.
Phase I: Task analysis
The workflow begins with task parsing. The system provides the natural-language modeling intent to the Task Structure Generation Agent, which outputs a task-card set. To ensure that subsequent generations are executable and reproducible, each task card must include, at a minimum, (i) a task identifier, (ii) dependency relationships, and (iii) key modeling information for validation, such as the modeling objective, constraints/boundary conditions, parameter slots, and instantiation values, and the expected outputs. This stage outputs task_card_set, which serves as the unified basis for subsequent model code generation.
Phase II: Iterative code generation
In iterative generation, the system initializes the code context prev_code to an empty state and generates code for each task card sequentially according to an order determined by the dependency fields. For each task card, the Code Generation Agent takes the current task card and the contextual code as input to produce candidate_code and then immediately invokes the Syntax Validation Module for checking. The module validates the code using the official SysML v2 validation environment and returns diagnostic results. If validation succeeds, the candidate_code is used to update prev_code and supports subsequent generation. If validation fails, the Code Repair Agent is triggered and performs minimal, targeted edits guided by the returned diagnostics, after which the repaired code is resubmitted for revalidation. This repair revalidation loop is bounded by the maximum repair budget Kmax. If validation succeeds within the budget, the passing version updates prev_code; otherwise, after Kmax attempts, the system logs the failure and continues with subsequent task card generation using the last repaired version as prev_code to avoid blocking the workflow while maintaining contextual continuity.
Phase III: Semantic validation
After the code has been generated for all task cards, the workflow proceeds to semantic validation. The Semantic Validation Agent assesses consistency between the final code and the modeling intent using key fields in task_card_set as references and outputs the semantic validation results. If validation succeeds, prev_code is accepted as the final SysML v2 model code. Otherwise, the system generates a Semantic Deviation Report that identifies unmet task card fields and the required revision scope. The Code Repair Agent then revises the code accordingly and outputs the revised model code as the final result.
Model architecture and methodology
Model architecture
The MAS4SysML framework, illustrated in Figure 1, comprises four collaborative agents: the task structure generation agent, code generation agent, code repair agent, and semantic validation agent. The corresponding prompt templates are presented in Figure 2.
The task structure generation agent performs semantic analysis of the input modeling intent and generates executable, structured task cards. It first applies a hierarchical task decomposition mechanism (see hierarchical task decomposition mechanism) to decompose the overall modeling objective into task nodes with well-defined semantic boundaries and then constructs a structured task card for each node. Subsequently, the task cards are ordered according to their modeling dependency fields to ensure that the execution sequence aligns with the eventual code structure, thereby laying the foundation for bottom-up code generation driven by the global modeling objective.
The code generation agent progressively generates SysML v2-compliant model code according to the modeling dependencies. Building on the code artifacts produced by parent tasks, the agent performs the corresponding code generation operations based on the requirements specified in each task card, thereby enabling a stepwise construction process—from local components to the complete model.
The code repair agent corrects errors in the generated code based on the outcomes of the syntax validation module (see syntax validation module) and the semantic validation results. For syntactic repair, it leverages the error type, position, and contextual information returned by the syntax validator to synthesize targeted repair strategies and generate corrected code. For semantic repair, it adjusts structural and logical relations according to the semantic-validation results, ensuring semantic consistency and structural completeness in the final model.
The semantic validation agent assesses the semantic consistency between the fully generated code and the task cards using a dedicated semantic validation mechanism (see semantic validation mechanism). Through quantitative assessment, it ensures that the generated code accurately reflects the original modeling intent, thereby achieving precise alignment between the model code and the specified modeling requirements.
Hierarchical task decomposition mechanism
As a formal modeling language for complex systems, SysML v2 features tightly coupled syntax, deeply nested hierarchical structures, and cross-level semantic constraints. For example, a system structure block may contain multiple subparts, attributes, and ports while simultaneously expressing performance or behavioral requirements through cross-layer constraints. These structures and constraints create top-down structural dependencies and bottom-up semantic feedback relationships. With a flat, one-shot generation approach, accurately mapping such hierarchical dependencies becomes challenging, often resulting in missing relations, semantic inconsistencies, or the loss of constraint information.
To address this challenge, we develop a task-tree-based modeling intent parsing method that hierarchically decomposes natural-language modeling requirements. As illustrated in Figure 3, complex modeling goals are decomposed into structured and traceable task nodes, enabling the system to interpret modeling semantics in a top-down manner and identify dependency relationships. Specifically, when the task structure generation agent receives the user input, it first leverages the semantic parsing capabilities of LLMs to identify core modeling objectives, key entities, and their dependencies. It then recursively decomposes the top-level goal into semantically independent subtasks and further refines them into atomic tasks that can be directly mapped to SysML v2 modeling operations, ultimately forming a complete task structure tree. After the task tree is constructed, the agent generates a structured task card for each task node based on a predefined template. The format of the task card is defined as follows:
TC = {id,O,N,K,P,V,C,D} (1)
Where id as the unique identifier of the task node, O as the task objective, N as the natural-language description of the task, K denotes the core SysML v2 semantic elements that may be involved in the task, mainly including requirement def/requirement, part def/part, port def/port, item def, attribute def/attribute, and state/transition. Relationships among these elements are primarily expressed through connect (structural connections), input/output items on ports (information/material flows), and trigger/guard conditions of state machine transitions (e.g., commands, health status, and threshold constraints), C as the semantic rules or boundary conditions, P as the parameterizable slots within the task such as attribute names, data types or composite types, V as the instantiated values for each slot and D as the modeling dependencies between tasks where depend_on specifies required outputs from other tasks before generating the current task code, provides denotes outputs produced after the task is completed and consumes represents external inputs required by the task.
Syntax validation module
A syntax validation module is constructed based on the SysML v2 Pilot Implementation. By invoking its parser and validator interfaces, the module parses and verifies the syntactic correctness of the generated SysML v2 model code. The module's validation criteria are primarily derived from the SysML v2 language specification, as well as the grammar rules, scope-resolution rules, and related constraint-checking mechanisms implemented in the Pilot tool. Specifically, the validation examines whether element declarations are well-formed, whether block structures are complete, whether type annotations are valid, whether names and references can be successfully resolved, and whether modeling constructs such as ports, connections, states, and transitions comply with the language's requirements.
After the code generation agent produces the code fragment for the current task, the output is forwarded to the syntax validation module, where the validation script analyzes the code and returns the results in the form of structured diagnostic information. The validation results are reported as follows:
e1 = (typei,posi,msgi) (2)
Where ei denotes the list of detected issues for the current modeling task, each entry containing the error type typei, error location posi, and diagnostic message msgi .
For example, if the generated code contains a syntax error such as "an attribute is not typed by an attribute definition," the validation module returns the following diagnostic message:
'type' : 'error'
'message' : 'ERROR: An attribute must be typed by attribute definition.' (3)
'position' : 'line 7 column: 3'
When the validation result ei ≠ 0, the collected error information ei is forwarded to the code repair agent for further correction. Therefore, the code repair process is not an unconstrained modification procedure, but a targeted revision guided by the explicit diagnostic information returned by the parser and validator.
Semantic validation mechanism
The semantic validation mechanism uses key task card fields that have explicit and traceable correspondences to the model code as semantic anchors. It assesses semantic consistency at the model level, thereby providing explicit, actionable criteria for subsequent model repair. Specifically, for each task card TCi, the following fields are used as key semantic references: (i) the modeling objective Oi, (ii) semantic constraints and boundary conditions Ci, (iii) instantiated parameter-slot values Vi, and (iv) expected outputs after task completion Di['provide']. These fields impose complementary semantic constraints on the generated model from multiple perspectives: realization of modeling intent, satisfaction of constraints, consistency of parameter instantiation, and completeness of model outputs—enabling a principled decision on whether the model code satisfies the modeling requirements without requiring extra assumptions.
Based on these key fields, we define a multi-field semantic consistency decision function:
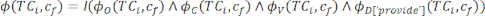 (4)
where I(·) denotes an indicator function that equals 1 if all sub-decision functions inside the parentheses hold, and 0 otherwise. This binary decision explicitly distinguishes between the states of satisfying the modeling requirements and requiring further repair, providing a deterministic trigger condition for the subsequent semantic repair process. The overall decision is jointly determined by the following four sub-decision functions:
(1) Modeling objective consistency:
Φ0 (TCi,cf) = I(consist(cf,0i)) (5)
where Consist(cf,0i) indicates whether the model code cf is semantically consistent with the modeling objective 0i specified in the task card.
(2) Semantic constraint satisfaction:
Φc (TCi,cf) = I(Satisfy(cf,Ci)) (6)
where Satisfy(cf,Ci) indicates whether the model code cf satisfies the semantic constraints and boundary conditions Ci specified in the task card.
(3) Parameter consistency:
Φc (TCi,cf) = I(Instant(cf,Vi)) (7)
where Instant(cf,Vi) indicates whether the instantiated parameter values Vi in the task card are reflected consistently in the model code.
(4) Output consistency:
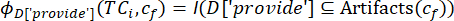 (8)
where Artifacts(cj) indicates whether the outputs expected by the task card are present in the final model code, serving as a measure of the completeness of the generated result.
These consistency judgments are implemented by the Semantic Validation Agent by leveraging the semantic understanding capability of the LLM; the agent's internal reasoning process does not alter the formal definition or usage of the consistency function.
Through this multi-field semantic consistency checking, the generated model can be validated field by field to ensure that each modeling objective, constraint condition, parameter configuration, and expected output is adequately satisfied. This process not only provides an explicit trigger for subsequent semantic repair but also supplies traceable semantic evidence throughout the generation pipeline, thereby improving the reliability and consistency of the generated model.
Experimental data and evaluation
Experimental data
SysML v2 model code is not ordinary software code; its generated artifacts exhibit distinctive characteristics of formal modeling. Different views typically involve distinct categories of core modeling elements, such as requirements, parts, ports, attributes, states, and transitions, which differ substantially in their declaration styles, organizational forms, and compositional structures. In addition, the model code must satisfy multiple constraints, including type referencing, hierarchical nesting, connection constraints, and semantic reuse among elements.
To comprehensively evaluate the performance of the proposed method under varying modeling complexities, a code dataset covering five representative model view types—requirements, use cases, structure, parametrics, and state machines—is constructed. These model views correspond to requirement specification, functional interaction, structural composition, parametric constraint representation, and behavioral logic description in system modeling, respectively. Evaluating the framework separately on different model view types enables a finer-grained analysis of its applicability under diverse code structure characteristics and modeling constraint conditions.
Each model view type contains 15 manually created model instances, resulting in a dataset of N = 75 SysML v2 models. The dataset spans multiple engineering domains, including aerospace, automotive, medical, and smart home systems, and all models successfully passed the official SysML v2 validation environment, ensuring strict syntactic compliance.
Subsequently, we generated a corresponding natural-language modeling intent description for each model. To improve construction efficiency, we used the prompt template shown in Supplementary File 2 and employed GPT-4o to produce initial descriptions. GPT-4o was selected for its strong semantic understanding and information extraction capabilities, enabling it to accurately capture core model elements without hallucination and generate human-like modeling intent descriptions9. To ensure accuracy and eliminate ambiguity, all generated descriptions were manually reviewed and refined by researchers with a systems engineering background. Representative examples for different model types are shown in Table 1.
Evaluation metrics
We employ the following three key metrics to evaluate the quality of the generated SysML v2 model code:
Average syntactic error rate (SER)
This metric quantifies the proportion of syntactic errors detected when the generated model code is validated against the official SysML v2 syntax rules. It is computed as:
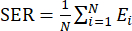 (9)
where Ei denotes the number of syntactic errors identified in the i-th generated model. This metric reflects the extent to which the generated model code adheres to the formal SysML v2 syntax specification.
Semantic consistency score (SCS)
This metric evaluates how accurately and comprehensively the generated model code captures the semantic intent expressed in the natural-language modeling specifications. Specifically, we extract semantic units from the modeling intent—such as system entities, participating components, core functions or behavioral scenarios, and key conditions or constraints—and compare them with the semantic units present in the generated model code. The semantic consistency is computed as:
 (10)
where U represents the set of semantic units extracted from the modeling intent, and  represents the set of semantic units identified in the generated code.
 indicates the number of units correctly captured by the generated model code. A higher SCS value indicates stronger semantic coverage and alignment.
Human quality evaluation
Traditional automated metrics such as BLEU and CodeBLEU primarily assess surface level similarity or code executability, but they do not capture whether the model truly understands or correctly expresses the intended modeling semantics. These metrics are limited in evaluating semantic consistency, completeness of key elements, and alignment with the modeling intent10. In contrast, human evaluation can more accurately identify issues such as missing semantic elements, logical inconsistencies, structural redundancy, or unsupported hallucinations, thereby providing a more reliable assessment11. Motivated by these limitations, we design a human evaluation framework for generated SysML v2 models consisting of three criteria: (1) Correctness: the generated model must accurately reflect the modeling intent, maintain structural and logical consistency with the task objectives, and contain no semantic ambiguity, missing elements, or erroneous extensions. (2) Readability: the model code should be clear and easy to understand, with consistent naming, coherent structure, and a well-organized hierarchy that supports inspection and subsequent maintenance. (3) Integrity: the model should exhibit complete structural logic, consistent cross-element references, and no undefined types or broken dependency chains, ensuring its usability for downstream analysis and integration. We invited researchers with SysML modeling experience to score each generated model on a three-point scale, where 1 denotes the lowest quality and 3 the highest. During evaluation, assessors were allowed to compare the generated model code with the ground-truth model to ensure a more accurate and comprehensive assessment.
Base line
We selected multiple evaluation baselines for comparative testing against the proposed method, including:
CodeCoT12: Combines chain-of-thought reasoning with a self-check mechanism, enabling the model to explicitly reason during generation and self-correct syntactic errors, thereby improving code quality and semantic consistency.
Self-planning13: Introduces a two-stage code generation pipeline in which the model first plans the solution steps and then generates code according to the plan, effectively enhancing logical coherence and interpretability for complex tasks.
Self-edit14: Adopts an iterative generate and edit paradigm that executes the generated code and automatically corrects errors based on runtime feedback, continuously refining the output.
CodeChain15: Uses modular generation and iterative revision by decomposing complex tasks into independent functional modules and improving structural soundness and overall quality through multiple optimization rounds.
Self-debugging16: Endows the model with autonomous debugging and explanation capabilities. Through a closed-loop process of generation, execution, and debugging, it substantially improves correctness on complex programming tasks without human intervention.
MapCoder17: Constructs a multi-stage collaborative framework consisting of four agents—retrieval, planning, coding, and debugging—closely simulating the human programming workflow and enabling closed-loop generation from task understanding to result verification.
Self-Collaboration18: Organizes the system as a virtual programming team with roles such as analyst, programmer, and tester, improving overall performance on complex code generation through role-based collaboration and iterative feedback.
Experimental setup
To ensure fairness and comparability across experiments, we first evaluated several mainstream LLMs using a direct code generation approach to establish baseline performance. Based on these initial results, the best-performing LLM was selected as the unified backbone model for all subsequent experiments. We subsequently compared the proposed MAS4SysML framework with multiple representative code generation methods. All LLM interactions were conducted using a fixed temperature setting (T = 0.2) to minimize randomness during generation. For each modeling task, the maximum number of repair iterations in MAS4SysML was set to Kmax = 3. All baseline methods were executed under the same experimental configuration as MAS4SysML to ensure result consistency and experimental fairness. The Python script of the MAS4SysML method is provided as Supplementary File 3.
Results
Baseline model evaluation
We first selected several mainstream LLMs and conducted preliminary performance tests using direct model-to-code generation, including CodeX(175B)19, CodeGen-Mono(16.1B)20, PaLM Coder(62B)21, Alphacode(1.1B)22, Incoder(6.7B)23, and code-davinci-002(175B)24. As shown in Table 2, code-davinci-002(175B)24 exhibited the best performance on both the SER and SCS metrics. Therefore, code-davinci-002(175B) was selected as the base LLM for evaluating various code-generation strategies in this study. The results of these strategy evaluations are summarized in the lower half of Table 2.
Among single-agent methods, CodeCoT leverages chain-of-thought reasoning and self-checking to correct certain local errors, but its improvements remain largely constrained to local adjustments: its SER remains as high as 4.98, and its SCS reaches only 0.72. In contrast, Self-Planning, Self-Edit, and CodeChain introduce task planning and iterative generation, which improve structural coherence, reducing SER to 3.82, 3.61, and 3.23 and increasing SCS to 0.77, 0.75, and 0.78, respectively. Notably, Self-Debugging benefits from the self-explanation capability of LLMs and achieves superior semantic performance with an SCS of 0.83, but its syntactic accuracy remains inadequate, indicating that self-debugging alone is insufficient to ensure both syntactic correctness and semantic consistency. For multi-agent collaborative methods, MapCoder enhances contextual sharing through a multi stage process comprising retrieval, planning, coding, and debugging, yielding SER and SCS scores of 3.42 and 0.88. Self-Collaboration simulates the workflow of a virtual team, forming a feedback loop across analysis, generation, and validation, and further improving semantic alignment, with SER and SCS of 3.38 and 0.87.
In contrast, the proposed MAS4SysML achieves the best performance across both metrics, reducing SER to 2.63 and increasing SCS to 0.91. These substantial performance gains stem from the integration of explicit task-tree decomposition, progressive layer-by-layer code generation, and a unified syntax–semantic dual-validation mechanism, which collectively ensure optimal structural consistency and semantic alignment in the generated models.
Performance analysis of different LLMs
To systematically evaluate LLM performance in SysML v2 code generation, we selected several mainstream conversational models for baseline testing, including Fastchat(3B)25, ChatGLM(6B)26, MPT(7B)27, Vicuna(7B/13B)28, HuggingChat(30B)29, Dromedary(65B)30, and the high-performing GPT-4o9. We evaluated each model under two settings: (1) direct generation of SysML v2 model code and (2) serving as the base model within MAS4SysML, to distinguish the inherent capabilities of each LLM from the gains introduced by our collaborative framework.
As shown in Table 3, overall code generation quality improves substantially as model size increases. Models below 13B typically yield SER values around 30 and SCS values below 0.6, indicating limited capability in handling SysML v2 syntax and semantic alignment, and even with MAS4SysML, the improvements remain marginal. When model size increases to 30B and 65B, SER decreases to 20.21 and 12.96, while SCS increases to 0.78 and 0.82, suggesting that these models achieve more stable syntactic correctness and semantic consistency, and that MAS4SysML provides greater benefits at this scale. Among all tested models, GPT-4o achieves the best performance, with SER reduced to 3.78 and SCS reaching 0.85, demonstrating its strong capability for generating syntactically compliant and semantically aligned SysML v2 models. Overall, model size emerges as the primary factor influencing SysML v2 code generation quality. When model size is sufficiently large, MAS4SysML can significantly enhance syntactic correctness and semantic alignment; however, when model size is small, the potential gains offered by MAS4SysML are substantially constrained.
We additionally evaluated several LLMs with strong code-generation capabilities, including text-davinci-002(175B)31, code-davinci-002(175B)24, code-cushman-001(13B)32, and Code LLaMA (7B/13B/34B)33. Among them, code-davinci-00231, code-cushman-00132, and the Code LLaMA series33 were trained on large-scale programming corpora, providing stronger syntactic control and structural code modeling capabilities. The results are presented in Table 4. The results indicate that for smaller models, MAS4SysML yields only limited improvements due to the inherent capability ceilings of the underlying LLMs. When model size increases to 34B, the benefits of the multi-agent framework become more apparent, with SER decreasing to 9.83 and SCS improving to 0.75. At the same 175B scale, code-davinci-002(175B)24 significantly outperforms the general-purpose model text-davinci-002(175B)31, demonstrating that code oriented training substantially enhances code generation capabilities. However, the absence of a large and high-quality SysML v2 training corpus limits domain-specific fine-tuning, leaving current SysML generation performance heavily dependent on the LLMs' pretraining capability.
Overall, LLM performance on SysML v2 code generation improves substantially with larger model sizes and more specialized training paradigms. When model size exceeds 30B parameters, both syntactic correctness and semantic consistency exhibit notable gains, and the collaborative benefits of MAS4SysML become increasingly pronounced. Furthermore, specialized code training plays a crucial role in improving generation quality. Future work leveraging large-scale SysML v2 corpora for domain-adapted training may further enhance the reliability and quality of SysML model generation.
Cost analysis
In general, multi-agent frameworks incur higher runtime overhead than single-agent setups. Accordingly, for cost analysis, we compare MAS4SysML with one single-agent code-generation baseline (Self-Debugging) and two multi-agent baselines (MapCoder and Self-Collaboration). Table 5 summarizes the evaluation results for these frameworks. We monitored runtime overhead using the Python library psutil34, recording execution time, CPU utilization, memory usage, disk I/O, and network I/O to assess the cost efficiency of MAS4SysML. All experiments were performed on a dedicated server to minimize interference from other services or processes.
The results indicate that, although MAS4SysML requires more runtime than the single-agent baseline, it achieves the best efficiency among the multi-agent methods. Specifically, MAS4SysML completes execution in 174.6 s, compared with 194.7 s for MapCoder and 231.5 s for Self-Collaboration. Moreover, MAS4SysML and MapCoder exhibit similarly low CPU utilization (1.2%), both lower than Self-Collaboration (2.3%), suggesting that MAS4SysML maintains low CPU demand while achieving competitive throughput.
In terms of memory consumption, MAS4SysML uses 0.17 GB, whereas Self-Collaboration reaches 0.37 GB, indicating higher memory pressure for Self-Collaboration. For disk write I/O, Self-Collaboration produces markedly higher write volume (112.5 MB) than the other frameworks, while MAS4SysML writes only 14.7 MB, reflecting more conservative storage activity.
Network overhead shows a similar pattern. Self-Collaboration yields the largest transmission volume (34.3 MB), likely due to repeated inter-agent exchanges, whereas MAS4SysML transfers 12.9 MB, which is lower than the other multi-agent baselines. This result suggests that MAS4SysML's collaboration protocol is comparatively communication-efficient.
Overall, MAS4SysML exhibits lower overhead than the other multi-agent code-generation frameworks considered in this study. We attribute this advantage primarily to its task-structure decomposition strategy: by organizing complex modeling requests into hierarchically structured subtasks, MAS4SysML can generate code incrementally under explicit constraints, reducing unnecessary regeneration and redundant reasoning, and thereby lowering overall computational and resource costs.
Ablation evaluation
In this section, we systematically analyze the contribution of each key agent in the MAS4SysML framework through a series of ablation studies. To this end, we compare the full MAS4SysML configuration with the following five variants: (1) w/o Task Planning: this variant removes the task-structure generation agent. The model directly generates code from the natural-language modeling intent and is followed only by syntax checking, error repair, and semantic validation. (2) w/o Syntax Validation: this variant omits the syntax-validation module and performs semantic validation directly after code generation. (3) w/o Code Repair: this variant excludes the code-repair agent. Errors detected by the syntax validator are not automatically corrected but are instead passed back to the code-generation agent, which attempts self-correction in the next iteration. (4) w/o Semantic Validation: this variant performs syntax-level verification only, without semantic-consistency checking, and is used to assess structural completeness and intent alignment when semantic constraints are absent. (5) Direct: this baseline includes no planning, validation, or repair. The model generates the full code in a single pass and serves as a reference for quantifying the performance improvements brought by the complete MAS4SysML framework.
As shown in Figure 4, all key components of the MAS4SysML framework contribute substantially to overall performance. When the task structure generation agent is removed, SER rises to 3.84 and SCS falls to 0.82, indicating that without the task tree, the model's ability to interpret hierarchical structures and cross-element dependencies is substantially weakened, increasing its susceptibility to structural and syntactic errors in complex models. The syntax validation module exerts the most pronounced impact: removing it causes SER to surge to 6.78, with errors primarily involving missing structural elements, omitted keywords, and syntactic conflicts. Eliminating the code repair agent also raises SER to 5.12, demonstrating that deterministic verification and repair are essential for preventing error accumulation and maintaining generation stability. In contrast, removing the semantic validation agent has a smaller effect on SER, but SCS declines markedly to 0.75. Further inspection shows that although the generated code passes syntactic validation under this condition, it frequently exhibits semantic deviations such as missing constraints, incomplete role relationships, or unwarranted extensions. This highlights the critical role of semantic validation in maintaining logical coherence and ensuring faithful alignment with the modeling intent.
Overall, the components operate in a complementary manner: the task structure generation agent provides hierarchical task organization and semantic dependency parsing; the syntax validation module and code repair agent ensure structural completeness and compilability; and the semantic validation agent enforces global semantic alignment and consistency. Together, these components enable MAS4SysML to achieve stable, high-quality automated SysML v2 code generation for complex modeling tasks.
Impact of maximum repair iterations
To evaluate the impact of the maximum number of repair iterations Kmax on final code quality, we conducted a controlled comparison by varying its value. The results, shown in Figure 5, reveal a clear downward trend in SER as Kmax increases. The most substantial improvement occurs when Kmax increases from 0 to 1: SER drops from 6.31 to 3.62, indicating that even a single repair iteration can correct a large proportion of syntax errors. Meanwhile, SCS also increases markedly, suggesting that the repair mechanism enhances not only structural correctness but also semantic alignment between the generated code and the modeling intent. As Kmax continues to increase, performance improvements persist but gradually diminish. With Kmax=2, SER decreases by an additional 0.84 compared with the previous setting, although the SCS gain becomes modest. At Kmax=3, performance stabilizes: SER decreases by only 0.16, and SCS drops slightly by 0.02, while the computational cost for generation and validation increases noticeably. Overall, the results indicate that multiple repair iterations can effectively improve code-generation quality, but Kmax=2 provides the best balance between performance gains and computational cost. Therefore, setting the maximum number of repair iterations to 2 represents the optimal choice under the trade-off between quality and efficiency.
We further examined the small number of cases that still failed to fully satisfy the validation criteria under Kmax=3. These cases were primarily associated with (i) incomplete task-card specifications resulting from implicit or underspecified modeling intent, (ii) structurally complex initial generations involving nested declarations, references, or connection logic, and (iii) syntactically valid yet semantically incomplete outputs that could not be fully corrected through explicit diagnostic feedback alone. This finding suggests that increasing the number of repair iterations is effective for resolving explicit syntax-related issues; however, its effectiveness diminishes when residual errors stem from upstream intent interpretation or deeper semantic incompleteness.
Human evaluation
We adopt the human assessment metrics described earlier to subjectively score the generated SysML v2 model code. Twenty modeling tasks were randomly selected from the dataset, and five code versions were prepared for each task: True, Self-Debugging16, MapCoder17, Self-Collaboration18, and MAS4SysML. During evaluation, each developer reviewed the five code versions for the same task simultaneously and assigned comparative scores. A total of ten developers with 2–5 years of SysML modeling experience participated in the study. The evaluation was conducted using anonymous questionnaires, and the presentation order of the five methods was randomized to mitigate potential bias.
The human evaluation results are shown in Figure 6. In terms of correctness, MAS4SysML exhibits a score distribution closest to the True baseline, with most scores concentrated in the 2.5–3 range, indicating that its generated code is highly reliable in terms of structural consistency, semantic accuracy, and constraint logic. In contrast, Self-Debugging and MapCoder show more dispersed distributions with a greater number of scores in the 1–2 range, reflecting issues such as logical omissions and inconsistent constraints. Regarding readability, MAS4SysML again performs best, producing code with more standardized naming, clearer hierarchical organization, and more coherent logical structure. Self-Collaboration benefits from its multi-role cooperation mechanism, yielding improved structural clarity and ranking second in readability. For integrity, MAS4SysML leverages hierarchical task decomposition and semantic validation to substantially reduce missing fields, incomplete constraints, and undefined elements, with scores concentrated between 2 and 3. Although Self-Debugging can address some local errors, it lacks sufficient coverage of modeling intent and cross element dependencies, resulting in the lowest integrity scores. Self-Collaboration and MapCoder, despite their collaborative advantages, frequently produce incomplete attributes, interfaces, or binding relations, leading to scores predominantly in the 1–2 range.
Overall, the human evaluation demonstrates that MAS4SysML achieves the highest performance across correctness, readability, and integrity, with scores approaching those of the True baseline. This confirms that MAS4SysML can achieve modeling quality comparable to human created SysML V2 models in practical modeling tasks.
Case study
We conduct qualitative evaluations through representative case studies to assess the effectiveness of MAS4SysML across diverse modeling scenarios. The first case considers structural-model generation for a smart home system and demonstrates how multiple agents collaborate throughout the modeling workflow. The second case addresses requirements, structural, and behavioral modeling for a launch-vehicle propulsion subsystem, encompassing requirements modeling, structural modeling, and state-machine modeling, to evaluate the method's ability to capture diverse modeling objectives in complex equipment systems.
In the smart home structural modeling task, the agents within MAS4SysML sequentially execute task parsing, code generation, syntax validation, code repair, and semantic-consistency verification (as illustrated in Figure 7). (1) The task structure generation agent constructs a task tree based on requirement semantics, decomposing the overall modeling objective into structured task cards that define explicit modeling goals and semantic constraints. (2) The code generation agent produces model code in a layer-by-layer manner according to the task cards, progressively extending previously generated content to maintain structural continuity and contextual coherence. (3) The syntax validation module uses the official SysML v2 validation environment to perform formal checks on the generated code. During one of these checks, it detected a syntax error on line 6, indicating that "HomeState" was undefined. (4) The code repair agent then modifies the code precisely based on the validation feedback, correcting the erroneous reference from "HomeState" to the correct type "HomeStatus." (5) Finally, the semantic validation agent compares the generated code with the task cards and confirms that the model satisfies both structural and semantic requirements, thereby completing the end-to-end generation process.
In the second case study, MAS4SysML is applied to the modeling task of a launch-vehicle propulsion subsystem. The evaluation considers three core task types: requirements modeling, structural modeling, and behavioral modeling. Together, these subcases capture key design information from the perspectives of requirements, architecture, and control logic, and are used to assess the proposed framework's ability to automate modeling across heterogeneous task types.
Requirements modeling. First, we construct a requirements view of the propulsion subsystem to establish a requirements baseline for subsequent structural and behavioral modeling. In this task, MAS4SysML is applied to specify the subsystem's thrust-provision capability during main-stage operation, critical safety constraints, and control responsiveness. The task specification is as follows: Construct the requirements view of the propulsion subsystem and define four key requirements: (i) during main-stage operation, the propulsion subsystem shall provide at least the target thrust and support thrust build-up and stable operation; (ii) the combustion-chamber pressure shall remain within the specified range, and protection or shutdown shall be triggered if it exceeds this range; (iii) the propulsion subsystem shall implement interlocks for ignition, propellant supply, and shutdown, and support abort under abnormal conditions; and (iv) the propulsion subsystem shall respond to flight control commands to execute ignition, throttling, and shutdown, supporting closed loop control execution. The generated model code is visualized using Graphviz, as shown in Figure 8.
Structural modeling. Second, the structural modeling task identifies key internal components and their interaction relationships. MAS4SysML is used to model the propellant tank, rocket engine, and engine controller, together with the associated material transfer and information-interaction links. The task specification is as follows: Construct the structural diagram of the launch-vehicle propulsion subsystem. The subsystem comprises three components: a propellant tank, a rocket engine, and an engine controller. The tank supplies propellant to the engine, and the engine converts propellant into thrust under controller-issued commands. The propulsion subsystem receives external control commands; these commands are first routed to the controller, which generates executable control commands and transmits them to the engine. Meanwhile, the controller outputs engine status to external interfaces as telemetry information. The resulting model is shown in Figure 9.
Behavioral modeling. Finally, we construct a state-machine model for the engine control logic to describe state evolution and safety handling strategies under different commands and health conditions. MAS4SysML is applied to formalize the state sequence, transition guards, and abnormal handling paths. The task specification is as follows: Build a state machine model for the engine control logic of the launch vehicle propulsion subsystem. The engine starts in the Off state, and the external command interface issues three commands: Start, Shutdown, and Abort. Upon receiving Start under nominal health status, the engine transitions through Pre cooling, Ignition, and Thrust ramp up, and then enters Steady state operation. Entry into steady state is permitted only if, during thrust ramp up, the combustion-chamber pressure is detected within the specified lower and upper bounds. If Shutdown is issued during steady state, the engine enters the shutdown process and returns to Off only after thrust drops to zero. At any stage, if an Abort command is received or health status degrades, the engine shall immediately transition to Abort to execute protective actions; when conditions permit, it may return to Off via Shutdown. The resulting model is shown in Figure 10.
Data Availability
All raw data generated and analyzed during this study have been made publicly available. The dataset is deposited on Zenodo with DOI: 10.5281/zenodo.18439316.
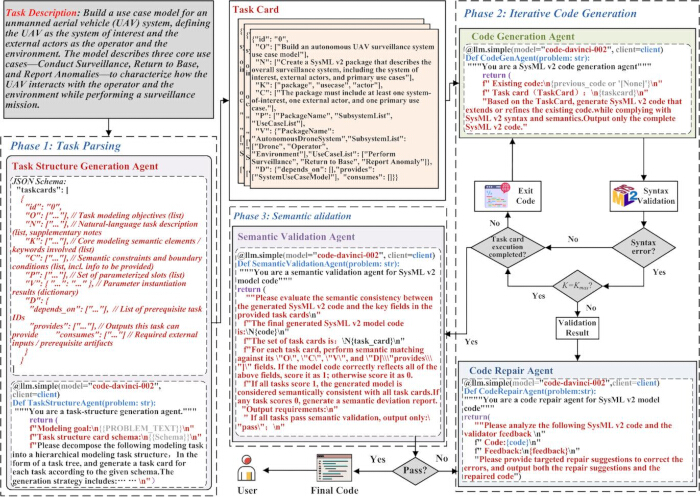
Figure 1: MAS4SysML framework. The framework utilizes multi-agent collaboration to perform task decomposition, code generation, syntax validation, error repair, and semantic consistency checking, enabling the automated transformation from modeling intent to SysML v2 code. Please click here to view a larger version of this figure.
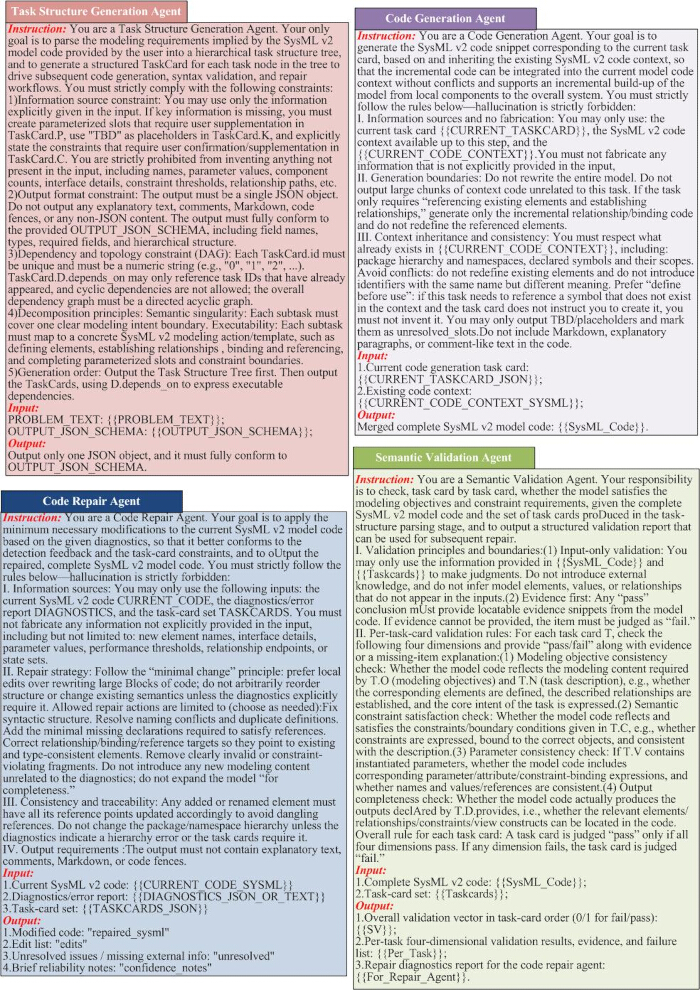
Figure 2: Prompt templates for agents in the MAS4SysML framework. This figure presents the prompt templates used by the four core agent types within the framework, specifying the input structure, generation objectives, and operational rules for each agent. Please click here to view a larger version of this figure.
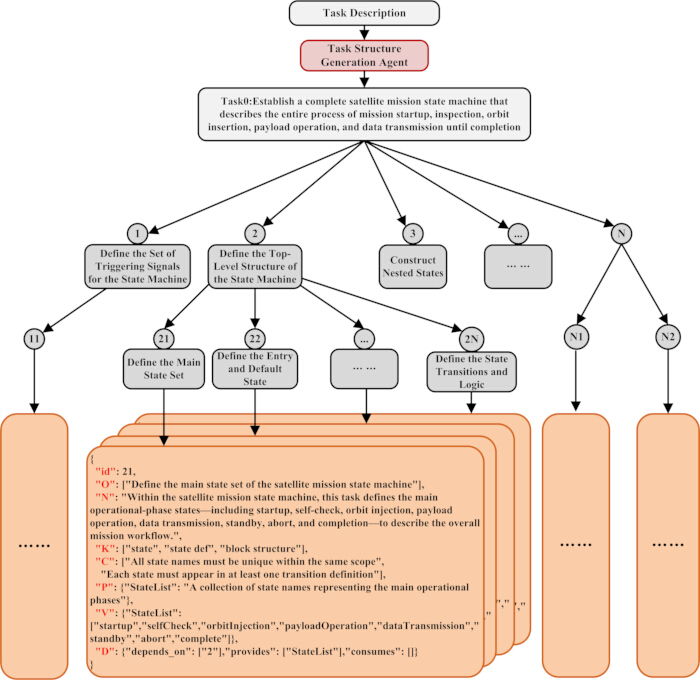
Figure 3: Illustration of the hierarchical task decomposition mechanism. This figure shows how the task structure generation agent iteratively decomposes the overall modeling objective into structured subtasks through a task tree. Each node corresponds to a task card that provides clear semantic constraints and operational guidance for subsequent automatic code generation. Please click here to view a larger version of this figure.
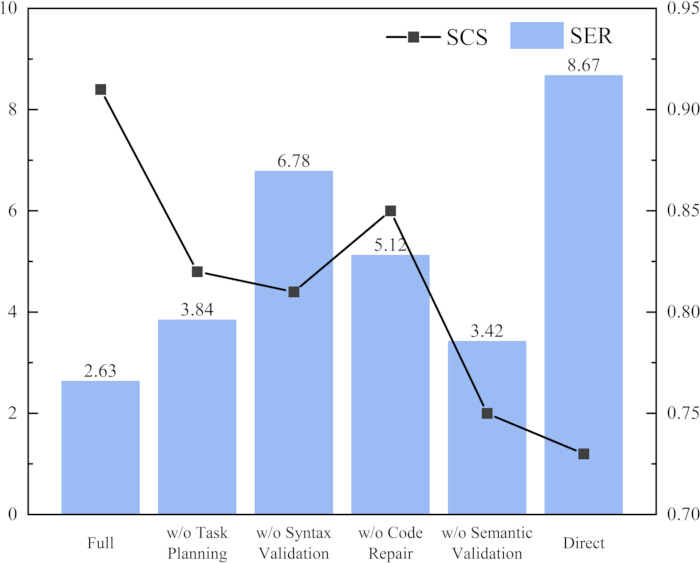
Figure 4: Ablation result. This figure shows how the model's performance changes when different modules are removed, including variations in SER and SCS. Please click here to view a larger version of this figure.
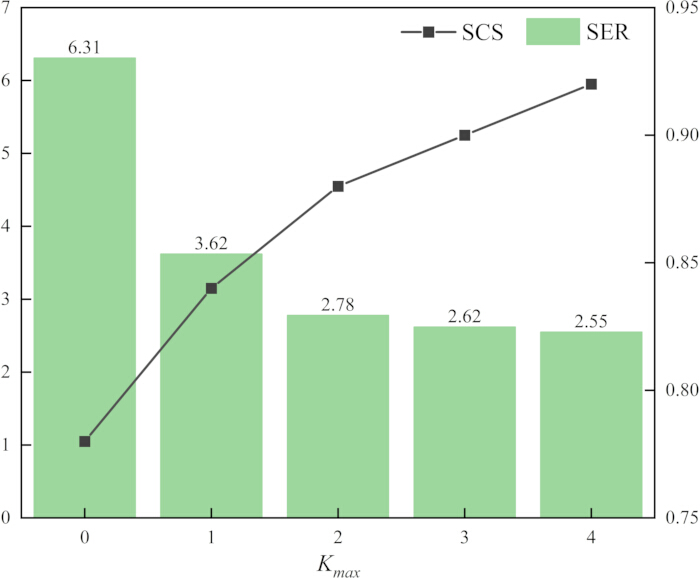
Figure 5: Impact of maximum repair attempts. This figure illustrates the trends in SER and SCS under different maximum repair attempt settings Kmax. Please click here to view a larger version of this figure.
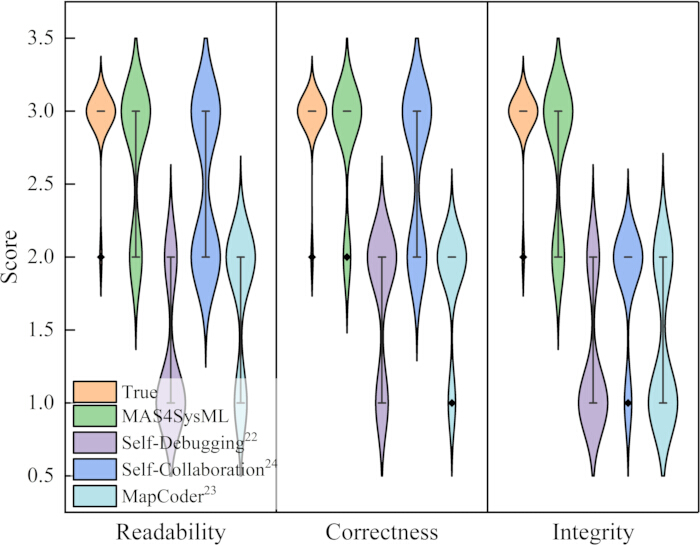
Figure 6: Human evaluation results. This figure presents the score distributions given by human reviewers for different code generation methods across three evaluation criteria: readability, correctness, and integrity. Please click here to view a larger version of this figure.
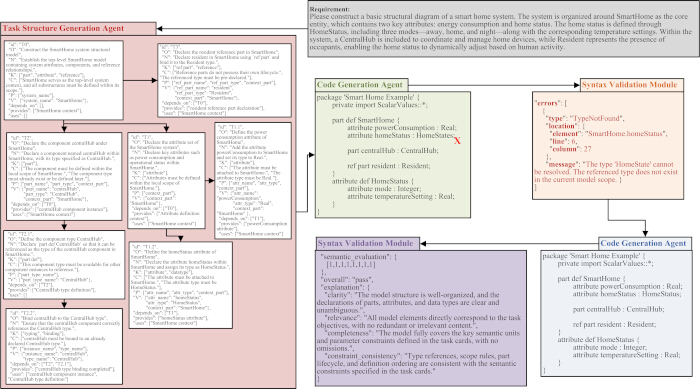
Figure 7: Structural model generation process for a smart home system. This figure illustrates the complete execution process of MAS4SysML in the structural modeling task for a smart home system, including task structure generation, code generation, syntax validation, code repair, and semantic validation. Please click here to view a larger version of this figure.
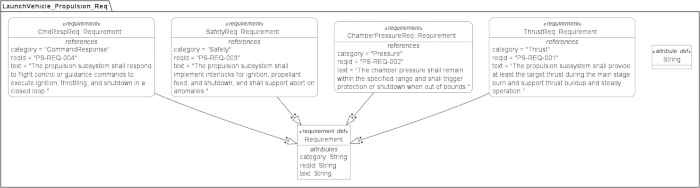
Figure 8: Requirements modeling view of the launch vehicle propulsion subsystem generated by MAS4SysML. This figure presents the propulsion subsystem requirements modeling view automatically generated by MAS4SysML. It includes key requirements such as thrust requirements, combustion-chamber pressure constraints, interlock/abort safety requirements, and command-response requirements, and represents them in a structured manner using a unified Requirement definition. Please click here to view a larger version of this figure.
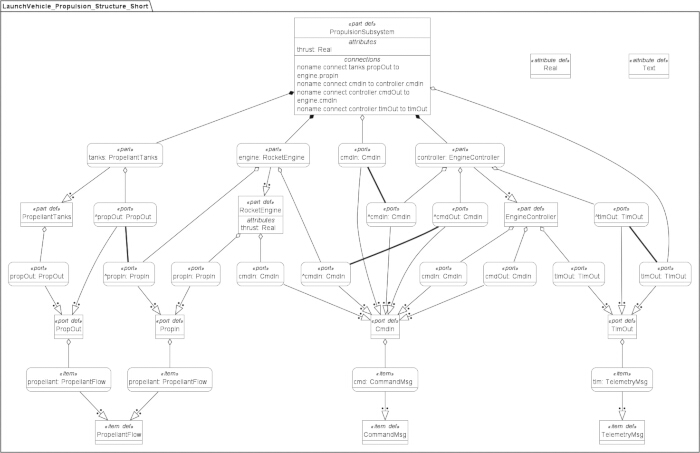
Figure 9: Structural model of the launch vehicle propulsion subsystem generated by MAS4SysML.This figure shows the structural decomposition and interaction relationships of the propulsion subsystem, including three core components:PropellantTanks, RocketEngine, and EngineController. Please click here to view a larger version of this figure.
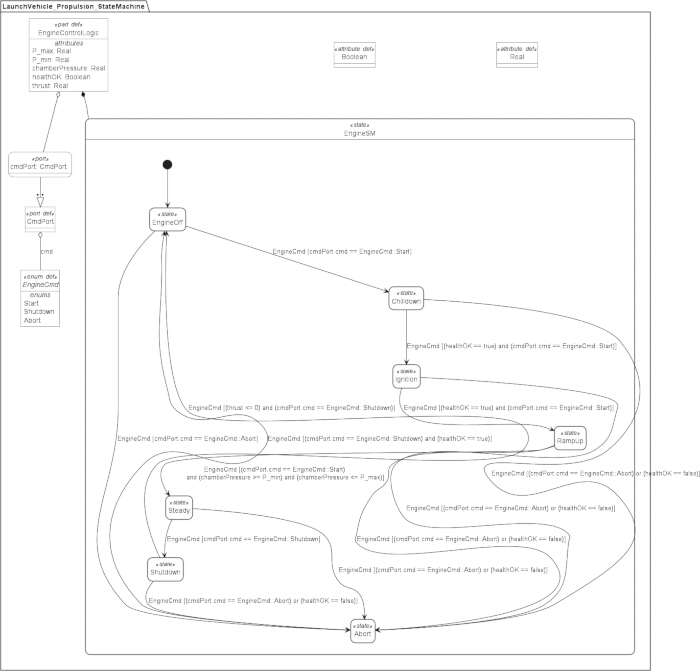
Figure 10: State machine model for engine control logic generated by MAS4SysML.This figure illustrates the state machine model of the engine control logic, consisting of states Off, Chilldown, Ignition, RampUp, Steady, Shutdown, and Abort, together with state transitions triggered by Start/Shutdown/Abort commands and the health status. Entry into the steady-state is constrained by combustion-chamber pressure bounds, and completion of shutdown is constrained by the thrust dropping to zero. Please click here to view a larger version of this figure.
| Model type | Description | |||
| Requirements Model | Construct a requirements diagram for a home security system focusing on intrusion detection and alarm response. The system is intended to identify unauthorized entry in real time and promptly notify the user and security service when an intrusion occurs. In addition, the system must include mechanisms to reduce false alarms caused by pets or environmental disturbances. | |||
| Use Case Model | Construct a use case diagram for a satellite telemetry and telecontrol system. The system subject is an on-orbit satellite, which exchanges status information and control commands with the ground station and the mission control center. The satellite must perform three primary tasks: provide operational status and health parameters to the ground station, receive and execute telecommands from the mission control center, and maintain or adjust its attitude and orbit according to mission requirements. | |||
| Structure Model | Construct a system structure diagram for an unmanned aerial vehicle (UAV). The system is composed of an avionics subsystem, a propulsion subsystem, a mission payload subsystem, a communication subsystem, and a power subsystem. These subsystems are responsible for flight control, thrust generation, mission execution, ground communication, and energy supply, respectively. The model should also define the data link and control interfaces between the UAV and the ground control station. | |||
| Parametric Model | Construct a parametric diagram that describes the endurance performance constraints of a small UAV during mission execution. The model takes the UAV’s battery capacity, baseline power consumption, flight speed, aerodynamic drag coefficient, and payload weight as input parameters, and uses a power consumption model to represent the influence of these factors on actual power usage. Based on this, the endurance time is determined by the proportional relationship between battery capacity and actual power consumption. | |||
| State Machine Model | Construct a state machine diagram representing the launch process of a launch vehicle from pre-launch preparation to orbital insertion. The system subject is the launch vehicle executing the mission, and the mission process is composed of sequential phases including pre-launch checks, propellant fueling, countdown, ignition, liftoff, ascent, stage separation, and orbital insertion. Additionally, a safety mechanism is included that triggers an abort sequence if any anomaly occurs during any stage of the process. | |||
Table 1: Examples of modeling intents for different model types. This table presents modeling intent examples for various model types,including requirements, use case, structural, parametric, and state machine models. These examples were automatically generated by GPT-4o based on manually constructed model code and subsequently validated by human review.
| Approach | SER | ΔSER | SCS | ΔSCS |
| Direct Generation (Baseline) | ||||
| CodeX (175B) | 10.16 | 1.49 | 0.71 | −0.02 |
| PaLM Coder (62B) | 15.34 | 6.67 | 0.62 | −0.11 |
| CodeGen-Mono (16.1B) | 23.63 | 14.96 | 0.61 | −0.12 |
| Incoder (6.7B) | 29.51 | 20.84 | 0.57 | −0.16 |
| AlphaCode (1.1B) | 31 | 22.33 | 0.54 | −0.19 |
| code-davinci-002 (175B) | 8.67 | 0 | 0.73 | 0 |
| Methods Based on code-davinci-002 | ||||
| CodeCoT | 4.98 | −3.69 | 0.72 | −0.01 |
| Self-Planning | 3.82 | −4.85 | 0.77 | 0.04 |
| Self-Edit | 3.61 | −5.06 | 0.75 | 0.02 |
| CodeChain | 3.23 | −5.44 | 0.78 | 0.05 |
| Self-Debugging | 3.65 | −5.02 | 0.83 | 0.1 |
| MapCoder | 3.42 | −5.25 | 0.88 | 0.15 |
| Self-Collaboration | 3.38 | −5.29 | 0.87 | 0.14 |
| MAS4SysML | 2.63 | −6.04 | 0.91 | 0.18 |
Table 2: Baseline model evaluation. This table presents the performance comparison of various code generation models on SysML v2 automatic modeling tasks. The evaluation includes SER and SCS metrics, as well as their changes relative to the baseline model (ΔSER and ΔSCS), providing a comprehensive assessment of each model's syntactic correctness and semantic alignment.
| Model | SER | SCS | SER (Direct) | SCS (Direct) |
| Fastchat (3B) | 32.83 | 0.54 | 34.42 | 0.53 |
| ChatGLM (6B) | 32.51 | 0.51 | 32.24 | 0.51 |
| MPT (7B) | 31.75 | 0.57 | 33.98 | 0.56 |
| Vicuna (7B) | 28.23 | 0.53 | 30.76 | 0.54 |
| Vicuna (13B) | 23.93 | 0.66 | 28.32 | 0.57 |
| HuggingChat (30B) | 20.21 | 0.78 | 25.77 | 0.62 |
| Dromedary (65B) | 12.96 | 0.82 | 16.85 | 0.63 |
| GPT-4o | 3.78 | 0.85 | 7.23 | 0.81 |
Table 3: Performance analysis of different mainstream conversational LLMs. This table compares the performance of several mainstream conversational LLMs on SysML v2 automatic modeling tasks.
| Model | SER | SCS | SER (Direct) | SCS (Direct) |
| code-davinci-002(175B) | 2.63 | 0.91 | 8.67 | 0.71 |
| text-davinci-002(175B) | 3.12 | 0.9 | 9.21 | 0.74 |
| code-cushman-001(13B) | 15.98 | 0.71 | 18.64 | 0.6 |
| Code LLaMA(34B) | 9.83 | 0.75 | 13.21 | 0.67 |
| Code LLaMA(13B) | 18.64 | 0.67 | 19.86 | 0.61 |
| Code LLaMA(7B) | 25.41 | 0.64 | 27.93 | 0.58 |
Table 4: Performance analysis of code generation LLMs. This table compares the performance of several representative code generation LLMs on SysML v2 automatic modeling tasks.
| Method | Run Time (s) | CPU Usage (%) | Memory Usage (GB) | Disk Write (MB) | Net Traffic (MB) |
| Self-Debugging | 168.4 | 0.8 | 0.16 | 21.9 | 7.4 |
| MapCoder | 194.7 | 1.2 | 0.19 | 46.3 | 28.1 |
| Self-Collaboration | 231.5 | 2.3 | 0.37 | 112.5 | 34.3 |
| MAS4SysML | 174.6 | 1.2 | 0.17 | 14.7 | 12.9 |
Table 5: Runtime overhead comparison of different methods in the prototype system experiments. This table summarizes the resource consumption of each method across multiple overhead metrics.
Supplementary File 1: Automatic model code generation process based on the MAS4SysML. This table presents the overall automatic code generation workflow of MAS4SysML.Please click here to download this file.
Supplementary File 2: Prompt template for modeling intent generation. This table presents the prompt template used to generate natural-language modeling intent from SysML v2 model code. The template specifies rules for describing modeling goals, identifying core system elements, and summarizing functional or behavioral logic, while explicitly prohibiting line-by-line code enumeration or the direct use of SysML specific terminology, ensuring the generated intent descriptions are concise and semantically accurate.Please click here to download this file.
Supplementary File 3: Python script of the MAS4SysML method. This file provides the full implementation details of the MAS4SysML method, covering the core modules, including task structure generation, code generation, syntax validation, code repair, and semantic verification, and the key functions that support the complete workflow of automated SysML v2 model code generation.Please click here to download this file.
Discussion
We propose MAS4SysML, a multi-agent collaborative framework for semi-automated SysML v2 model code generation. The framework consists of four functionally complementary agents. During generation, it (i) hierarchically decomposes natural-language modeling requirements using a task-tree–based structure and formalizes them into structured task cards, and (ii) generates SysML v2 model code in a bottom-up manner guided by the constraints and dependency relations specified in these cards. Throughout generation, a syntax validation module built on the official SysML v2 validation environment performs syntax diagnostics and returns repair-oriented feedback. After code generation, the framework further checks semantic consistency against key task-card fields, improving both the executability of the produced code and its alignment with the intended requirements.
MAS4SysML offers a practical pathway for transforming natural-language modeling intent into SysML v2 model code. It helps reduce the cost and learning burden of manual modeling in complex equipment development and improves iteration efficiency through a closed-loop validation process. Relative to template or rule-driven model generation approaches35, MAS4SysML avoids large-scale manual template maintenance and can adapt to diverse modeling tasks at lower engineering cost under structured task-card constraints, while improving output stability and executability via validation feedback. In contrast to end-to-end SysML v2 code generation using LLMs alone36, MAS4SysML mitigates the risks of syntactic errors and semantic drift through complementary constraints, including task decomposition, syntax diagnostics, and semantic consistency checking, thereby enhancing controllability and consistency. These features indicate strong potential for engineering deployment in the complex-equipment domain. Beyond rapid generation of executable models for typical systems, the validation-driven mechanism can support key modeling activities such as requirements traceability, interface consistency checking, and verification planning. The framework can also be integrated into engineering toolchains to support semi-automated construction and maintenance of model assets, thereby improving modeling efficiency and consistency in large-scale projects. However, the current framework should be regarded as a semi-automated modeling aid rather than a fully autonomous solution, since expert review is still necessary to confirm domain correctness and resolve residual errors in complex engineering scenarios.
Despite improvements in syntactic correctness and semantic consistency, MAS4SysML has several limitations. First, performance partially depends on the LLMs' ability to interpret complex modeling intent; semantically ambiguous descriptions, implicit constraints, or highly specialized terminology may bias task decomposition and omit critical information. Second, semantic consistency checking currently relies primarily on rule-based, text-level field alignment and cannot fully replace expert judgment of domain correctness, particularly for cross-element dependencies and implicit constraints. Therefore, human quality inspection remains necessary before generated model code can be adopted in engineering practice. Third, the quality of task cards strongly affects the final output; incomplete or imprecise requirements may cause the task tree to deviate from the true intent, reducing generation accuracy and increasing repair overhead.
Future work will focus on three directions. First, we will introduce retrieval-augmented mechanisms supported by knowledge graphs, engineering vocabularies, and modeling case libraries to improve interpretation of specialized requirements and implicit constraints. Second, we will strengthen automatic task-tree construction and adaptive optimization by leveraging domain ontologies, historical modeling data, and error-driven feedback, thereby improving the robustness and generalization of task decomposition. Third, although this study evaluates multiple representative SysML v2 modeling tasks, these tasks are currently generated and assessed mainly at the individual view code level. The framework does not yet explicitly address the joint generation and consistency maintenance of a complete system model across multiple interrelated views, such as requirements, structure, parametrics, and behavior. In particular, cross-view reuse and reference relationships among model elements have not been fully incorporated into the current generation and evaluation process. Therefore, the present work should be regarded as a foundational step toward broader system-level model generation, rather than a complete solution for end-to-end generation of fully consistent SysML v2 system models.
Disclosures
The authors have no conflicts of interest. AI/LLM tools were used only during dataset construction. Specifically, to build an evaluation dataset, we used an AI tool to generate natural-language modeling problem statements corresponding to manually created SysML v2 models (i.e., generating the "task description" given an author-built SysML v2 model), forming input–output pairs for benchmarking. Beyond this limited purpose, AI was not used to generate the proposed method, experimental results, data analyses, figures/tables, or any manuscript text.
Acknowledgements
This research is supported by the Civil Aerospace Project (D020101) of the China State Administration of Science, Technology, and Industry for National Defense.
Materials
| Name | Company | Catalog Number | Comments |
|---|---|---|---|
| LangChain | LangChain (open-source project) | v1.0.8; https://github.com/langchain-ai/langchain | Framework for LLM interaction and agent orchestration |
| LangGraph | LangChain (open-source project) | v1.0.3; https://github.com/langchain-ai/langgraph | Multi-agent workflow execution framework |
| Python | Python Software Foundation | 3.10.x; https://www.python.org/downloads/release/python-3100/ | Main programming language for MAS4SysML implementation |
| SysML v2 Pilot Implementation | Object Management Group (OMG) | (provide release/tag version); https://github.com/Systems-Modeling/SysML-v2-Pilot-Implementation | Used for syntax validation and model parsing |
References
- Miller, W. D. The Future of Systems Engineering: Realizing the Systems Engineering Vision 2035. Transdisciplinarity and the Future of Engineering. , IOS Press. (2022).
- Kirshner, M. J. A. Model-based systems engineering cybersecurity for space systems. Aerospace. 10 (2), 116(2023).
- Bajaj, M., Friedenthal, S., Seidewitz, E. J. I. Systems modeling language (sysml v2) support for digital engineering. Insight. 25 (1), 19-24 (2022).
- Cibrián, E., Olivert-Iserte, J., Llorens, J., Álvarez-Rodríguez, J. M. J. An agent-based approach for the automatic generation of valid sysmlv2 models in industrial contexts. Comput Ind. 172, 104350(2025).
- Dehart, J. K. Leveraging large language models for direct interaction with SysML v2. INCOSE International Symposium, 34, 2168-2185 (2024).
- Erikstad, S. O. Multi-agent LLMs and MBSE for developing design optimization models. ICCAS 2024 - International Conference on Computer Applications in Shipbuilding, Genoa, Italy, , (2024).
- Molnár, V., et al. Towards the formal verification of SysML v2 models. Proceedings of the ACM/IEEE 27th International Conference on Model Driven Engineering Languages and Systems, , (2024).
- Friedenthal, S. J. I. Requirements for the next generation systems modeling language (sysml® v2). Insight. 21 (1), 21-25 (2018).
- Wu, Y., et al. Evaluating GPT-4o's embodied intelligence: A comprehensive empirical study. TechRxiv. , (2025).
- Wu, Z., Rybak, V. Evaluation methods for code generation models. , Available from: https://libeldoc.bsuir.by/bitstream/123456789/56939/1/Zhong_Wu_Evaluation.pdf (2024).
- Harkous, H., Groves, I., Saffari, A. Have your text and use it too! End-to-end neural data-to-text generation with semantic fidelity. Proceedings of the 28th International Conference on Computational Linguistics, Barcelona, Spain, , (2020).
- Wei, J., et al. Chain-of-thought prompting elicits reasoning in large language models. NIPS'22: Proceedings of the 36th International Conference on Neural Information Processing System, New Orleans, LA, USA, , (2022).
- Jiang, X., et al. Self-planning code generation with large language models. ACM Trans Softw Eng Method. 33 (7), 182(2024).
- Zhang, K., Li, Z., Li, J., Li, G., Jin, Z. Self-edit: Fault-aware code editor for code generation. Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics, Toronto, Canada, , (2023).
- Le, H., et al. Codechain: Towards modular code generation through chain of self-revisions with representative sub-modules. arXiv. , (2023).
- Chen, X., Lin, M., Schärli, N., Zhou, D. J. aP. A. Teaching large language models to self-debug. arXiv. , (2023).
- Islam, M. A., Ali, M. E., Parvez, M. R. J. aP. A. Mapcoder: Multi-agent code generation for competitive problem solving. arXiv. , (2024).
- Dong, Y., Jiang, X., Jin, Z., Li, G. Self-collaboration code generation via chatgpt. ACM Trans Softw Eng Method. 33 (7), 189(2024).
- Chen, B., et al. Codet: Code generation with generated tests. arXiv. , (2022).
- Nijkamp, E., et al. Codegen: An open large language model for code with multi-turn program synthesis. arXiv. , (2022).
- Chowdhery, A., et al. Palm: Scaling language modeling with pathways. J Mach Learn Res. 24 (1), 240(2023).
- Kolter, J. Z. Alphacode and "data-driven" programming. Science. 378 (6624), 1056(2022).
- Fried, D., et al. Incoder: A generative model for code infilling and synthesis. arXiv. , (2022).
- Chen, M. J. Evaluating large language models trained on code. arXiv. , (2021).
- Chiang, W. -L., et al. Chatbot arena: An open platform for evaluating LLMs by human preference. Proc Mach Learn Res, 235, 8359-8388 (2024).
- Glm, T., et al. ChatGLM: A family of large language models from GLM-130B to GLM-4 all tools. arXiv. , (2024).
- Introducing MPT-7B: A new standard for open-source, commercially usable LLMs. AI Research. , Available from: https://www.databricks.com/blog/mpt-7b (2023).
- Chiang, W. -L., et al. Vicuna: An open-source chatbot impressing gpt-4 with 90%* chatgpt quality. , ORKG. Available from: https://orkg.org/papers/R602383 (2023).
- Huggingchat. , Available from: https://huggingface.co/chat/ (2024).
- Sun, Z., et al. Principle-driven self-alignment of language models from scratch with minimal human supervision. arXiv. , (2023).
- Ye, J., et al. A comprehensive capability analysis of GPT-3 and GPT-3.5 series models. arXiv. , (2023).
- Luo, Z., et al. Wizardcoder: Empowering code large language models with evol-instruct. arXiv. , (2023).
- Roziere, B., et al. Code llama: Open foundation models for code. arXiv. , (2023).
- Rodola, G. Psutil documentation. , Psutil. Available from: https://psutil.readthedocs.io/en/latest (2020).
- Akundi, A., Ontiveros, J., Luna, S. Text-to-model transformation: Natural language-based model generation framework. Systems. 12 (9), 369(2024).
- Wang, Y., et al. Generating SysML behavior models via large language models: an empirical study. Proceedings of the 16th International Conference on Internetware, , (2025).